Inspect grouped STATS results in Discover
When your ES|QL query uses a STATS BY clause with a single grouping field, Discover displays the results as expandable groups instead of a flat table. Each row represents one unique value of the grouping field. You can expand it to inspect the underlying documents without leaving the query.
- You need an ES|QL query in Discover. If you're new to ES|QL in Discover, start with Get started with ES|QL in Discover.
- Your query groups by a single field, or by a single
CATEGORIZEcall. Other queries keep the standard flat results table:- Queries that group by more than one field, for example
BY clientip, extension.keyword. - Queries that use other grouping functions, such as
BUCKETorTBUCKET. - Queries that use
TS_INFOorMETRICS_INFO. Their rows describe metrics and have no documents to expand.
- Queries that group by more than one field, for example
In Discover, in ES|QL mode, enter a
STATS BYquery with a single grouping field. For example:FROM kibana_sample_data_logs | STATS Visits = COUNT(*), AvgBytes = AVG(bytes) BY geo.dest | SORT Visits DESCSelect Search.
Result: The table lists one row per group. The results count reports the number of groups instead of the number of documents.
NoteWhen you search large data sets, you can get faster, estimated results by using Fast mode. Refer to Use ES|QL in the Kibana UI > Get faster results with approximate STATS.
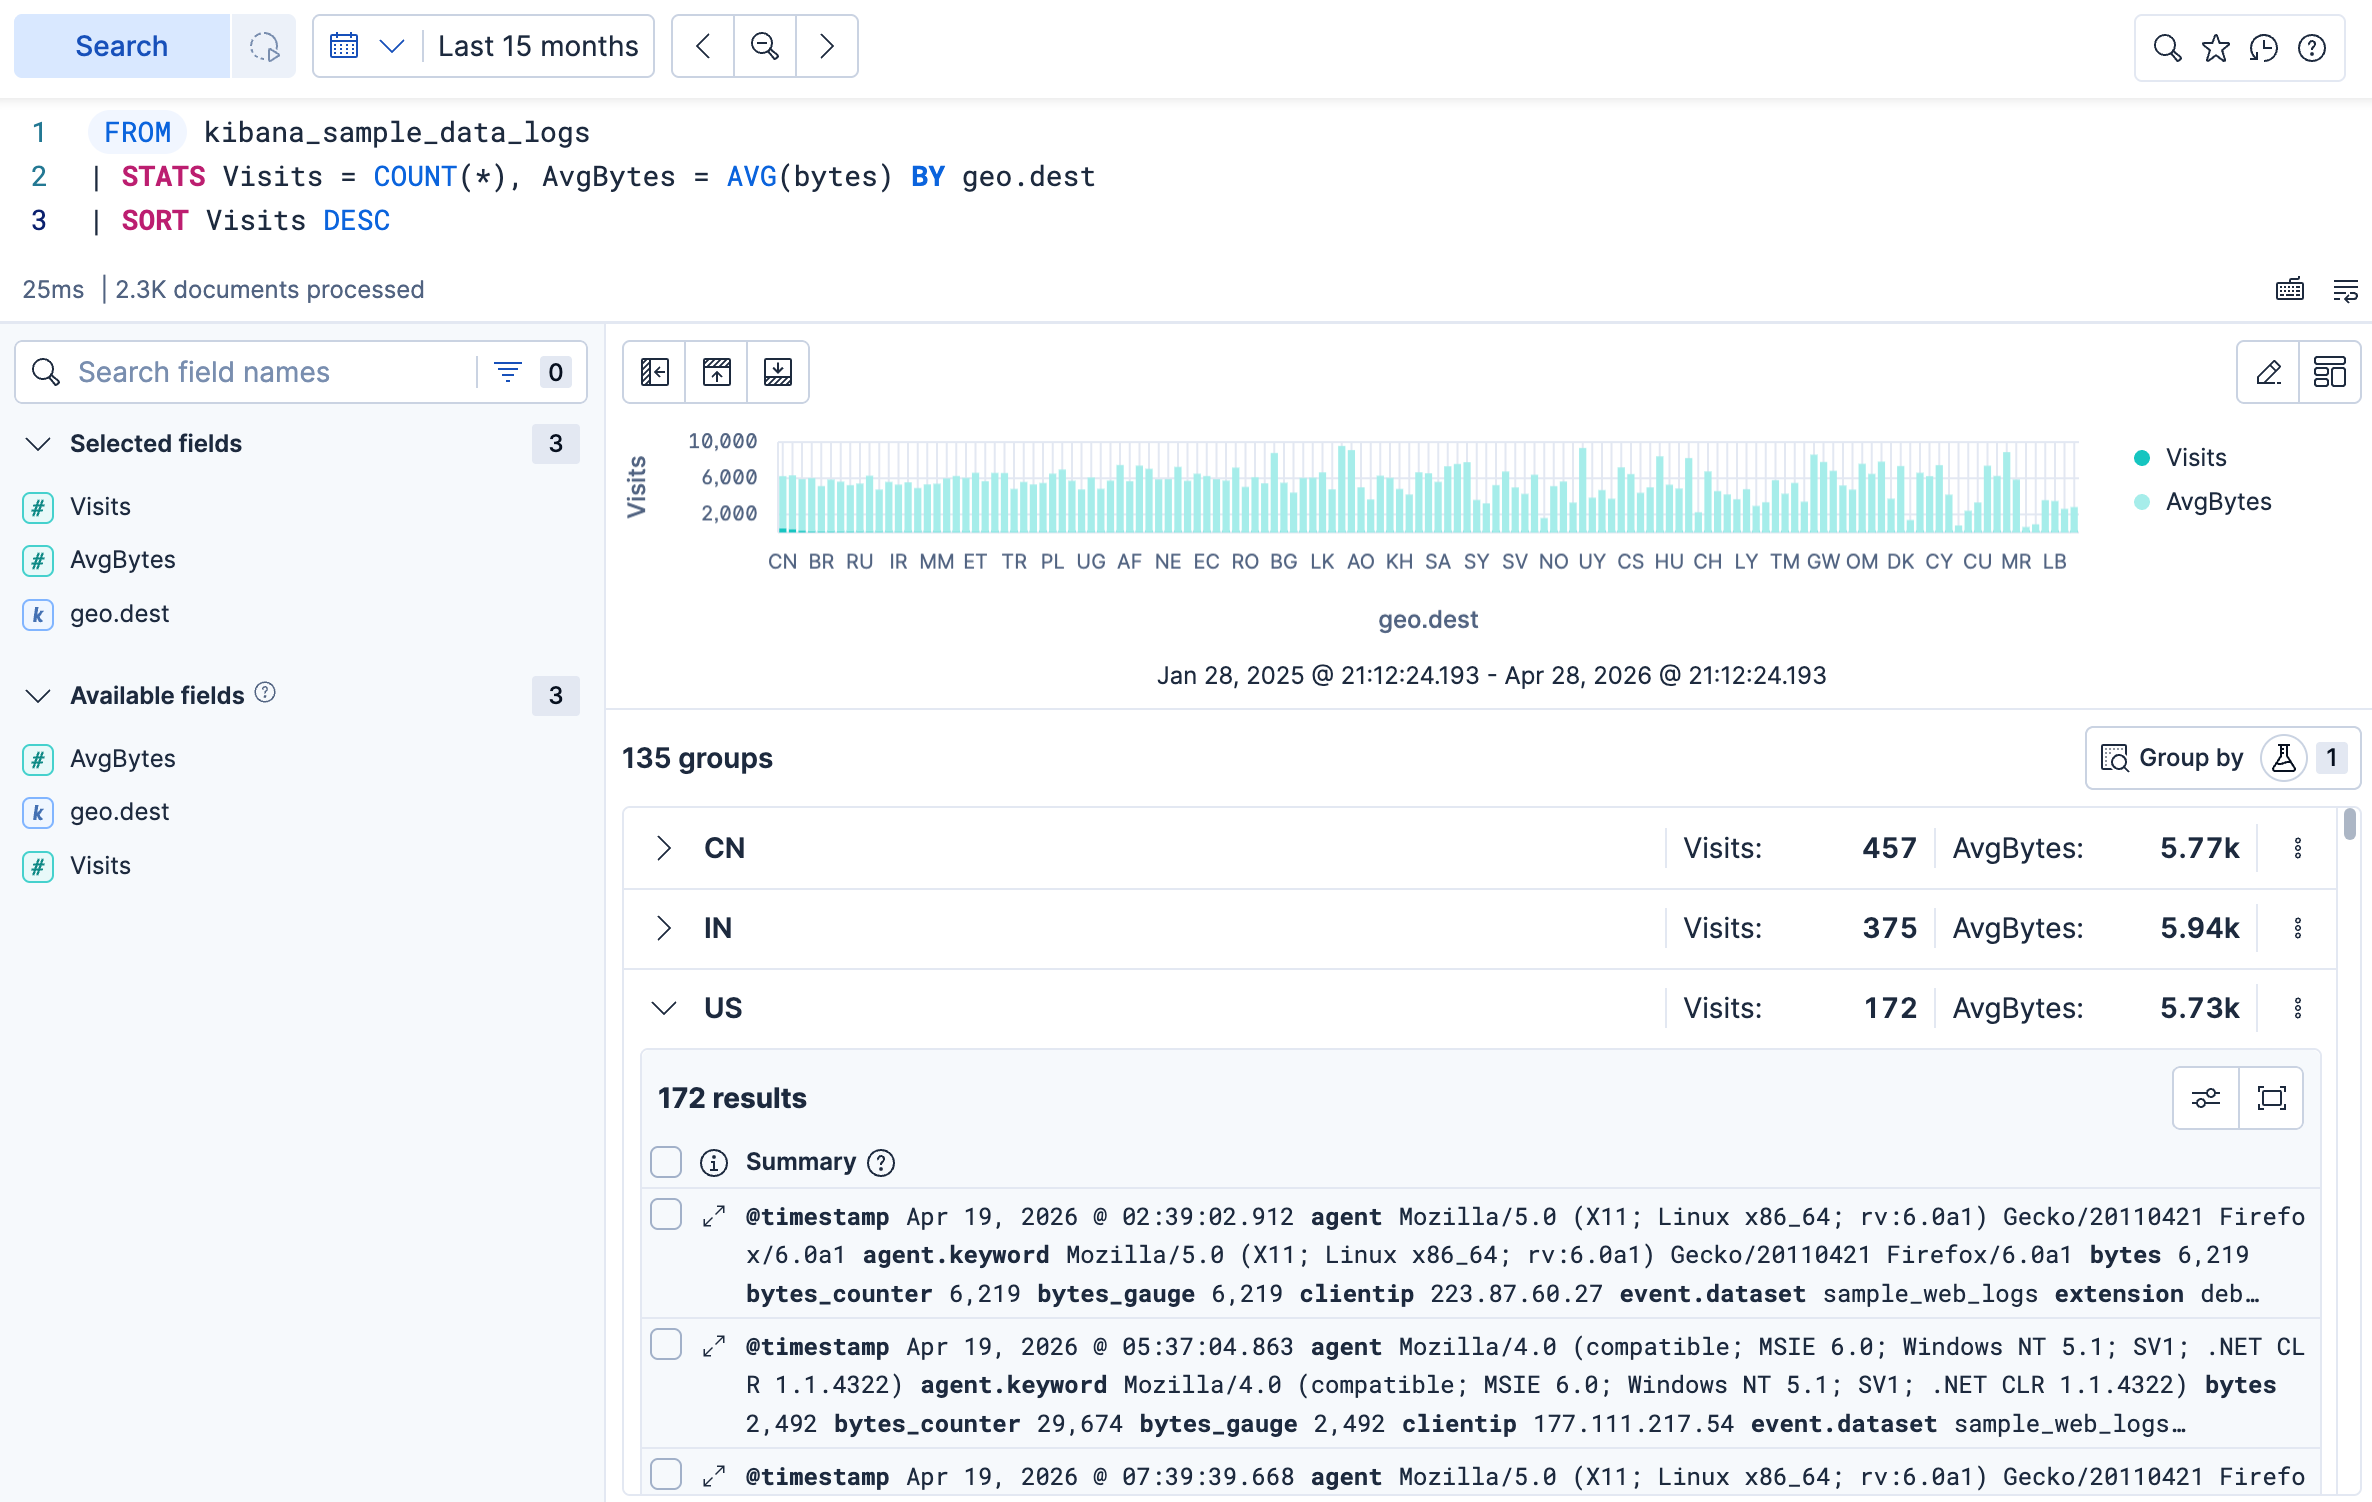
Expand a row to inspect the underlying documents.
When the grouping field uses CATEGORIZE, each row title shows the detected pattern with token highlighting, so you can scan repeated message structures at a glance.
FROM kibana_sample_data_logs
| STATS Count = COUNT(*) BY Pattern = CATEGORIZE(message)
| SORT Count DESC
Pattern detection on text fields is also available outside ES|QL from the Patterns view in Discover's classic mode. Refer to Run a pattern analysis on your log data.
When the query also computes a SPARKLINE over time, Discover renders an inline chart next to the row aggregates. For example, the following query categorizes log messages and renders a sparkline for each pattern:
FROM kibana_sample_data_logs
| WHERE @timestamp >= ?_tstart AND @timestamp < ?_tend
| STATS Count = COUNT(*),
        Sparkline = SPARKLINE(COUNT(*), @timestamp, 40, ?_tstart, ?_tend)
    BY Pattern = CATEGORIZE(message)
| SORT Count DESC
On larger data sets, add a SAMPLE command before STATS to keep the categorization fast, and divide COUNT(*) by the same sample fraction to keep the counts representative. For example, SAMPLE 0.001 followed by Count = COUNT(*) / 0.001.
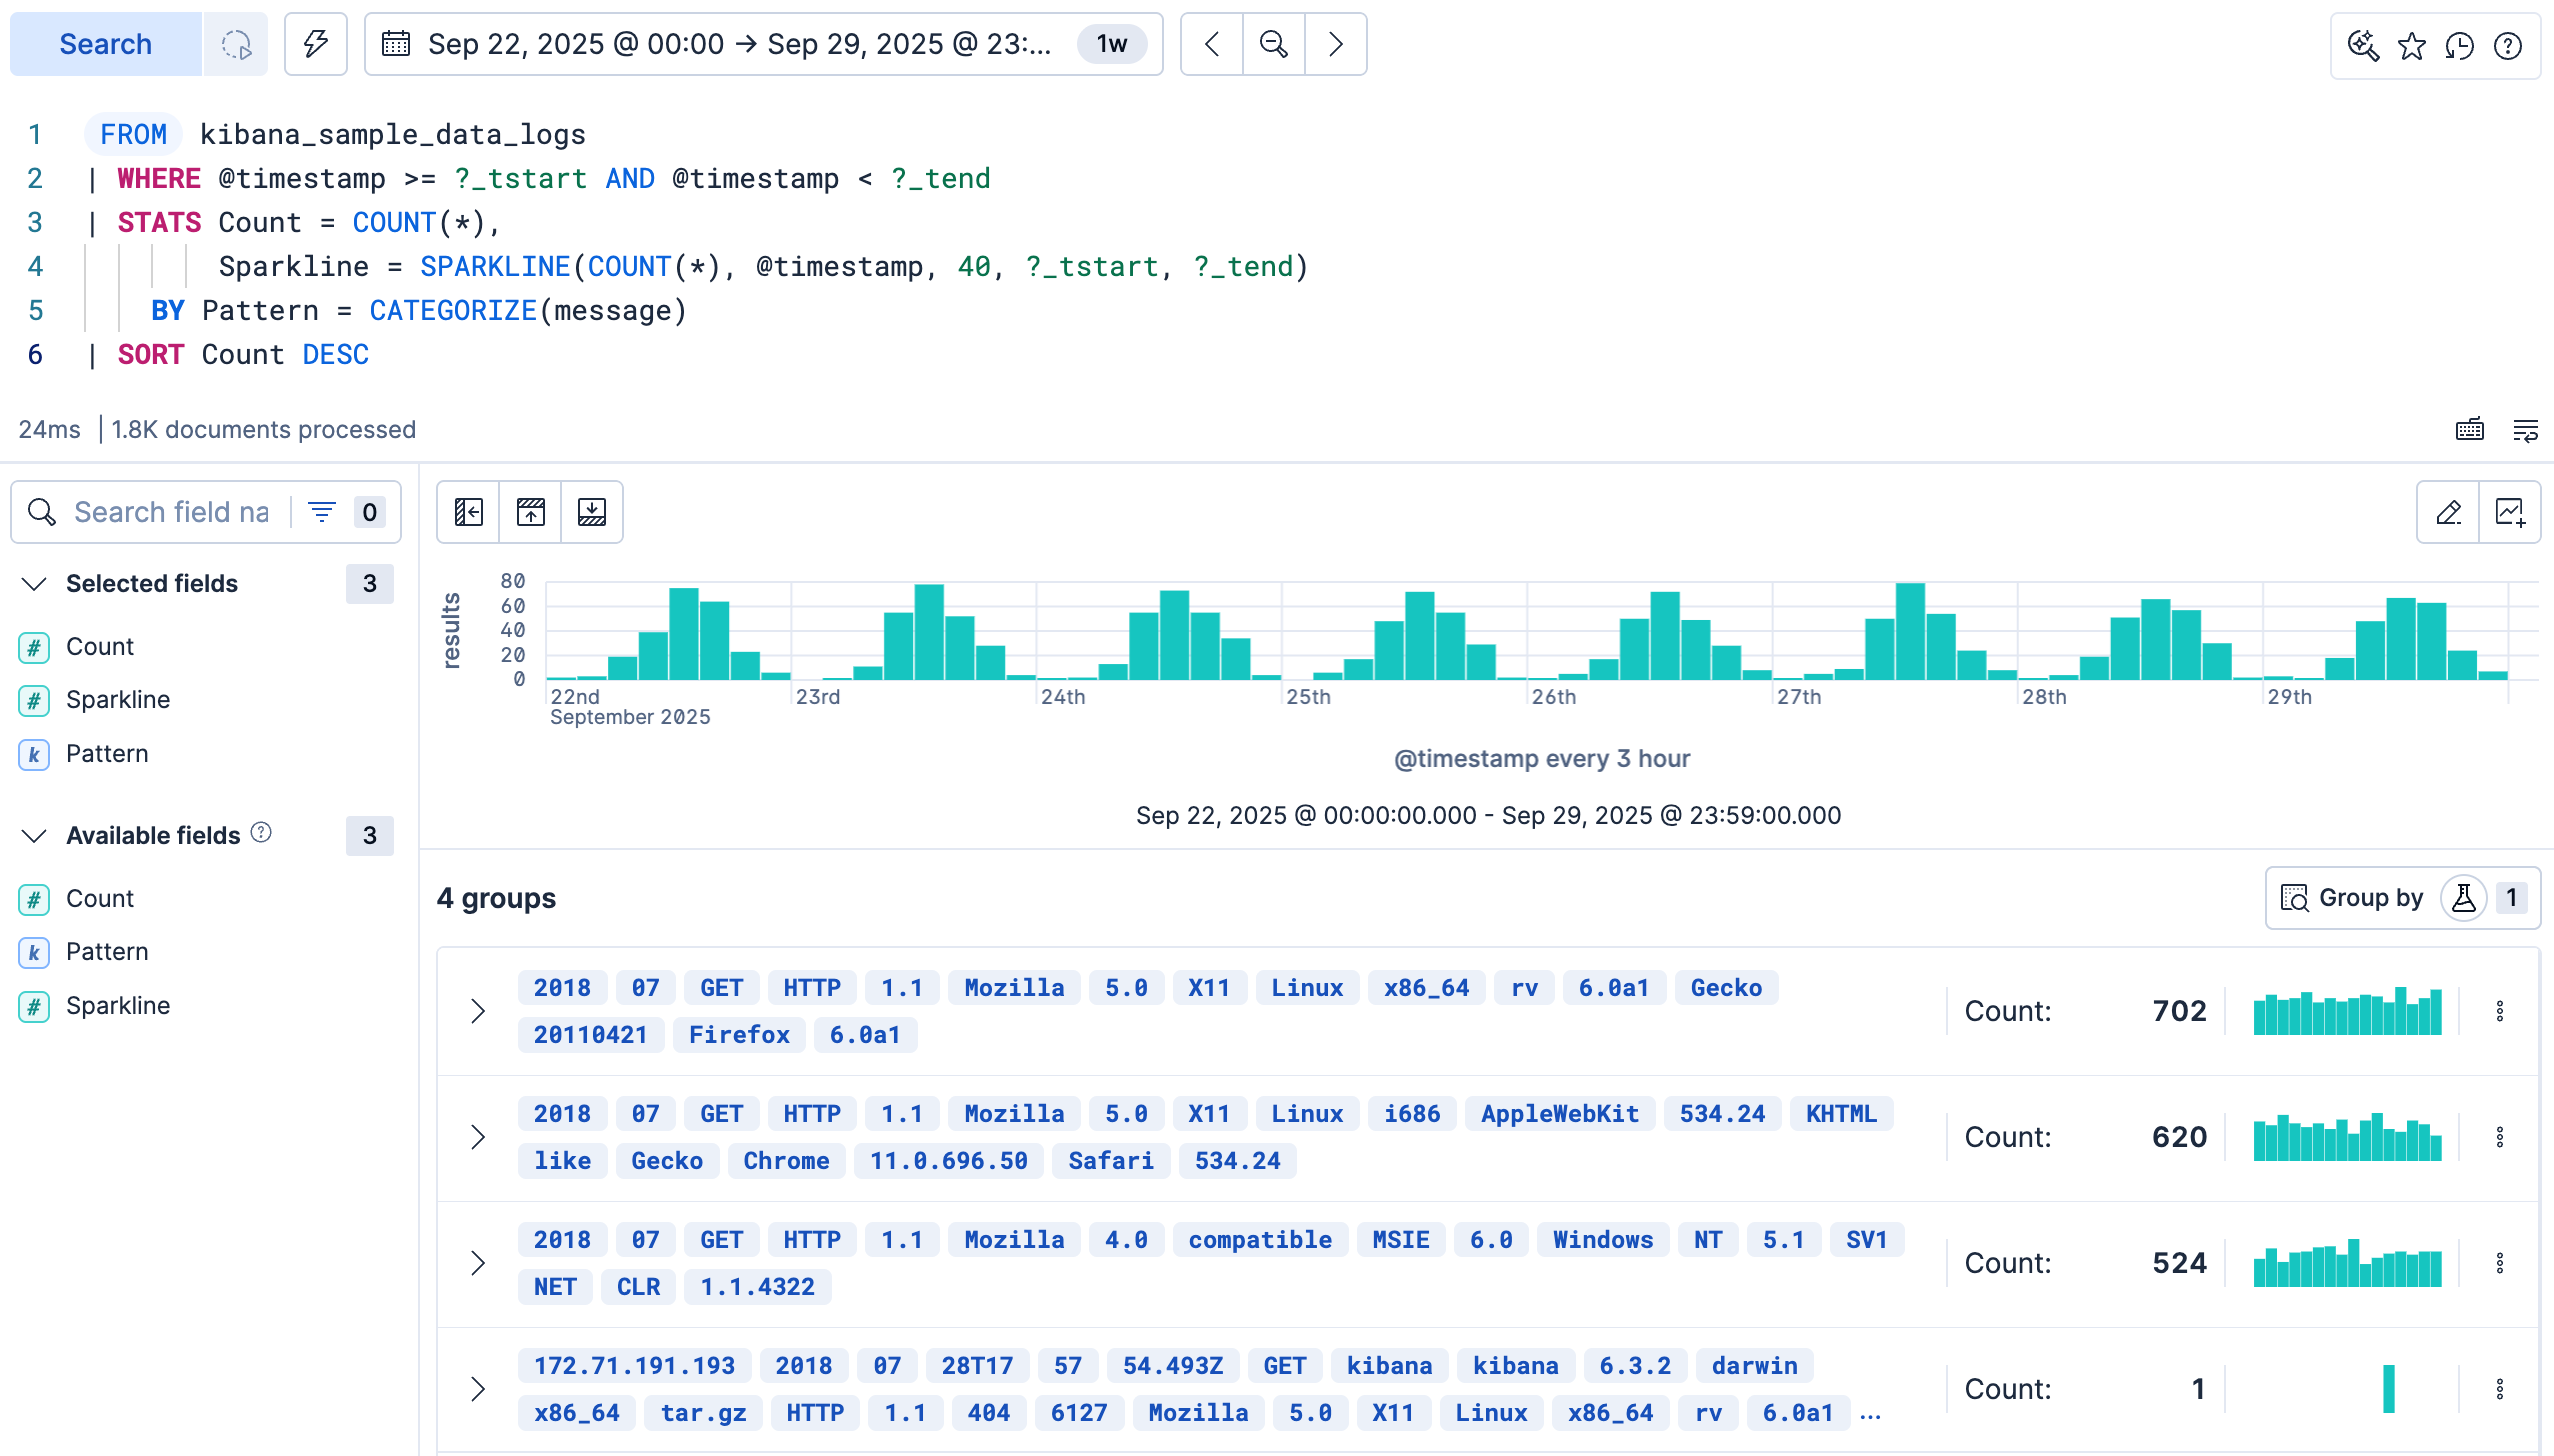
Select the actions button on any group row to:
- Copy to clipboard: copy the group's value.
- Filter in: append a
WHEREclause to your query that keeps only documents matching this group. - Filter out: append a
WHEREclause that excludes documents matching this group. - Open in new tab: open the documents in this group in a new Discover tab, with a query scoped to that group.
Filter in and Filter out are disabled when the grouping field isn't filterable.
When the grouped layout activates, Discover replaces the regular results table toolbar with a Group by button. The button shows the number of active groupings as a badge.
Discover preselects the grouping field from your STATS BY clause. From the Group by menu, select none to go back to the standard flat results table and the regular toolbar.