Observability Labs
Explore Elastic Observability Labs for expert-led resources and hands-on learning. Enhance your skills and optimize your observability strategy with Elastic.
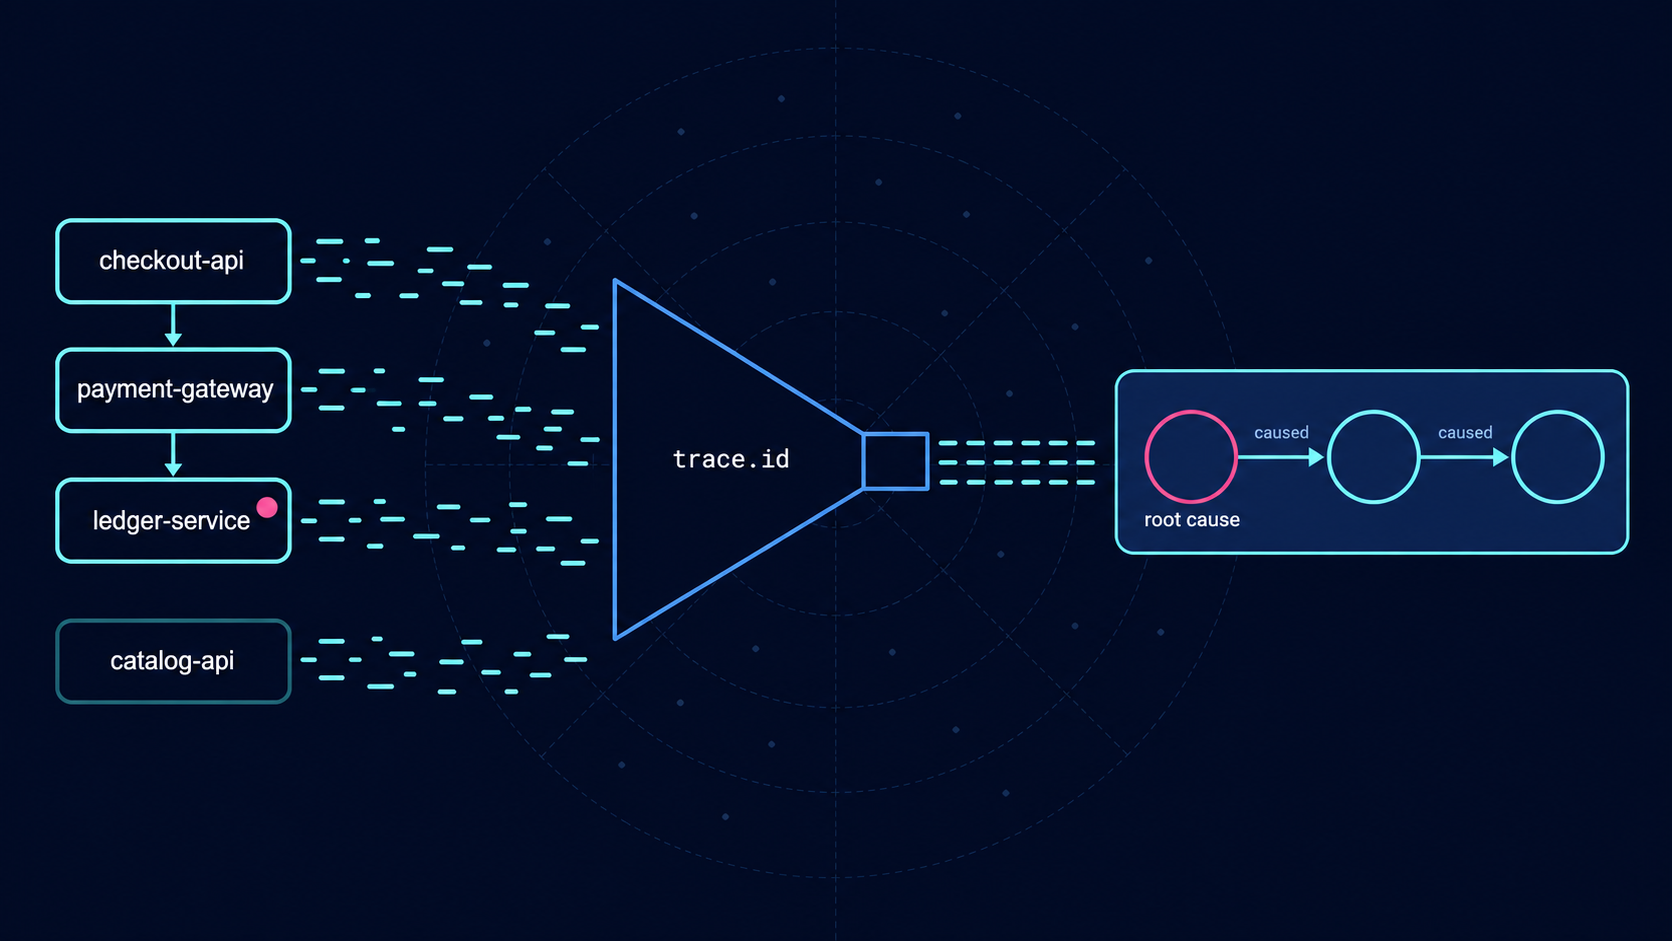
The service with the most errors was healthy: root cause analysis from logs with ES|QL
Metrics ranked three services identically at 19.1%. Four ES|QL queries over the same 4,688 OpenTelemetry log records traced 955 of 956 failure chains back to one of them, and needed no service dependency model to do it.
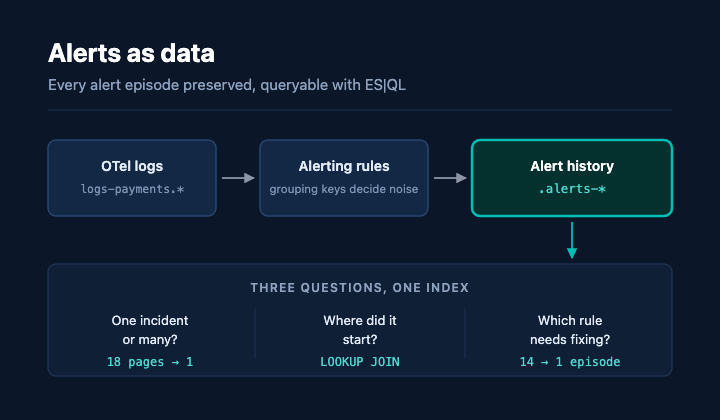
14 alerts, 1 incident: Measuring alerting rule noise with ES|QL in Elasticsearch
Kubernetes attributes processor v1: What it means for EDOT Collector
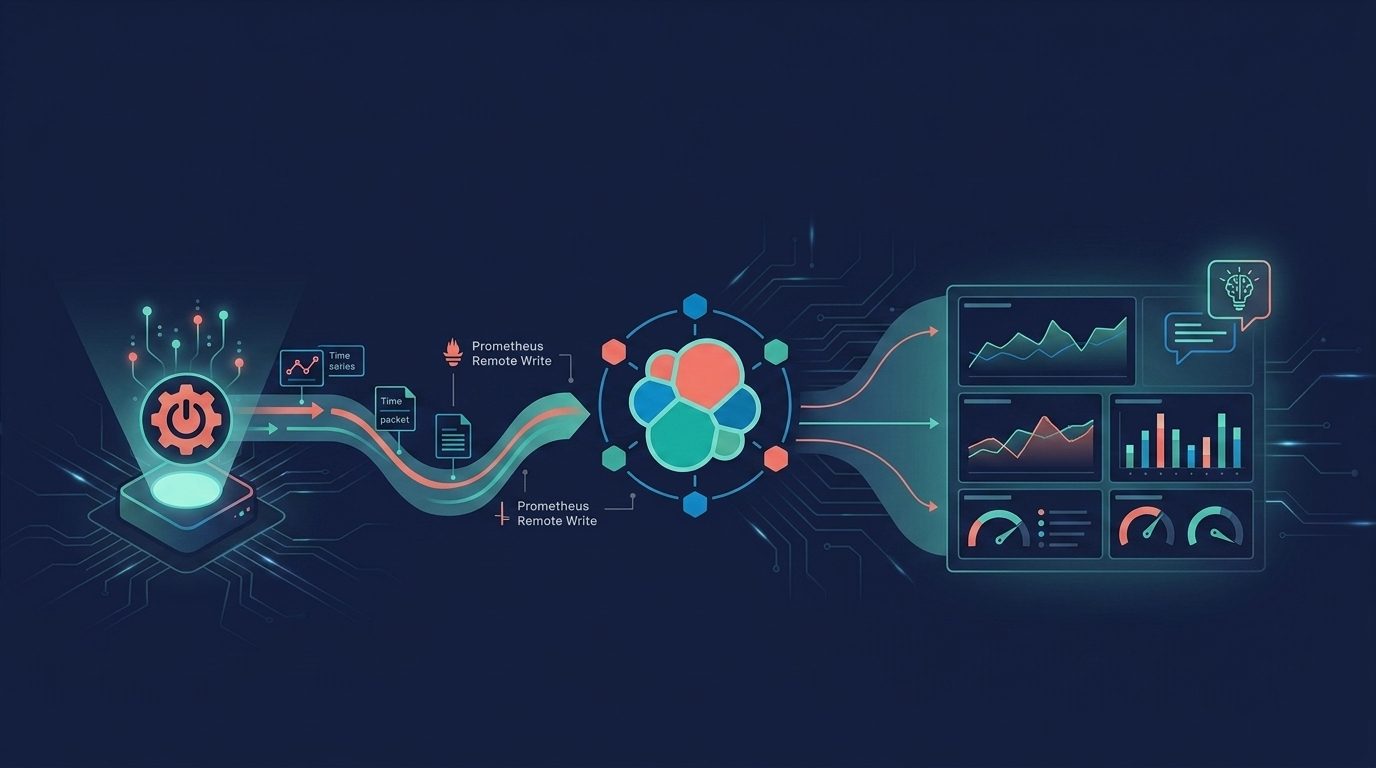
Two dependencies and one config block: Spring Boot metrics to Elasticsearch over Prometheus remote write
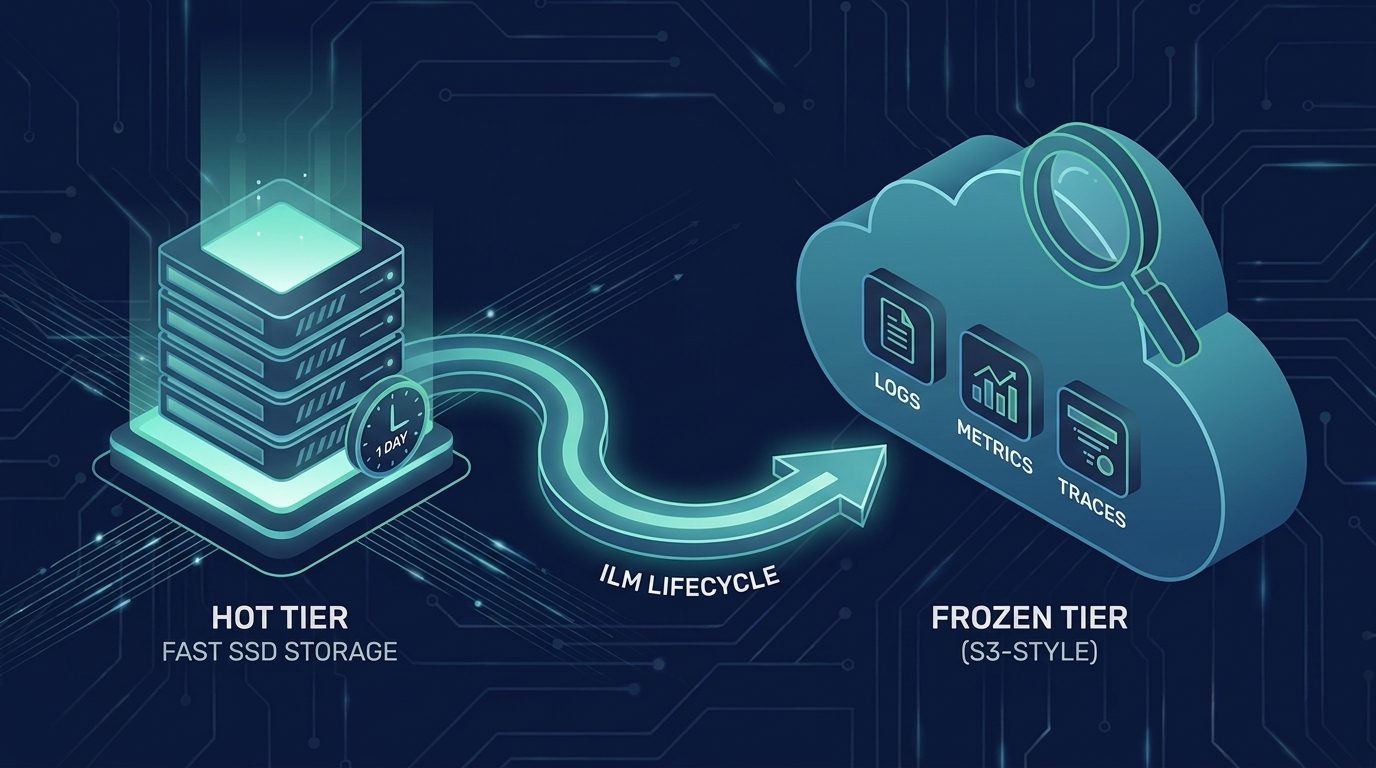
Blog
Developer insights and practical observability articles from our experts to inspire and empower your monitoring stack
Temporal Cloud observability in Elastic: 50+ metrics, zero collectors
Elastic scrapes metrics.temporal.io, so the workflow that has been stuck in Running for an hour turns out to be a task queue nobody is polling, and you find that out before you open a single worker log.
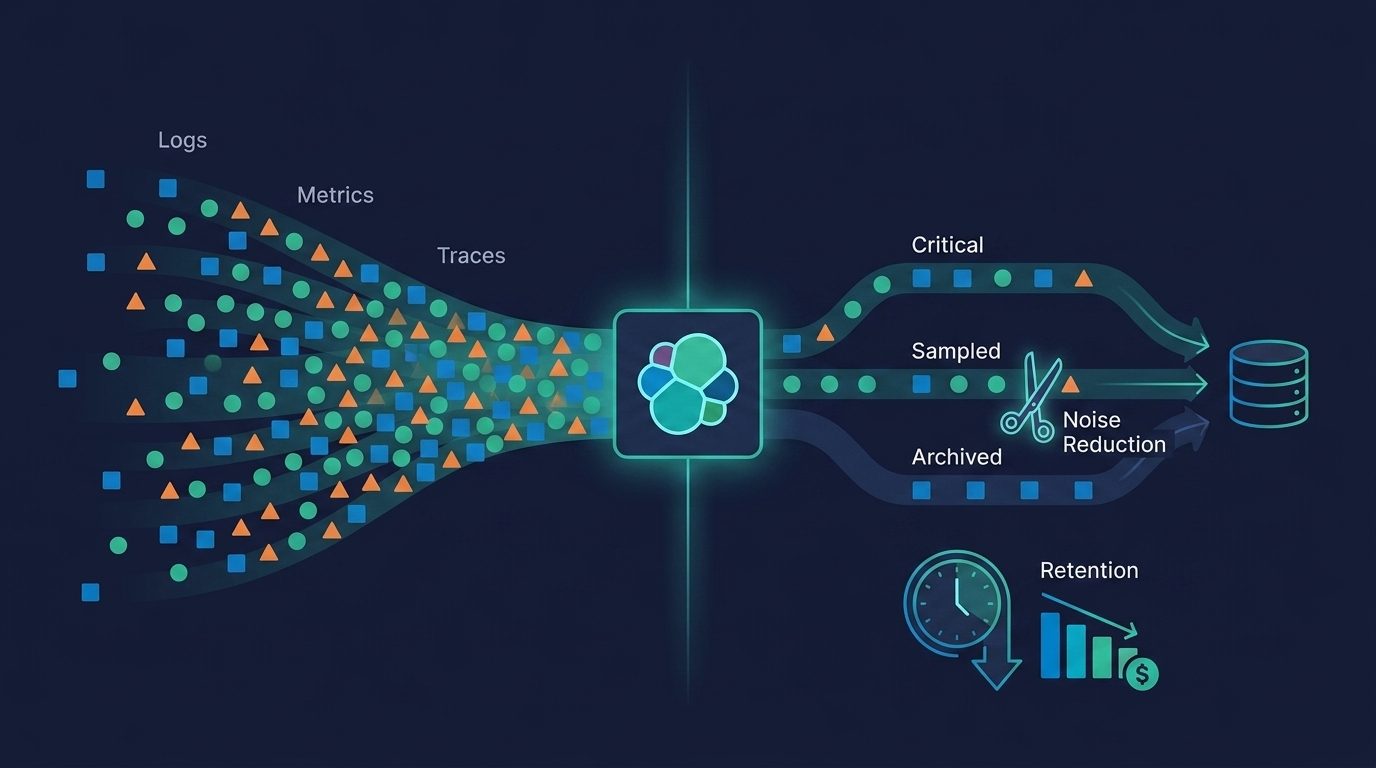
Not every log deserves 90 days: per-stream retention in Elastic Streams
AI Partitioning reads your data and proposes child streams. Retention, drops and downsampling then become per-stream settings, so the noisy ones expire on their own schedule.
Cross-project search for Elastic Observability: one query across every linked project
Keep your observability data where it lives, and still search, alert, and monitor across every linked Serverless project, easily!
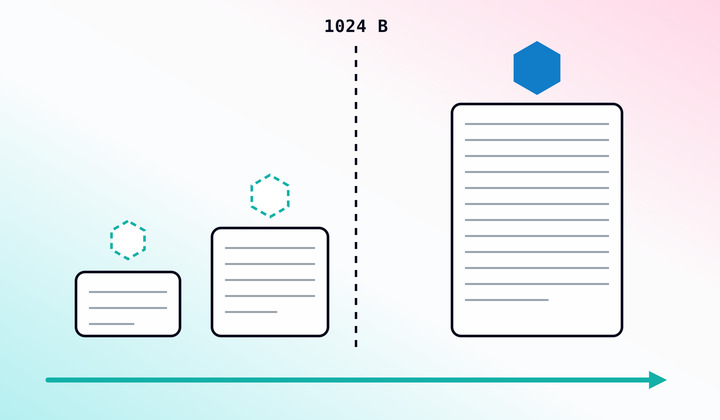
No log file too small: How Elastic Agent tracks files below the 1 KiB threshold
Elastic Agent 9.5 builds a small log file's identity out of the bytes it already has, then re-links it as it grows and crosses 1024 bytes, so it is never re-ingested.
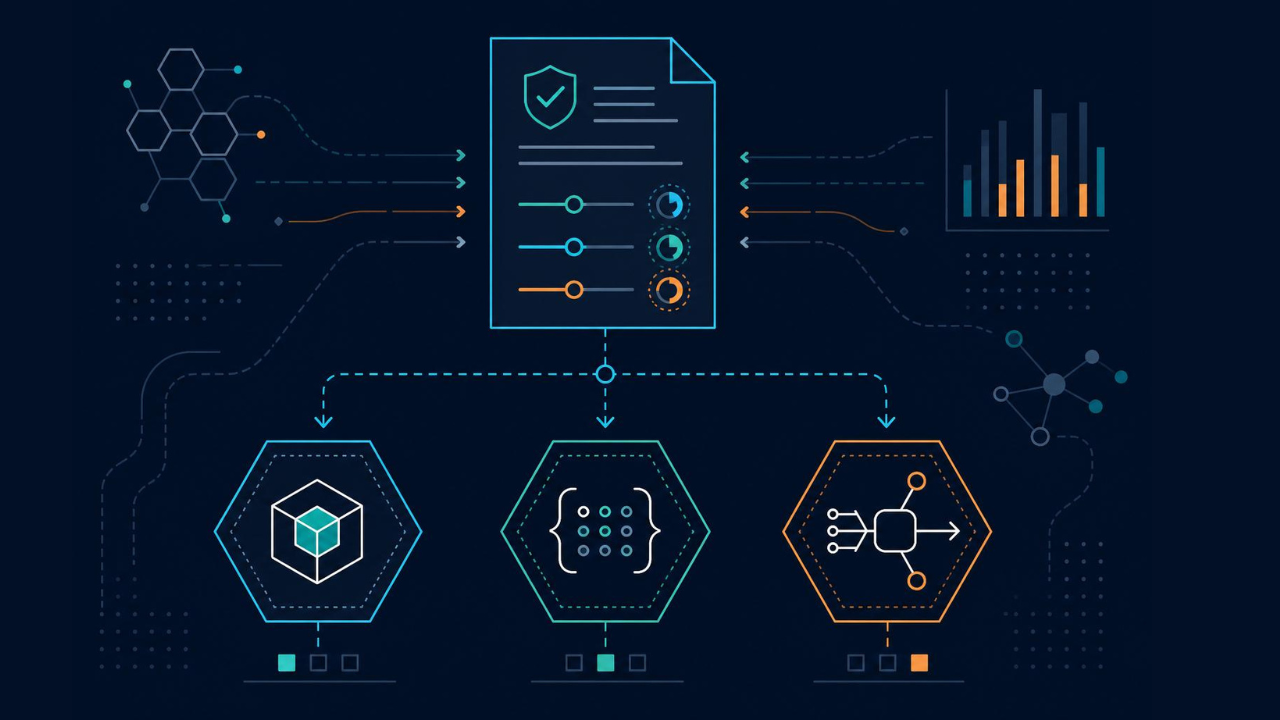
Telemetry Policy: change OpenTelemetry sampling and log levels at runtime, no restart
Telemetry Policy says what you want to happen and leaves each component to work out how. Change an OpenTelemetry Java agent's trace sampling to 1% and the JVM keeps serving traffic.
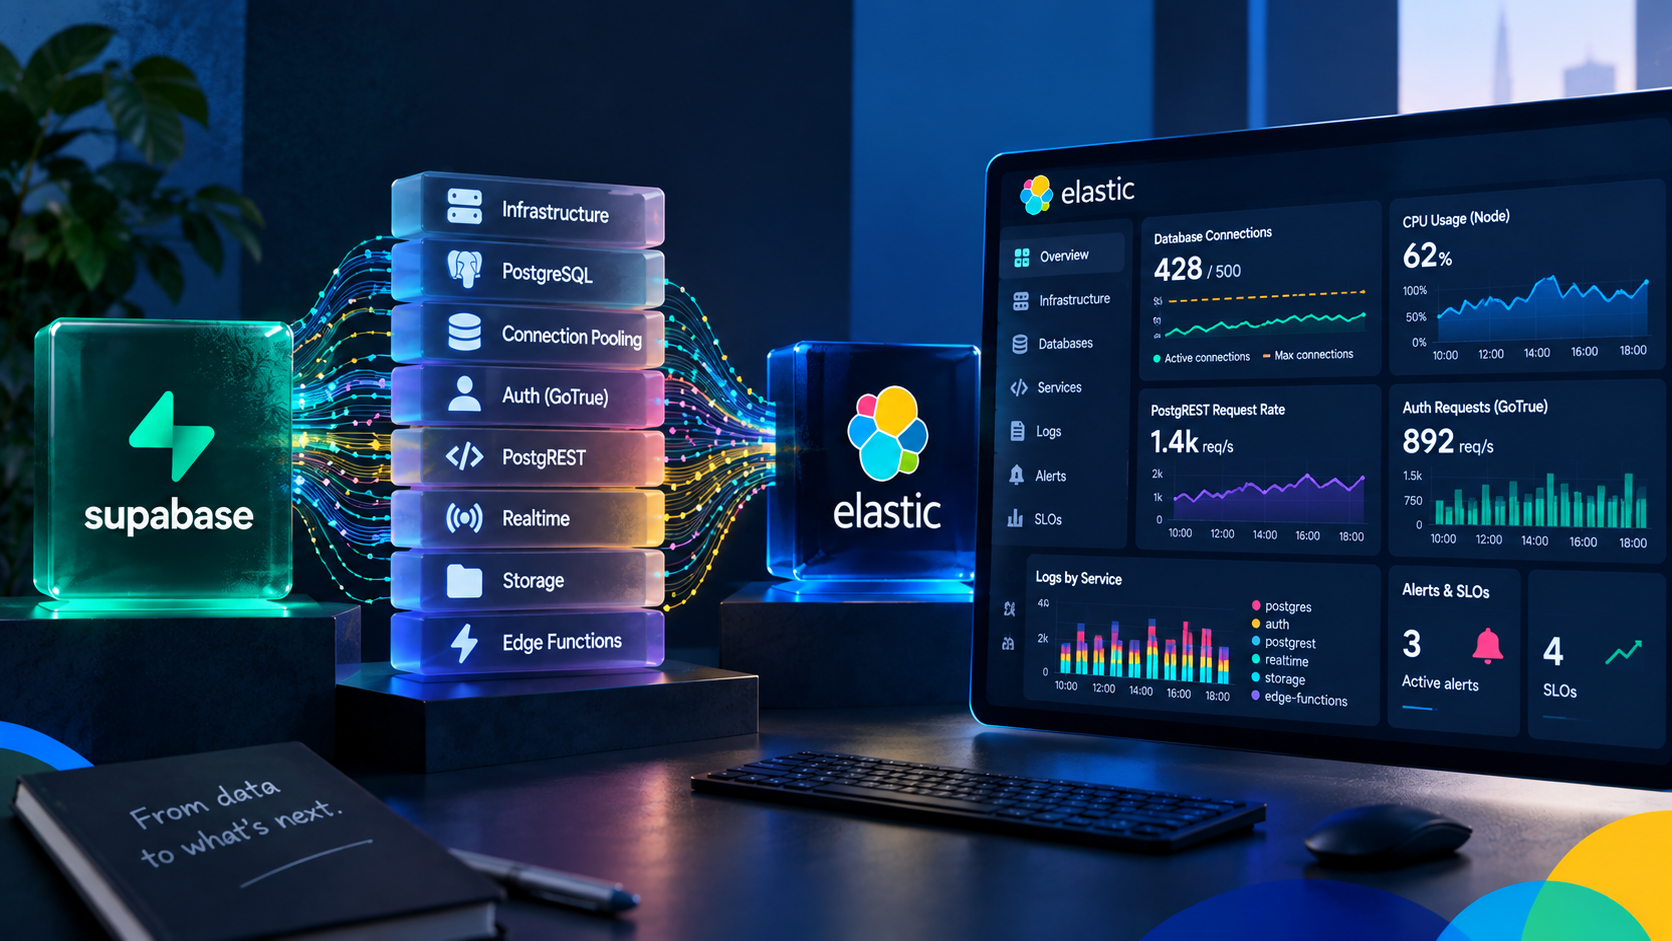
Monitor Supabase in Elastic: dashboards, alert templates, SLO templates, and zero agents
When your Supabase API goes slow, it could be the node, Postgres, the pooler or PostgREST. Elastic tells you which one and shows you the logs from whichever it was.
Native OTLP metrics ingestion on Elastic Cloud Hosted
Send an exponential OpenTelemetry histogram and Elasticsearch keeps the scale and buckets you sent. All four type and temporality combinations work now, and your SDK and Collector config stay exactly as they are.
Collecting rootless Podman logs with Elastic Agent: the CRI parser, user-scoped paths, and the Podman socket
Rootless Podman containers write their logs in CRI format. This Fleet policy reads them and attaches container.* fields, with the match_source_index value that rootless paths need.
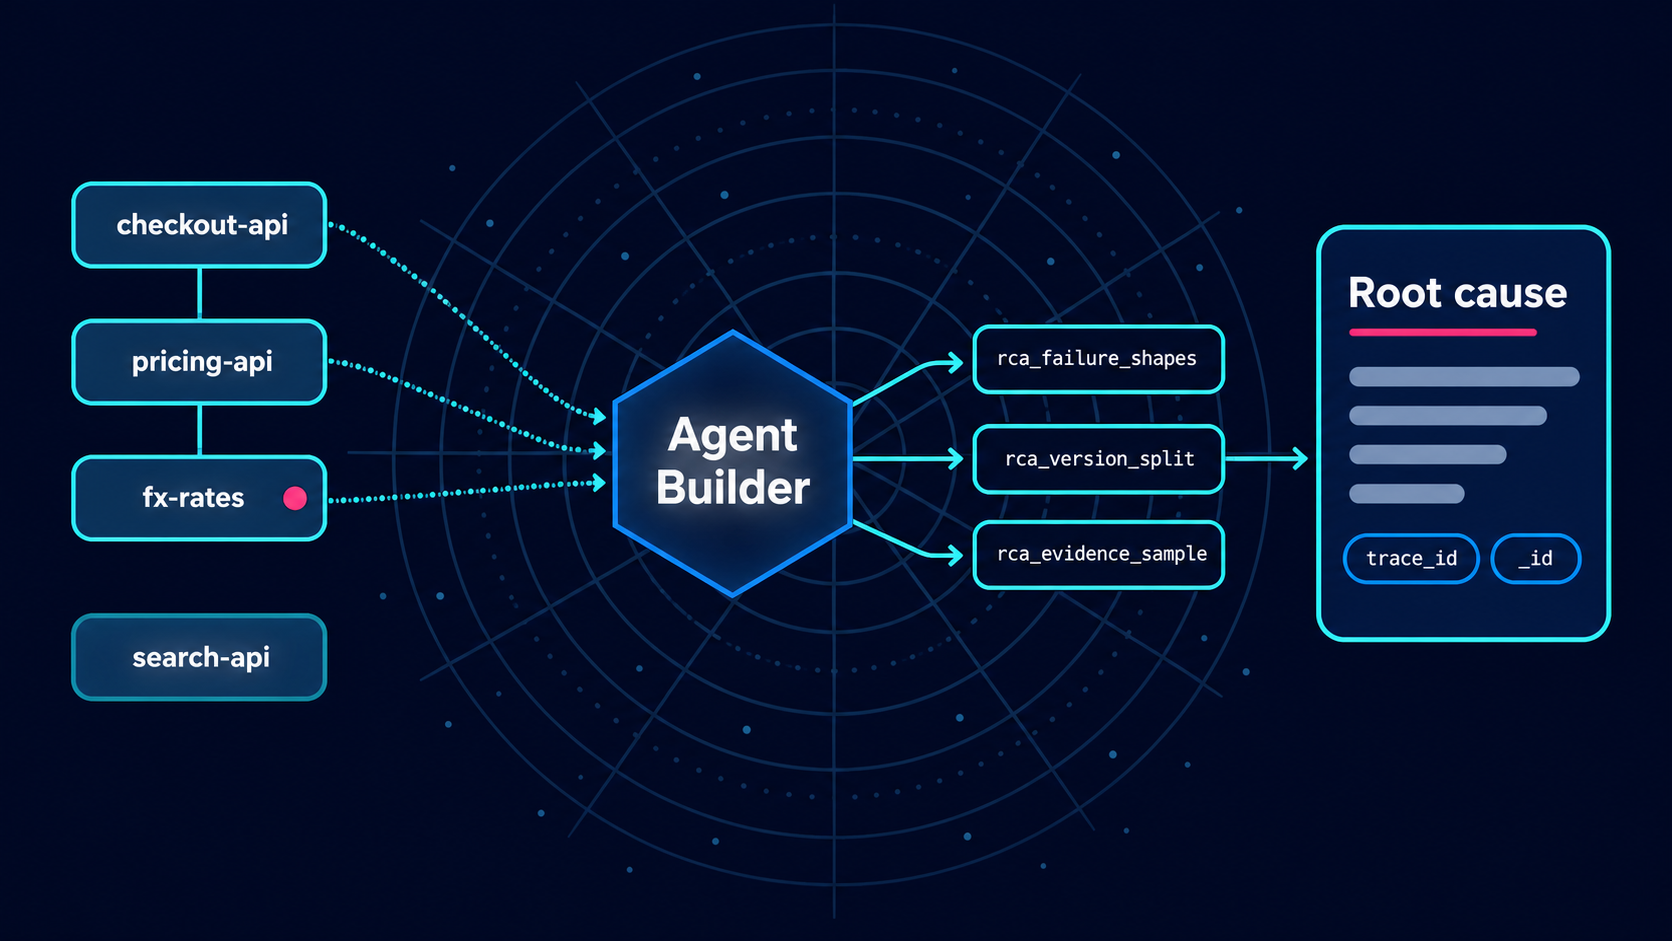
AI root cause analysis in Elastic Agent Builder that cites its evidence
The new release failed at 27.2%, the old one at 28.2%, so the deploy was never the cause; the agent worked that out in 72 seconds and handed back a trace ID for the failure that was.
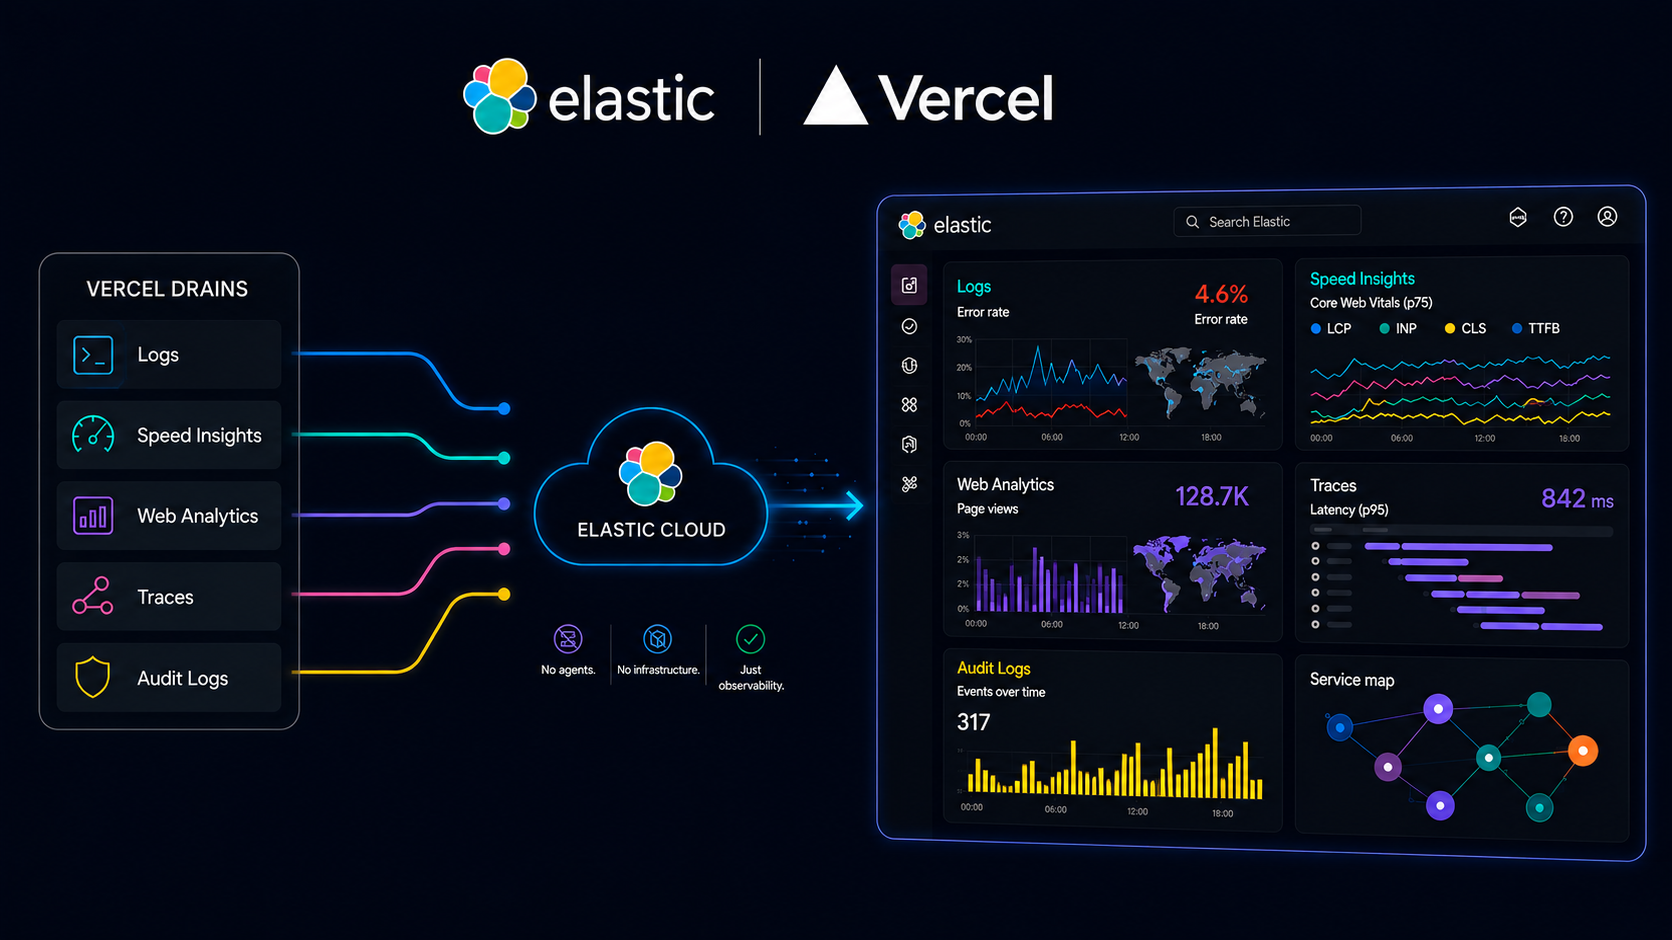
Drain Vercel into Elastic: serverless observability with nothing to install
A drain and an API key put Vercel logs, traces, and Speed Insights into Elastic Cloud, where you can follow a slow request from the edge to the Lambda function behind it.
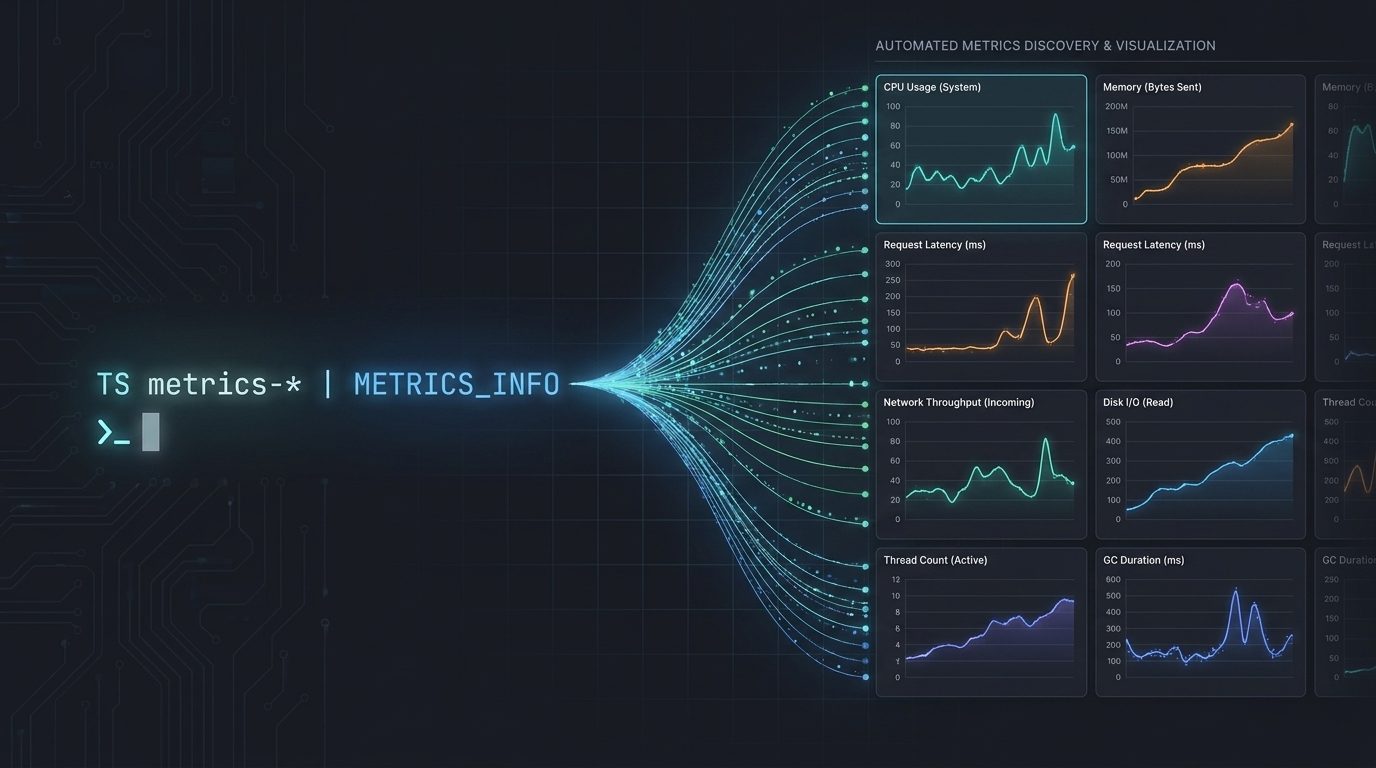
How one ES|QL query builds a metric chart for every metric in Elasticsearch
METRICS_INFO reports what metrics are in your data and how to aggregate each one, so Kibana Discover can chart counters, gauges and histograms correctly with no configuration and no field names to look up.
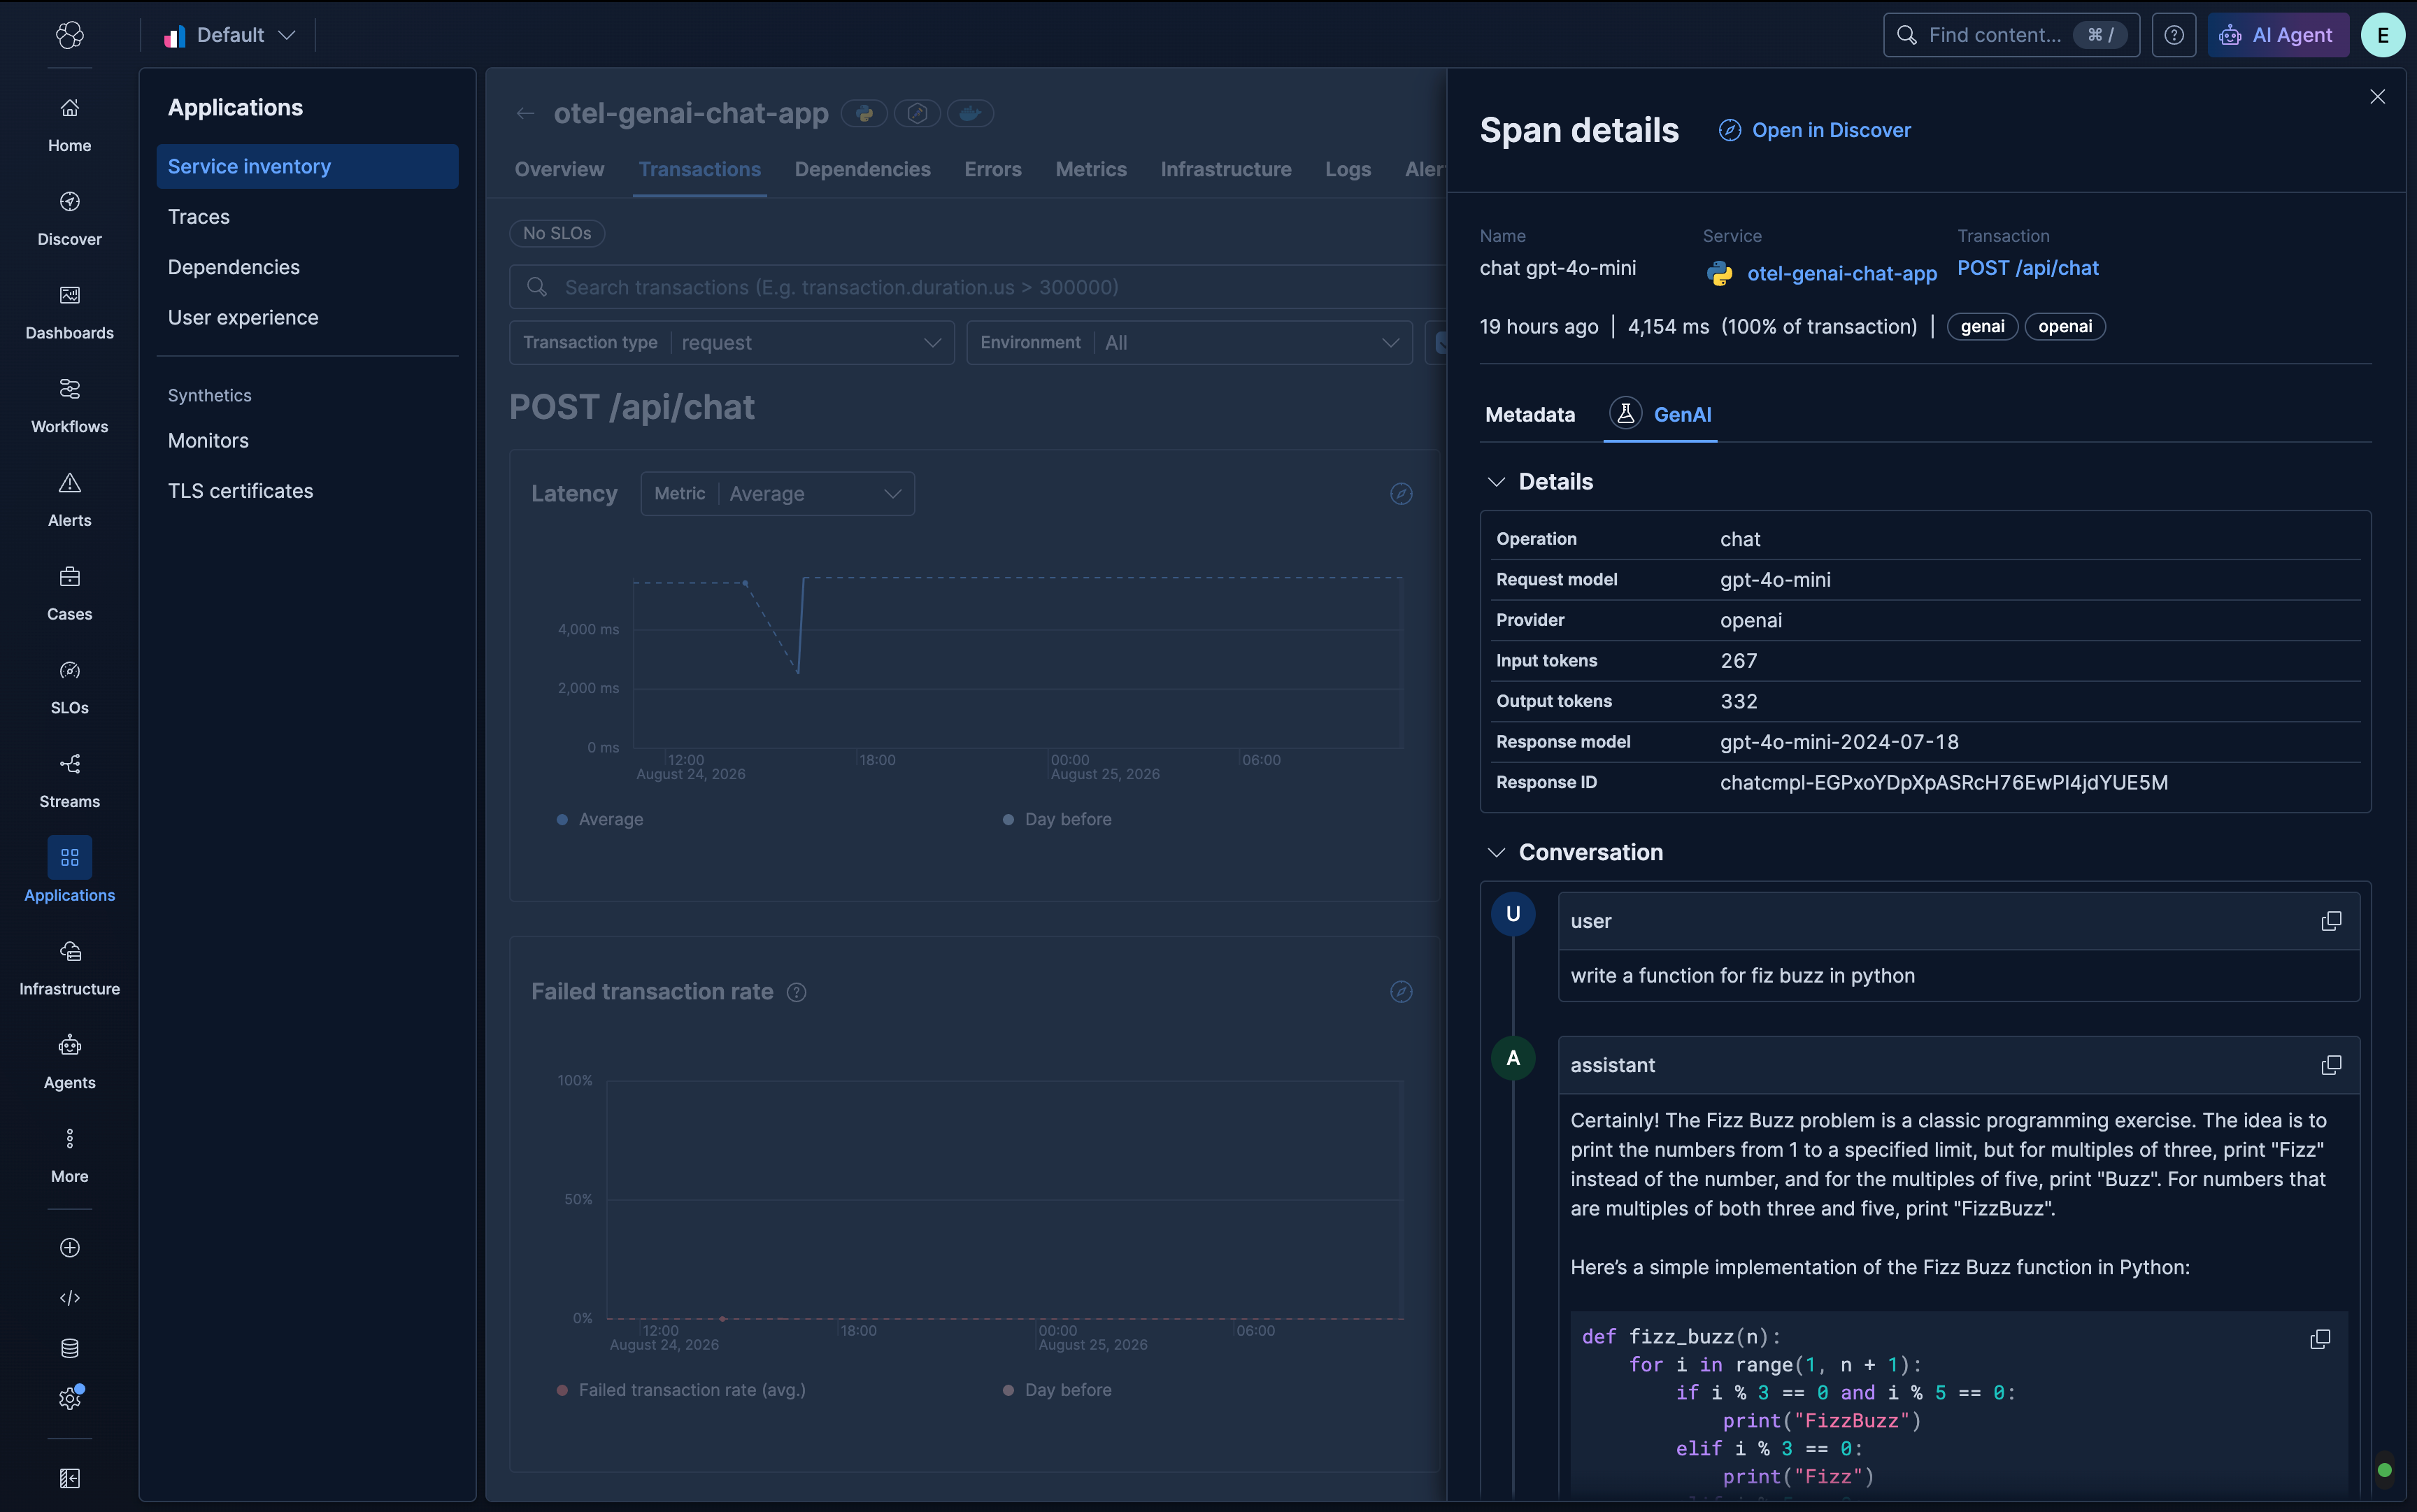
LLM tracing in Elastic APM: prompts, responses, and token counts in the span view
In a twenty-call agentic trace, you can see which span is using the most tokens and read the prompt that caused it. Both live in Elastic APM, so there is no second tool to run.
Your AI agent needs an alibi: Observability and audit trails for Agent Builder in Elastic
Elastic 9.5 traces every Agent Builder run as OpenTelemetry spans in your own cluster, so tool calls and token counts are queryable with ES|QL. One workflow step adds the approval record, in a data stream the pipeline cannot rewrite.
From a 582ms latency spike to the team that owns it, using Kibana Discover
Getting there takes a data view, some filter pills, a KQL query and a switch to Lucene query syntax, but the part that actually names the team is one ES|QL LOOKUP JOIN against a service catalog index.
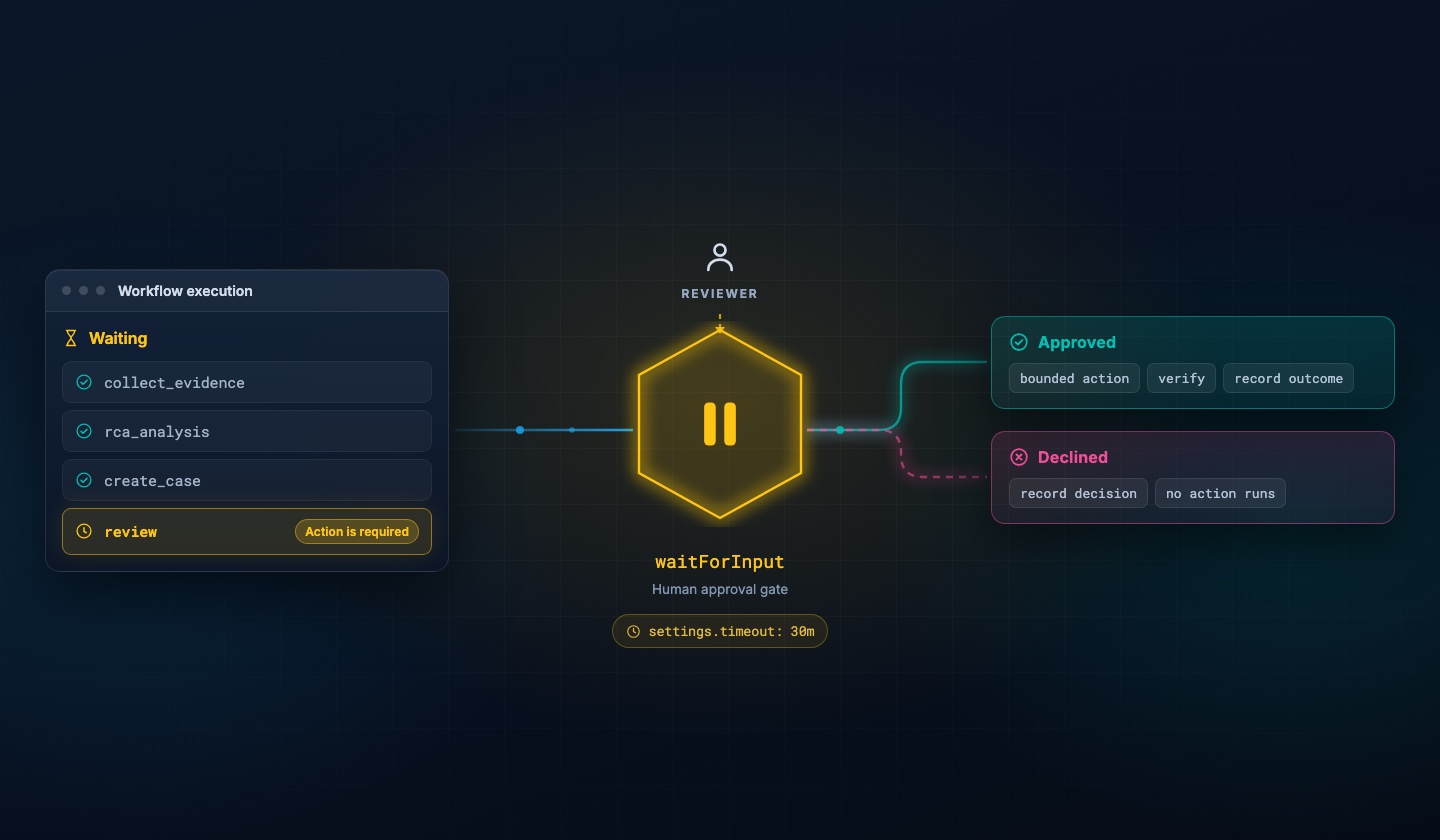
From recommendation to remediation in 4 stages: human-in-the-loop automation with Elastic Workflows
An approval gate that pauses incident response automation before the action and gives the reviewer enough evidence to decide in seconds. Whatever happens next, approved or declined, lands in one auditable record.