Telemetry Policy: change OpenTelemetry sampling and log levels at runtime, no restart
Telemetry Policy says what you want to happen and leaves each component to work out how. Change an OpenTelemetry Java agent's trace sampling to 1% and the JVM keeps serving traffic.
Elastic speaks OpenTelemetry natively. Send traces, logs, and metrics over OTLP straight into Elasticsearch, no proprietary agents required. See how it fits together, try it for free in the cloud, or run it locally.
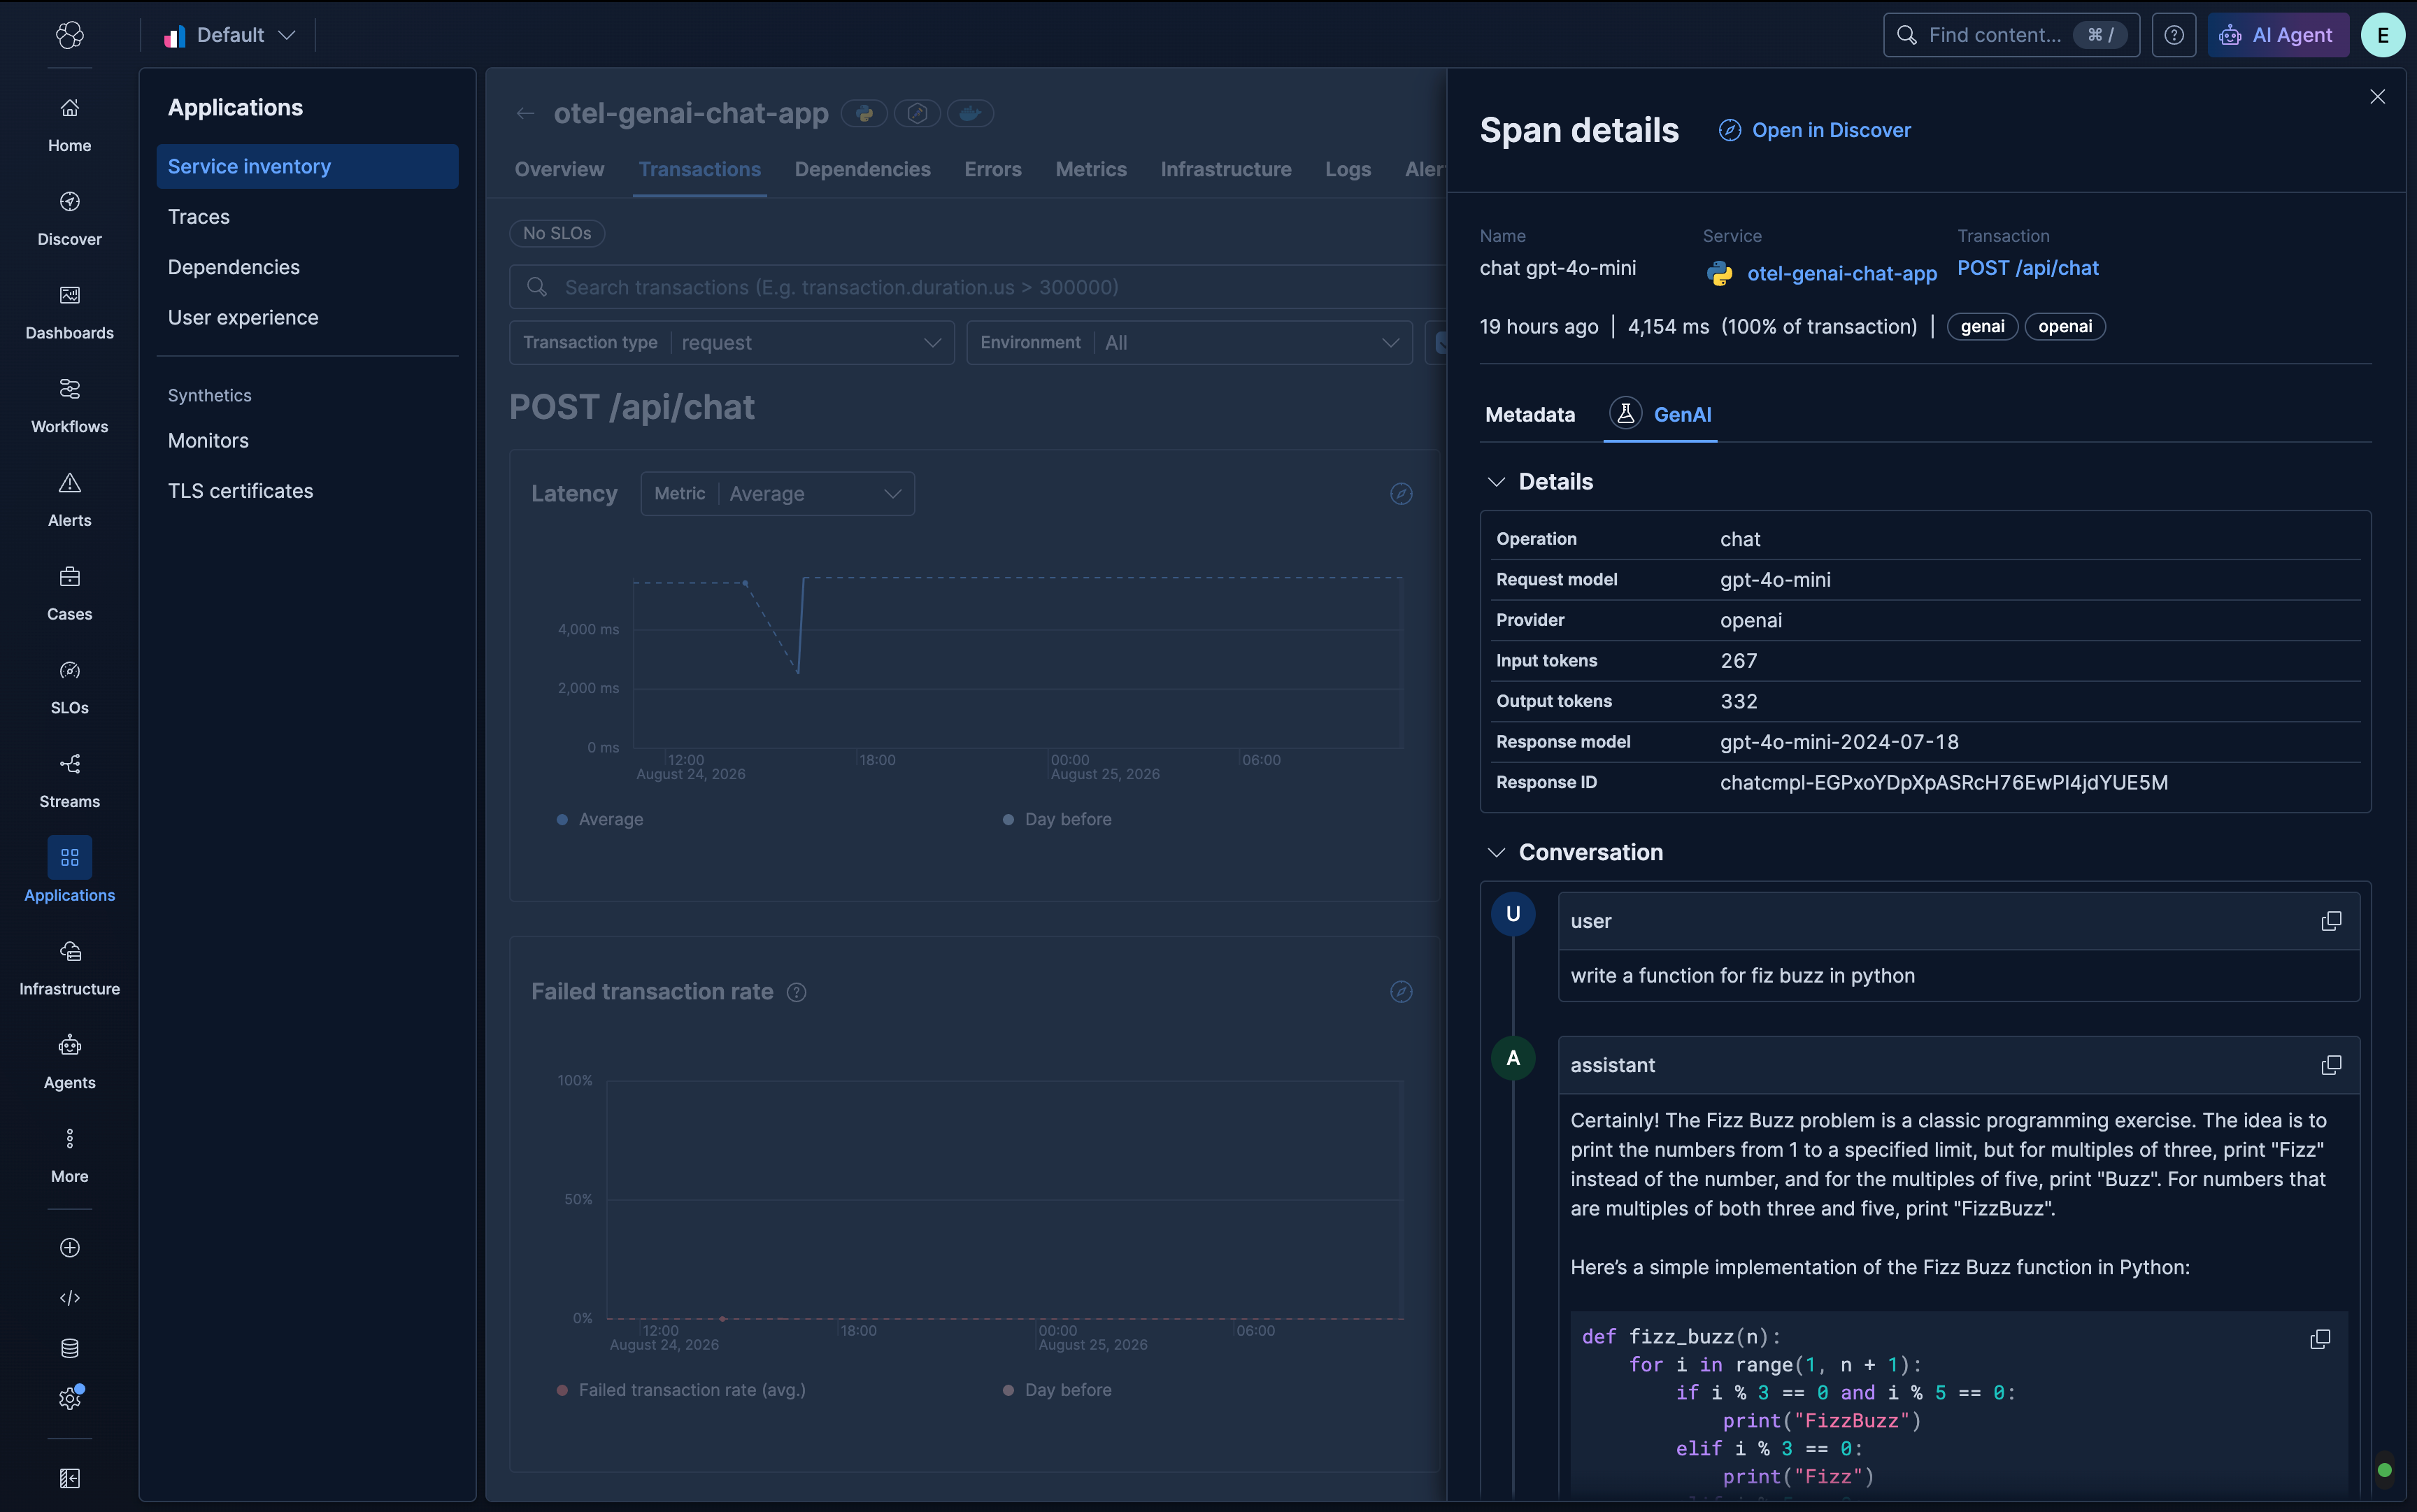
Change the trace sampling rate of a running Java application from 5% to 1% without restarting the JVM. Telemetry Policy states what you want to happen and leaves each SDK, agent or collector to work out how, so a platform team defines it once and applies it everywhere. The screenshots below show a sampling rate of 0.1 set in the Elastic APM UI, and the Java agent logging that it received and applied the value. The rest of this post covers what a policy is and where the limits are. In the next one I'll walk through the first experimental implementation in the OpenTelemetry Java contrib repo.
How to change OpenTelemetry Java agent sampling at runtime
Until now, with some proprietary exceptions, configuring that telemetry had to be done at startup of the telemetry-generating component (e.g., SDK, agent, or OpenTelemetry Collector). Telemetry Policy is the emerging standard that will allow you to reconfigure some telemetry configurations without needing to restart the telemetry-generating component.
For example, let's say you want to:
- Change the trace sampling percentage to 1% during some special peak periods (eg special sales days), but keep it at 5% at all other times.
- Change the log level (e.g., to debug level or back to info) temporarily.
- Stop some instrumentations that are active.
These are all straightforward requirements. But applying any of them until now has meant changing the configuration of the component and restarting it. For a Java application (and applications in most languages) that previously meant also restarting the application, as there was no way to change the agent configuration without restarting the JVM.
Why central management needs one policy format
Central management adds another challenge. A controlling system that requests a change such as "increase log level to debug" must know how to apply that change to every component it controls. The configuration change for a collector will not look like the change for a Java SDK, even though both are applying the same decision.
Telemetry Policy addresses both problems by separating:
- what we want to happen
- from how a particular SDK, agent, or collector makes it happen.
Using the Elastic APM UI to set the Java agent sampling rate 0.1 (10%)
Elastic APM Java agent log statements confirming that the sampling rate value of 0.1 was received and applied
What is a Telemetry Policy in OpenTelemetry?
A Telemetry Policy is an independent rule describing the behaviour a user wants.
For example:
Sample traces at 5%
A policy that says to sample traces at 5% does not say which sampler to install, where to add a processor, or how the telemetry pipeline is laid out. Those are implementation details specific to each component. The policy only states the intended result.
The draft specification defines a policy as a typed, standalone object. Each policy has an ID, a name, and one target signal such as traces, logs, or metrics. The target determines the matching fields and actions that can be used.
Here is an example of that 5% sampling policy:
{
  "id": "sample-spans-5-percent",
  "name": "Sample traces at 5%",
  "trace": {
    "match": [
      {
        "exists": true
      }
    ],
    "keep": {
      "percentage": 5.0
    }
  }
}
The policy says to match every trace and apply 5% sampling using the policy with ID sample-spans-5-percent.
Each telemetry component that understands that ID will be able to apply the policy.
Any telemetry component that doesn't understand the policy will simply ignore it.
Which settings can Telemetry Policy change at runtime?
Policies are not expected to cover every configuration, or even many configurations of each component. Telemetry Policies are not a general-purpose "reconfigure anything" tool. Policies are specific to the things that users would most like to change without restarting. For application agents, our experience at Elastic suggests there are only a dozen or so important policy types that most customers need to be able to change at runtime without restarting the application, including:
- Changing the trace sampling percentage.
- Turning individual instrumentations or all instrumentations off and on.
- Turning individual signal exporters (traces, metrics, logs, profiles) off and on.
- Changing logging level.
- Changing the configuration of a select few instrumentations.
- Such as changing which HTTP routes to ignore when creating traces (eg ignore
/heartbeat). - Or changing which methods to instrument.
- Such as changing which HTTP routes to ignore when creating traces (eg ignore
How a Telemetry Policy reaches an SDK, agent or collector
The overall telemetry policy pipeline has certain components, and at minimum covers the sequence:
Message -> Provider -> Policy -> Policy aggregator -> Implementer
A concrete example of changing the trace sampling percentage directed by central management using the Open Agent Management Protocol (OpAMP) helps to understand this flow:
| Stage | What it does | In the 5% sampling example |
|---|---|---|
| Message | Carries the requested change into the component | An OpAMP message specifying a trace sampling percentage of 5%, like the JSON above |
| Provider | Reads policies from an input stream | The OpAMP provider reads the message from the OpAMP data flow |
| Policy | The internal representation of the change | A trace-sampling-percentage-policy with a target value of 5%, which is how the ID sample-spans-5-percent is implemented in the component* |
| Policy aggregator | Combines the policy with others already applied or pending, handling source priority and merges | A pass-through, because there is only one provider |
| Implementer | Applies the change to the running component | Installs a new sampler set to 5% |
Source priority decides which policy wins when two sources disagree. A message from an OpAMP source has higher priority than one from an HTTP source.
The implementer installs a new sampler unless the sampler already running can have its sampling percentage changed at runtime, in which case it updates that one.
*Note that the policy type may become a required part of the message in future. There is currently no standard mapping from a policy ID to a policy type, so the type must either be included in the message or supplied through an external mapping.
Delivering policies over OpAMP, HTTP or a local file
Telemetry Policy does not define a new transport mechanism or protocol. Policies can be delivered through existing transports:
- OpAMP.
- HTTP.
- Local files.
- Custom sources.
The same trace sampling policy could be read from a local file while testing, supplied over HTTP, or sent from a central management system using OpAMP. OpAMP is not a requirement for Telemetry Policy; it is a supported provider and is likely to be a common transport for centrally managed systems.
Telemetry Policy status in OpenTelemetry
Telemetry Policy is currently an accepted developing project. The schema, policy types, and implementation details are still being developed before they will become accepted OpenTelemetry standards.
The first experimental Java SDK implementation
The first experimental Java SDK implementation starts with dynamically changing the trace sampling probability. This is deliberately narrow, providing a simple practical way to test the complete policy flow.
Telemetry Policy separates observability decisions from the internal configuration of the component applying them. This allows a platform team to define a policy once and apply it consistently in SDKs, agents, and collectors.
In the next blog, I'll walk through the first experimental implementation in the OpenTelemetry Java contrib repo, including how it receives policies through OpAMP and changes trace sampling in a running Java application without requiring a restart.
How helpful was this content?
Related Content
Monitor Supabase in Elastic: dashboards, alert templates, SLO templates, and zero agents
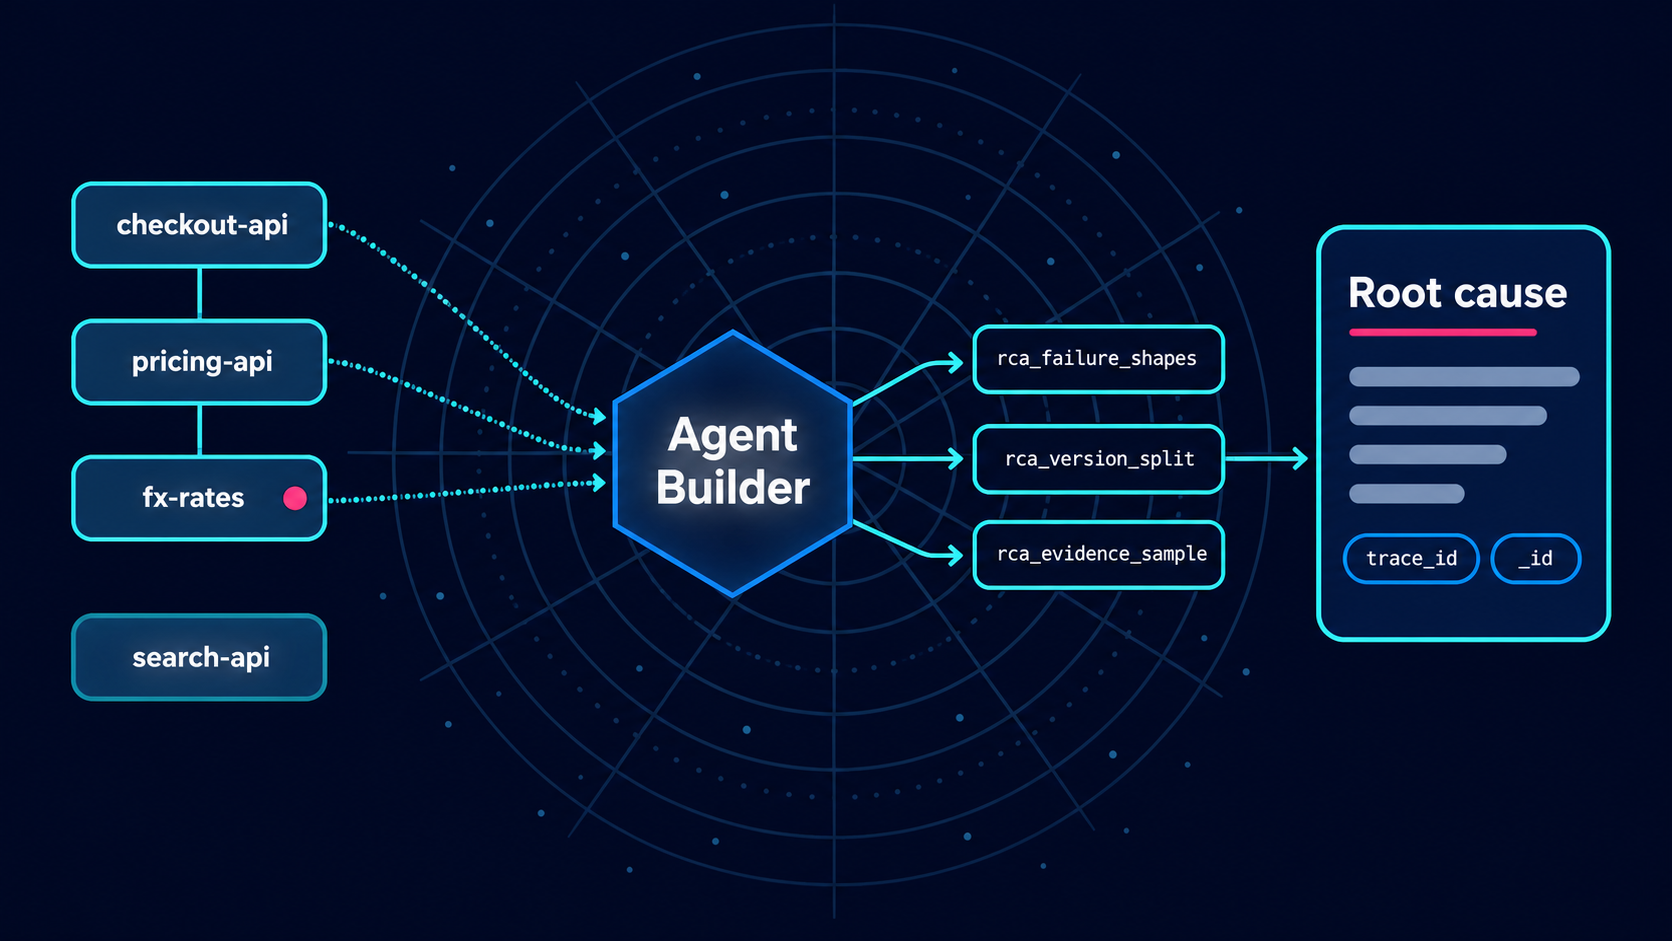
AI root cause analysis in Elastic Agent Builder that cites its evidence
Drain Vercel into Elastic: serverless observability with nothing to install