Automated root cause analysis for AWS: From a CloudWatch alert to a diagnosed incident in 36 seconds
We broke a live RDS instance with a connection leak, and the workflow came back with the Postgres refusals, the downstream 5xx and a root cause nobody had to write by hand.
Build and observe AI agents where your data already lives. Begin with Elastic Agent Builder. You can also start a free cloud trial or try Elastic on your local machine today.
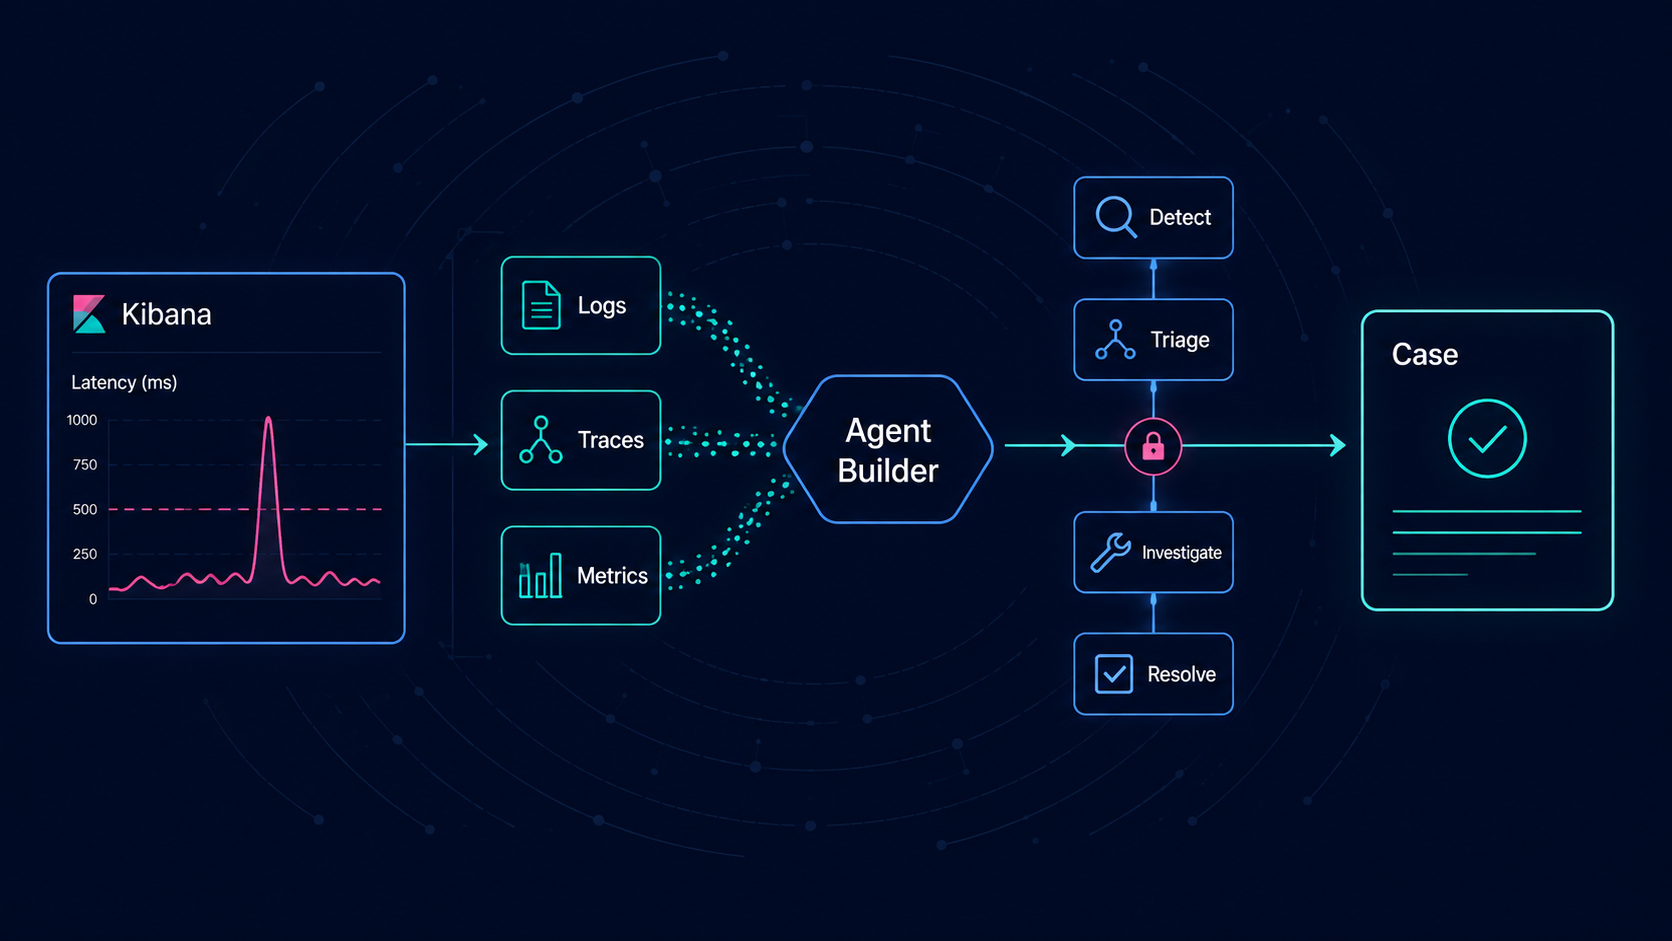
Automated root cause analysis for AWS runs the moment that an alert fires. We injected a connection leak into a live Amazon Relational Database Service (Amazon RDS) instance, and 36 seconds later, the workflow had named the cause. Connections had plateaued at a ceiling of 73, with 2,914 refusals in the Postgres log and a 40% error rate on the orders service downstream. Every number was judged against that instance's own pre-incident baseline rather than a fixed threshold. Four workflows ship in this release, alongside an agent skill for the open-ended cases. The same integrations bring dashboards, 43 alert rule templates, eight Service Level Objective (SLO) templates, and eight machine learning (ML) anomaly detection jobs for Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (Amazon ECS), AWS Lambda, Amazon RDS, Amazon Simple Queue Service (Amazon SQS), and Application Load Balancer (ALB). Plus, the collection is agentless. Enter a region and credentials into the Amazon CloudWatch (OpenTelemetry [OTel]) integration, and metrics flow without deploying anything in your account.
Earlier this year, we shipped the same model for Kubernetes. We covered dashboards, alerts, and anomaly detection in one blog post and the agentic investigation layer in another. This release applies that model to AWS. In today’s blog post, we cover both halves: the foundational assets and the workflows that consume them.
Everything here is built on CloudWatch metrics in the OTel schema, so if you’re standardizing your pipeline on OTel, these integrations meet you there. The AWS OTel integrations described in this post are generally available (GA) across Elastic Cloud Serverless (Serverless), Elastic Cloud Hosted (ECH), and self-managed deployments, and they require Kibana 9.5.0 or later. The Workflow Template Library is available in technical preview.
What complete AWS monitoring includes
A dashboard alone tells you where to look, once you already know something is wrong. The design goal for these integrations is to cover the whole operational loop: dashboards to see an overview and drill into details, alert templates to catch known-bad states, SLO templates to track reliability against a budget, ML jobs to flag deviations from each resource's own baseline, investigation workflows to run the diagnosis when something fires, and agentic skills to drive investigations from your harness of choice.
Here’s what ships for each service:
Service | Alert templates | SLO templates | ML jobs (detectors) |
EC2 | 8 | 1 | 1 (3) |
ECS | 4 | 0 | 1(2) |
Lambda | 9 | 2 | 2 (5) |
RDS | 11 | 1 | 1 (6) |
SQS | 5 | 2 | 1 (3) |
ALB | 6 | 2 | 2 (5) |
Total | 43 | 8 | 8 (24) |
The rest of this post walks through each layer using the shipped assets.
CloudWatch dashboards for EC2, ECS, Lambda, RDS, SQS, and ALB
The service packages use an overview-and-drilldown pattern: EC2, ECS, Lambda, and RDS each include an overview and a resource detail dashboard. SQS has one dashboard, and AWS Elastic Load Balancing (ELB) includes an overview plus detail dashboards for ALB, Network Load Balancer (NLB), and Gateway Load Balancer (GLB). The overview answers Across everything I run, what needs attention right now? with a status summary and a hex map colored by status or a metric that you choose (the outlier is surfaced without requiring a query) and top-N breakdowns that surface the outliers.
Detail dashboards answer the follow-up question: Why does this one look unhealthy? The layout is deliberately consistent across services, so moving from EC2 to Lambda to RDS doesn't mean relearning the interface. On the EC2 details, for example, the header identifies the instance, account, region, and current status, with direct links to the raw metrics in Discover and to the instance in the AWS console. A status timeline shows saturated, low-storage, and healthy states across the window. Below it, every core signal is clear: current value plus trend, with min, max, average, and last-value statistics and a last-versus-average delta, covering CPU, storage, read and write latency, input/output operations per second (IOPS), and network throughput. Dashboards render quickly and cheaply, thanks to our recent columnar engine for metrics.
43 CloudWatch alert templates for AWS failure modes
The six packages ship with 43 prebuilt alerting rule templates. Each is built on an Elasticsearch Query Language (ES|QL) query, which you can read and adjust, and opens as a prefilled rule form ready to connect to your notification channels.
They follow the same philosophy as the Kubernetes templates; that is, start with states that are wrong by definition. A failed EC2 instance status check is always a problem, and so is a message sitting in a dead-letter queue (DLQ); both represent failed work. A Lambda function that cannot write to its configured DLQ is silently losing events. An ALB that rejects connections has hit its connection ceiling, indicating a hard capacity failure. Templates like these need no baseline and no tuning, which is why they can fire usefully on day one.
The rest are threshold rules for saturation and latency, and the thresholds are parameters that you set against your own workload: sustained CPU on EC2 and RDS, ECS reservation and utilization for both CPU and memory, ALB 5xx rates at both the load balancer and target level, SQS backlog depth, Lambda error and throttle rates, and RDS latency and memory floors.
Taken together, the templates cover the failure modes that an AWS operator actually gets pages on: availability, saturation, latency, errors, processing lag, storage, and cost. The coverage map below shows where each service has immediate detection or an SLO outcome in this release:
Coverage map of 43 alert rule templates and eight SLO templates across the six AWS OTel integrations, organized by operational failure mode.
Each rule carries the operational judgment that an experienced AWS operator would put in a runbook comment.
EC2 Amazon Elastic Block Store (EBS) throughput. EBSReadBytes measures attached EBS volumes and not instance store. The rule points you to the local disk metrics, if that’s what your instances use.
RDS connections. CloudWatch doesn’t publish max_connections, so the threshold has to be set against your engine limit rather than a percentage.
RDS burst balance. Depleted gp2 credits typically precede the disk queue depth and latency spikes that you would otherwise page on later.
ALB tail latency. The rule watches the Maximum statistic as a tail proxy in the metrics collected by this integration.
SLO templates: Reliability targets and error budgets per service
The packages also ship SLO templates. While alerts catch the incident in front of you, SLOs tell you whether a service is meeting its reliability target over weeks and how much error budget an incident consumed:
SLO activity across Lambda, SQS, RDS, and ELB services.
Each service ships one or two SLO templates aimed at the reliability outcome that its operators actually answer for:
Request success and latency for Lambda and ALB.
Read latency for RDS.
Processing freshness (oldest message age) and an empty DLQ for SQS.
Status-check availability for EC2.
All SLOs pair a 99.5% target with a rolling 30-day window and are built to be tuned, down to documenting the queue-name pattern that the DLQ template matches. ECS ships alert templates only in this release. The coverage map above shows which outcome each service tracks.
ML anomaly detection for CloudWatch metrics
Alerts answer Is something broken?, but anomaly detection answers Is something changing? Most incidents announce themselves as change before they qualify as broken, such as the RDS instance whose freeable memory drifts down day over day, or the queue whose backlog is normal for Monday morning but not for Saturday night.
That division of labor is written into the job configurations themselves: threshold breaches belong to the alert rules, and the ML jobs cover the sub-threshold drift that precedes them. A connection count climbing toward the pool ceiling is not yet an incident, and a static threshold low enough to catch the climb would also catch every busy Tuesday. A model trained on that instance's own history catches it without the noise.
Anomaly detection job for RDS instance resources, showing detectors firing for read/write latency, CPU, disk, and memory.
This release ships eight anomaly detection jobs with 24 detectors across the six services:
RDS instance resources is the deepest job, with six detectors: connections (the pool-exhaustion trajectory), CPU, read and write latency, freeable memory, and disk queue depth, each modeled per database (DB) instance.
EC2 instance resources watches CPU, burstable credit balance draining toward exhaustion, and network egress.
ECS service resources models CPU and memory per service within its cluster, which catches slow memory-leak trajectories that survive task recycling.
Lambda gets two jobs, one for error, throttle, and dead-letter failure rates, and one for duration drift and concurrency climbing toward the account limit.
SQS queue backlog watches visible backlog, in-flight count, and oldest-message age per queue.
ALB also gets two jobs, one for load balancer and target 5xx rates, plus rejected connections, and one for target response time and unhealthy-host count per target group.
Every job surfaces the resource identifier, region, and account as influencers, so in a multi-account deployment, an anomaly is attributed to the account and region it came from rather than reported as an undifferentiated fleet-wide signal.
Automated root cause analysis: How the investigation workflows run
The investigation workflows in this release run the diagnosis itself, automatically when a linked alert fires or on demand from a manual trigger. For automatic execution, enable the workflow, declare an alert trigger, and attach the workflow to the alerting rule through a Run Workflow action. You can also run the workflow manually on demand.
The workflows are a YAML procedure with a fixed sequence of ES|QL queries and two bounded AI steps, ai.classify and ai.summarize. (For these to function, you need to configure a generative AI connector.) The queries gather the same categories of evidence on each run, while the two judgment steps remain model-driven. Each workflow queries the incident window, queries a pre-incident baseline for comparison, runs correlation queries specific to the failure mode, classifies the result, optionally reads any deployed SLO and alert status to calibrate severity, and summarizes everything into a report with a root cause, evidence, causal chain, and recommended next steps.
Workflow execution diagram and result summary (AWS RDS Connection Exhaustion Investigation).
Four workflows ship in this release, distributed through the Workflow Template Library:
RDS connection exhaustion. Decides whether a database refusing connections hit its connection ceiling or a different bottleneck (CPU, memory, IO, storage), judging each resource against its own pre-incident baseline. It then confirms the cascade rather than assuming it: the refusals in the RDS Postgres log, the 5xx responses in the dependent service's access log, and the target 5xx count on the fronting ALB.
SQS consumer lag. Decides whether a growing backlog means that the consumer cannot keep up, the consumer has stalled entirely, or producers spiked, by weighing the visible backlog, the age of the oldest message, and the sent-versus-deleted throughput, each compared against the queue's baseline rate so that a producer surge isn’t mistaken for a slow consumer.
ALB 5xx surge. Decides whether elevated 5xx responses come from the back end targets failing, from the load balancer having no healthy targets to route to, or from latency degradation.
Lambda error spike. Decides whether a function is failing outright, being throttled on concurrency, or degrading as duration climbs.
All four workflows have been validated end to end against faults injected into a live AWS environment.
From alert to root cause: An RDS connection exhaustion walkthrough
Here’s a real run against a connection-leak fault that we injected into a live AWS test environment. A connection-leak fault is a bug where an application opens connections to the database but never closes them, so open connections pile up until the database hits its limit and refuses new ones.
The workflow received the RDS instance identifier, the dependent service (orders), the fronting load balancer, and the alert timestamp as inputs, and it completed analysis in 36 seconds.
The workflow:
Queries the connection count across the incident window and checks the signature of exhaustion: a climb to a steady ceiling that plateaus.
Queries the same metric across a pre-incident baseline window to size the deviation. RDS publishes no connection-limit or max_connections metric, so exhaustion has to be inferred from the symptom, and the workflow encodes that inference.
Queries the alternative explanations (CPU, memory, IO, storage) across the incident window, so a different bottleneck isn’t misdiagnosed as pool exhaustion.
Queries those same resource metrics across the baseline window, so each one is judged against what’s normal for this instance rather than against a fixed idea of "nominal."
Correlates with 5xx counts on the fronting ALB to establish downstream impact.
Searches the RDS Postgres log for connection refusals in both windows. CloudWatch cannot show a refused connection, but Postgres logs one line per refusal, so this turns "connections were refused" from an inference into an observation. The two log checks run when the RDS log and the service's access logs are shipped to Elastic; otherwise the report marks them not available.
Counts 5xx responses per service in the application access logs, baseline against incident, so the report can name which dependent service started failing and show that it wasn’t failing before.
Uses a deterministic evidence gate to refuse to diagnose if the incident window holds no data for the instance.
Classifies the failure mode.
Reads the instance's SLOs and any alerts on it, and tags each alert as having started before or during the incident window. Only an alert that measures the classified signal and started in-window may count as corroboration; anything else is reported as preexisting context.
Summarizes, tagging every link in the causal chain as observed (with the evidence that shows it) or as inferred.
The findings:
In this run, the incident-window query found connections peaking at 73 and plateauing there, on an instance whose baseline averaged fewer than one connection.
The resource check compared every other metric with its own pre-incident baseline rather than an absolute threshold: CPU (9.3% versus 8.0%), free storage, and read latency were unchanged, while freeable memory fell from 218 MB to 79 MB, and write latency and disk-queue depth rose about threefold, indicating the footprint of 73 busy back ends rather than a competing cause. The downstream cascade was observed end to end: the Postgres log recorded 2,914 refused connections starting at 22:22:16, the orders service’s gateway access log went from zero 5xx to 2,580 of 6,505 requests beginning the same second, and the ALB counted 2,846 target 5xx across 6,826 requests.
The classify step called it connection exhaustion. The report describes the surge as a flood; whether those connections were leaked or legitimately busy is exactly what its first recommended step (inspecting pg_stat_activity) would settle.
The calibration queries then added operational context. The instance's read-latency SLO was still HEALTHY, and one [AWS RDS OTel] Freeable memory low alert was already active before the fault was injected. The report lists it as preexisting context and declines to count it as corroboration, even though memory did drop during the incident, because the alert measures the wrong signal and predates the event.
The report that the workflow produces is the answer, with the evidence attached:
ROOT CAUSE HYPOTHESIS
A connection flood on fis-orders-db-20260616081655544800000016 exhausted all available PostgreSQL connection slots, which likely caused the orders service to return errors to its callers.


EVIDENCE
Connections peaked at 73 vs a baseline average of 0.13 — roughly 560x above normal. The series plateaued at 73, indicating the instance hit its connection ceiling. During the incident 2,914 connection refusals were recorded in the Postgres log vs zero in the baseline; the first refusal occurred at 22:22:16 UTC. The sample log line reads: "FATAL: remaining connection slots are reserved for roles with privileges of the 'rds_reserved' role" — a definitive RDS connection exhaustion message.


Resource metrics vs their own baselines:
- CPU: 9.25% incident vs baseline 8.02% — effectively unchanged.
- Freeable memory: min 79 MB incident vs baseline min 218 MB and baseline avg 227 MB — a notable drop (~65% below baseline min), but 79 MB remained available and memory did not approach zero; this is likely a consequence of the connection flood, not a primary failure.
- Free storage: 18,318,249,984 bytes vs baseline 18,318,757,888 bytes — unchanged (sub-1 MB difference).
- Read latency: max 0.00123s vs baseline 0.002s — unchanged (slightly lower).
- Write latency: max 0.02149s vs baseline 0.006597s — modestly elevated (~3x) but not sustained or extreme.
- Disk queue: max 0.241 vs baseline 0.075 — elevated ~3x, consistent with connection-flood I/O pressure, not a primary storage issue.


Access logs for /ecs/fis-gateway (orders' gateway) show 2,580 HTTP 5xx errors out of 6,505 requests during the incident vs zero 5xx out of 7,681 requests at baseline. First 5xx occurred at 22:22:16 UTC — the same timestamp as the first connection refusal. ALB recorded 2,846 target 5xx errors across 6,826 requests; maximum target response time was 0.318s.


SEVERITY & CALIBRATION
The single alert on this resource is "[AWS RDS OTel] Freeable memory low," which was already active at 22:03:08 UTC — before the incident window. It measures freeable memory, not DatabaseConnections, so it does not corroborate the connection exhaustion classification regardless of timing. Freeable memory did drop during the incident window (79 MB vs baseline min 218 MB), but that movement is a downstream consequence of the connection flood; the alert pre-dates the incident and is non-corroborating, and its prior firing likely reflects standing memory pressure unrelated to this event.


The read-latency SLO is HEALTHY (SLI 0.9999, 2.3% error budget consumed) — user-facing read latency impact is not visible in this window.


The classification rests on raw metrics and Postgres log evidence alone, with no SLO or alert corroboration.


Severity: HIGH — over 2,900 connection refusals produced a ~40% 5xx error rate on the orders gateway during the incident window.


CAUSAL CHAIN
Connection count surged to 73, ~560x above baseline average [observed: peak connections 73 vs baseline avg 0.13]
→ All non-reserved PostgreSQL connection slots were exhausted [observed: 2,914 "rds_reserved" refusals in Postgres log, 0 in baseline]
→ New inbound connections from the orders service were rejected [observed: first refusal at 22:22:16 UTC]
→ orders gateway returned HTTP 5xx errors to clients [observed: 2,580 5xx / 6,505 requests in /ecs/fis-gateway, first 5xx at 22:22:16 UTC; ALB target 5xx = 2,846]
→ Freeable memory fell to 79 MB (vs baseline min 218 MB) under connection pressure [observed: resource metrics; pre-existing memory alert does not corroborate this event]


RECOMMENDED NEXT STEPS
1. Query pg_stat_activity on the instance to identify which host(s) and application users hold the excess connections and whether any are idle-in-transaction or leaked.
2. Review connection-error and pool-timeout lines in the orders service application logs to confirm it was exhausting its pool rather than a third party.
3. Check distributed traces for the incident window to correlate 5xx responses with database timeout errors in the orders service.
4. Drain or forcibly close leaked/idle connections (pg_terminate_backend) to restore headroom immediately.
5. Restart the orders service to reset its connection pool if leaked connections cannot be reclaimed in place.
6. Review max_connections on the RDS instance and the orders service pool size configuration; increase the pool ceiling with appropriate headroom and add a connection timeout/backoff to prevent unbounded growth.
7. Investigate the root cause of the leak (missing pool.release() calls, long-running transactions, or misconfigured pool max) and fix in code.
8. Evaluate the pre-existing freeable memory alert separately; with only 79 MB remaining under load, instance sizing or parameter tuning may be warranted.


DOWNSTREAM IMPACT
- orders service (via /ecs/fis-gateway): 2,580 HTTP 5xx errors (~40% error rate) during the incident window — observed.
- End users of the orders service experienced request failures — observed (ALB 2,846 target 5xx).
- Read latency SLO remained healthy; no storage or CPU impact on downstream consumers — observed.
Why a workflow and not an AI agent?
We measured it using a custom internal harness by injecting failures with known causes into a live AWS environment, freezing the telemetry, and applying a spectrum of approaches to investigate the same data: bare agents, agents with increasingly specific instructions, and workflows. All approaches investigated the same injected faults, scored against known ground truth. On a frontier model, the approaches were comparable; on a small model, the workflow held near 0.87 while a bare agent fell to 0.07, because only the workflow's two bounded judgment steps depend on the model. We’ll publish the full methodology and quantitative results, including model selection, scoring, repetition, and contamination controls, in a follow-up post.
AI root cause analysis for open-ended investigations: The csp-investigation skill
Although it’s helpful to use workflows to automate deterministic paths, not every investigation can be expected to be that clean, so we also built a companion agent skill for the open-ended case; that is, an engineer asking What's wrong with this RDS instance? with only the resource name and a rough time. The skill gives a model the same kind of reasoning that the workflows encode, enabling flexible investigations.
The csp-investigation skill guides the investigating large language model (LLM) to compare a cloud resource against its own baseline, divide error counts by volume to get a rate, rule out a coincidental incident firing in the same window, and treat "nothing is wrong here" as a valid answer.
We wrote it from actual measurements. We ran real injected AWS incidents through weak and strong models with no guidance and recorded where they went wrong, and we added only the guidance that improved the score. On one Lambda error-rate incident, a weak model scored 0.06 out of 1 without the skill and 0.44 with it. When asked to check a resource that was actually healthy, with no alert firing, it went from 0.06 to 0.74, showing that the skill was what kept the model from inventing a failure that isn't there. The skill, named csp-investigation, uses a router pattern at the top to direct models to the appropriate cloud service provider context (currently just AWS, but Google Cloud Platform [GCP] and Azure will be added soon).
Reasoning and strategy that the csp-investigation skill gives a model, for a fired alert or an open-ended What’s wrong with this resource? prompt.
Getting started with AWS monitoring in Elastic
Step 1: Connect your AWS account to Elastic
On the Add Data page, from the quickstart paths, select Cloud and then AWS. This brings you to the AWS CloudWatch (OpenTelemetry) input integration (aws_cloudwatch_input_otel) with a choice of two deployment paths. The six service packages are content only, and adding the input installs them automatically, so the dashboards, alert rule templates, and SLO templates for the services that you enable are in place before the first metric arrives. Use AWS credentials scoped to read-only CloudWatch access. At minimum, the integration requires cloudwatch:ListMetrics and cloudwatch:GetMetricData.
The Elastic Managed Integration path is agentless. Elastic runs the collection for you, using the OpenTelemetry Collector's CloudWatch metrics receiver under the hood. Enter an AWS region and credentials (an access key and secret, or temporary AWS Security Token Service [STS] credentials with a session token), and metrics begin flowing into the metrics-aws.*.otel-* data streams. There’s nothing to deploy, patch, or scale in your account, and the gap between installing the integration and seeing data is filling in a form.
The agent-based path deploys Elastic Agent in your environment to run the same collection. Choose it if you already operate agents or need control over where collection runs.
Next, specify the AWS region and choose an authentication method: an access key ID and secret access key, temporary STS credentials with a session token, or identity and access management (IAM) role assumption with an optional external ID. Fleet stores sensitive integration-policy values separately from the rest of the policy and hides them in both the Fleet UI and rendered agent policy.
Enable the service namespaces you need: EC2, ECS, Lambda, RDS, SQS, and the load balancer family. Within each enabled namespace, the integration automatically discovers CloudWatch metrics up to the configured Autodiscover Limit. Review that limit and the collection interval before enabling collection because CloudWatch charges per metric requested. From the same page, you can also launch the EDOT Cloud Forwarder, an AWS CloudFormation stack that collects ELB access logs from Amazon S3.
Adding the AWS CloudWatch OpenTelemetry integration in Elastic with the agentless Elastic Managed deployment path selected.
Step 2: Enable the alert rule templates
Open the Alert Rules management page, click Create rule, and find the templates relevant to your environment. Then confirm or define your thresholds, and connect your notification channel.
Step 3: Create SLOs from the templates
Open SLOs, create them from the templates, and adjust targets and thresholds to your Service Level Agreements (SLAs).
Step 4: Enable the ML anomaly detection jobs
In Kibana, open Machine Learning, go to Anomaly Detection, and select Manage jobs. Then, choose Create job and pick the metrics-* data view. The supplied AWS anomaly detection jobs appear there, ready to enable.
Step 5: Install the investigation workflows
The four AWS investigations are published as templates in the Workflow Template Library, the public catalog that the Workflows app in Kibana browses and installs from. (The library is in technical preview in Kibana 9.5.0.) Instructions for enabling the template library can be found here. Open Workflows in Kibana, find the AWS investigation templates, and install or remix the ones for the services you run. Each arrives as a saved workflow in your Kibana, ready to link to its corresponding alert rule so the investigation runs when the alert fires.
Browse, install, and remix workflows from the Elastic Workflow Template Library, directly from Kibana.
What we're publishing next
We look forward to sharing the skill-versus-workflow experiment behind these investigation workflows in a follow-up post, with the full methodology and results.
If you run these services on AWS today, tell us which failure modes you still investigate by hand and which of them you’d trust a workflow to diagnose first. That feedback directly shapes which investigations we build next. You can join the Elastic community discussion here.
The release and timing of any features or functionality described in this post remain at Elastic's sole discretion. Any features or functionality not currently available may not be delivered on time or at all.
How helpful was this content?
Related Content
Collecting rootless Podman logs with Elastic Agent: the CRI parser, user-scoped paths, and the Podman socket
Your AI agent needs an alibi: Observability and audit trails for Agent Builder in Elastic
From recommendation to remediation in 4 stages: human-in-the-loop automation with Elastic Workflows
From alert to root cause in 3 minutes: automated root cause analysis with Elastic Agent Builder