
Elasticsearch simdvec deep-dive: Walking the memory tightrope to 2x better vector throughput
A deep dive into four optimizations (cascade unrolling, batch prefetching, dim-axis unrolling, a structural refactor) that pushed Elasticsearch simdvec to 2x vector throughput by working with the CPU, not against it.
Elasticsearch DiskBBQ: 40% faster vector scoring with native SIMD Blocks
A deep dive into how DiskBBQ's block layout, doc ID compression modes and native SIMD kernels combine to deliver 40% improved vector scoring throughput for DiskBBQ in 9.4.

Multilingual image search with Jina CLIP v2 and Elasticsearch
Build a multilingual image search system using Jina CLIP v2 and Elasticsearch. Query your image collection in 89 languages with no translation pipeline, and use Matryoshka Representations to cut index size by 75%

How we doubled vector search throughput on Elasticsearch Serverless
How we brought Elasticsearch's native SIMD scoring engine to serverless, and why serverless is where vector search innovation happens next.
Cutting Elasticsearch DiskBBQ query quantization time by 5x
See how asymmetric quantization cuts DiskBBQ query quantization overhead from about 20% to 4% with little recall impact.
Up to 3x faster stored-vector queries in Elasticsearch
Elasticsearch 9.4 provides a simpler way to search with vectors stored in an Elasticsearch index, with up to 3x lower latency.
Elasticsearch Vector DiskBBQ filter search is now 3–5x faster
Learn how Elasticsearch 9.4 makes restrictive filtered DiskBBQ vector search 3–5x faster and more stable by avoiding wasted centroid and postings-list work when selectivity is high.
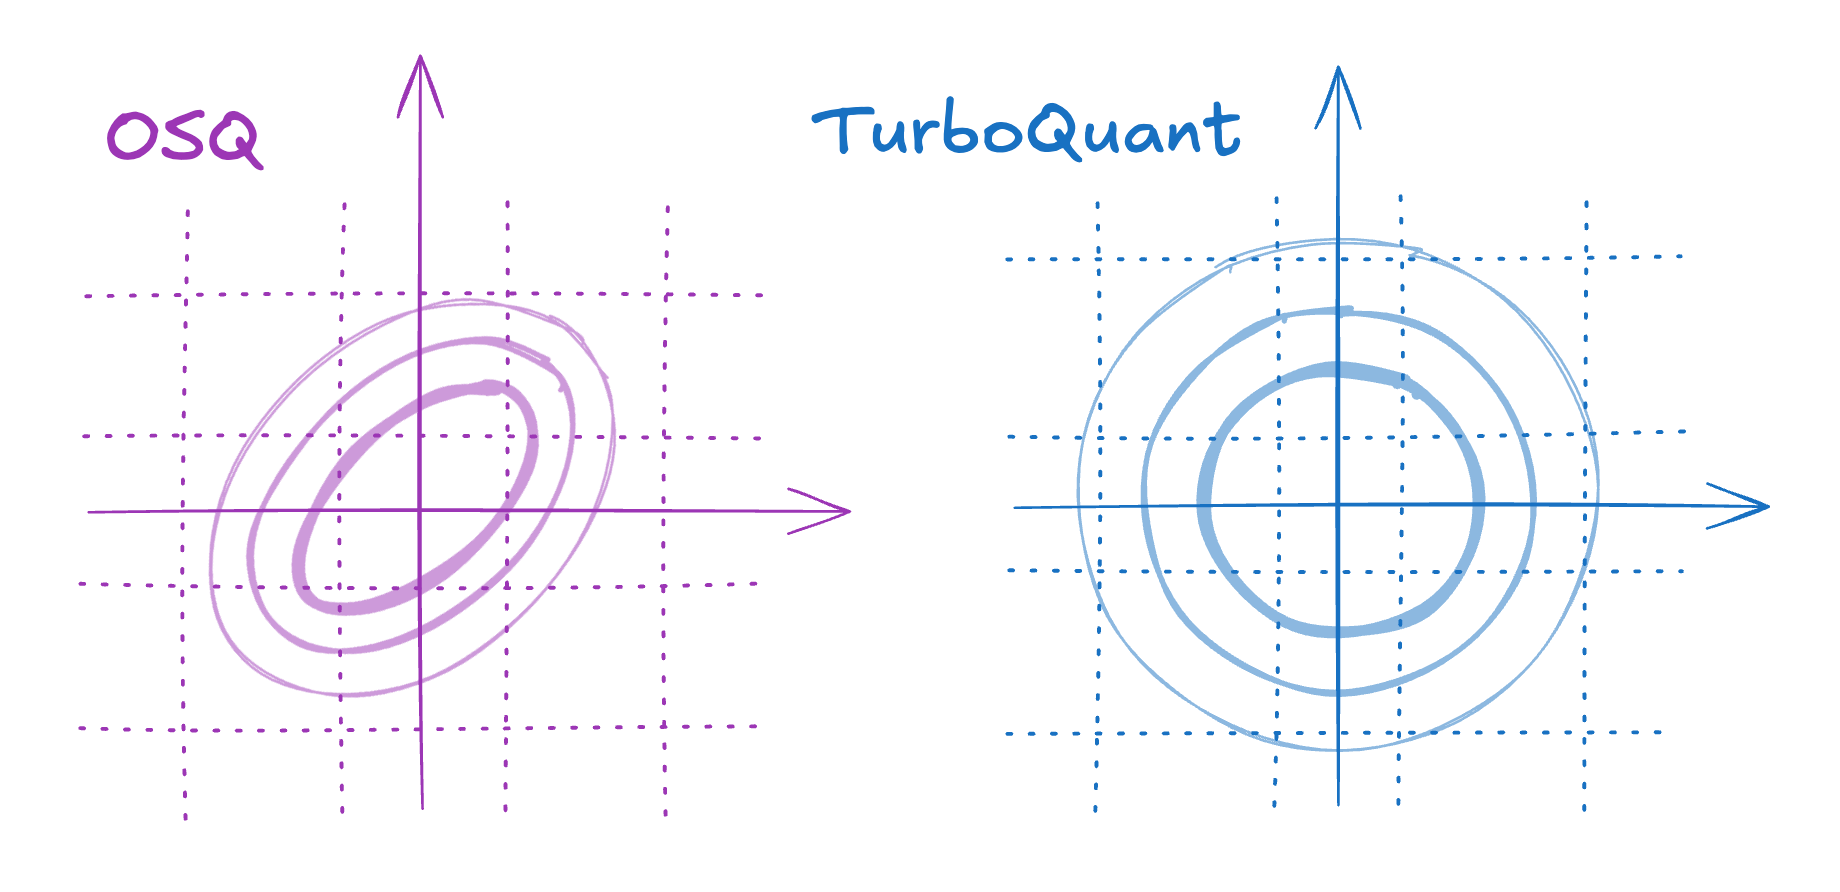
Elasticsearch's BBQ vs. TurboQuant: 10–40× faster on CPU and lower ranking noise
A head-to-head look at Elasticsearch BBQ and TurboQuant, including throughput, ranking accuracy, and why uniform quantization wins for CPU vector search with up to 40× faster comparisons and smaller ranking noise.
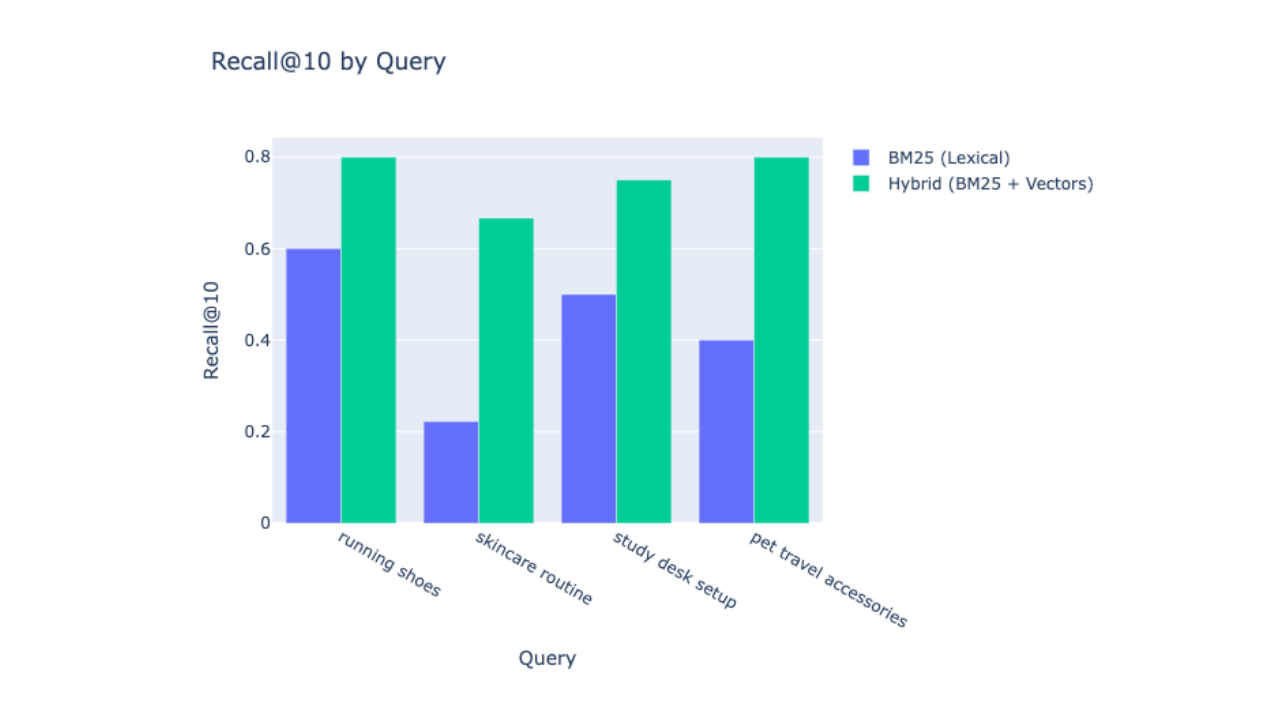
How to measure and improve Elasticsearch search recall: from 0.43 to 0.75 with hybrid search
Learn how to measure and improve search recall in Elasticsearch by combining BM25 lexical search with Jina AI vector embeddings, using the rank_eval API to validate the improvement with real numbers.

Preconditioning Vectors: Making Elasticsearch VectorDB Better Binary Quantization work for every vector
Modern quantization techniques can hurt recall when using older models or embeddings that aren’t normally distributed. Learn how preconditioning fixes these vectors through random orthogonal projection, making BBQ more effective and recovering recall.
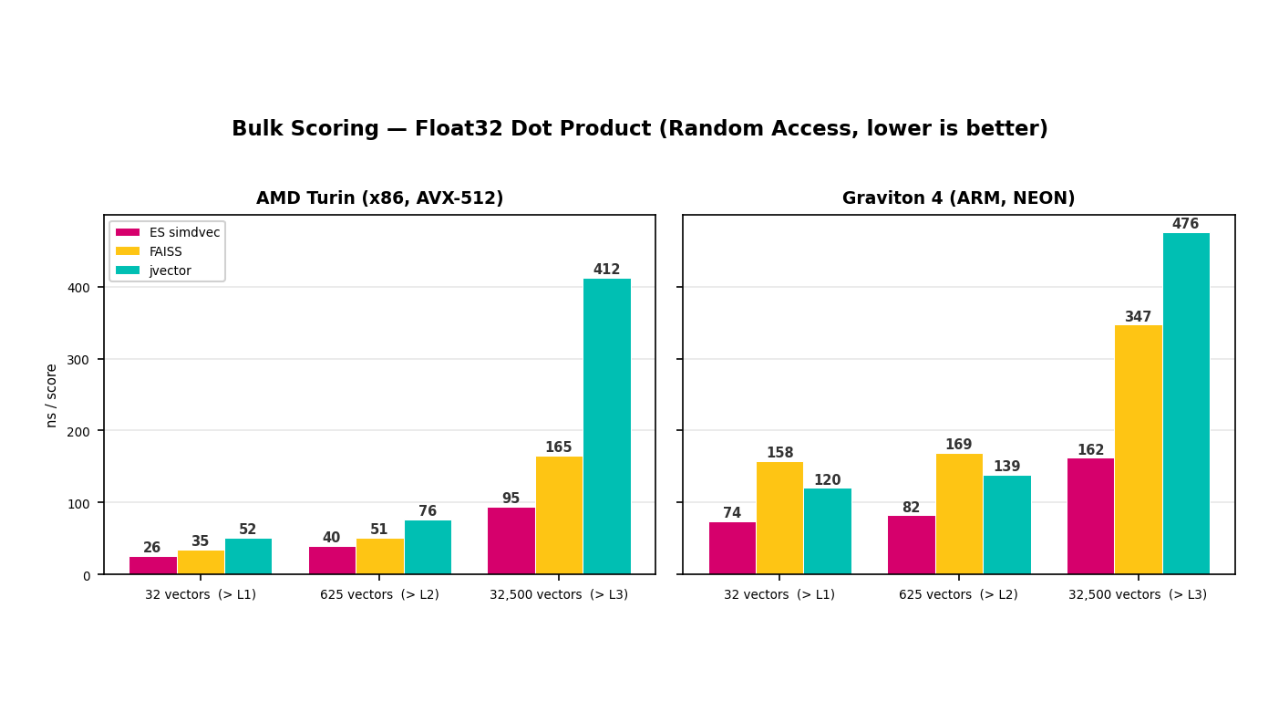
How we built Elasticsearch simdvec to make vector search one of the fastest in the world
How we built Elasticsearch simdvec, the hand-tuned SIMD kernel library behind every vector search query in Elasticsearch.
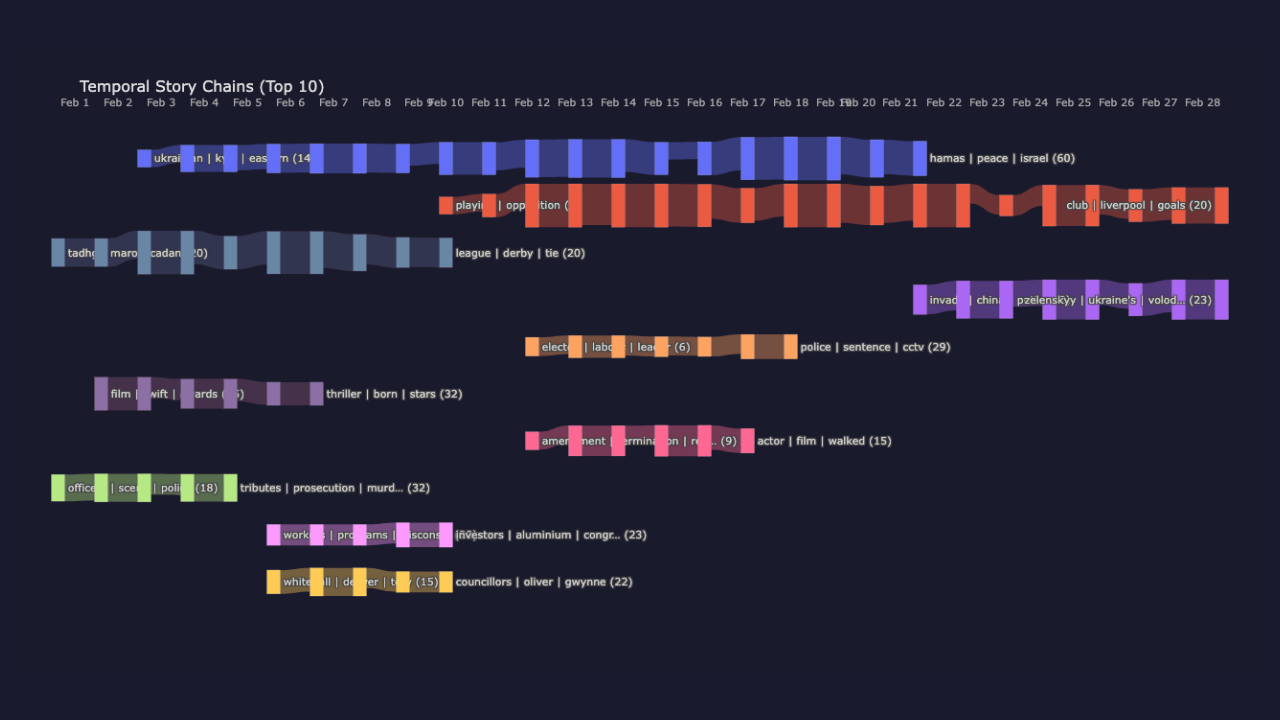
Unsupervised document clustering with Elasticsearch + Jina embeddings
A practical, reproducible approach to unsupervised document clustering with Elasticsearch and Jina embeddings.