
Chris Hegarty
Principal Software Engineer II
Chris is a committer and PMC member on the Apache Lucene Project, as well as a committer and reviewer in OpenJDK.

Trust, but benchmark: How we let an AI agent optimize Elasticsearch
We share how we built a harness that automatically identifies and implements optimizations in the Elasticsearch codebase.

A simdvec deep-dive: How Elasticsearch uses neural-net and video-codec CPU instructions for vector search
Four ways Elasticsearch's vector search engine reuses neural-network, video-codec and cryptography CPU instructions for up to 6x speedups; with the math, the failed attempts and the benchmarks.

Elasticsearch simdvec deep-dive: Walking the memory tightrope to 2x better vector throughput
A deep dive into four optimizations (cascade unrolling, batch prefetching, dim-axis unrolling, a structural refactor) that pushed Elasticsearch simdvec to 2x vector throughput by working with the CPU, not against it.

How we doubled vector search throughput on Elasticsearch Serverless
How we brought Elasticsearch's native SIMD scoring engine to serverless, and why serverless is where vector search innovation happens next.
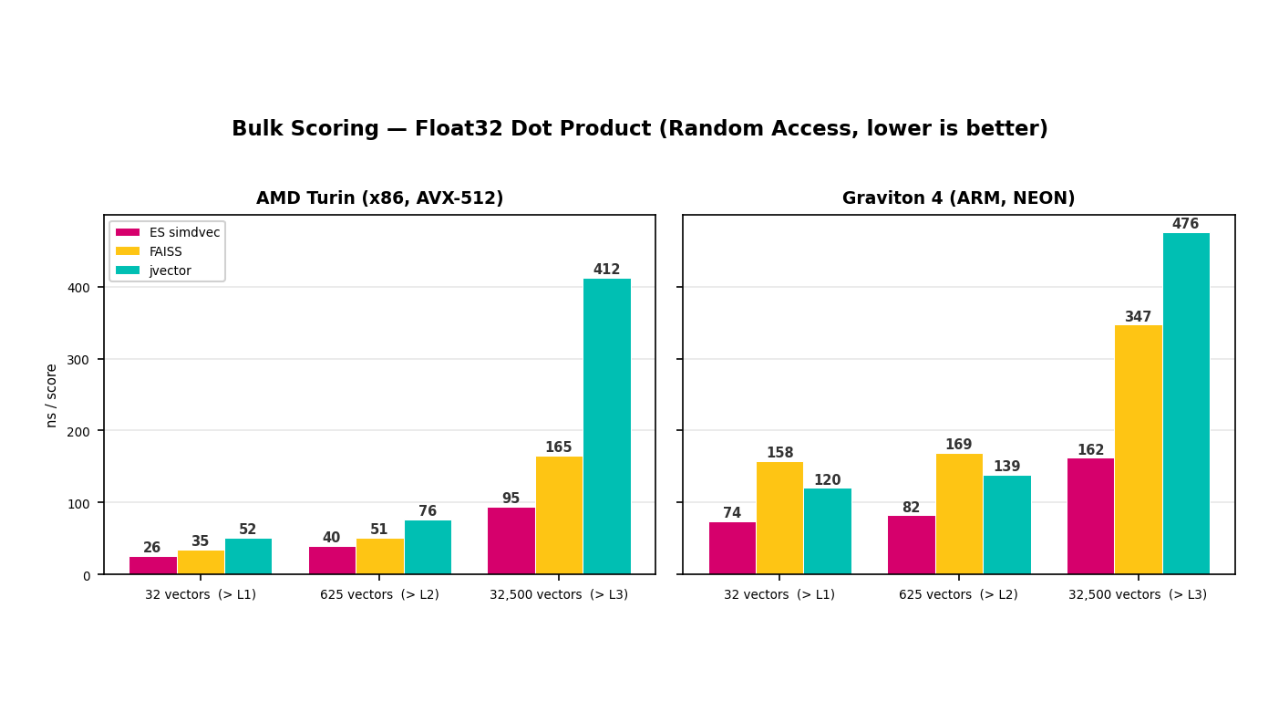
How we built Elasticsearch simdvec to make vector search one of the fastest in the world
How we built Elasticsearch simdvec, the hand-tuned SIMD kernel library behind every vector search query in Elasticsearch.
Apache Lucene 2025 wrap-up
2025 was a stellar year for Apache Lucene; here are our highlights.
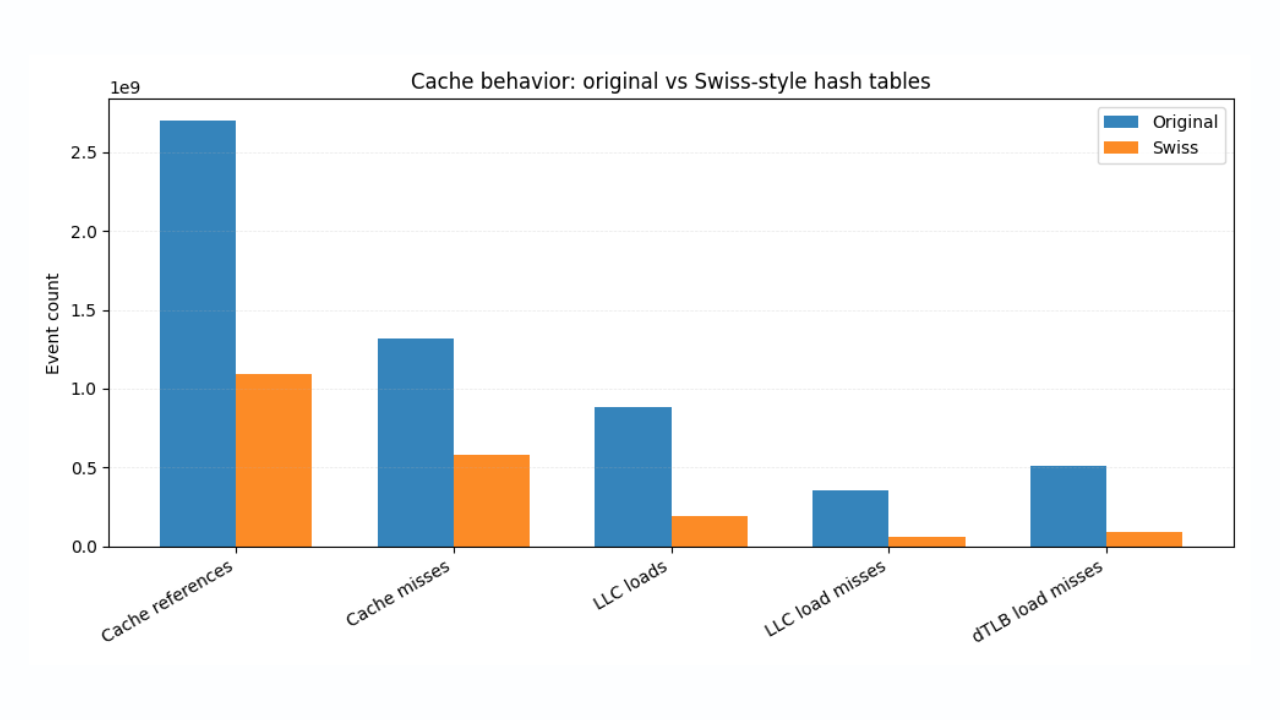
Faster ES|QL stats with Swiss-style hash tables
How Swiss-inspired hashing and SIMD-friendly design deliver consistent, measurable speedups in Elasticsearch Query Language (ES|QL).

Up to 12x Faster Vector Indexing in Elasticsearch with NVIDIA cuVS: GPU-acceleration Chapter 2
Discover how Elasticsearch achieves nearly 12x higher indexing throughput with GPU-accelerated vector indexing and NVIDIA cuVS.
Exploring GPU-accelerated vector search in Elasticsearch with NVIDIA: Chapter I
Powered by NVIDIA cuVS, the collaboration looks to provide developers with GPU-acceleration for vector search in Elasticsearch.

Lucene Wrapped 2024
2024 has been another major year for Apache Lucene. In this blog, we’ll explore the key highlights.

Smokin' fast BBQ with hardware accelerated SIMD instructions
How we optimized vector comparisons in BBQ with hardware accelerated SIMD (Single Instruction Multiple Data) instructions.

Making Lucene faster with vectorization and FFI/madvise
Discover how modern Java features, including vectorization and FFI/madvise, are speeding up Lucene's performance.

Optimizing vector distance computations with the Foreign Function & Memory (FFM) API
Learn how to optimize vector distance computations using the Foreign Function & Memory (FFM) API to achieve faster performance.

Understanding fused multiply-add (FMA) within vector similarity computations in Lucene
Learn how to use fused multiply-add (FMA) within vector similarity computations in Lucene and discover how FMA can improve performance.