0.35% trained, 100% competitive: the frozen-tower architecture behind jina-embeddings-v5-omni
The latest jina embeddings model generates multimodal embeddings for text, images, video and audio, competing with models nearly 6x its size on vector search while training just 0.35% of the weights.
17% faster search, zero config: auto-calibrating vector quantization in Elasticsearch
Automatic calibration at merge time picks vector quantization parameters for each segment by predicting recall from a small sample. Here's how we built it into Elasticsearch's merge path.
56% faster, up to 50% better retrieval performance: What's inside Jina's new 600 million parameter listwise reranker
Jina Reranker 3.5 beats v3 by 50%+ on case law, closes the gap with models 7x its size on legal, medical, and financial benchmarks, and beats them outright on structured data. It's a drop-in replacement for v3, with no API changes.
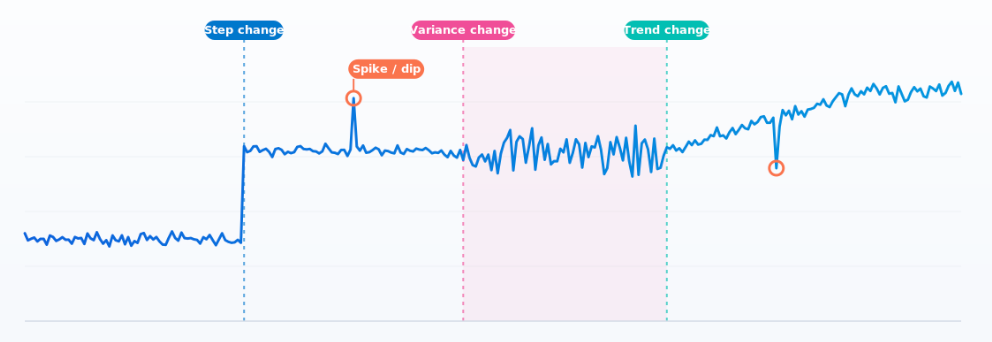
How Elasticsearch detects multiple change points in time series with 0.99 recall
ES|QL's CHANGE_POINT command finds structural shifts, variance changes and spikes in any metric in ~1ms, without tuning anything per series.
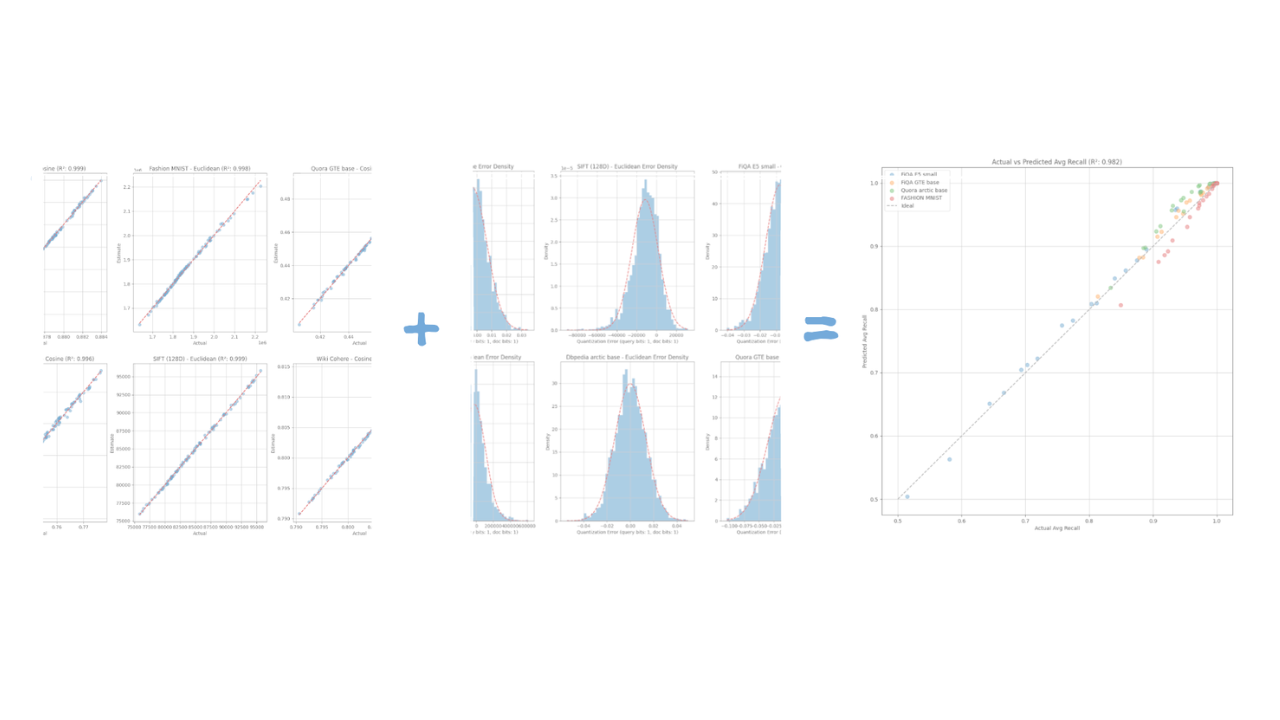
How Elasticsearch auto-tunes vector quantization to hit your recall target
Learn the geometric model that lets Elasticsearch predict recall with R² > 0.98 accuracy and auto-select vector quantization parameters from a small data sample.

How BBQ shrinks Jina v5 embeddings by 29x without losing recall in Elasticsearch
A hands-on test comparing BBQ and float32 vector indices in Elasticsearch, measuring memory, disk and recall@10 across five languages.
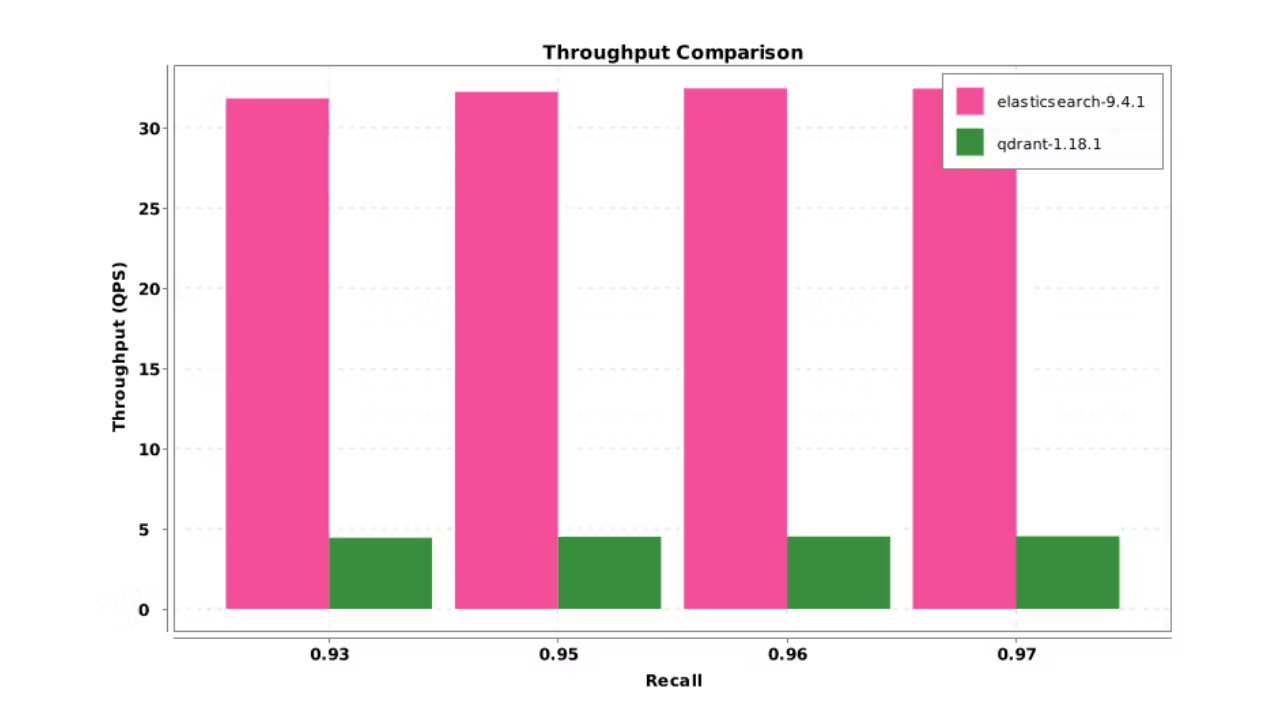
Elasticsearch DiskBBQ delivers 7x faster vector search than Qdrant on network-attached storage
Elasticsearch DiskBBQ achieves up to 7x higher vector search throughput than Qdrant at comparable recall on network-attached storage. Explore the benchmark methodology and full results.

Is your ML job's datafeed losing a race it cannot win?
Learn how switching from scroll-based to aggregation-based datafeeds optimizes machine learning jobs for large-scale deployments.
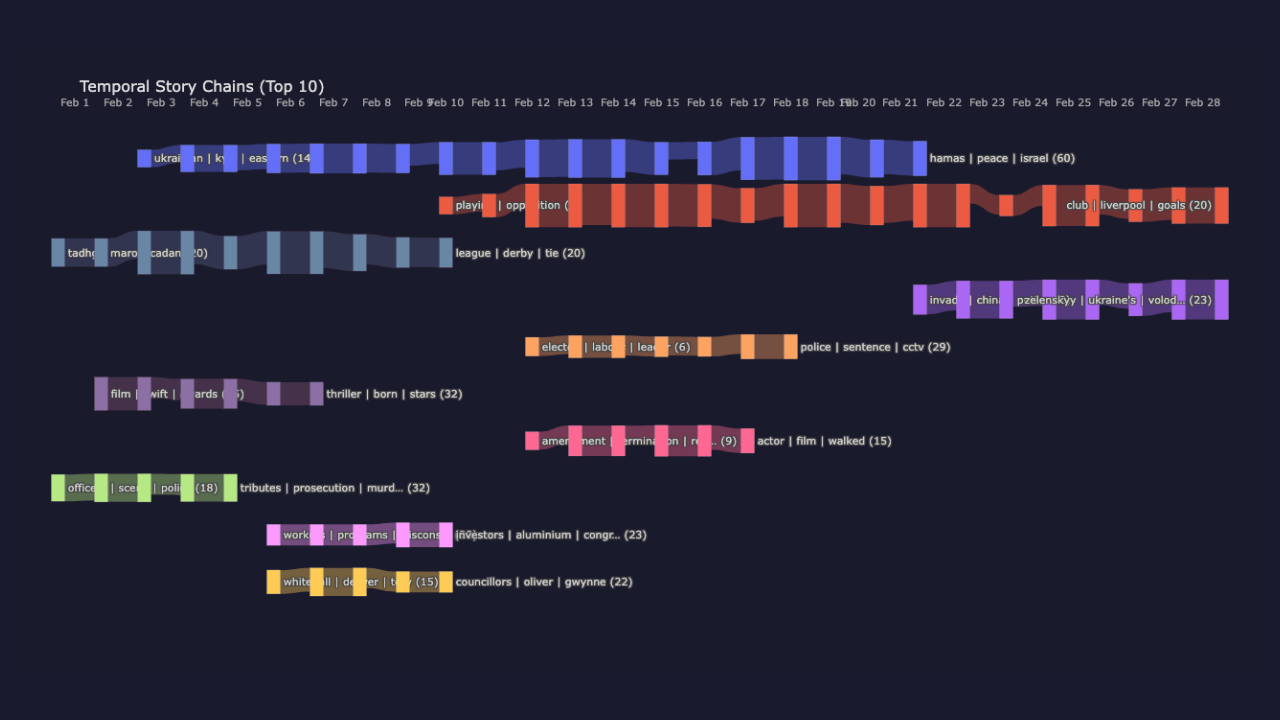
Unsupervised document clustering with Elasticsearch + Jina embeddings
A practical, reproducible approach to unsupervised document clustering with Elasticsearch and Jina embeddings.
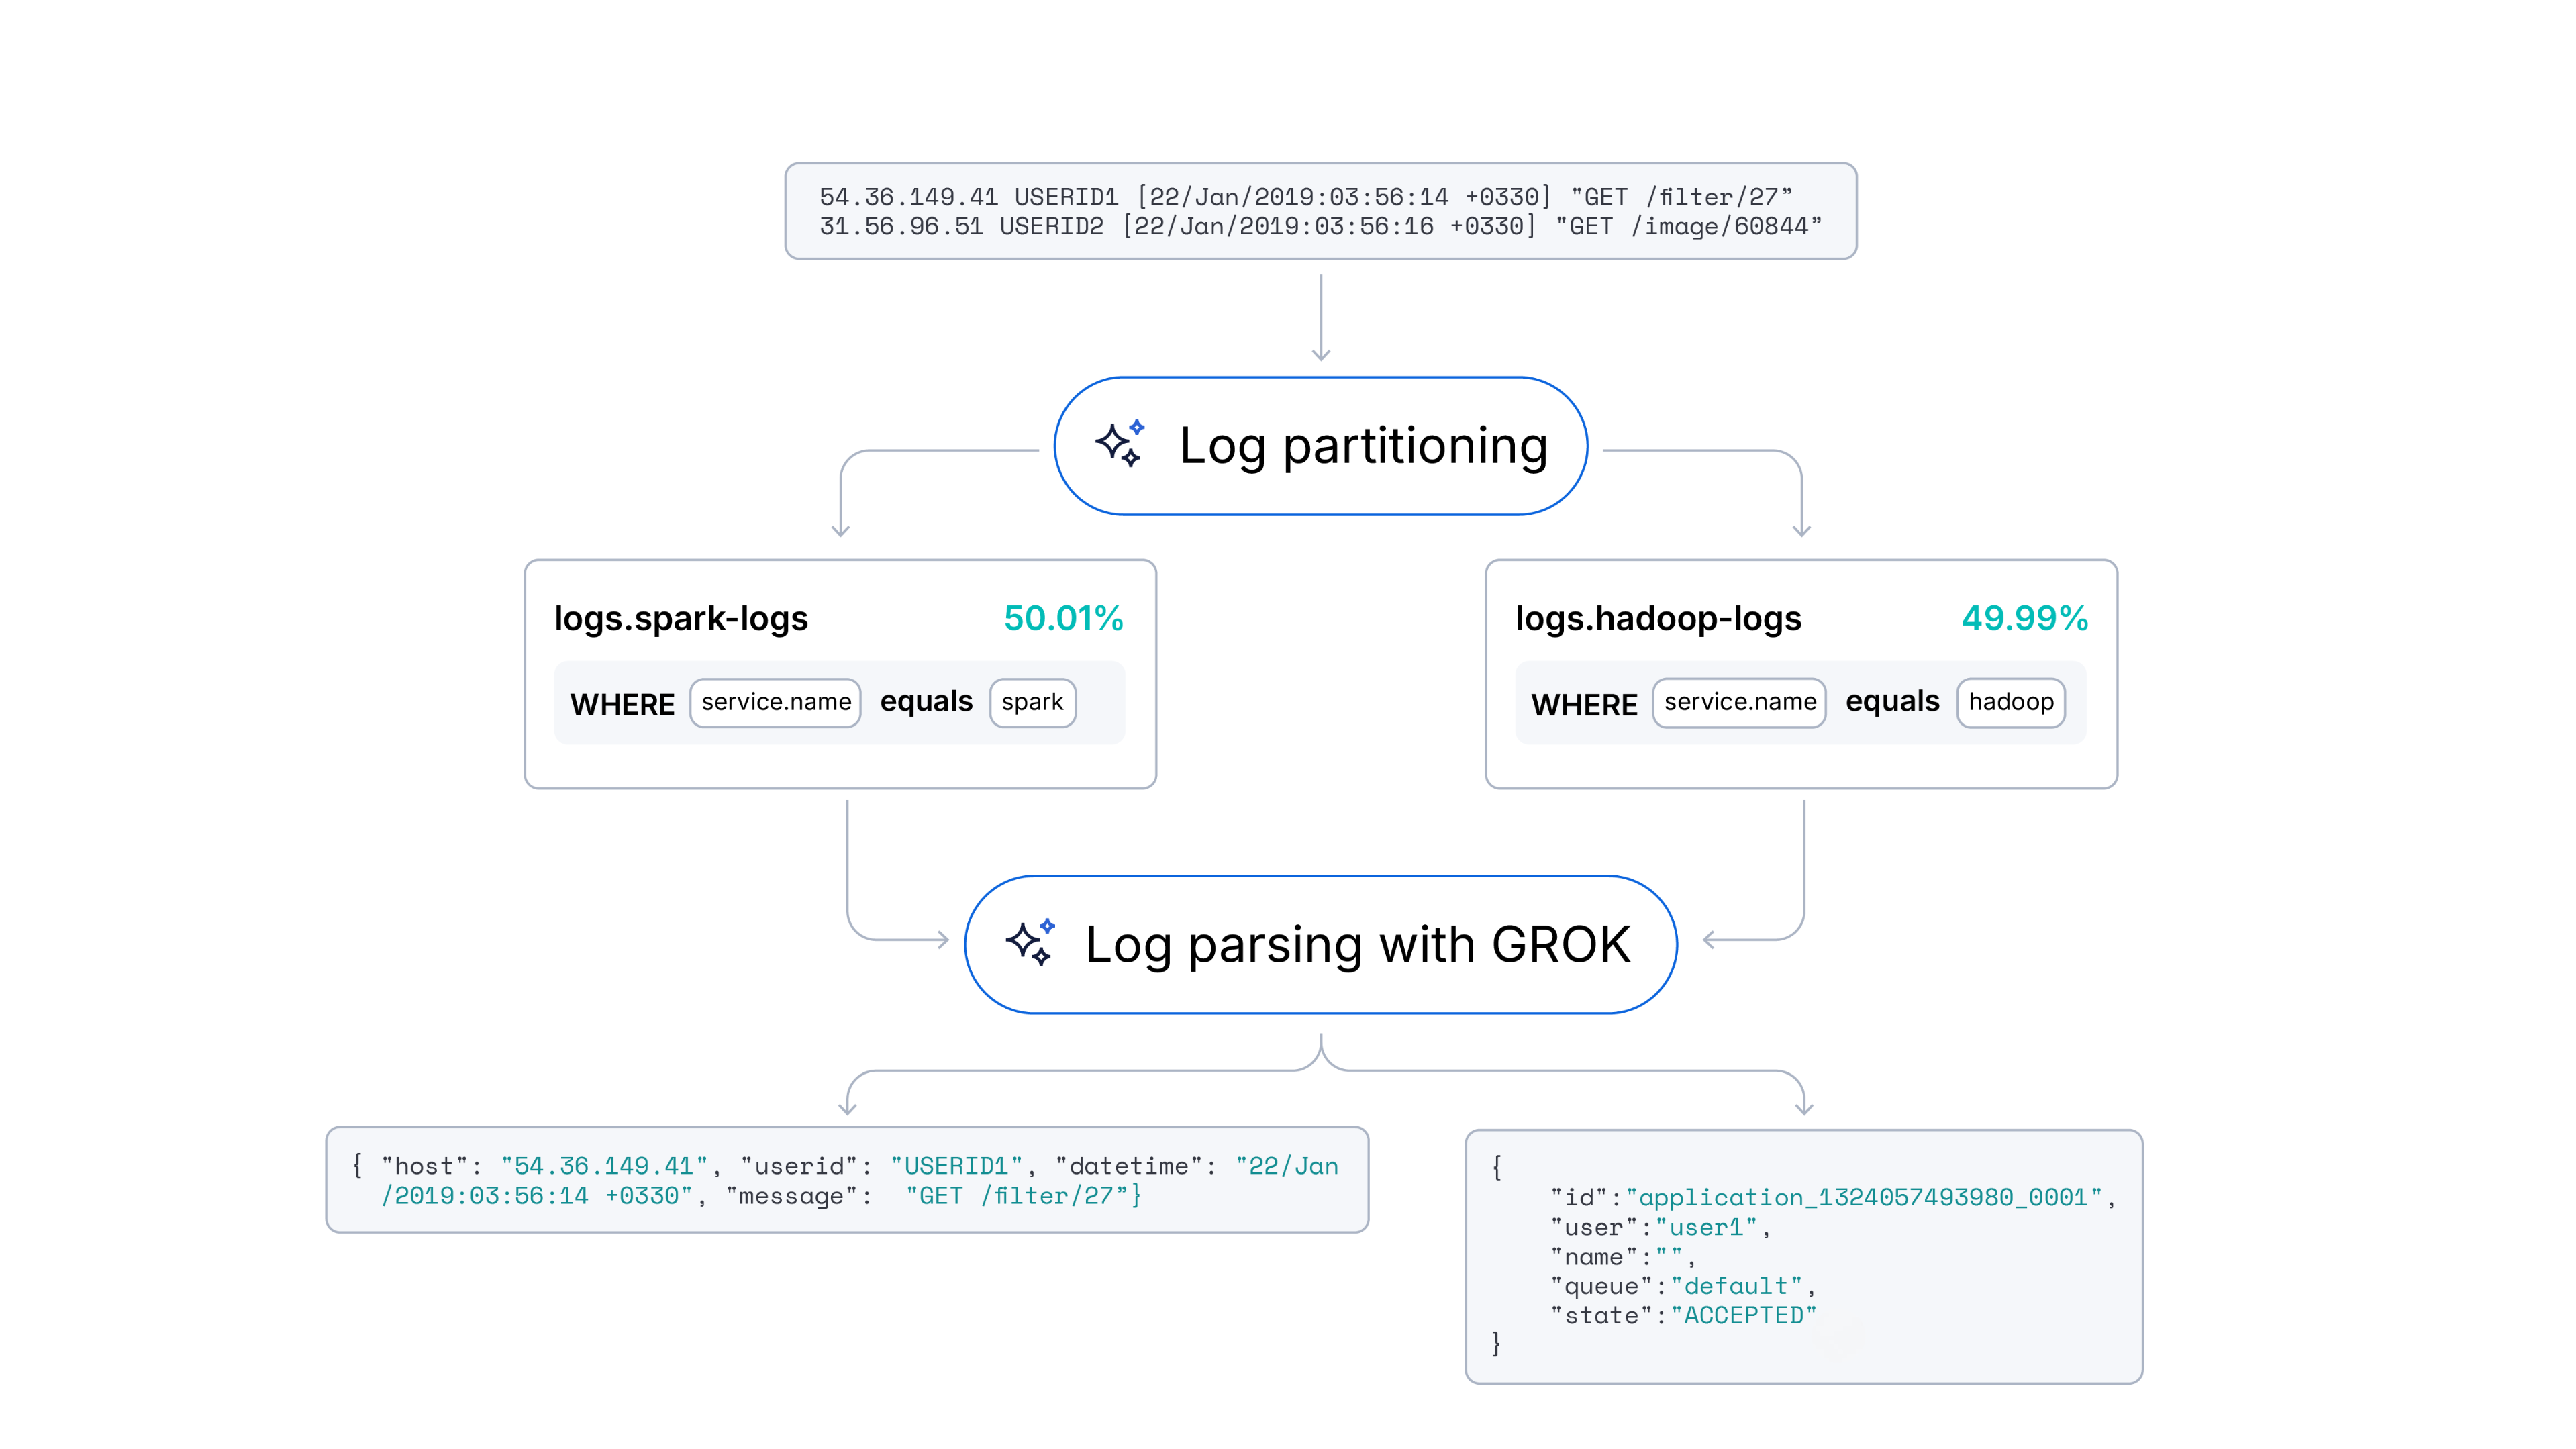
Automating log parsing in Streams with ML
Learn how a hybrid ML approach achieved 94% log parsing and 91% log partitioning accuracy through automation experiments with log format fingerprinting in Streams.

Generating filters and facets using ML
Exploring the pros and cons of automating the creation of filters and facets in a search experience using ML models vs the classical hard-coded approach.

Implementing clustering workflows in Elastic to enhance search relevance
We demonstrate how to integrate custom clustering models into the Elastic Stack by leveraging OpenAI text-ada-002 vectors, streamlining the workflow within Elastic’s ecosystem.