The fastest work is the work you never do: 100x faster sorted queries in Elasticsearch
How Elasticsearch 9.6 lets ES|QL push its current TopN threshold into Lucene, and how that 100x shows up on some sorted queries and barely registers on others.
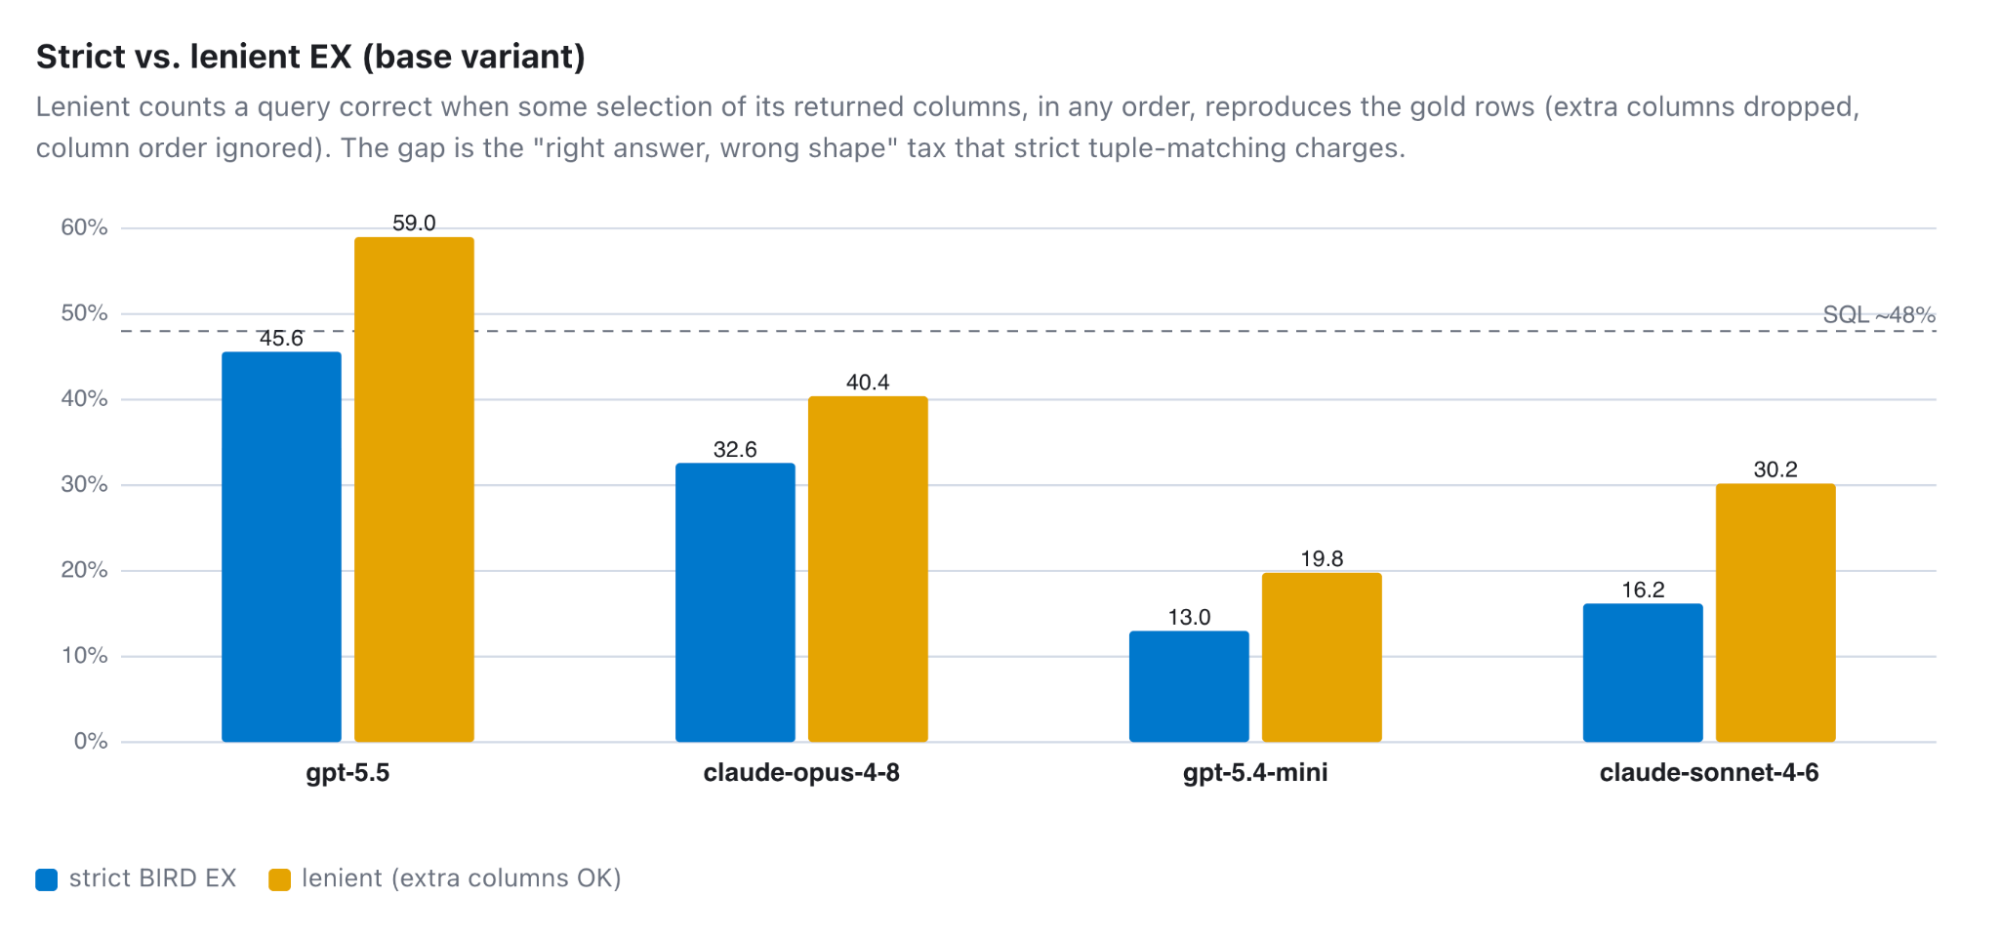
The best LLM writes correct Elasticsearch ES|QL 59% of the time. Here's what breaks the other 41%.
We scored 6,000 ES|QL queries from four models against BIRD's answer key. Most misses come from mismatched join keys, SQL syntax the parser rejects, counting after a one-to-many join, or a value the model guessed.
Ask Elastic Agent Builder why it's slow: Natural-language trace analysis
Four agent performance questions your Agent Builder traces can answer, covering token spend by model, tool error rates, slow conversation turns, and recent prompts. The ES|QL for each is here, including the type cast SUM() needs.
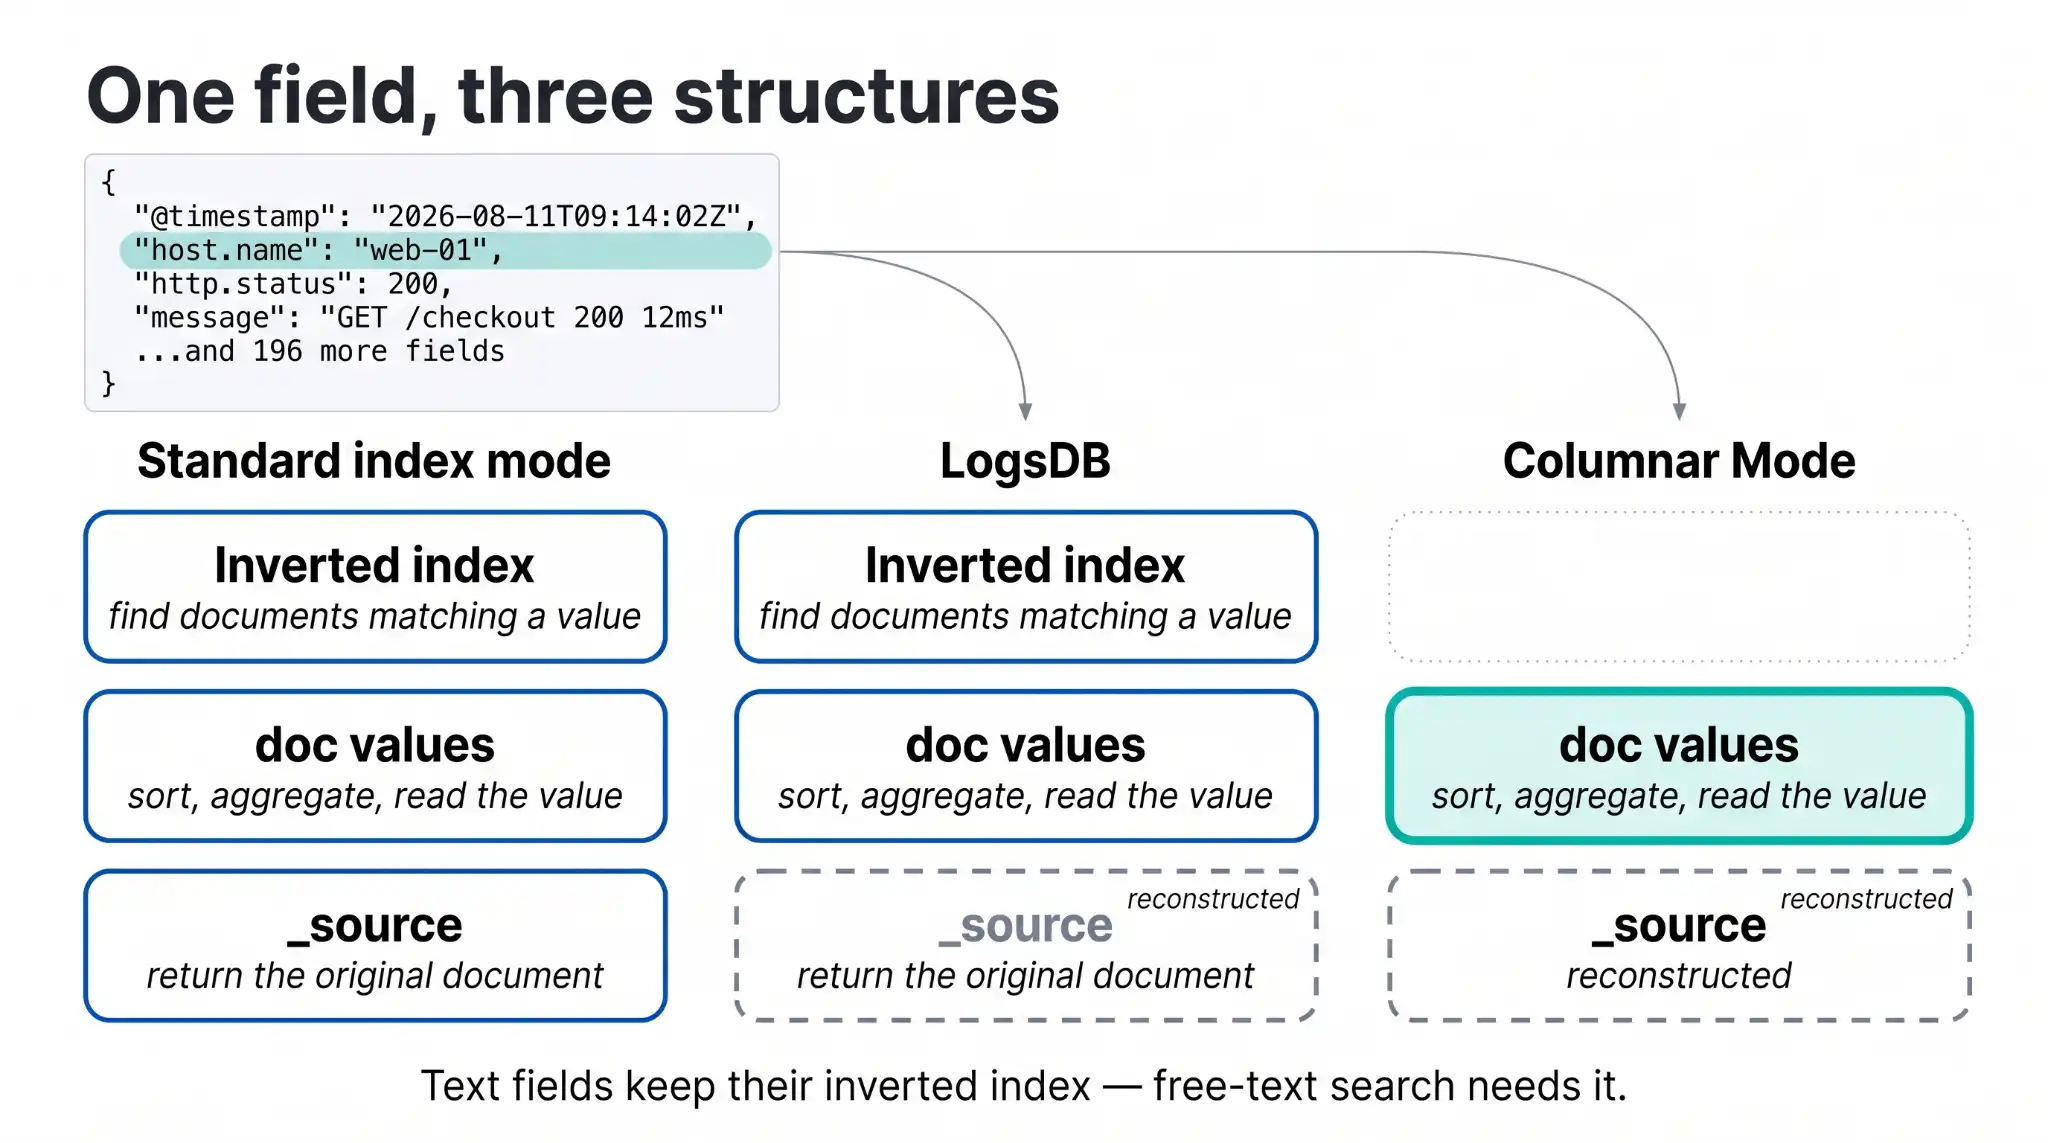
Columnar storage isn't a columnar database. What Columnar mode brings to Elasticsearch
Elasticsearch has stored data in columns since 2013, but adding full columnar database capabilities required a new mode.

How we built PromQL into Elasticsearch
PromQL runs on the same Elasticsearch compute engine as ES|QL, with no plugin and no separate process to operate. Getting there meant changing how the engine evaluates time windows and builds grouping keys.
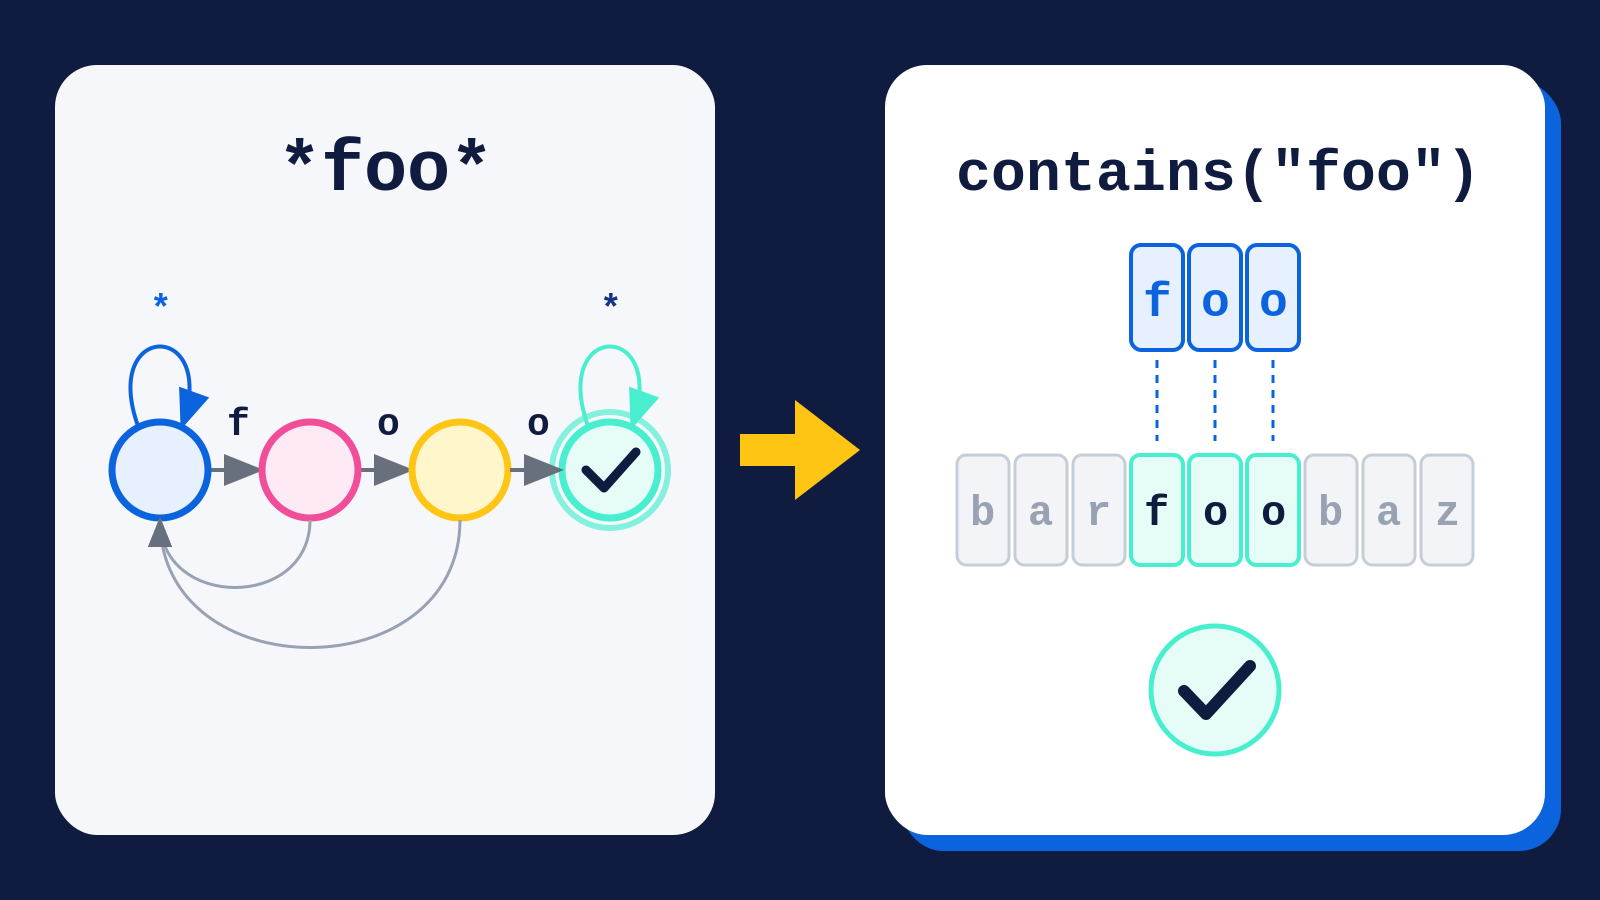
Query rewrite rules in Elasticsearch: 2.3x faster wildcard scans
A second rule makes empty-string filters 1.6x faster. It reads string lengths straight from the offset array and never touches the compressed bytes. Both rules came from the same habit of running real queries and hunting for the special case.
Introducing SPARKLINE in ES|QL: Spot trends at a glance
Spot trends across thousands of groups at a glance without leaving your workflow. ES|QL's new SPARKLINE function turns aggregations into trend lines. One array per row, zero effort.
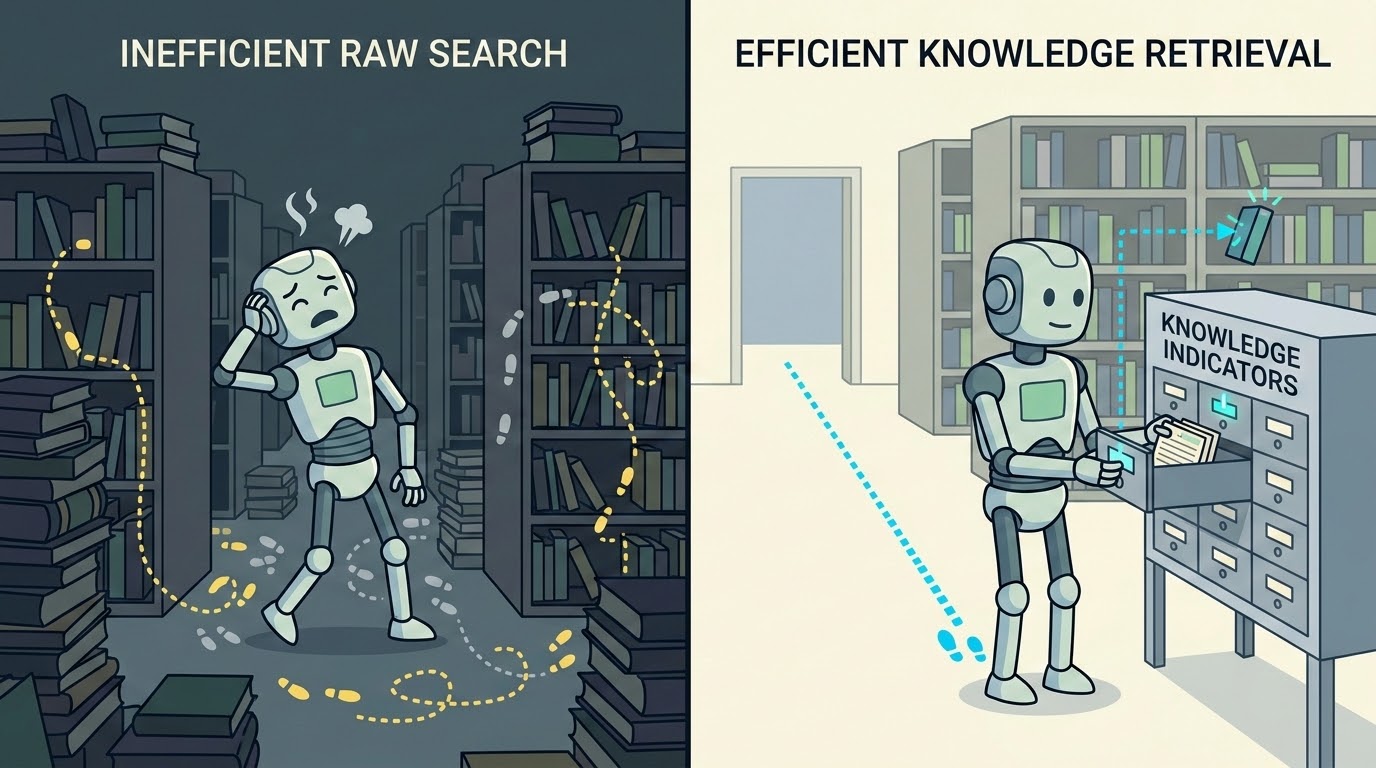
Know your facts: How Elasticsearch AI Indices let agents skip the reading and keep the answer
A technical walkthrough of precomputing facts into an Elasticsearch AI Index, so agents answer from a single ES|QL query instead of reading whole documents, with fewer tokens and lower latency.
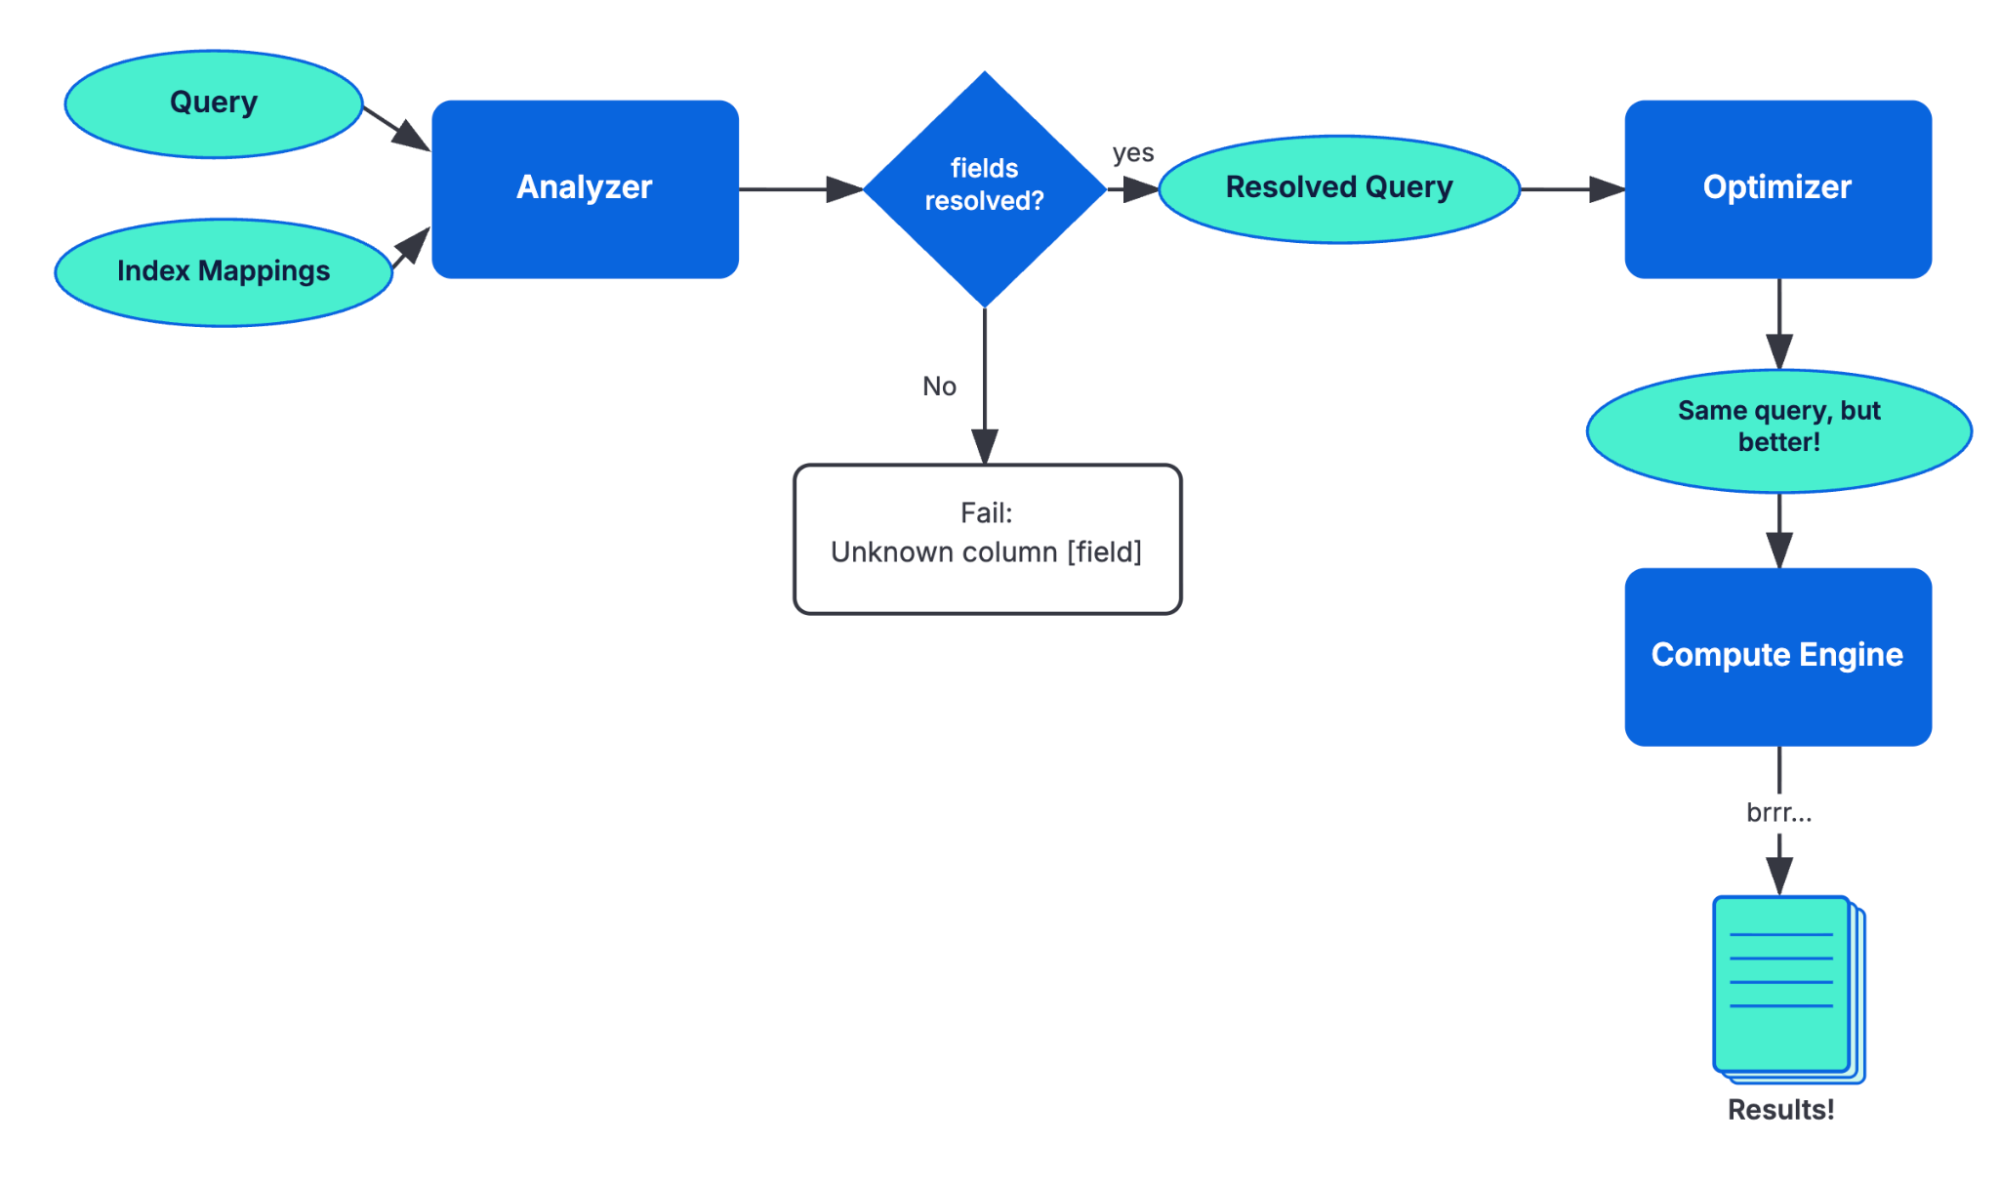
Taming PUNKs: How ES|QL queries Elasticsearch fields it was never told about
In Elasticsearch 9.5, ES|QL can query unmapped fields. It reads them from _source or returns nulls, so a query keeps working when a field drops out of the mapping and you avoid a reindex that takes hours.
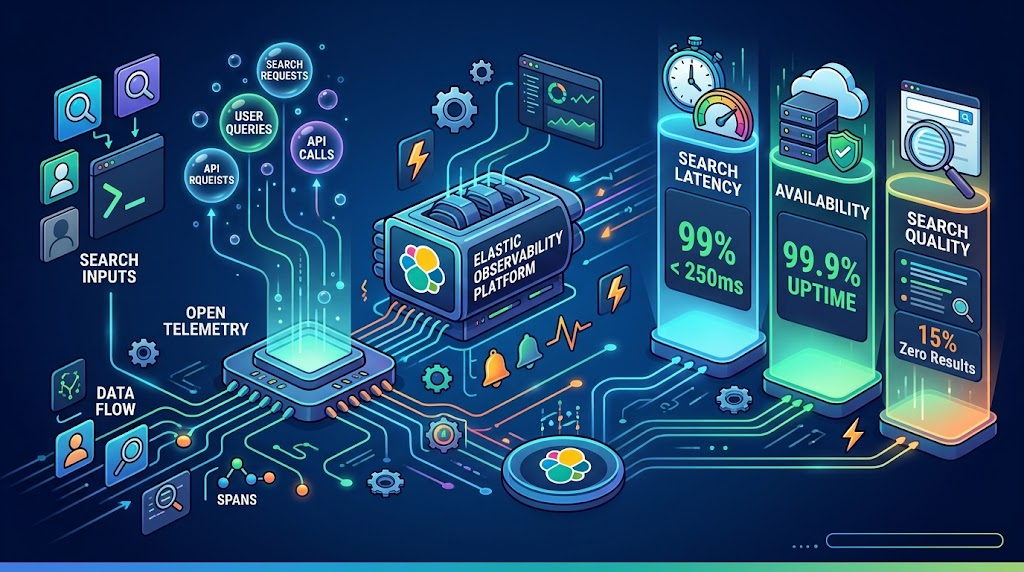
Three SLOs every search team needs: monitoring search latency, availability and quality with OpenTelemetry
Your OpenTelemetry search spans already carry the signals for SLOs, burn rate alerts, anomaly detection and incident response, and this post shows how to build all four in Elastic Observability.
Skip the mapping explosion: ES|QL queries schemaless JSON keys without dynamic mapping
Flattened fields turn Elasticsearch into a schema-on-read store where you index schemaless data under one mapping, then use ES|QL's FIELD_EXTRACT to pull out any JSON key you need to filter, group or join on, with predicates pushed into the columnar store.
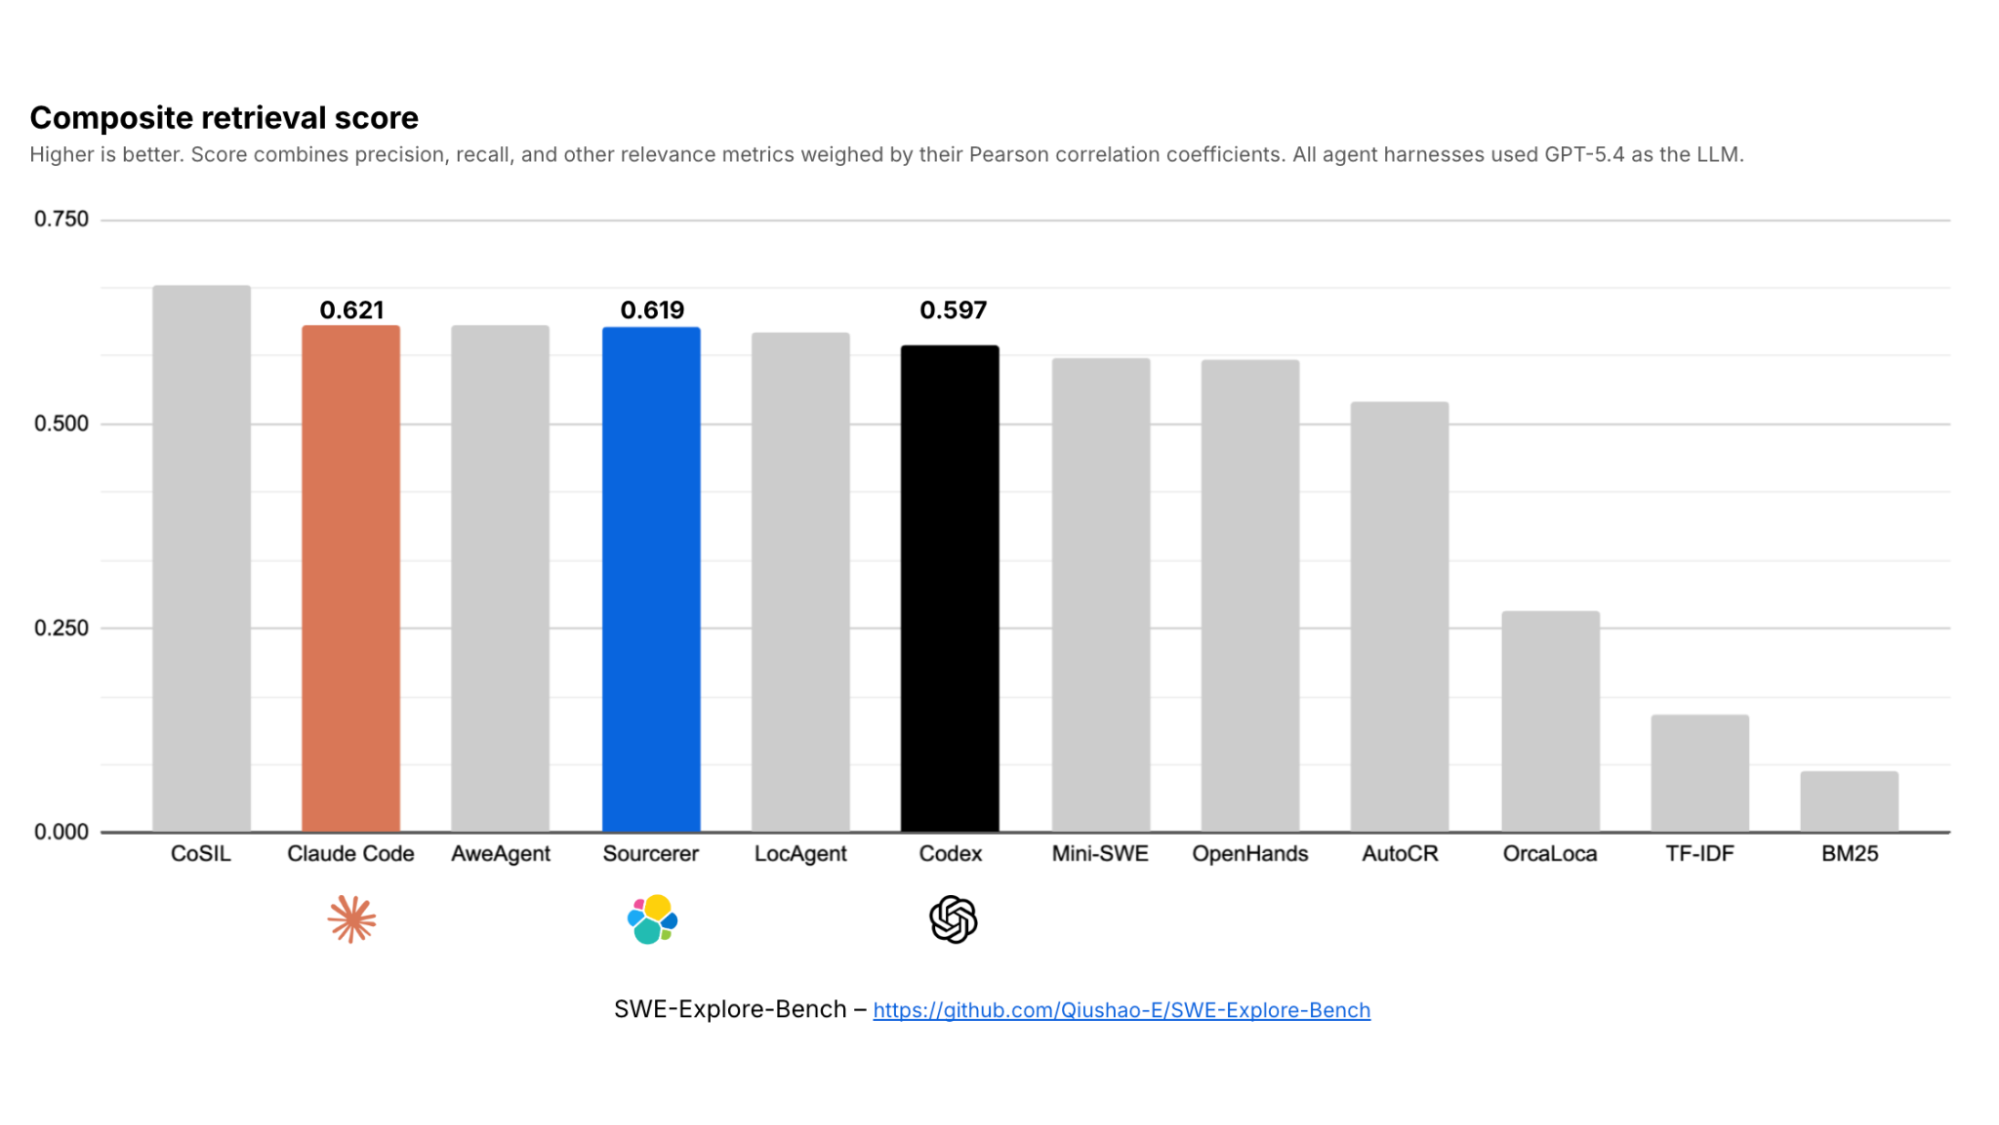
Ask the source: Scaling code search to a billion lines with Elasticsearch and Elastic Agent Builder
Sourcerer matches Claude Code and Codex on code retrieval quality and searches up to thousands of times faster than grep. Every answer links back to the exact files and lines across repos and versions.