The fastest work is the work you never do: 100x faster sorted queries in Elasticsearch
How Elasticsearch 9.6 lets ES|QL push its current TopN threshold into Lucene, and how that 100x shows up on some sorted queries and barely registers on others.
Check 100 candidates, not 10 million documents: Faster kNN filters in Elasticsearch
Elasticsearch now decides for each query whether to run a kNN filter before or after the vector search. On a 10M-vector corpus post-filtering was faster in 104 of 120 benchmark pairs while still returning k results.
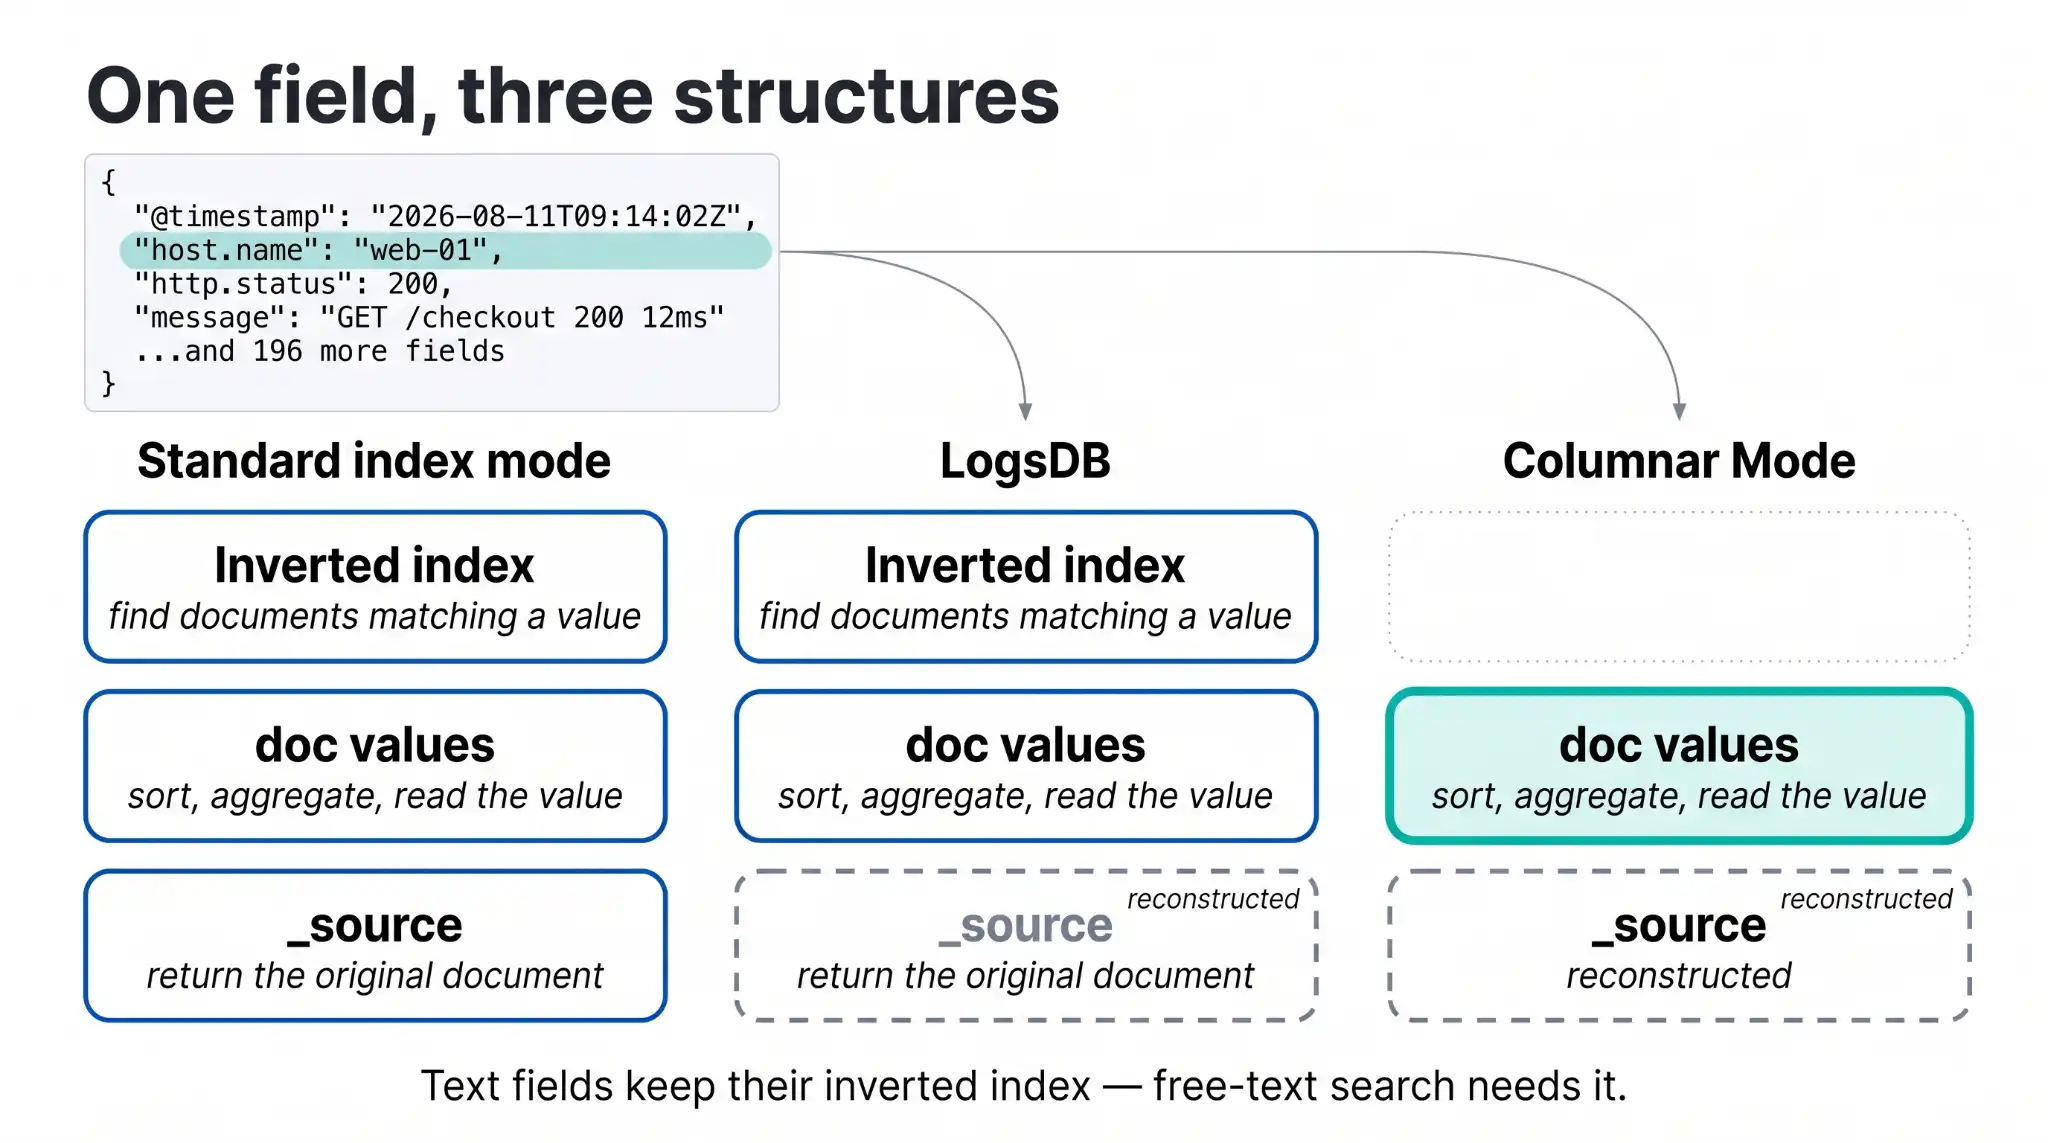
Columnar storage isn't a columnar database. What Columnar mode brings to Elasticsearch
Elasticsearch has stored data in columns since 2013, but adding full columnar database capabilities required a new mode.
One field, one copy: How Elasticsearch columnar storage drops the inverted index
Storing each field once means no inverted index, so doc values now read in bulk and skippers let queries skip whole ranges of documents, while new mapping attributes control what each field is allowed to contain.
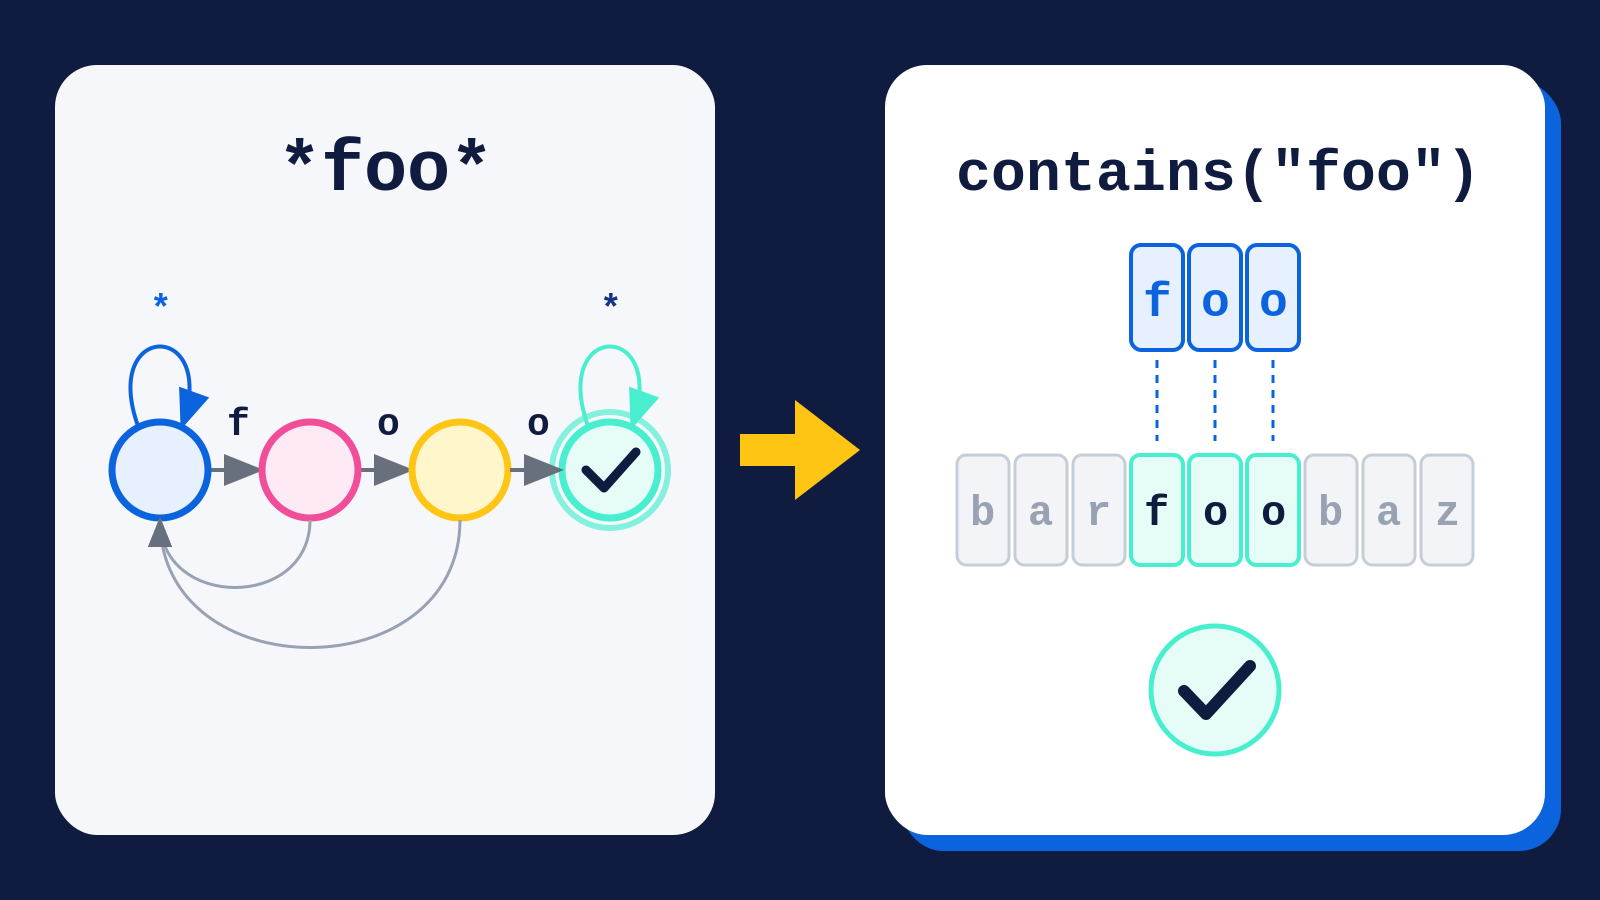
Query rewrite rules in Elasticsearch: 2.3x faster wildcard scans
A second rule makes empty-string filters 1.6x faster. It reads string lengths straight from the offset array and never touches the compressed bytes. Both rules came from the same habit of running real queries and hunting for the special case.
Skip the mapping explosion: ES|QL queries schemaless JSON keys without dynamic mapping
Flattened fields turn Elasticsearch into a schema-on-read store where you index schemaless data under one mapping, then use ES|QL's FIELD_EXTRACT to pull out any JSON key you need to filter, group or join on, with predicates pushed into the columnar store.
Bringing it together: How we rebuilt Elasticsearch as a columnar metrics engine; 6.6x less storage, 160x faster queries
Elasticsearch metrics in version 9.4 run on a fully columnar engine: 6.6x less storage, 160x faster queries, native PromQL and OTel support.
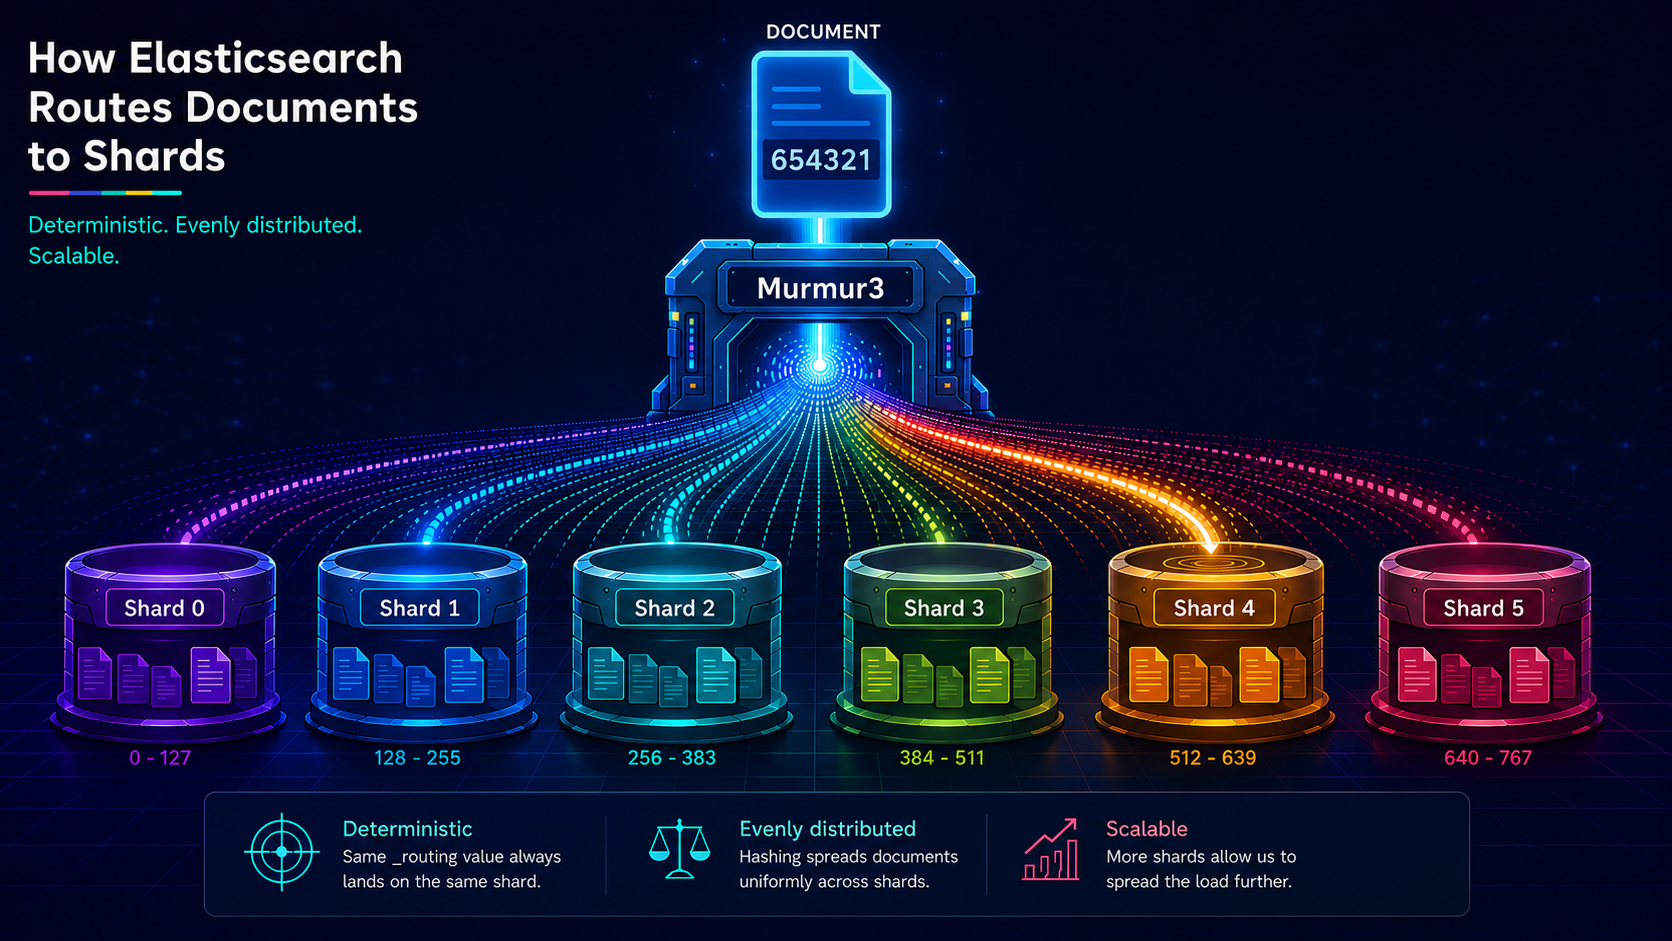
The hash() Elasticsearch won't name and the 12 bytes that prove it's Murmur3
Elasticsearch's routing formula uses MurmurHash3, but the docs never say so. This post names the function, walks through the full shard calculation, and shows you how to reproduce it externally.
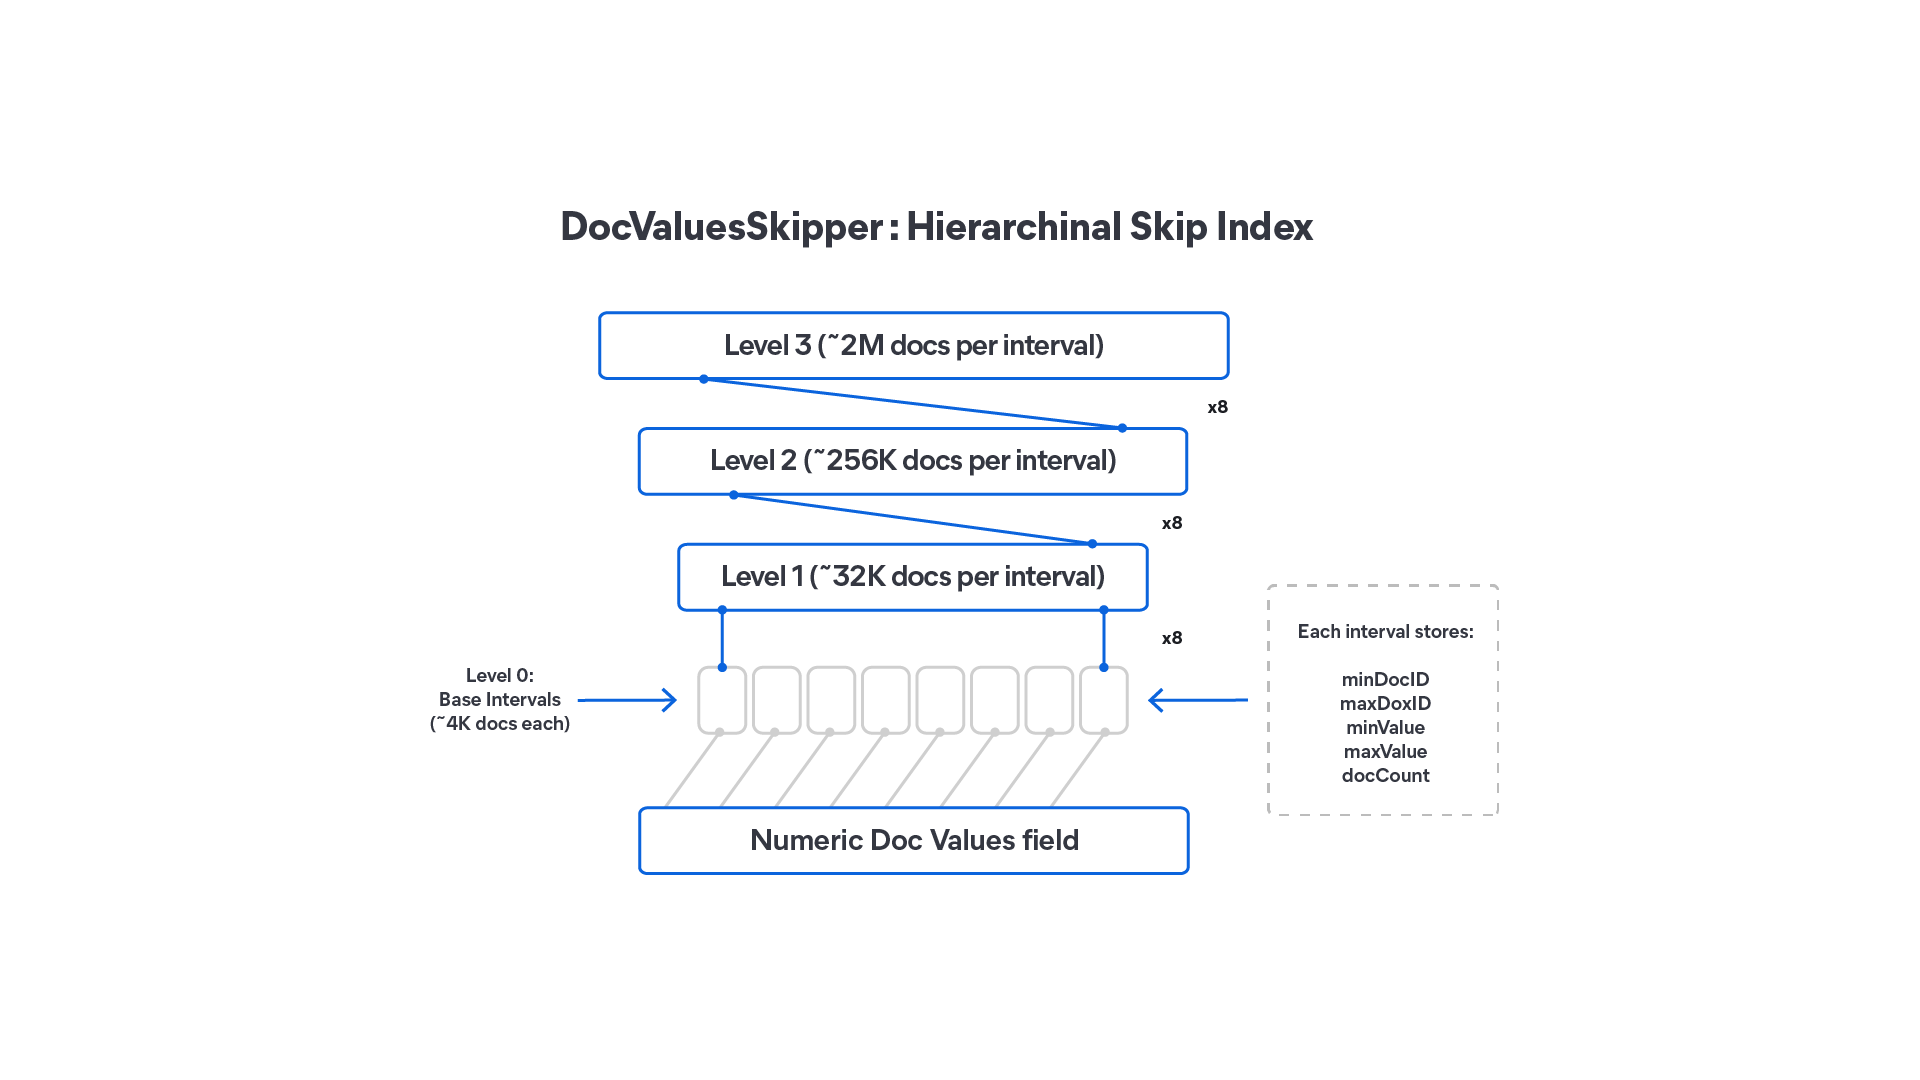
How DocValuesSkippers in Lucene 10 make range queries faster without doubling your storage
DocValuesSkippers add block-level skipping to Lucene DocValues fields, speeding up range queries on sorted or insert-ordered indexes with less than 0.1% storage overhead.
Apache Lucene 2025 wrap-up
2025 was a stellar year for Apache Lucene; here are our highlights.
Vector search filtering: Keep it relevant
Performing vector search to find the most similar results to a query is not enough. Filtering is often needed to narrow down search results. This article explains how filtering works for vector search in Elasticsearch and Apache Lucene.
Speeding up merging of HNSW graphs
Explore the work we’ve been doing to reduce the overhead of building multiple HNSW graphs, particularly reducing the cost of merging graphs.