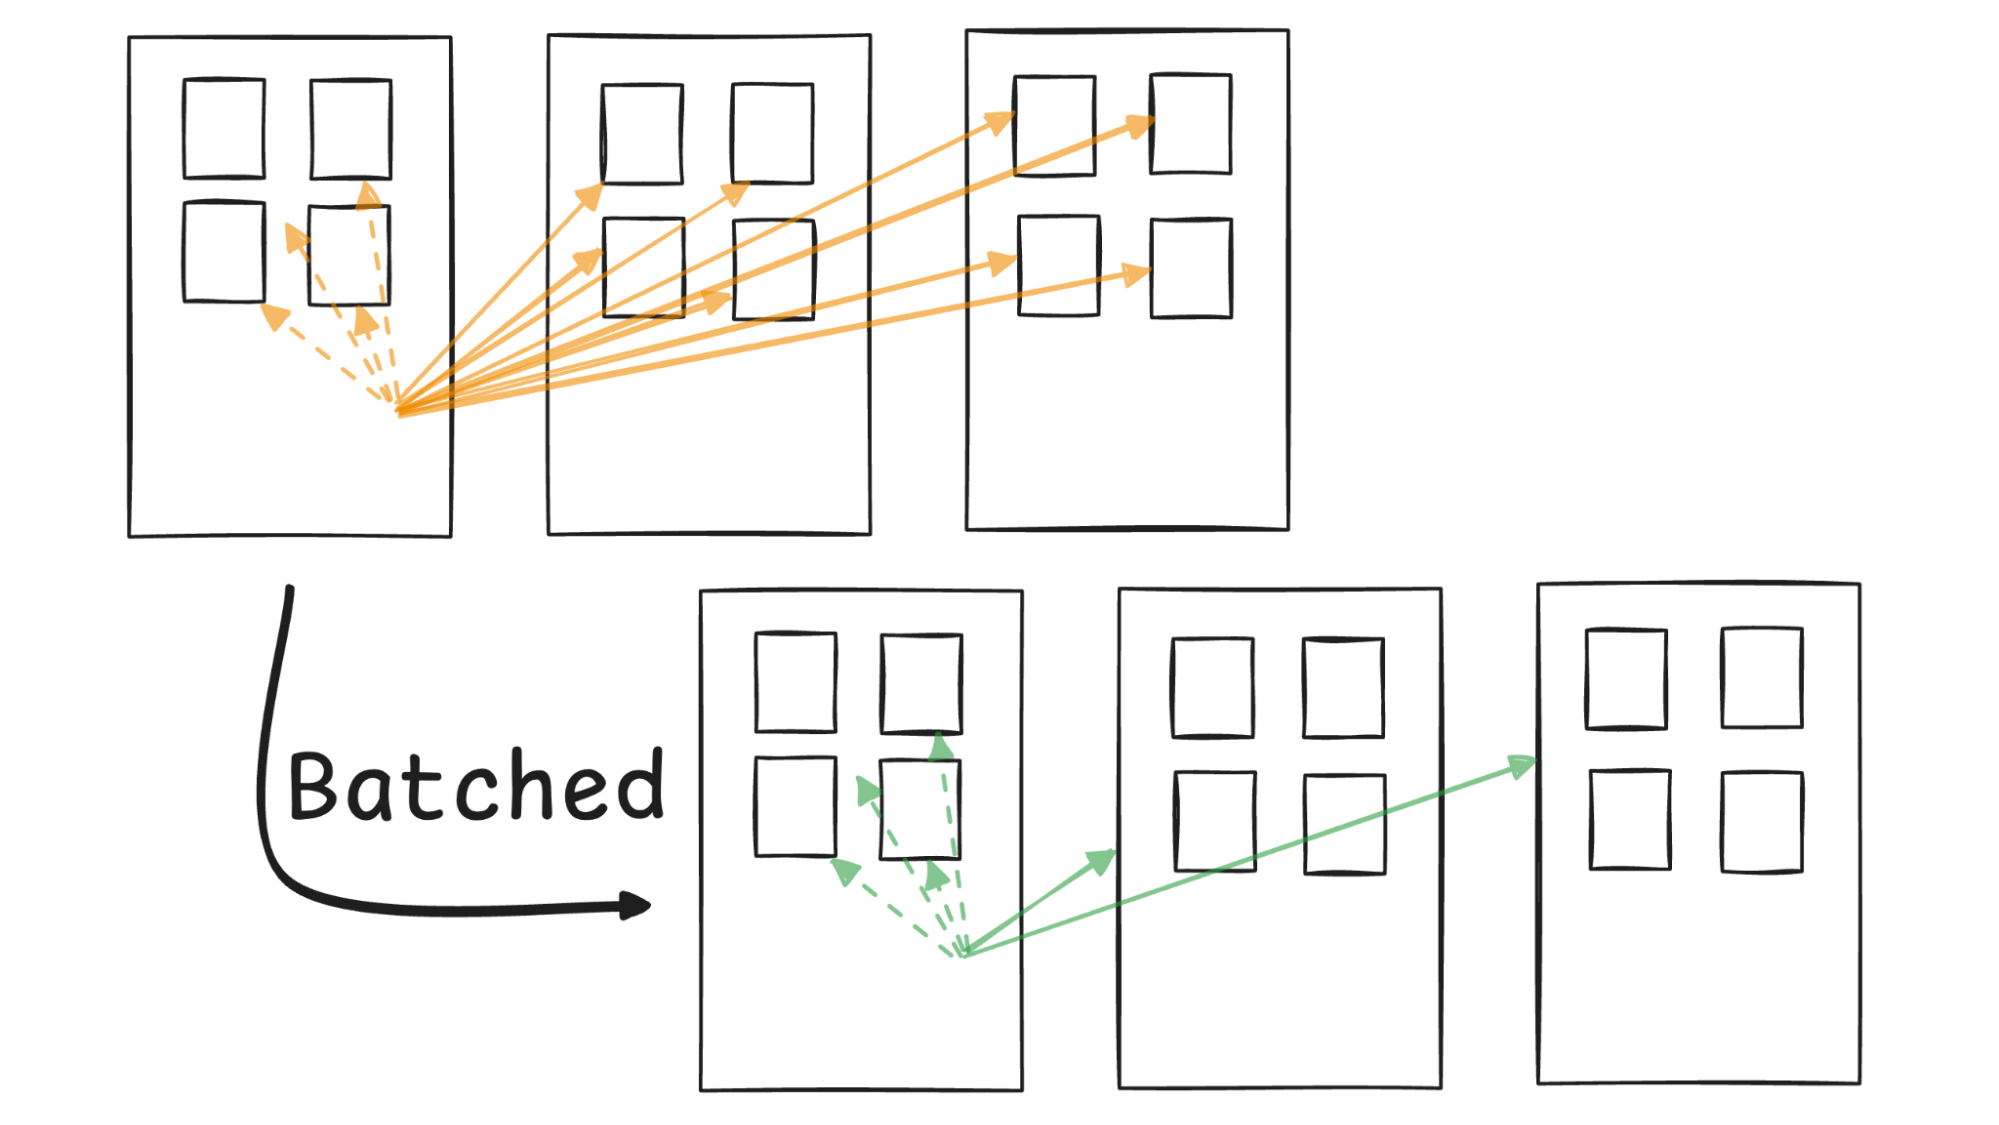
Check 100 candidates, not 10 million documents: Faster kNN filters in Elasticsearch
Elasticsearch now decides for each query whether to run a kNN filter before or after the vector search. On a 10M-vector corpus post-filtering was faster in 104 of 120 benchmark pairs while still returning k results.
Try out vector search for yourself using this self-paced hands-on learning for Search AI. You can start a free cloud trial or try Elastic on your local machine now.
Elasticsearch now decides, for each query, whether to apply a kNN filter before or after the vector search. Checking a broad match_phrase filter after the search took under a millisecond on a 1M-vector segment, compared with 33.4 ms before it. On a 10M-vector corpus, post-filtering was faster in 104 of 120 benchmark pairs, with recall within 0.01 of pre-filtering.
A filter inside the knn clause, such as a tenant ID or a language, runs as a pre-filter, so it's evaluated over every document in every segment before the search starts. When a filter matches enough of the corpus, Elasticsearch runs the vector search first and checks the filter only against the candidates that come back. The candidate pool is sized statistically so that at least k survive. If they fall short, Elasticsearch retries once and then falls back to the pre-filtered search. Your queries stay the same, and you still get k results. It's scheduled to be on by default in Elasticsearch 9.6.
How a kNN filter works in Elasticsearch
As a quick reminder, Elasticsearch has two approximate nearest-neighbor structures for dense_vector fields. HNSW is a proximity graph: the search walks from neighbor to neighbor, keeping the num_candidates closest vectors it has seen so far as its beam. IVF, the bbq_disk index type, clusters vectors around centroids, each with a posting list of its vectors, and scans the posting lists closest to the query; the fraction of the segment it scans, its visit ratio, is derived from num_candidates and k. The posts on HNSW graphs and DiskBBQ cover both in depth.
What sets up everything that follows is that neither is a single index-wide structure. Every Lucene segment carries its own HNSW graph or its own set of IVF posting lists, so a kNN query searches each segment separately and merges the results, first per shard and then on the coordinating node. Anything the search has to prepare before it starts exploring is therefore prepared once for every segment.
Now let's add a filter to the kNN query:
POST my-index/_search
{
  "knn": {
    "field": "embedding",
    "query_vector": [0.12, -0.03, ...],
    "k": 10,
    "num_candidates": 100,
    "filter": {
      "term": { "language": "en" }
    }
  }
}
Because the filter sits inside the knn clause, it is a pre-filter: the 10 results are the 10 nearest documents among those matching language: en. To deliver that, the search has to know, for every document it comes across, whether that document passes the filter. In each segment, this happens in two steps.
Step 1: Materializing the filter into a bitset
Neither structure visits documents in doc ID order. An HNSW walk jumps from a node to its graph neighbors, while IVF scans posting lists one centroid at a time, meaning document IDs arrive in whatever order vector proximity dictates. The search needs to answer "does doc 84,219 match?" on demand, and a filter's regular DocIdSetIterator (which can only move forward) cannot do that. Before the search starts, the filter is run to completion over the segment, and its matches are recorded in a bitset. For HNSW, this happens in Lucene's AcceptDocs:
// org.apache.lucene.search.AcceptDocs
private void createBitSetAcceptDocsIfNecessary() throws IOException {
  if (acceptBitSet == null) {
    acceptBitSet = Objects.requireNonNull(createBitSet(iterator(), liveDocs, maxDoc));
    cardinality = acceptBitSet.cardinality();
  }
}
createBitSet drains the filter's iterator to the end and fills either a FixedBitSet sized to the segment's maxDoc or a sparse bitset, depending on how many documents match. IVF does the equivalent through Elasticsearch's own ESAcceptDocs before it scans its first posting list. Either way, the cost depends on the size of the segment and how expensive the filter is to evaluate, not on how much of the segment the search goes on to visit.
Step 2: Skipping documents that fail the filter
Documents that fail the filter do not count toward the results. The search has to visit more of the segment to collect enough that pass: HNSW walks further through the graph, and IVF scans a few extra posting lists. Both keep this bounded. HNSW, for instance, stops walking the graph once it has visited as many vectors as the filter matches, and scores the matching documents directly instead. For a filter that matches most of the corpus, the extra work is small, as the profile in the next section shows.
The takeaway: The extra search work caused by a filter is bounded, and it is rarely where a filtered query's time goes. The materialization in step 1 has no such bound. That is why the interesting case is not a restrictive filter but a broad one, matching, say, 90% of the corpus. It prunes almost nothing and adds little search work, yet it is still materialized at full price in every segment.
Why a filtered kNN search can be slower than an unfiltered one
The search profile shows this cost directly, though not where you might first look for it.
Lucene's kNN queries do almost all of their work in rewrite. For HNSW, AbstractKnnVectorQuery#rewrite materializes the filter, searches every segment, merges the per-segment results, and returns a DocAndScoreQuery holding the final doc IDs and scores. IVF does the same and returns Elasticsearch's KnnScoreDocQuery. By the time the query is executed in the usual sense, the search is over, and all that is left is to hand back a precomputed list of hits.
A top-level knn clause runs in the DFS phase, so its profile lands under profile.shards[].dfs.knn[]. Here is an unfiltered search with k: 10 and num_candidates: 100 against a single HNSW segment of one million vectors, with each breakdown trimmed to its non-zero entries:
{
  "dfs": {
    "knn": [
      {
        "vector_operations_count": 2378,
        "query": [
          {
            "type": "DocAndScoreQuery",
            "description": "DocAndScoreQuery[177025,...][0.7580181,...],0.7580181",
            "time_in_nanos": 5708,
            "breakdown": {
              "create_weight": 1250,
              "build_scorer": 2583,
              "next_doc": 1041,
              "score": 834,
              ...
            }
          }
        ],
        "rewrite_time": 5158917,
        "collector": [...]
      }
    ]
  }
}rewrite_time, 5.2 ms, is the kNN search. The DocAndScoreQuery entry takes under 6 microseconds: it only returns the ten hits.
Now add a match_phrase filter that matches 90% of the documents. A phrase that matches nearly the whole corpus is not a common filter in practice, but it isolates the effect cleanly: it barely narrows the search, and it is expensive to evaluate. Most real filters that match this broadly cost somewhere between this one and the term filter we compare it to further down.
{
  "dfs": {
    "knn": [
      {
        "vector_operations_count": 2682,
        "query": [
          {
            "type": "CachingEnableFilterQuery",
            "description": "(ConstantScore(body:\"red fox\"))^0.0",
            "time_in_nanos": 33595666,
            "breakdown": {
              "create_weight": 9125,
              "build_scorer": 174083,
              "next_doc": 15708,
              "into_bit_set": 33396750,
              "into_bit_set_count": 1,
              ...
            },
            "children": [
              {
                "type": "PhraseQuery",
                "description": "body:\"red fox\"",
                "time_in_nanos": 33589916,
                "breakdown": {...}
              }
            ]
          },
          {
            "type": "DocAndScoreQuery",
            "description": "DocAndScoreQuery[163399,...][0.7200494,...],0.7580181",
            "time_in_nanos": 4092,
            "breakdown": {...}
          }
        ],
        "rewrite_time": 40076834,
        "collector": [...]
      }
    ]
  }
}
Three things changed:
- The filter has its own entry, next to the
DocAndScoreQueryrather than inside it, because it runs during the kNN query's rewrite.CachingEnableFilterQueryis the wrapper Elasticsearch puts around kNN filters so that the query cache always considers them worth caching; the query you wrote is its child. On abbq_diskfield, the entries are named differently, but the filter shows up the same way. into_bit_setis the materialization from step 1: a single call that runs the phrase query over the whole segment and records every match in the bitset. It took 33.4 ms. That time is part ofrewrite_time, not added to it;rewrite_timewent from 5.2 ms to 40.1 ms, and the filter accounts for 33.6 ms of the difference. (A filter matching fewer than about 1 in 128 documents is collected into a sparse bitset one document at a time instead, so its cost shows up undernext_doc.)vector_operations_countbarely moved. It went up 13%, roughly what you would expect when one visited document in ten fails the filter.
More than 80% of this query's time went into evaluating the filter. One thing to keep in mind when reading profiles like this: profiling bypasses the query cache and the profile always shows the filter's uncached cost, even for a filter that unprofiled requests would find in the cache.
kNN filter cost: Materialization vs. extra search work
Two costs make up the difference between these two profiles, and it is worth separating them because they scale differently.
Filter materialization is paid per segment, proportional to the segment size, before any vector work. How expensive it is depends entirely on the query type:
Filter | Materialization cost |
|---|---|
| Cheap - read one postings list, |
| Usually cheap - walks the points (BKD) index; only a field with doc values alone ( |
| Positions decoding and intersection for every document containing the terms; by far the most expensive |
| Cost of each clause, plus conjunction/disjunction bookkeeping |
Cached filter | Nearly free on a cache hit, full price on a miss |
On the one-million-document segment above, a term filter matching the same 90% of documents spends about 0.3 ms in into_bit_set, roughly 100x less than the phrase filter. And the cost grows with the segment: in the benchmarks below, a match_phrase filter matching 90% of a 10M-document segment takes an HNSW query from 2.3 ms to 395 ms.
Extra search work adds something on top, but as we saw, it is bounded, and for a broad filter it is small: the 13% above. Materialization dominates, and a filtered kNN search on a broad, expensive filter can spend most of its time on work that is not vector comparison. The answer it arrives at also overlaps heavily with the unfiltered one: if a filter matches 90% of the corpus and is unrelated to the query, about nine of the ten nearest neighbors overall already pass it, and the ones that do not are replaced by documents only a few ranks further down.
That is the asymmetry the rest of this post is about. The filter's cost is tied to how many documents it is evaluated over, and evaluating it after the vector search instead of before changes that number by orders of magnitude:
Pre-filtering evaluates the filter over every document in the segment before the vector search; post-filtering evaluates it only over the candidates the vector search returns.
Pre-filtering vs post-filtering in kNN search
What if we just post-filter? That observation is not new, and Elasticsearch has always let you act on it. Move the filter outside the knn clause and it becomes a post-filter: the kNN search runs unconstrained, and the filter is applied to the k results it returns.
POST my-index/_search
{
  "query": {
    "bool": {
      "filter": { "term": { "language": "en" } },
      "must": {
        "knn": {
          "field": "embedding",
          "query_vector": [0.12, -0.03, ...],
          "k": 10,
          "num_candidates": 100
        }
      }
    }
  }
}
We covered this trade-off in detail in How to choose between exact and approximate kNN search in Elasticsearch, where the catch is put plainly:
The problem with using post-filters in kNN is that the filter is being applied after we have gathered the top k results. This means that we can end up with less than k results, as we need to remove the elements that don't pass the filter from the top k results that we've already retrieved from the HNSW graph.
Ask for 10, get back 6. Or 2. Or 0. The vector search does not know the filter exists, so nothing guarantees that 10 of its results survive it. The only remedy available to you is to over-collect by hand: ask for k: 50 and hope 10 survive. That puts you in an awkward position:
- You have to guess the multiplier, and the right guess depends on how selective your filter is for this particular query; something you generally do not know.
- Guess too low and you silently return short result sets. Guess too high and you pay for exploration you did not need, which is the cost you were trying to avoid.
- Either way,
kno longer means what the API says it means, so paging,size, and anything downstream has to be reasoned about separately.
So both options are unsatisfying. Pre-filtering is correct but can be pathologically slow. Post-filtering is fast but shifts a statistics problem onto the user and still offers no guarantee.
The table below compares both options with the automatic post-filtering covered in the next section.
Pre-filtering | Manual post-filtering | Automatic post-filtering | |
|---|---|---|---|
Where the filter goes | Inside the | Outside the | Inside the |
Filter is evaluated over | Every document in every segment | The | The candidates the vector search returns |
Returns k results | Yes | Not guaranteed | Yes, by falling back to pre-filtering if needed |
Who sizes the candidate pool | Not needed | You, by guessing a multiplier for | Elasticsearch, from the filter's estimated selectivity |
Best suited to | Selective filters | Cases where a short result set is acceptable | Broad filters (selectivity of 0.7 or more by default) |
But we can do better
The insight is that the choice between these two does not have to be the user's, and it does not have to be made once for the whole index. Elasticsearch is holding the filter's Weight at rewrite time. It can estimate how selective the filter is, decide whether post-filtering is a good bet for this query on this shard, size the over-collection from that estimate rather than from a guess, and keep a correctness net underneath so that a bad estimate costs latency instead of results.
This is what automatic post-filtering adds, for both HNSW and IVF (bbq_disk). Importantly, none of it changes the query you write: you keep expressing a pre-filter, you keep getting pre-filter semantics, and how that gets satisfied becomes an engine decision.
Four ideas, in order:
- Estimate the filter's selectivity.
- Use it to size an over-collection.
- Retry once if that comes up short.
- Fall back to the original query if it still does.
Estimating kNN filter selectivity
First, we need a number for "how much of the corpus does this filter let through?" The cheap and surprisingly effective answer is to ask the filter's own scorers what they expect to match, and divide by the number of vectors actually indexed for the field:
public static float computeSelectivity(Weight filterWeight, List<LeafReaderContext> leaves, int totalVectors)
    throws IOException {
    long filterCost = 0;
    for (LeafReaderContext leafCtx : leaves) {
        ScorerSupplier ss = filterWeight.scorerSupplier(leafCtx);
        if (ss != null) {
            filterCost += ss.cost();
        }
    }
    return totalVectors > 0 ? Math.min(1f, (float) filterCost / totalVectors) : 0f;
}
Two things make this cheap. ScorerSupplier#cost() is an estimate. For a term query, it is the postings list length, read from metadata, so we get it without materializing anything. And the denominator is the vector count from the codec, not maxDoc, so a field that only some documents have does not skew the ratio.
Two things make it imperfect, and both are handled downstream rather than pretended away. cost() is an upper bound for conjunctions, and selectivity can be overestimated. More fundamentally, selectivity is a global property of the shard, while what actually matters is the filter's pass rate inside the neighborhood of the query vector. For a filter that is independent of vector content, the two match. For one that is correlated with it, they can drift apart in either direction.
Say language: en matches 90% of a shard. For an English query, nearly all of the nearest neighbors are English. The local pass rate is therefore close to 100% and the global estimate is merely conservative. For a query written in Spanish, the nearest neighbors can be dominated by the 10% of documents that are not English, and the local pass rate can fall far below 90% even though the global estimate has not changed. That second case is the one the retry and fallback rounds below exist for.
Sizing the candidate pool with a binomial model
Given selectivity , how many raw candidates should the unfiltered search collect to get at least survivors?
The naive answer is . That gets you survivors on average, which means it falls short roughly half the time. Averages are the wrong tool here: we need a high-probability guarantee.
So model each candidate as independently passing the filter with probability . The number of survivors out of candidates is then a binomial variable:
The assumption worth naming explicitly is independence. We assume it because, absent any signal about how the filter correlates with vector content, it is the only thing we can assume. The retry and fallback rounds below exist precisely to cover the cases where it is wrong.
How many extra candidates post-filtering collects
In code, that formula plus its guard rails:
/**
 * Minimum round-1 oversample factor. Round 1 always asks for at least this many ×
 * the target count, regardless of what the binomial variance formula computes. Active
 * when selectivity is near 1, where the variance term collapses to ≈ 0.
 */
float POST_FILTER_OVERSAMPLE_FLOOR = 1.2f;
float POST_FILTER_OVERSAMPLE_Z_SCORE = 2.5f;
static double zMargin(int k, float selectivity) {
    return POST_FILTER_OVERSAMPLE_Z_SCORE * Math.sqrt(k * (1.0f - selectivity) / selectivity);
}
static int computeScaledK(int k, float selectivity) {
    double zMargin = zMargin(k, selectivity);
    double floor = Math.min(Math.ceil(k * POST_FILTER_OVERSAMPLE_FLOOR), NUM_CANDS_LIMIT);
    return (int) Math.clamp(Math.ceil((k + zMargin) / selectivity), floor, NUM_CANDS_LIMIT);
}
The 1.2x floor matters because, as , the variance term vanishes and the formula would return exactly , leaving no slack for the handful of documents that do get filtered out. The NUM_CANDS_LIMIT cap (10,000) keeps a very restrictive filter from requesting an unbounded candidate pool.
For and , the resulting oversample:
Selectivity | margin | Candidates | Oversample |
|---|---|---|---|
0.99 | 0.79 | 12 (floor) | 1.2x |
0.95 | 1.81 | 13 | 1.3x |
0.90 | 2.64 | 15 | 1.5x |
0.80 | 3.95 | 18 | 1.8x |
0.70 | 5.18 | 22 | 2.2x |
0.55 | 7.15 | 32 | 3.2x |
Note how modest these are and how they shrink relative to k as k grows, because the standard deviation grows as while the mean grows as . At and the oversample is only 2.2x, versus 3.2x at . Asking for 15 results instead of 10 is nothing compared to materializing an expensive filter over a 10M-document segment.
There is a second budget that must not be conflated with k, and getting this wrong is an easy way to accidentally retune the search. For HNSW, num_candidates is the beam width, and it is an independent knob. The delegate keeps the user's value, floored at the grown k (a beam narrower than the number of results requested cannot surface them):
static int cappedNumCands(int numCands, int scaledK) {
    return Math.clamp(numCands, scaledK, NUM_CANDS_LIMIT);
}
A consequence worth spelling out: an HNSW delegate hands back more candidates than the grown k. Each segment's graph walk keeps its whole beam (up to num_candidates candidates), and every one of them is checked against the filter. On HNSW, the grown k mostly matters when num_candidates is close to k; with the usual wider beam, round one has plenty of candidates to draw from.
For IVF, num_candidates is only meaningful relative to k: the codec derives its visit ratio from the ratio of the two. Carrying num_candidates over unchanged while k grows would silently reduce exploration, and IVF scales it to preserve the ratio:
static int numCandsPreservingRatio(int numCands, int k, int newK) {
    if (k <= 0) {
        return Math.clamp(numCands, newK, NUM_CANDS_LIMIT);
    }
    long scaled = (long) Math.ceil((double) numCands * newK / k);
    return Math.clamp(scaled, newK, NUM_CANDS_LIMIT);
}
Retrying when post-filtering comes up short
The binomial model is calibrated for ~99.4% success, and its independence assumption can be wrong. Therefore, round one sometimes comes up short. The retry round is what turns "usually enough" into "enough."
It runs only if the shortfall looks like bad luck rather than a bad model. If round one returned far fewer survivors than global selectivity predicts, that is evidence that the filter is correlated with the query neighborhood; the case the binomial model explicitly cannot handle. More rounds will not fix a wrong model, so we exit early instead:
double expectedHits = k * (double) selectivity;
double threshold = expectedHits * 0.5;
boolean shouldExit = scoreDocsCount < threshold;
Fewer than half the predicted survivors means the filter is hostile to this query's vector neighborhood, and pre-filtering is the right tool. The check is skipped for k < 5 , where the expected count is too small for the ratio to mean anything.
A retry is not just a re-run with a bigger k ; that would re-find the same candidates. It has to search somewhere new, so it carries three pieces of state forward:
int remaining = expectedBaseQueryDocMatches - scoreDocs.length;
int retryK = PostFilterableKnnQuery.computeScaledK(remaining, selectivity);
Query retry = postFilterQuery.createRetryQuery(searcher.getIndexReader(), excluded, seedDocsPerLeaf, retryK);
TopDocs retryDocs = searcher.search(retry, retryK);
An exclusion set. Every document seen in round one, both the ones that passed the filter and the ones that did not, is excluded via an ExcludeDocsQuery. HNSW composes it into the accept-docs; IVF pushes it into posting-list iteration so the codec skips those documents outright.
Seed entry points. For HNSW, restarting the graph walk from the top layer would retrace the same descent. Instead, the retry seeds from the nearest round-one matches (up to four per segment) so it starts already in the right neighborhood and explores outward:
int[][] seedDocsPerLeaf = nearestSeedsPerLeaf(matching, MAX_SEEDS_PER_LEAF);IVF ignores seeds (for now); it already knows which centroids are closest and simply rescans them with the excluded documents skipped.
A re-sized target. remaining is the shortfall in survivors. It is run back through computeScaledK with the same selectivity to inflate it for the attrition the retry will also suffer.
There is exactly one retry. A second would be chasing a distribution the model has already been shown to be wrong about, and the fallback below is both cheaper and strictly correct.
Falling back to pre-filtering
The fallback round makes automatic post-filtering safe to enable by default. If post-filtering does not produce the full candidate pool, its results are thrown away, and the original pre-filtered query runs instead.
if (scoreDocs.length < expectedBaseQueryDocMatches) {
    logger.debug(
        "post filtering retrieved only [{}] results, less than the desired [{}] results. Falling back to original query",
        scoreDocs.length,
        expectedBaseQueryDocMatches
    );
    return null;
}
Returning null from postFilterRewrite sends rewrite down the ordinary path:
Query rewritten = ((Query) innerQuery).rewrite(searcher);
this.totalVectorOps += innerQuery.totalVectorOps();
return rewritten;ScorerSupplier#cost() be good enough; it only has to be right often enough to pay for the times it is wrong.In short, after round one:- If at least candidates passed the filter, return the nearest .
- If fewer than half the expected number passed (), exit early to the pre-filtered query.
- Otherwise, retry once. If at least have passed by then, return the nearest ; if not, fall back to the pre-filtered query.The same two checks, one row per round. Every pre-filter outcome returns exactly what pre-filtering alone would.
One detail that matters for score correctness. For quantized fields, approximate scores get refined by an exact rescoring pass. Normally, IVF does that inside its own rewrite, but on a post-filter delegate it must happen after filtering, or we would rescore documents that are about to be discarded. The delegate skips it, and the orchestrator calls back in through finalizeTopK once the pool is final. Without that hook, post-filtered results would carry raw quantized scores while fallback results carried exact ones, mixing two score domains inside a single search.
A filtered kNN query, end to end
Say you run this against a 10M-document shard where language: en matches 9M of them:
{
  "knn": {
    "field": "embedding",
    "query_vector": [...],
    "k": 10,
    "num_candidates": 100,
    "filter": { "term": { "language": "en" } }
  }
}
1. Rewrite. PostFilterKnnQuery#rewrite builds the filter Weight, conjoined with a FieldExistsQuery on embedding, so documents without a vector never count, but does not execute it.
2. Estimate. ScorerSupplier#cost() over the segments gives ~9M against 10M indexed vectors: . That clears the default threshold of 0.7, so post-filtering is on. (Had it come in at 0.4, we would stop here and run the ordinary pre-filtered query.)
3. Size round one. , so a filter-less delegate is built asking for 15 results instead of 10. Its exploration budget follows the rules above: on HNSW, num_candidates stays at 100, the beam width; on IVF, it scales to 150 so the visit ratio does not change.
4. Search unfiltered. The delegate runs across all segments with no accept-docs bitset: no filter materialization and no extra exploration. Each segment keeps every candidate its own search collected, so the orchestrator does not have to re-derive them. On HNSW that is the segment's whole beam, up to 100 candidates; on IVF it is a small multiple of the 15 requested, since IVF over-collects to absorb documents that appear in more than one posting list.
5. Apply the filter to the candidates, not to 10 million documents. applyFilter walks each segment's candidates in doc-ID order and tests them through Lucene#asSequentialAccessBits. For a filter exposing a TwoPhaseIterator, that is one approximation advance per candidate, plus a matches() call whenever the approximation lands on it. This is the whole point: the filter is evaluated once per candidate rather than once per document in the segment.
It also means the filter no longer needs to be cached to be fast. With pre-filtering, the usual way to avoid paying for materialization on every query is the filter cache, which stores the filter's per-segment bitset for reuse. That only helps once a filter has been seen often enough to get cached, and every new segment starts cold. Post-filtering has nothing worth caching: applyFilter tells the filter how few candidates it will be checked against, and Lucene's query cache declines to build a bitset for a filter that matches millions of documents when only a tiny fraction of them will be looked at. The filter is just as fast on its first use as on its hundredth.
6. Check against the target. The target is the 10 results the user asked for. With a filter that passes 90% of documents, roughly nine in ten candidates pass, far more than 10 across the segments. We deduplicate and keep the 10 nearest.
Suppose instead that only 7 distinct candidates had passed, as can happen when the filter is correlated with the query, like the Spanish-language query from earlier. 7 is above the hostile-filter threshold (), so a retry fires: exclude every candidate already seen, whether it passed or not, seed from up to 4 of the nearest passing candidates per segment, and ask for computeScaledK(3, 0.9) = 5 more to cover the shortfall of 3. If that still leaves us short of 10, the pre-filtered query runs and post-filtering has cost nothing but the candidate collection.
7. Finalize. Select the top k by score via introselect and wrap the result in a KnnScoreDocQuery.
The filter was evaluated only on the candidates the vector search returned, instead of on ten million documents. The vector search was unconstrained, and the returned documents are the same 10 that pre-filtering would have found, with a guarantee that if they were not, you would have gotten the pre-filtered answer instead.
Post-filtering vs. pre-filtering benchmarks on up to 10M vectors
Benchmark setup
To measure the ceiling here, we ran a forced comparison: every configuration executed twice, once pre-filtered and once post-filtered, with the adaptive logic bypassed so that neither strategy could bail out to the other. That is a deliberately harsher test than production behavior; the real implementation picks per query and falls back, but it maps out where each strategy wins.
Grid: 5 datasets from 523K to 10M vectors, each indexed with both IVF and HNSW, in both single- and multi-segment layouts, against 5 filter types at 7 selectivities, run both pre-filtered and post-filtered: 5 × 2 × 2 × 5 × 7 × 2 = 1400 measurements, or 700 matched pre/post pairs. The seven selectivities are 0.55, 0.7, 0.8, 0.9, 0.95, 0.99, and 1.0, where 1.0 means no filter. Fixed at num_candidates=1000, k=10, 1% visit ratio, uncached filters, 300 queries per point. IVF with clusterSize=384; HNSW with m=16, efConstruction=200; 1-bit quantization throughout.
Filters were uncached. That is the cold case for pre-filtering: a warm filter cache would narrow the gap for filters that repeat across queries. It is also the only case for post-filtering, which never relies on the cache in the first place.
Not every dataset has a numeric, keyword, or text field for the range, term, and phrase filters to target. Where one was missing, we added it and filled it with random content. We then sampled the corpus to pick filter values that match the target D% of documents:
rangeis a range query over a numeric field, with bounds chosen so that D% of the documents fall inside them.termmatches a keyword value that D% of the documents carry.phraseis a phrase query over a text field, for a phrase that D% of the documents contain. Evaluating it means checking term positions, not just term presence, which makes it the most expensive filter here to materialize.range_termcombines arangeand atermfilter in aboolquery.randommatches a randomly chosen D% of the documents.
Results across corpus sizes and filter types
For filtering, the property of a dataset that matters most is its size, since materializing a filter costs time in proportion to the number of documents in each segment. We use the five datasets to show how the two strategies compare as the corpus grows, and take the detailed numbers below from the largest, cohere-msmarco-10M (10M vectors, 1024 dimensions, float32).
Median post-filter speedup over pre-filter across selectivities below 1.0, by corpus size. Blue means post-filtering is faster, red means pre-filtering is faster.
Post-filtering comes out ahead almost everywhere: at every corpus size, with both index types, and in both layouts. How far ahead depends on how expensive the filter is to materialize, and in most layouts the gap widens as the corpus grows. The 16 cells out of 100 below 1.0x are all cheap term or range filters on multi-segment layouts, and the lowest is 0.68x.
On the cohere-msmarco-10M dataset, 104 of the 120 filtered pairs are faster with post-filtering, including all 60 on a single segment, and 2 more are ties (within 2%). The remaining 14 are cheap range and term filters on multi-segment layouts, where pre-filtering is ahead by at most 1.33x (1.76 ms against 2.34 ms).
The latency-versus-selectivity curves show the mechanism directly:
Latency vs filter selectivity on cohere-msmarco-10M, single segment. Red is pre-filter, blue is post-filter; solid lines are IVF, dashed are HNSW.
The blue post-filter lines are nearly flat. With post-filtering, latency is driven mainly by the kNN search itself, which runs unfiltered and therefore costs the same no matter how much the filter matches. Applying the filter to the candidates adds little on top, and the over-collection stays small even as the filter narrows. For a given filter type, latency is almost indifferent to selectivity: in the median configuration it varies by about 10% across the whole 0.55-0.99 range, against about 50% for pre-filtering. The red pre-filter lines sit above them by roughly the cost of materializing the filter, meaning the gap is as large as the filter is expensive, and everything converges at 1.0, where there is no filter to evaluate.
Recall is essentially strategy-independent: every one of the 140 pairs is within 0.01 recall, so the trade-off really is pure latency.
Each point is one of the 140 pre/post pairs on cohere-msmarco-10M. Left: recall. Right: latency on a log scale; points below the diagonal are faster with post-filtering.
Limitations: Correlated filters and multi-segment layouts
Two caveats are worth stating plainly.
These filters are largely uncorrelated with the vectors. A filter built on random content passes documents independently of where they sit in vector space, which is exactly the assumption the binomial model makes. It shows in the results: within any one configuration, recall differs by at most 0.04 across the five filter types, and median recall is 0.74-0.75 at every selectivity. Correlated filters, like the language example earlier, are handled by the retry, early exit, and fallback rounds, which keep results correct even when the selectivity estimate is off. Measuring how much of the speedup carries over to strongly correlated filters is a natural next benchmark.
Multi-segment layouts shrink post-filtering's edge. Compare the single- and multi-segment panels of the heatmap. Fixed per-segment costs are paid more times, and pre-filtering amortizes its bitset across a smaller maxDoc per segment. Post-filtering still wins on the expensive filters; it just wins by less.
How to enable and tune automatic post-filtering
Automatic post-filtering is scheduled to be enabled by default in Elasticsearch 9.6 and in upcoming Elastic Cloud Serverless releases. Once it is, there is nothing to change in your queries: you keep writing filters inside the knn clause, and each shard decides, query by query, whether post-filtering is worth attempting.
Tuning the post-filter selectivity threshold
That decision is controlled by a single index setting, index.dense_vector.post_filter_selectivity_threshold, which defaults to 0.7. A query goes through the post-filter pipeline when its estimated selectivity is greater than or equal to the threshold. The threshold is therefore a floor on how broad a filter must be before post-filtering is tried:
Threshold | Behavior |
|---|---|
| Off. No filter can qualify. |
| Only very broad filters - matching 90%+ of the corpus - post-filter. |
| Filters matching 70%+ post-filter. |
| Every filtered kNN query attempts post-filtering. |
To tune it for an index, lower it if your filters tend to be expensive to evaluate, or set it to 1.0 to opt out entirely. You can set this up in the index settings:
PUT my-index
{
  "settings": {
    "index.dense_vector.post_filter_selectivity_threshold": 0.5
  },
  "mappings": {
    "properties": {
      "embedding": {
        "type": "dense_vector",
        "dims": 1024,
        "index_options": { "type": "bbq_hnsw" }
      }
    }
  }
}
Scope and limitations
Worth knowing about scope:
- Applies to both HNSW and
bbq_disk(IVF) fields, forfloat,bfloat16, andbyteelement types, as well asbitvectors on HNSW. - Nested vector fields are handled, with one wrinkle: because a nested kNN search keeps only one hit per parent, a parent that already produced a match is excluded from the retry as a whole block, while a parent whose child was merely filtered out stays eligible - a deeper child of it may still pass.
- Query semantics are unchanged. You still write a pre-filter and get pre-filter semantics. Nothing in the request body changes; this is purely an execution-strategy decision.
- The profile shows which strategy ran. When a query is post-filtered, the filter's entry has no
into_bit_set: the filter is checked candidate by candidate, meaning it reports oneadvanceper candidate the vector search returned. On the phrase-filter example from earlier, that is 100advancecalls (one per candidate in the beam), taking well under a millisecond in total, instead of a 33.4 msinto_bit_set. A second hit-list entry, aKnnScoreDocQueryholding the final topk, also appears next to the vector search's own. For the individual decisions (retries, early exits, fallbacks, and the selectivity estimates behind them), setlogger.org.elasticsearch.search.vectors.PostFilterKnnQuery: DEBUG.
What's next for filtered kNN search in Elasticsearch
The pieces we are most interested in improving:
Better selectivity estimates. ScorerSupplier#cost() is free but crude, and it overestimates conjunctions. Elasticsearch already tracks richer field statistics; wiring those in, or sampling the filter over a bounded slice of a segment, would let the threshold be set less conservatively.
Detecting correlation up front. The hostile-filter early exit is reactive: we find out the filter is correlated with the query neighborhood only after spending a round discovering it. Estimating the filter's local pass rate before committing (from the seed documents of the graph descent, say, or from cached per-query statistics) would turn that into a cheap up-front routing decision and let us safely lower the threshold.
Cost-aware routing. The benchmarks say the right threshold depends on filter type as much as selectivity: a match_phrase filter is worth post-filtering at far lower selectivity than a term filter, because its materialization cost is orders of magnitude higher. A cost model over the filter's query shape, rather than selectivity alone, would let the engine make that call per query instead of relying on a single per-index threshold.
Per-segment decisions. Routing is currently per shard, but selectivity and segment size vary between segments. Deciding per segment would let a small segment pre-filter while a large one post-filters in the same query.
The broader point generalizes beyond kNN. Elasticsearch has spent a lot of effort making vector comparisons fast (quantization, SIMD, better HNSW graphs, and a disk-friendly IVF index), and has been rewarded with queries where vector comparison is no longer the bottleneck. When most of a filtered kNN search goes into materializing an expensive filter, the optimization worth having is not a faster distance function. It is noticing that the filter did not need to run over ten million documents to answer a question about ten.
Frequently Asked Questions
What is the difference between pre-filtering and post-filtering in kNN search?
Pre-filtering applies the filter while the vector search runs, so the top k results are the k nearest documents among those matching the filter. Post-filtering runs the vector search unconstrained and applies the filter to the results afterwards, which is faster but can return fewer than k results unless the search over-collects candidates first.
Why is a filtered kNN query sometimes slower than an unfiltered one?
Pre-filtering materializes the filter into a bitset for every segment before any vector comparison happens, and that cost is proportional to segment size rather than to the number of documents the search touches. For an expensive filter such as match_phrase, this work can dominate the query, and it is paid in full even when the filter matches almost every document and therefore excludes almost nothing.
How helpful was this content?
Related Content
GPU-accelerated vector indexing in Elasticsearch with NVIDIA cuVS: 138M vectors in under 10 minutes
AI video search with Elasticsearch and Jina: Find the exact seconds of footage you need
Elasticsearch Vector Database: Ship in minutes, scale affordably to hundreds of billions
One setting for production vector search: How vectordb_document mode tunes Elasticsearch automatically