The fastest work is the work you never do: 100x faster sorted queries in Elasticsearch
How Elasticsearch 9.6 lets ES|QL push its current TopN threshold into Lucene, and how that 100x shows up on some sorted queries and barely registers on others.
Check 100 candidates, not 10 million documents: Faster kNN filters in Elasticsearch
Elasticsearch now decides for each query whether to run a kNN filter before or after the vector search. On a 10M-vector corpus post-filtering was faster in 104 of 120 benchmark pairs while still returning k results.
How Elasticsearch Serverless hollow shards cut indexing-node shutdowns by 30%
Idle indexing shards in Elasticsearch Serverless now drop their Lucene writers and segment readers from memory until the next write, freeing indexing-tier heap at the cost of a median 218ms wait on that first write.
GPU-accelerated vector indexing in Elasticsearch with NVIDIA cuVS: 138M vectors in under 10 minutes
Moving index builds to the GPU leaves the CPU free for queries, which is how vector indexing throughput went up 7x and p90 search latency fell 6x while indexing ran, with no change to recall.
One button, three places: How we rebuilt Kibana's page headers with stricter APIs
We gave Kibana's shared shell typed contracts, which is how design system governance became the default, and why the new page headers have no breadcrumbs.
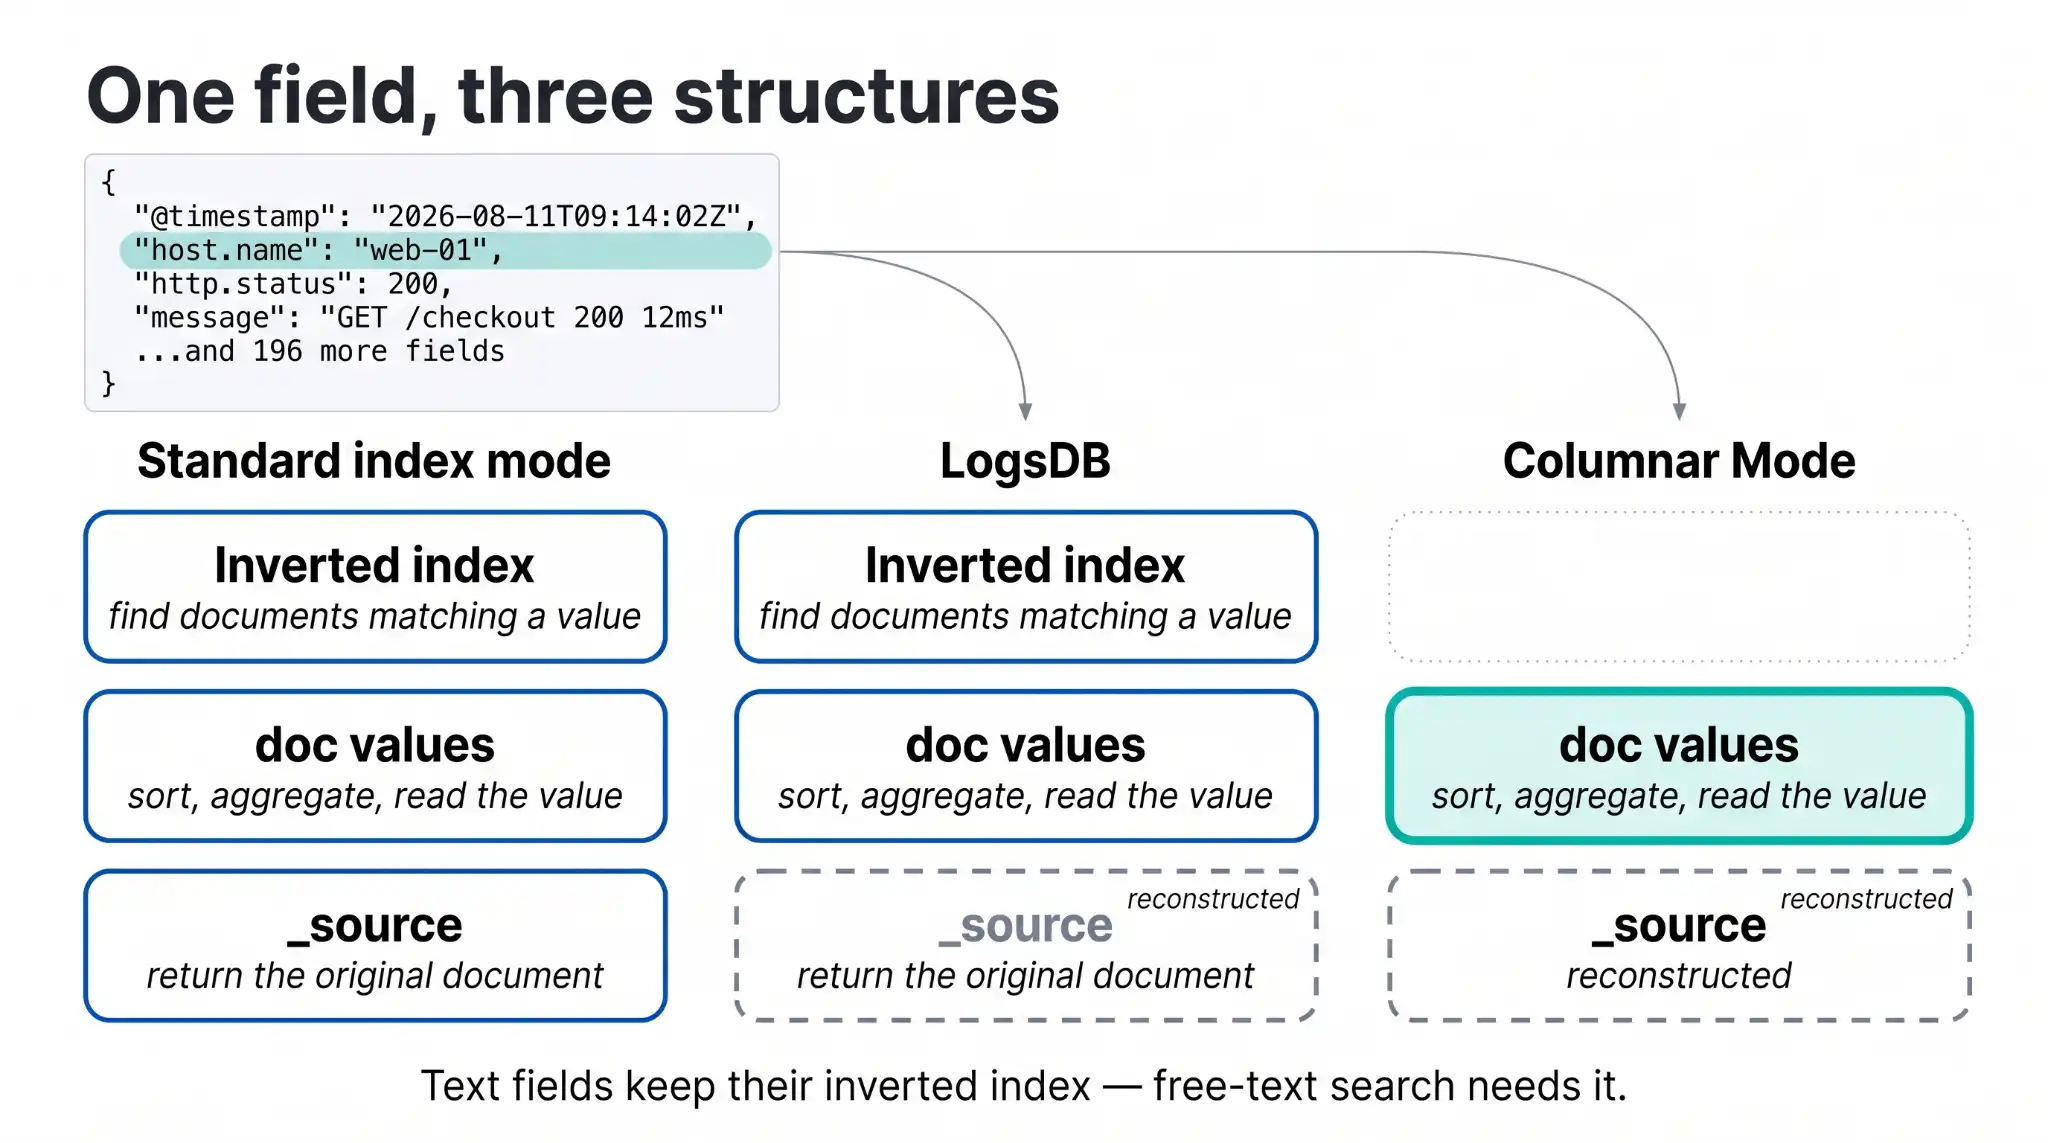
Columnar storage isn't a columnar database. What Columnar mode brings to Elasticsearch
Elasticsearch has stored data in columns since 2013, but adding full columnar database capabilities required a new mode.

How we built PromQL into Elasticsearch
PromQL runs on the same Elasticsearch compute engine as ES|QL, with no plugin and no separate process to operate. Getting there meant changing how the engine evaluates time windows and builds grouping keys.

Trust, but benchmark: How we let an AI agent optimize Elasticsearch
We share how we built a harness that automatically identifies and implements optimizations in the Elasticsearch codebase.
No more allocation delays: Decoupling snapshots from shard relocation in stateless Elasticsearch
Clusters scale out under load without waiting for a snapshot to finish, because snapshots now read straight from the object store and no longer pin shards in place.
Avoiding and Correcting Hotspots: How Elasticsearch Serverless Balances Shards
Elasticsearch Serverless replaces the Elasticsearch node-weight based shard rebalancing algorithm with resource usage aware rebalancing that avoids index shard colocation, OOM events and write load hotspotting
Migrating 1,100 files to Redux Toolkit v2 without freezing the Kibana monorepo
Kibana gave Redux Toolkit v2 the default package name and pushed v1 onto an explicit alias, which inverts the usual migration order. Webpack externals, yarn resolutions and an ESLint rule keep React Redux v7 and v9 out of each other's way.
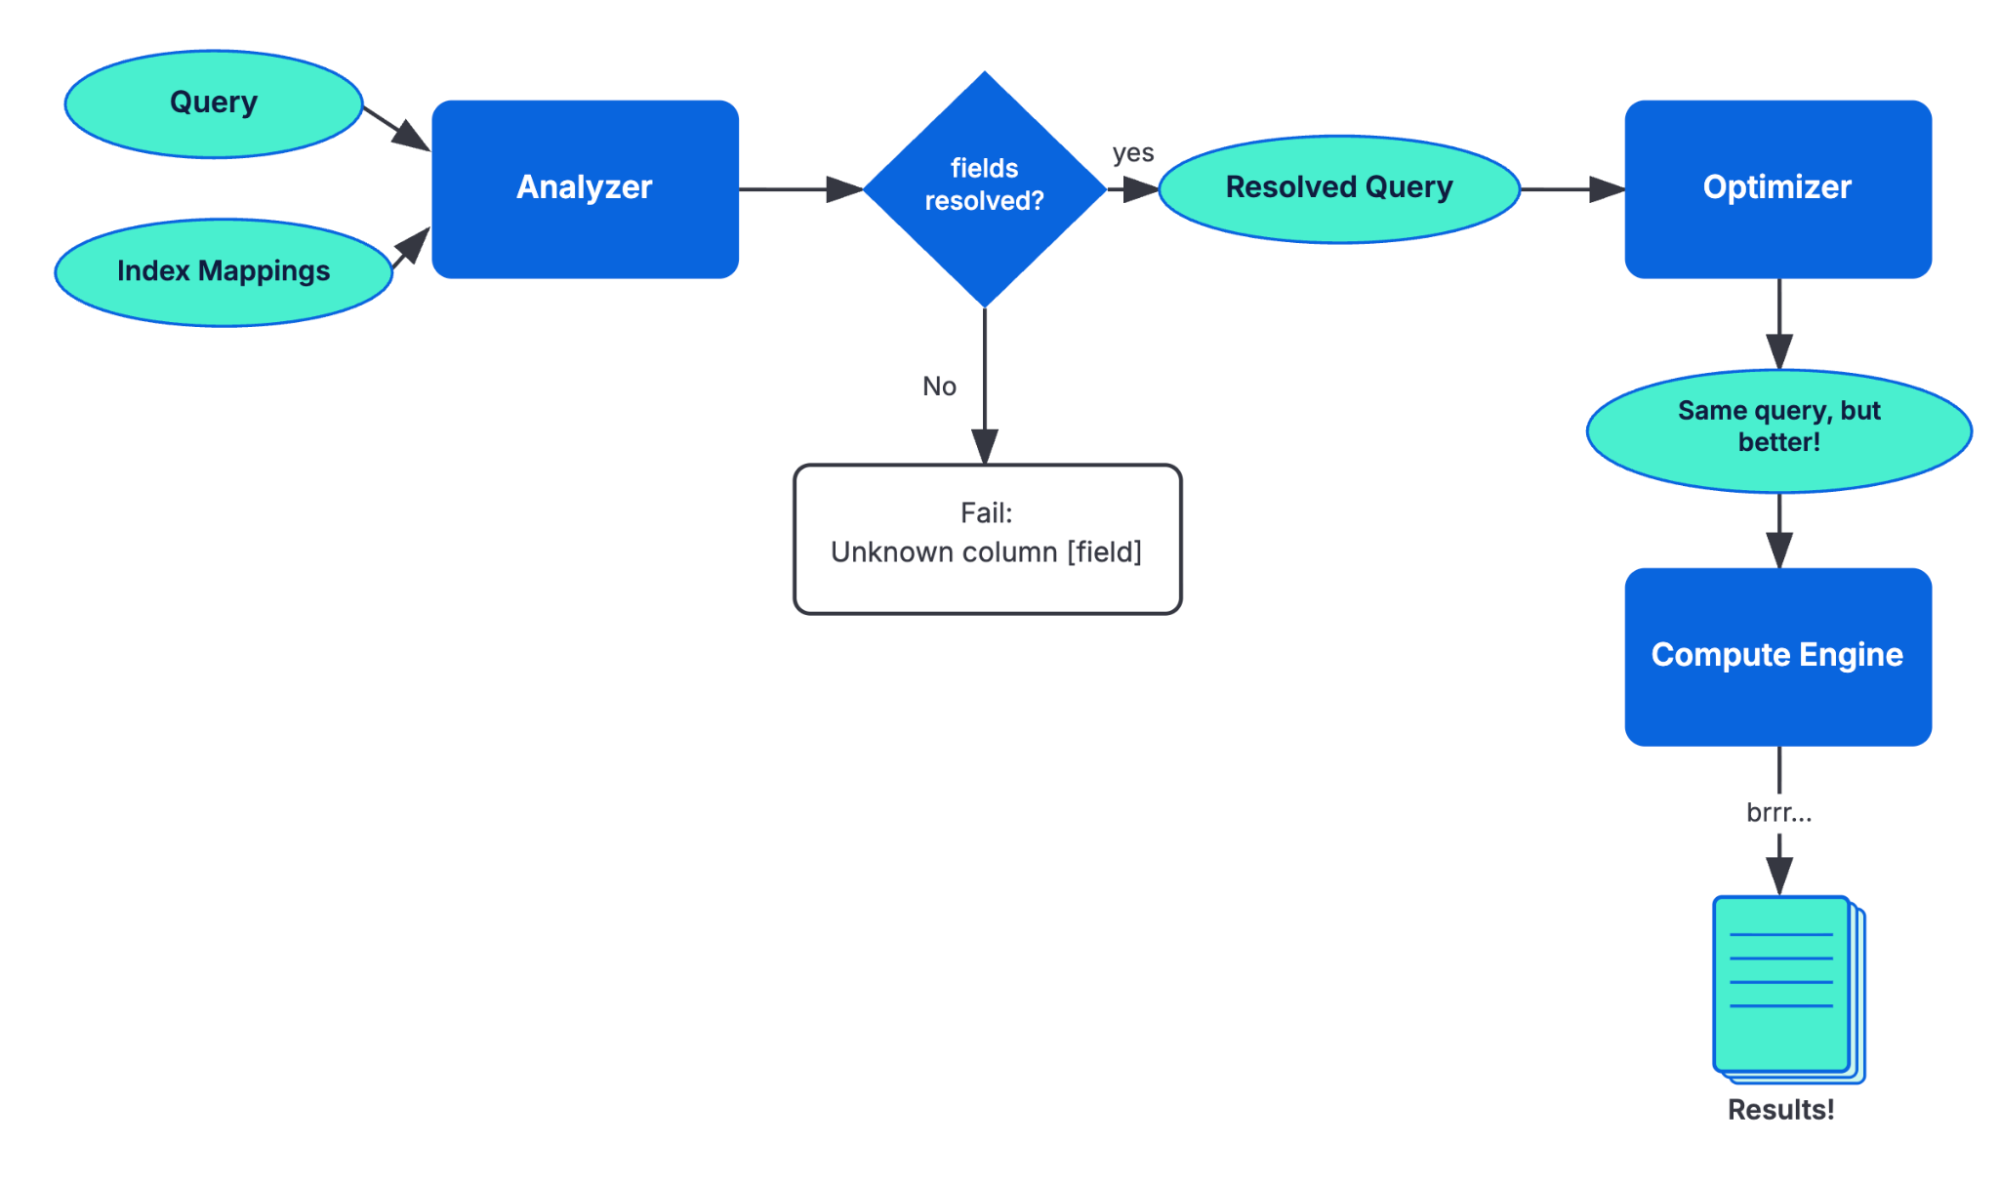
Taming PUNKs: How ES|QL queries Elasticsearch fields it was never told about
In Elasticsearch 9.5, ES|QL can query unmapped fields. It reads them from _source or returns nulls, so a query keeps working when a field drops out of the mapping and you avoid a reindex that takes hours.