Your AI chat is not a screenshot: Live shared conversations in Elastic Agent Builder
Whoever picks up the problem next reads the whole thread and carries on with the same agent, with no access to anything beyond that one conversation.
How we’re building a context engine to cut agent token use by 71%
With a context engine, the same agent and model answered in 64 seconds using 9 tool calls. The baseline took 213 seconds, 33 calls, and missed a key relationship entirely.
Ask Elastic Agent Builder why it's slow: Natural-language trace analysis
Four agent performance questions your Agent Builder traces can answer, covering token spend by model, tool error rates, slow conversation turns, and recent prompts. The ES|QL for each is here, including the type cast SUM() needs.
Agentic workflows in Elasticsearch: pause an AI agent for human approval, resume 72 hours later
Build AI agent orchestration where the workflow waits for a human approval and then executes the fix on its own, with nothing extra to provision and the whole decision trail queryable in Elasticsearch.
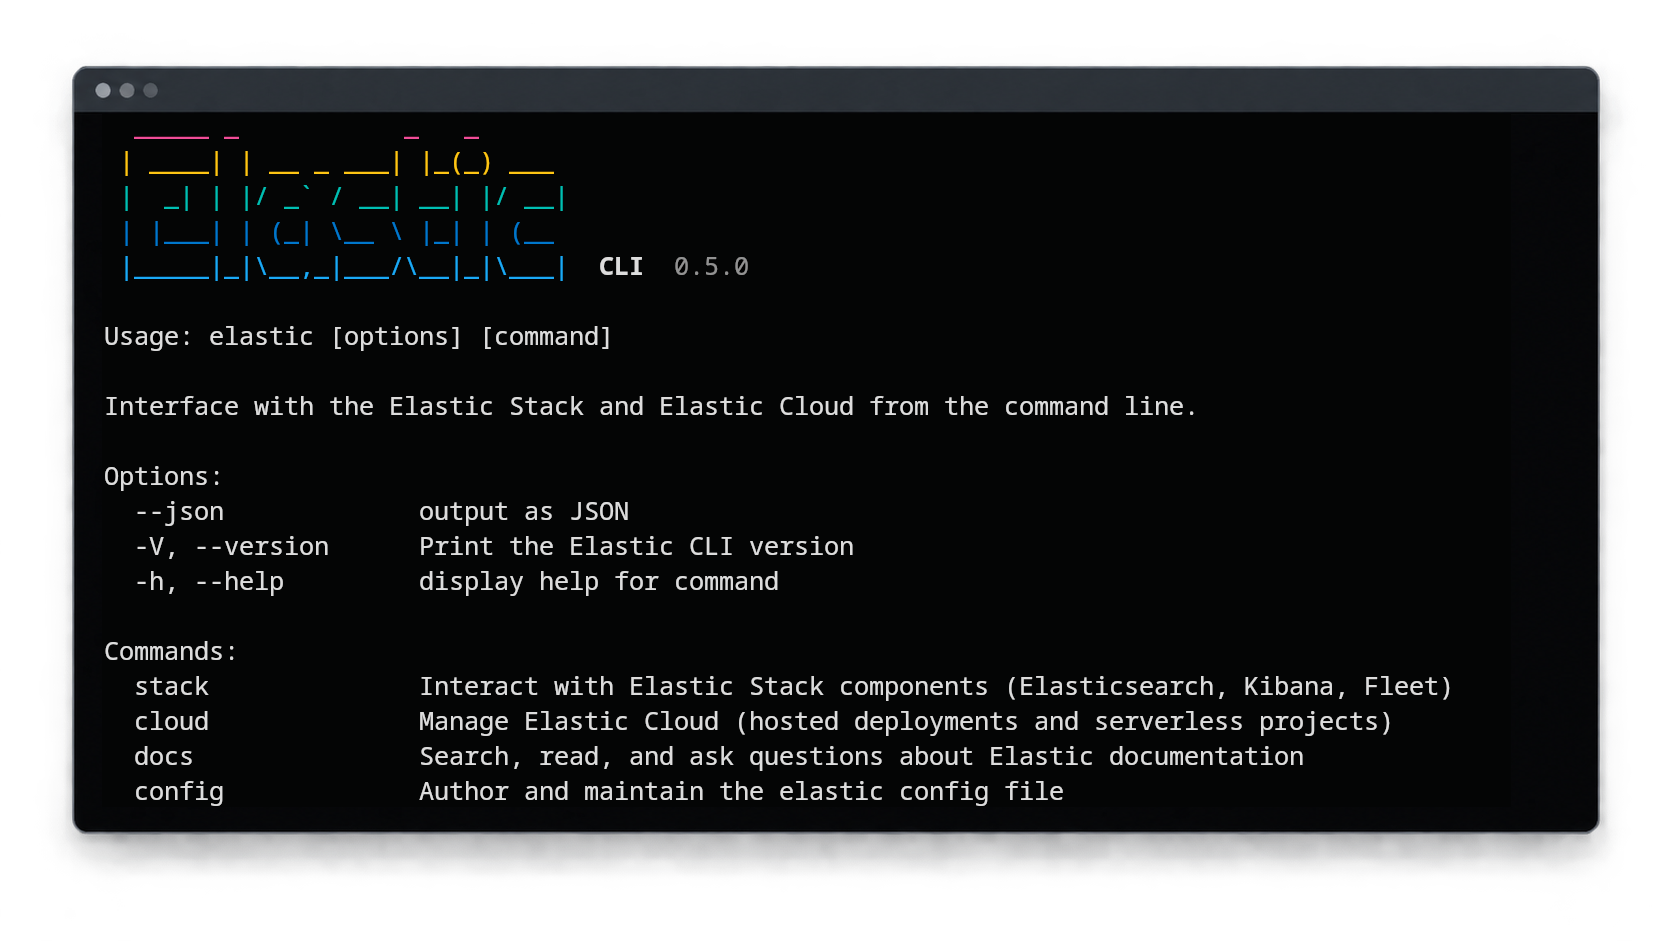
You and your AI agent shouldn't be using curl: Introducing the Elastic CLI and Agent Skills
Elastic CLI reaches every Elasticsearch, Kibana and Cloud API from one command, and it's what Elastic Agent Skills run on. Input is validated against a JSON Schema before anything leaves your machine, and API keys stay in your OS keychain.

Trust, but benchmark: How we let an AI agent optimize Elasticsearch
We share how we built a harness that automatically identifies and implements optimizations in the Elasticsearch codebase.
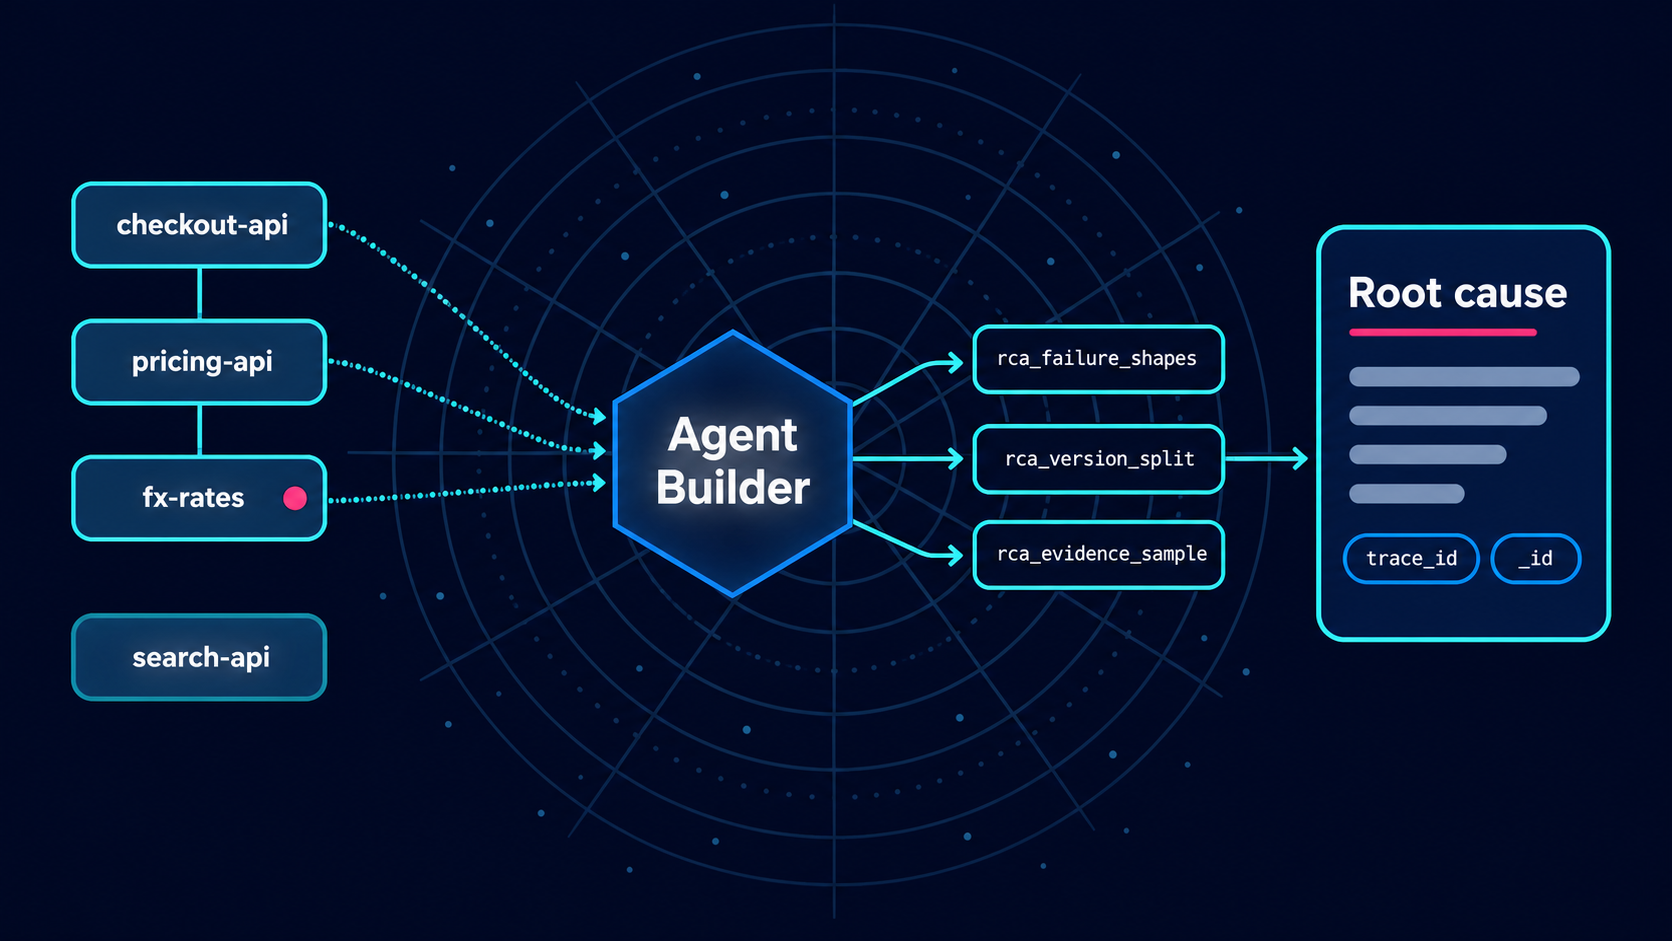
AI root cause analysis in Elastic Agent Builder that cites its evidence
The new release failed at 27.2%, the old one at 28.2%, so the deploy was never the cause; the agent worked that out in 72 seconds and handed back a trace ID for the failure that was.
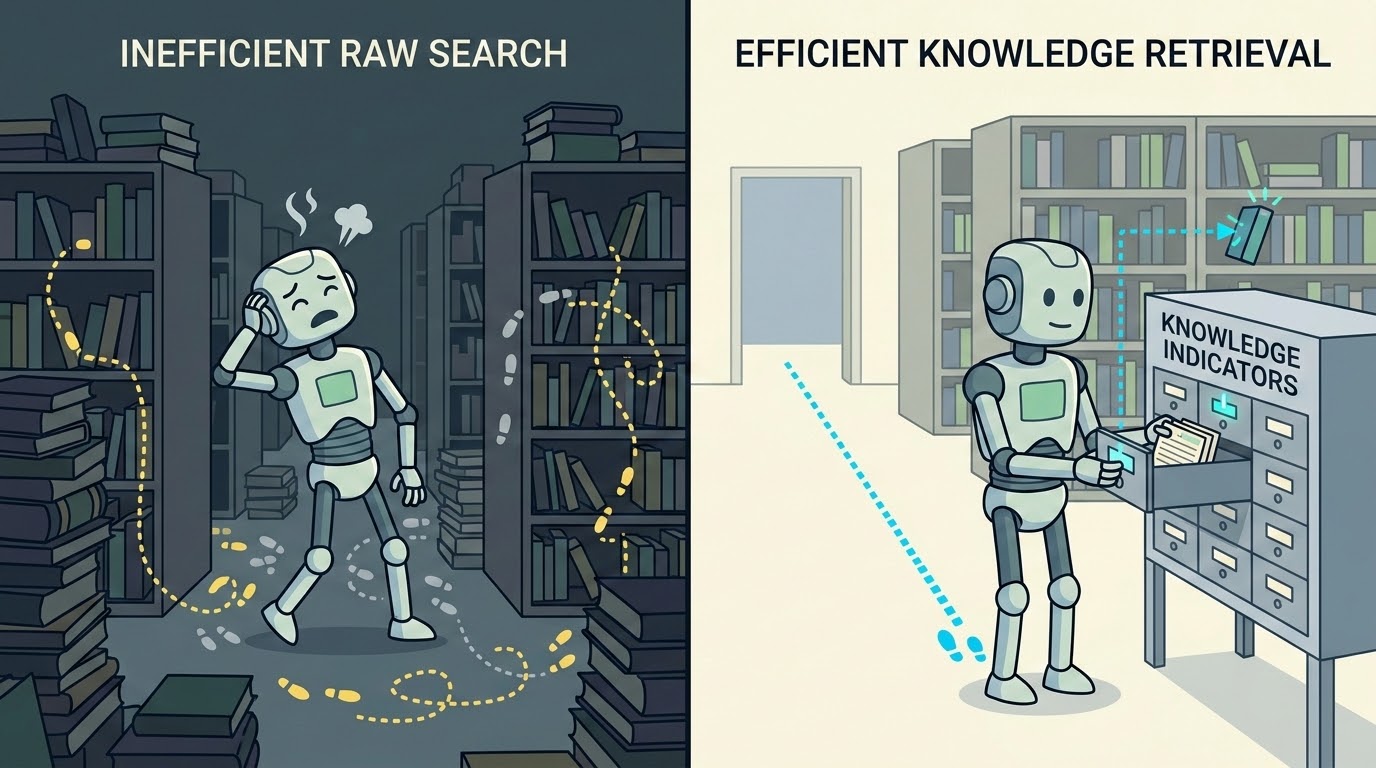
Know your facts: How Elasticsearch AI Indices let agents skip the reading and keep the answer
A technical walkthrough of precomputing facts into an Elasticsearch AI Index, so agents answer from a single ES|QL query instead of reading whole documents, with fewer tokens and lower latency.
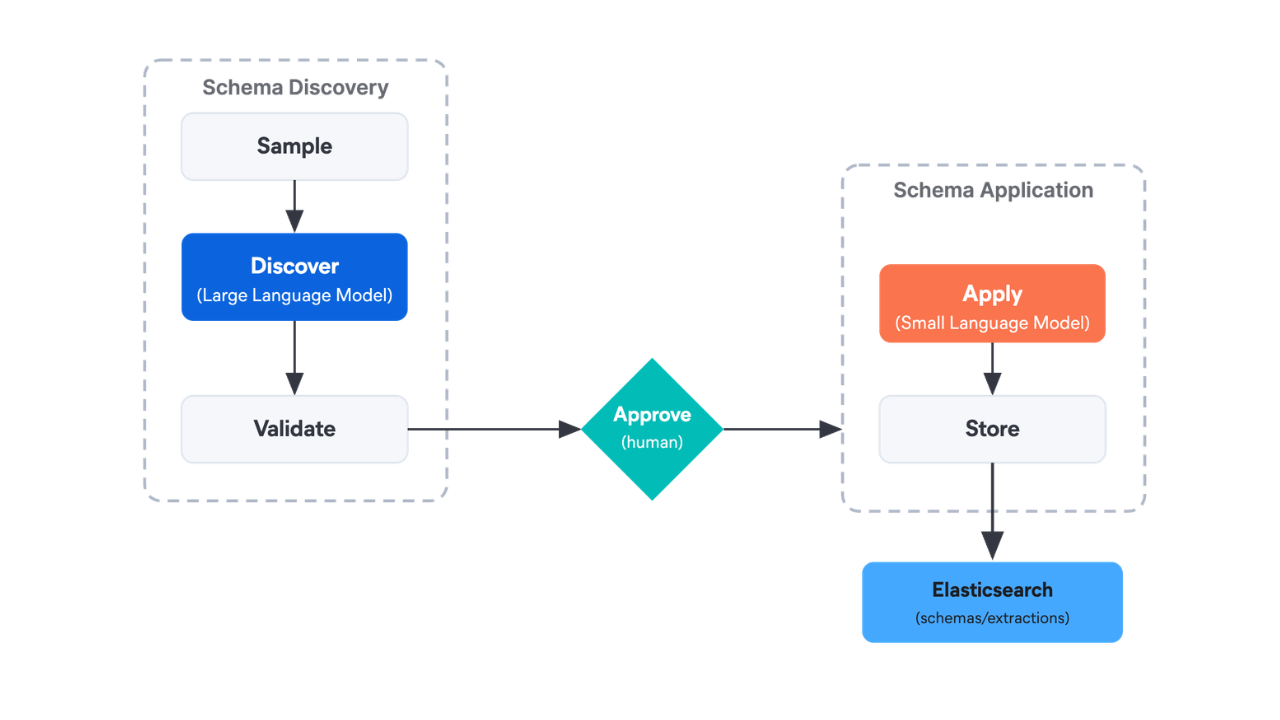
Let the big model think, let the small model work: Splitting LLM costs in Elastic Workflows
Build an Elastic workflow that sends a data sample to a large model to propose classification labels. A human signs off, then a smaller model applies them across the full corpus.
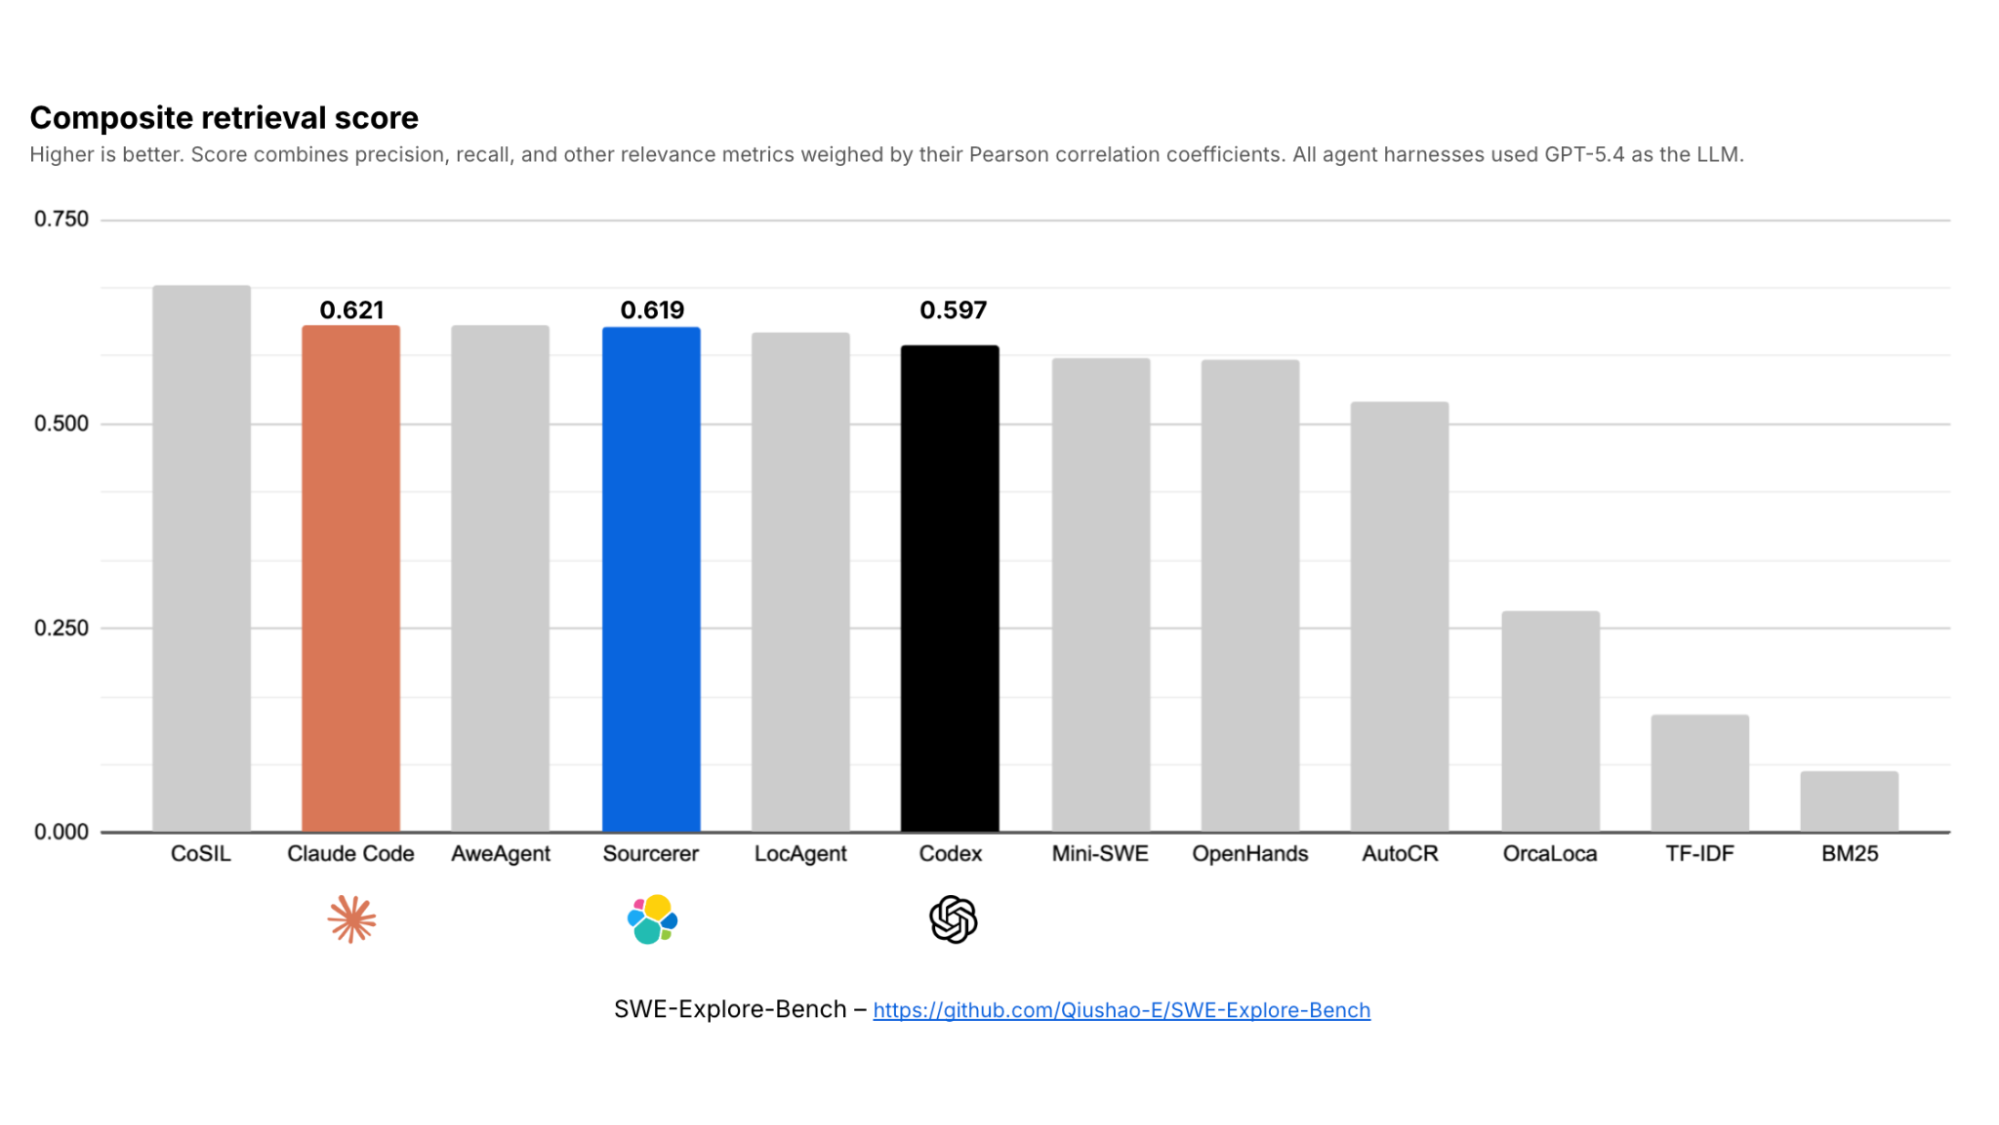
Ask the source: Scaling code search to a billion lines with Elasticsearch and Elastic Agent Builder
Sourcerer matches Claude Code and Codex on code retrieval quality and searches up to thousands of times faster than grep. Every answer links back to the exact files and lines across repos and versions.
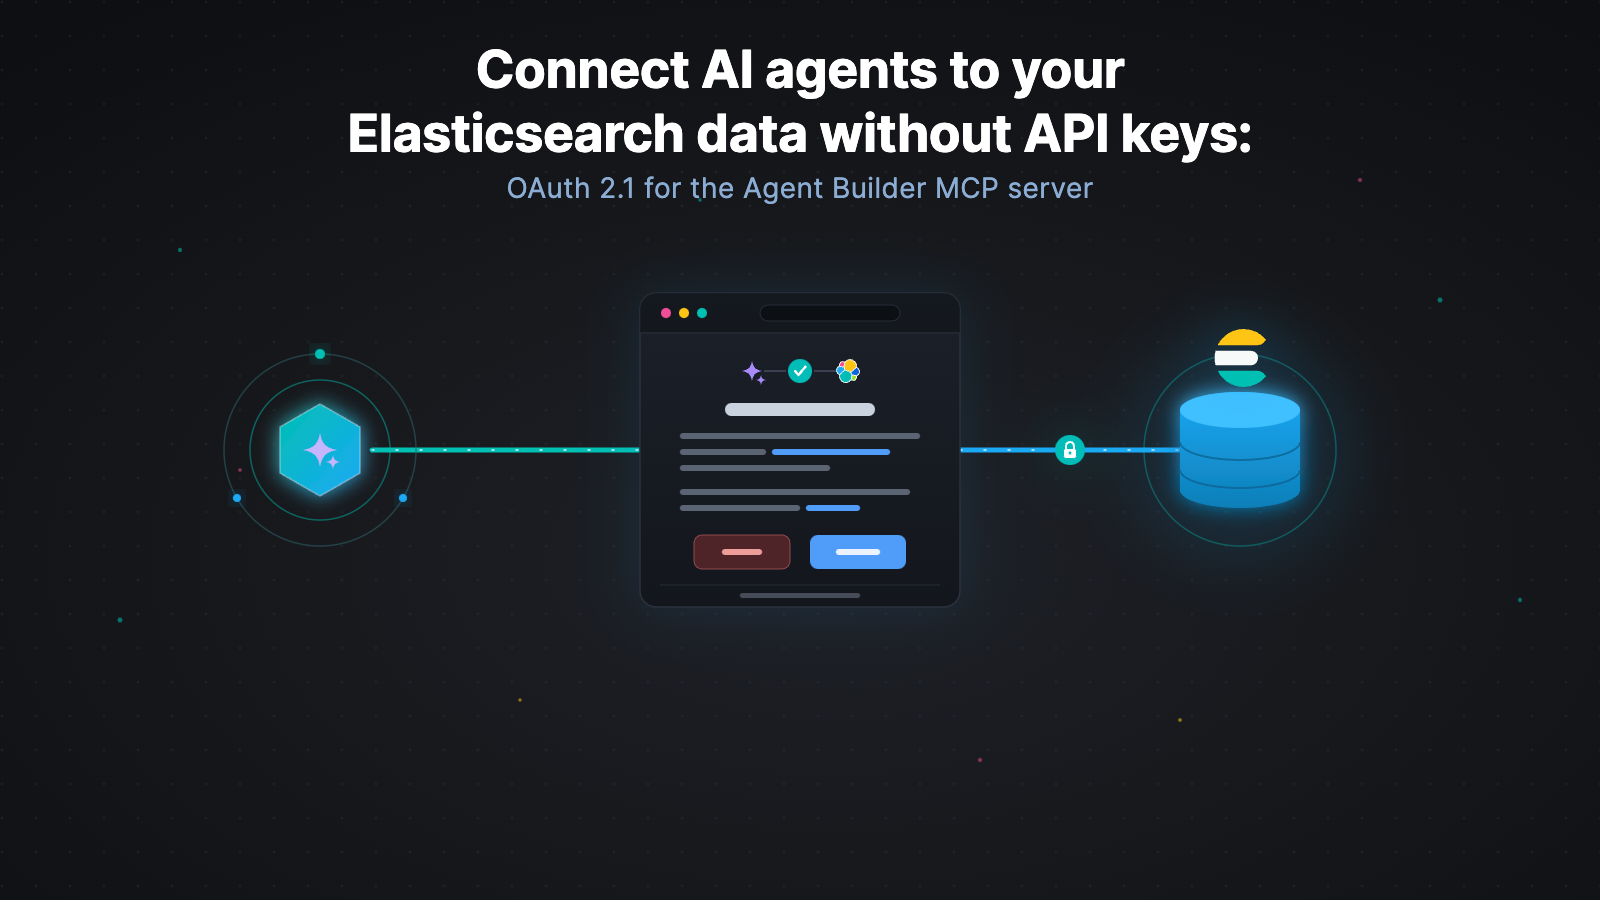
Your AI agent doesn't need your API key: OAuth 2.1 for Elasticsearch MCP server authentication
OAuth 2.1 lets you connect AI agents to the Elasticsearch MCP server with a browser sign-in instead of an API key. Your agent gets a short-lived token tied to your permissions that you can revoke any time.
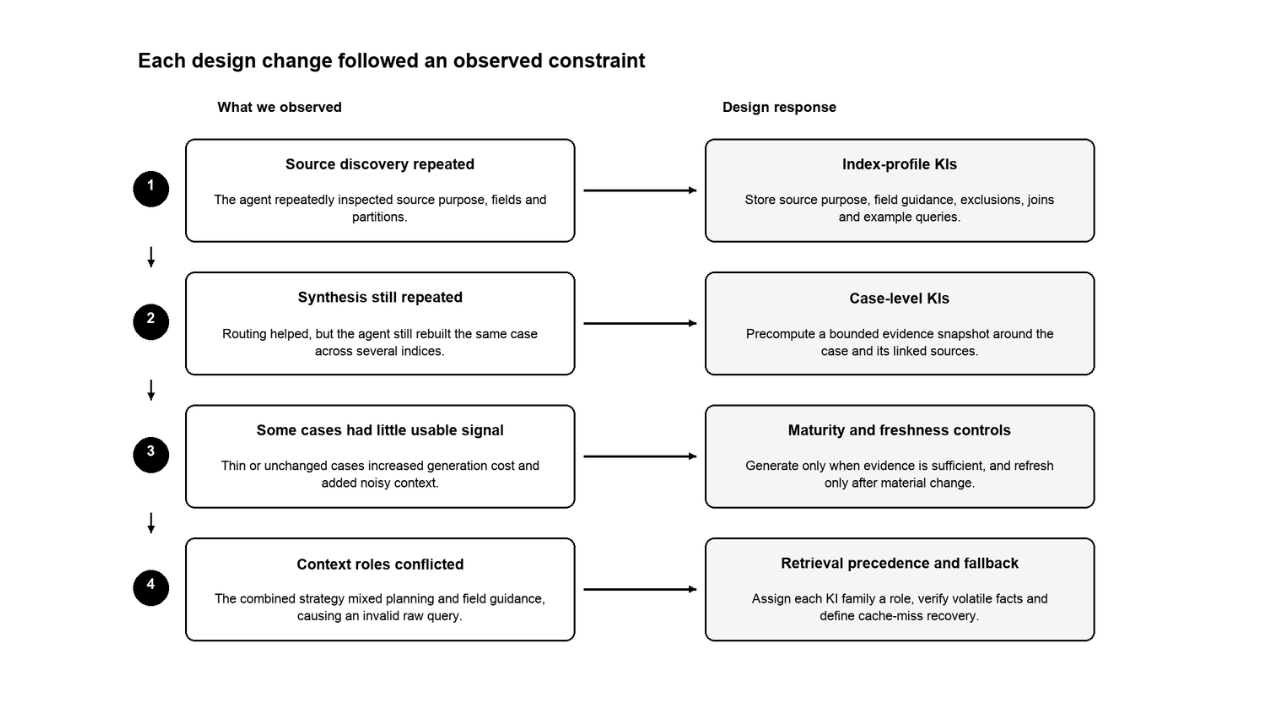
Faster, cheaper support investigations with precomputed context
Precomputed context cut input tokens by 58% and latency by 40% in Elastic’s support agent, making support investigations more efficient by reducing repeated retrieval.