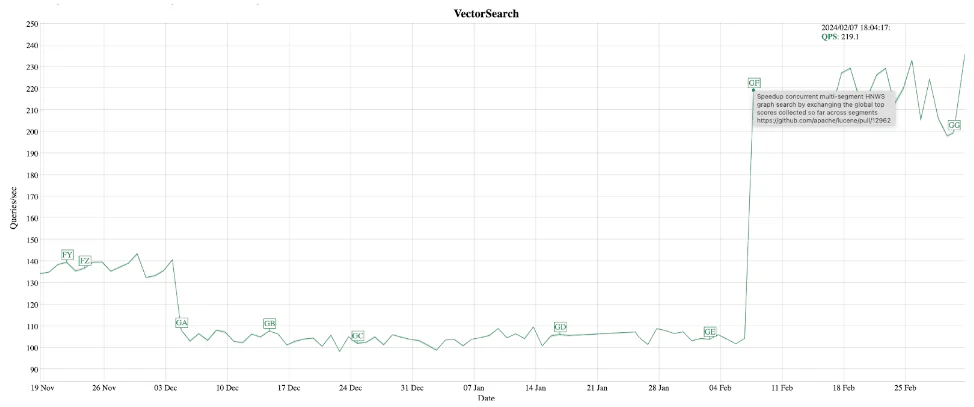
Making Elasticsearch and Lucene the best vector database: up to 8x faster and 32x efficient
Discover the recent enhancements and optimizations that notably improve vector search performance in Elasticsearch & Lucene vector database.
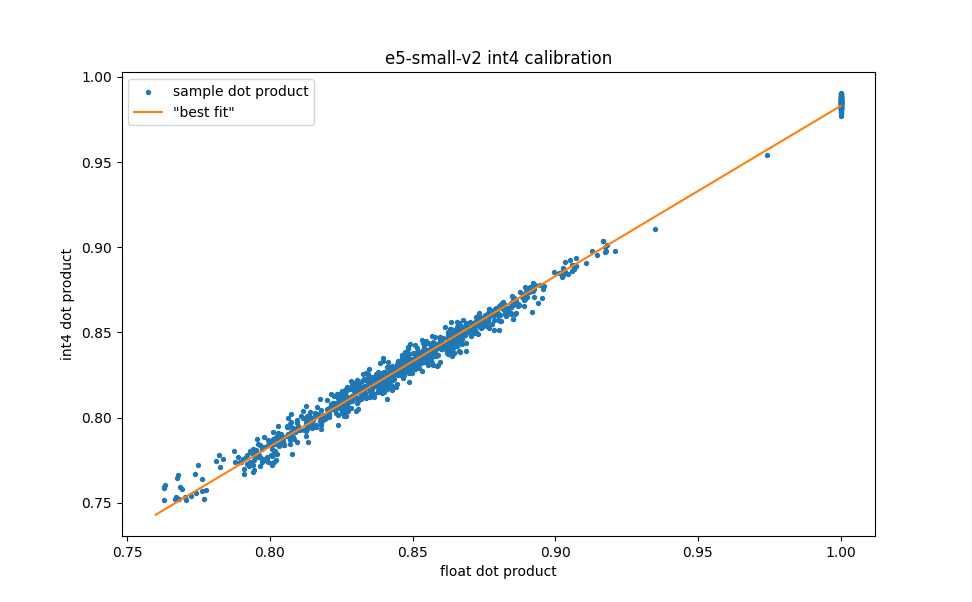
Scalar quantization optimized for vector databases
Optimizing scalar quantization for the vector database use case allows us to achieve significantly better performance for the same retrieval quality at high compression ratios.

Elastic Cloud adds Elasticsearch Vector Database optimized instance to Google Cloud
Elasticsearch's vector search optimized profile for GCP is available. Learn more about it and how to use it in this blog.

Simplifying kNN search
Elastic's kNN search has evolved. This blog explains the simplification of kNN search, where k and num_candidates are now optional.

Elasticsearch open Inference API adds support for Cohere’s Rerank 3 model
“Learn about Cohere reranking, how to use Cohere's Rerank 3 model with the Elasticsearch open inference API and Elastic's roadmap for semantic reranking.”

Using Cohere embeddings with Elastic-built search experiences
Elasticsearch now supports Cohere embeddings! This blog explains how to use Cohere embeddings with Elastic-built search experiences.

Scaling ML inference pipelines in Elasticsearch: How to avoid issues and troubleshoot bottlenecks
Learn strategies to run Machine Learning (ML) inference pipelines in Elasticsearch, troubleshoot bottlenecks and avoid issues when scaling.

Improving text expansion performance using token pruning
Learn about token pruning and how it boosts the performance of text expansion queries by making them more efficient without sacrificing recall.

Semantic search as service at a search center of excellence
Learn how to implement and scale semantic search as a service for a search Center of Excellence (COE) using ELSER.

How to deploy NLP: Text embeddings and vector search
Using text embeddings and vector similarity search, this blog explains how to run deep learning models for NLP & showcases Elasticsearch's vector search capability.

Avatar assisted & dialogue driven voice to RAG search
Create avatar-assisted voice search experience by integrating speech-to-text, semantic search, RAG and a synthesized avatar for responses.

Optimizing vector distance computations with the Foreign Function & Memory (FFM) API
Learn how to optimize vector distance computations using the Foreign Function & Memory (FFM) API to achieve faster performance.