56 scanned pages to a cited answer in 5 minutes: RAG pipeline for the documents search cannot read
Ask a scanned, table-heavy PDF a question in plain language and get an answer stamped with the page it came from, because jina-ocr-v1 turns every page into structured Markdown that Elasticsearch embeds at ingest.
How we’re building a context engine to cut agent token use by 71%
With a context engine, the same agent and model answered in 64 seconds using 9 tool calls. The baseline took 213 seconds, 33 calls, and missed a key relationship entirely.
Using Jev as a search reranker: benchmarks and how to implement
We had Jev score Elasticsearch hybrid search results and let a short Python policy do the reranking, taking nDCG@10 from 0.9351 to 0.9565 on 250 Amazon Shopping Queries, and the code is all here.
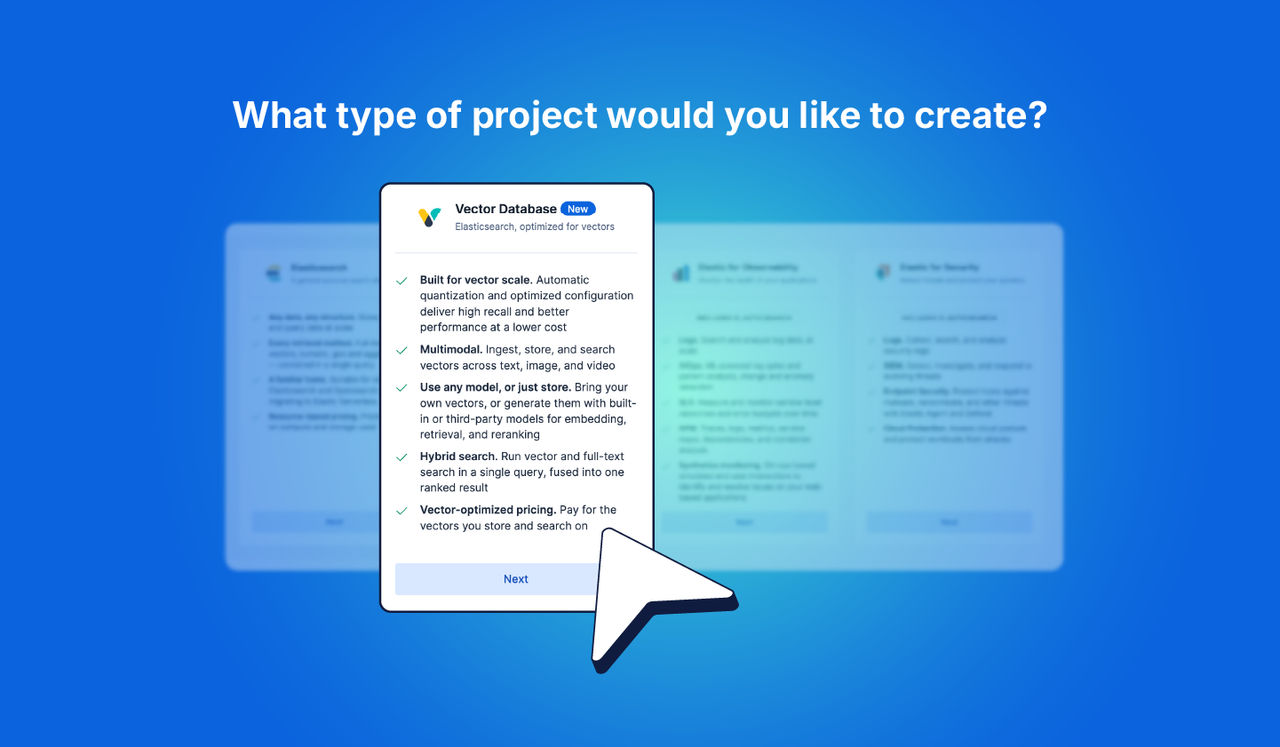
Elasticsearch Vector Database: Ship in minutes, scale affordably to hundreds of billions
The hard parts of hybrid retrieval, already done, with optimized defaults, third party and native Jina AI models, and managed GPU inference all out of the box. Build fast, scalable AI apps, not infrastructure.
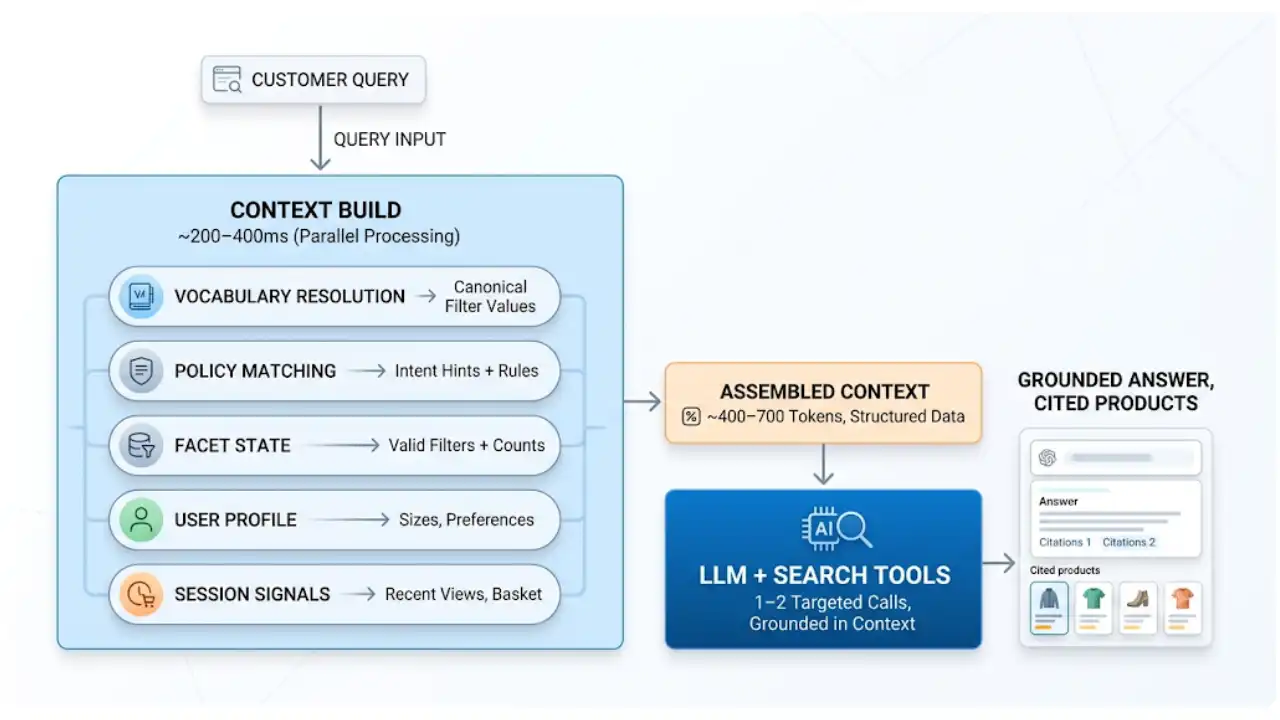
AI shopping agents: Why context comes before the query
AI shopping agents that guess at your vocabulary make expensive mistakes. Pre-computed catalog context stops the guessing before the first tool call.
jina-clip-v2 brings text-to-image search across 89 languages to Elasticsearch, no GPU needed
Run multimodal search across 89 languages inside Elasticsearch with jina-clip-v2: one embedding space for text and images, with no separate model infrastructure to manage.
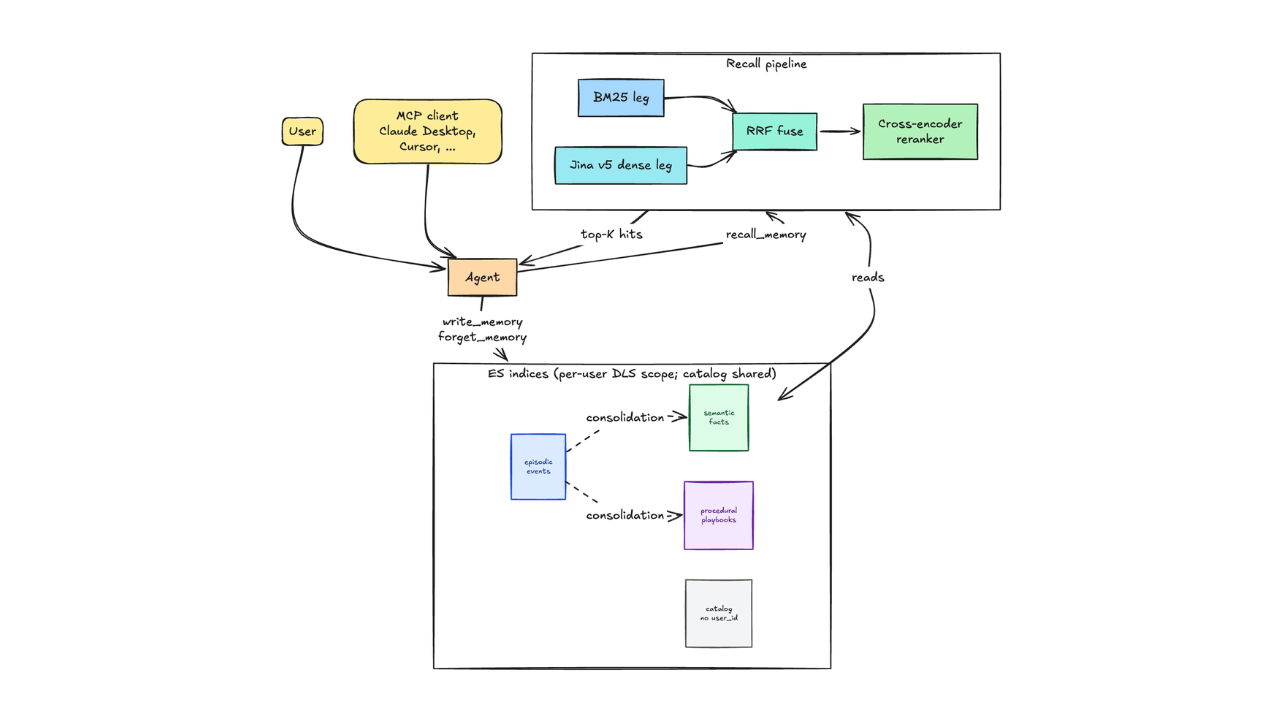
How we built a persistent agent memory layer on Elasticsearch with 0.89 recall and zero tenant leaks
Discover the architecture behind a persistent, multi-tenant agent memory layer on Elasticsearch: three indices, hybrid retrieval with RRF and a reranker, supersession, decay, and per-user DLS isolation. R@10 0.89 across 168 questions. Full open-source implementation included.
Best practices for building a modern app with vector search
Exploring six vector search tips for building modern AI search applications entirely on Elasticsearch, with an opinionated rationale at each architectural decision.
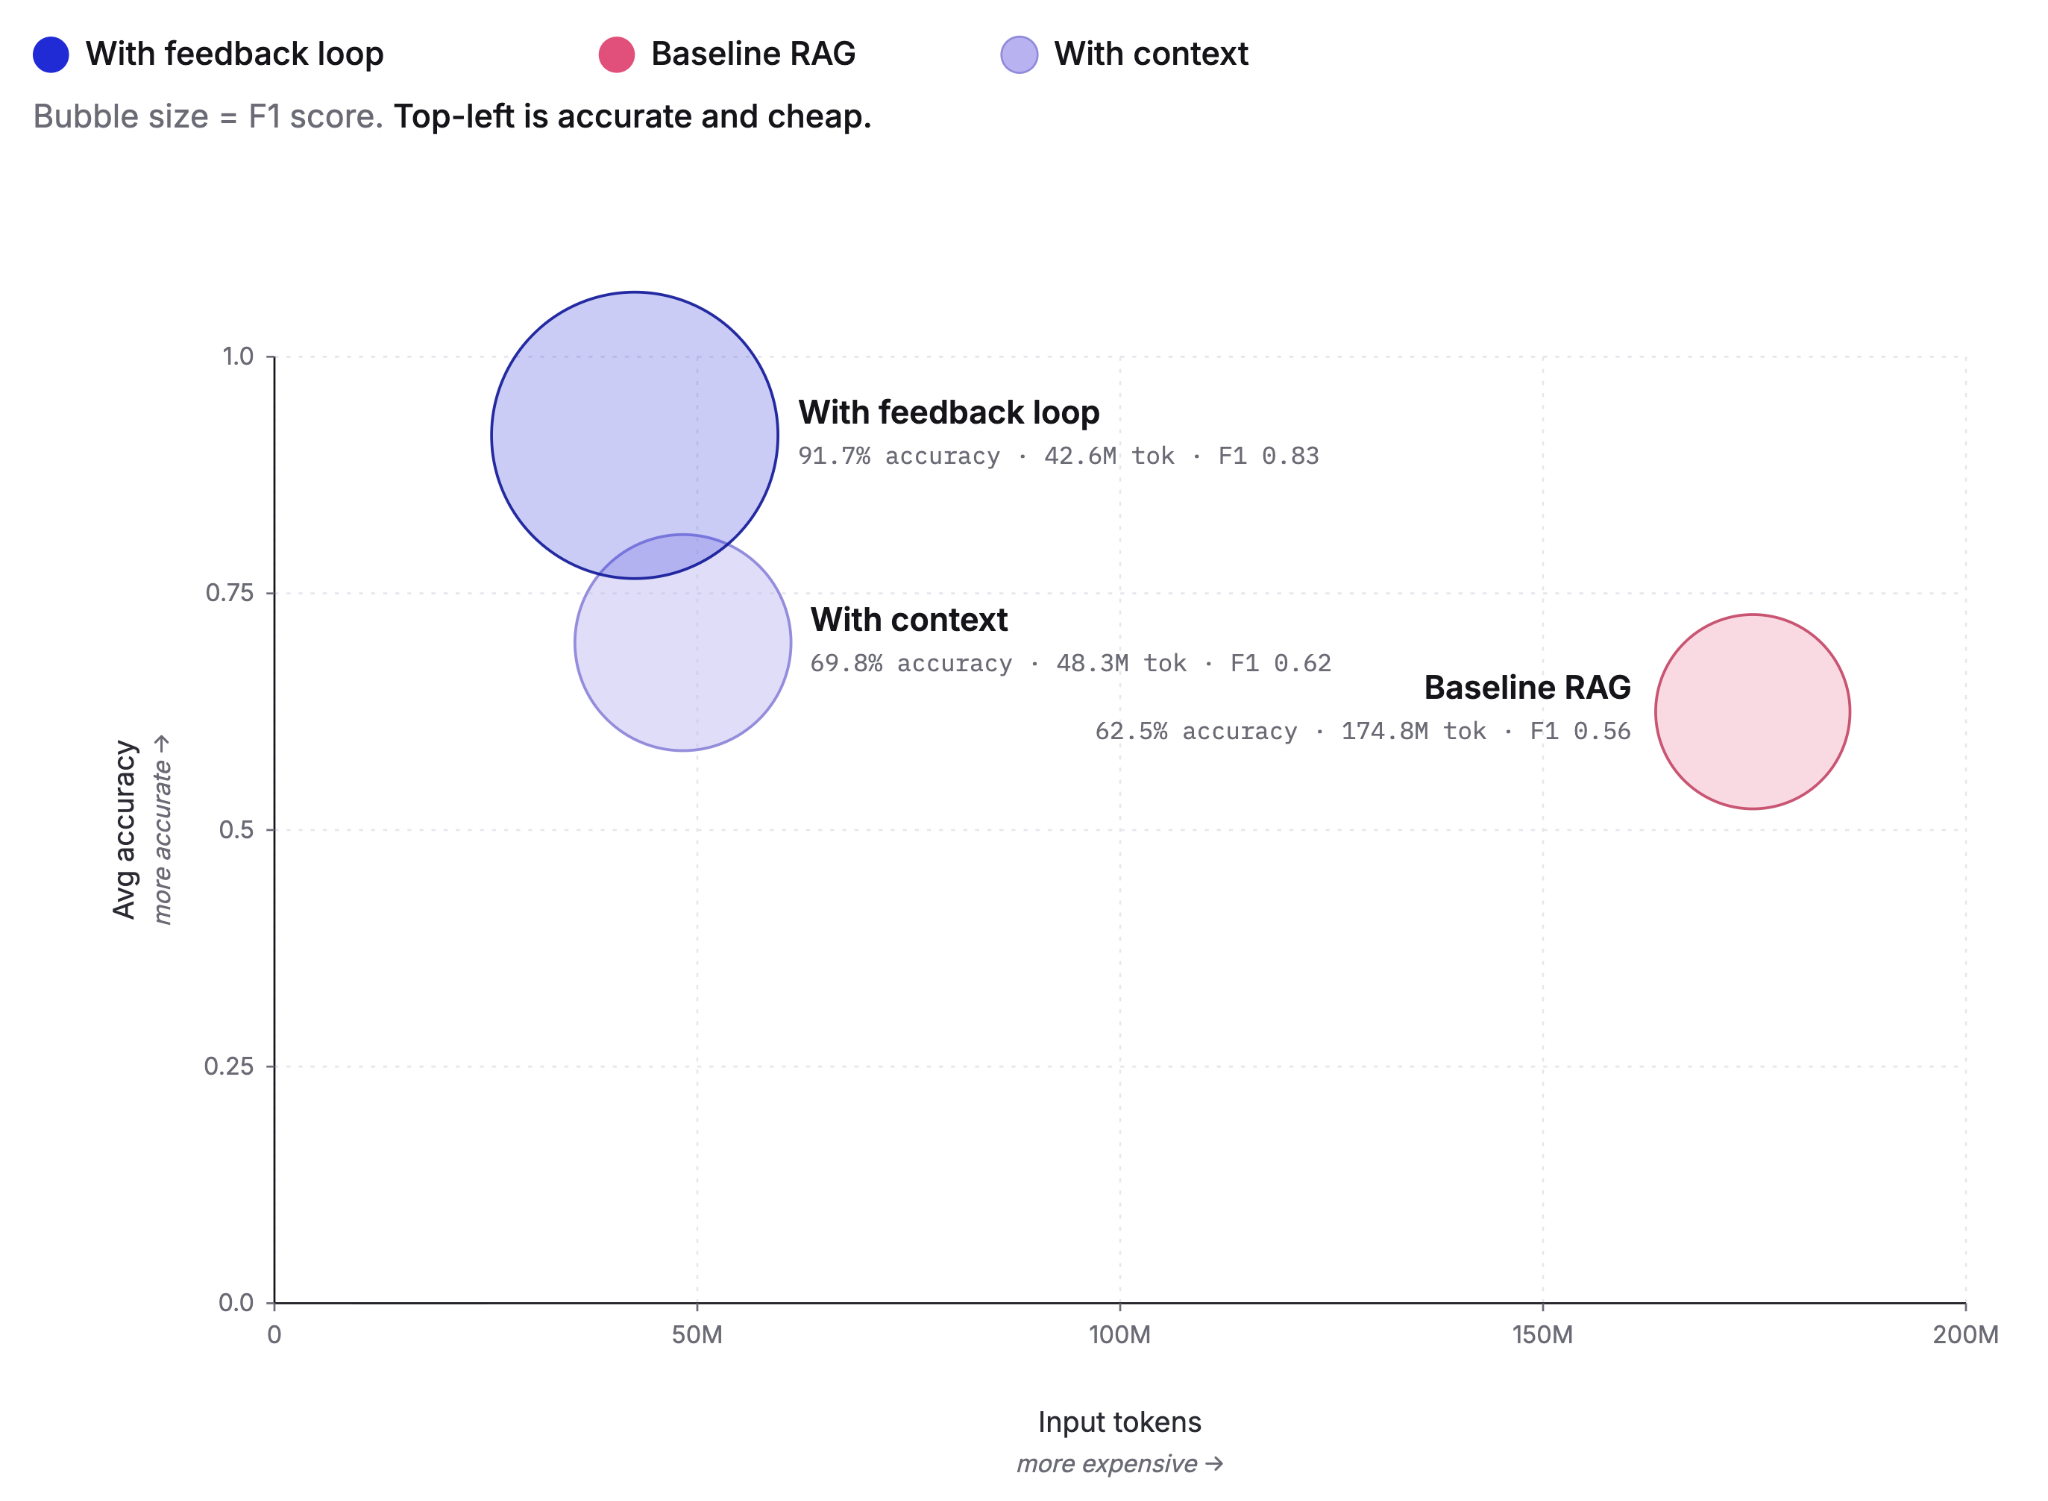
Cutting agent costs with pre-computed context
Pre-computing context as Knowledge Indicators reduces LLM agent token costs by up to 75% and improves answer accuracy from 60% to 92%. This post covers the extraction, retrieval and feedback loop that make it work, tested against the BrowseComp-Plus benchmark.
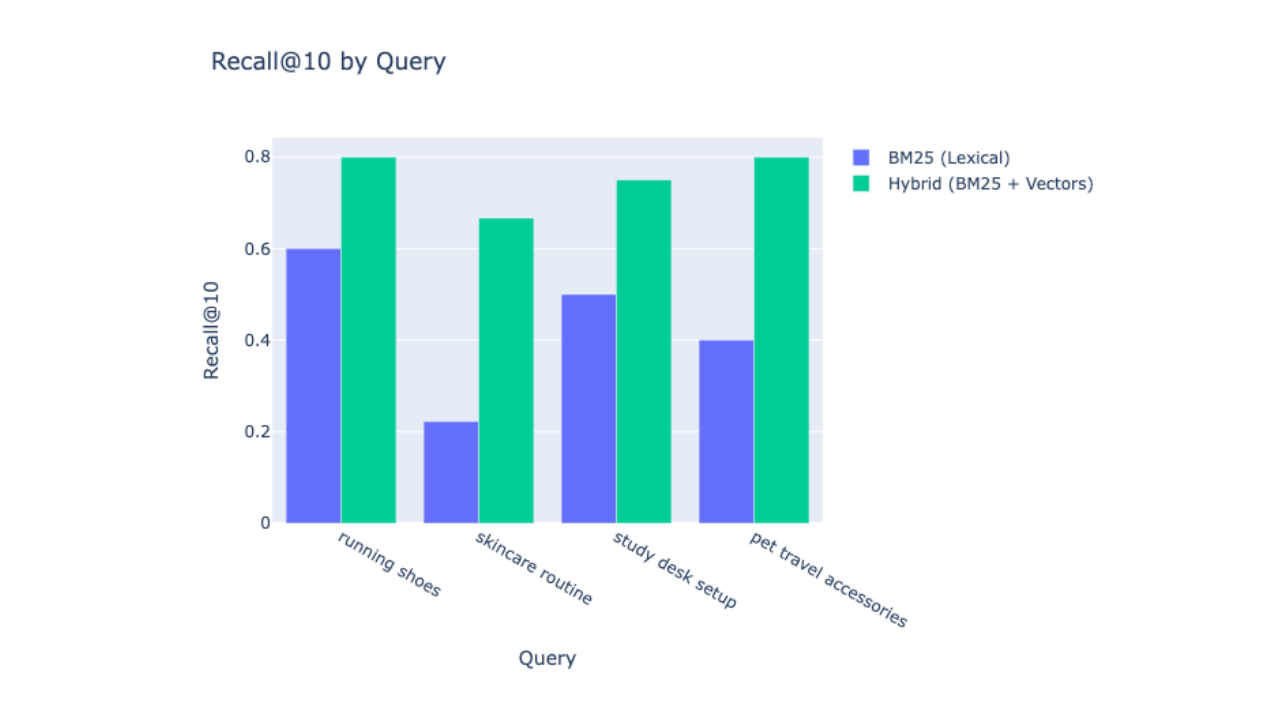
How to measure and improve Elasticsearch search recall: from 0.43 to 0.75 with hybrid search
Learn how to measure and improve search recall in Elasticsearch by combining BM25 lexical search with Jina AI vector embeddings, using the rank_eval API to validate the improvement with real numbers.
Entity resolution with Elasticsearch, part 4: The ultimate challenge
Solving and evaluating entity resolution challenges in a highly diverse “ultimate challenge” dataset designed to prevent shortcuts.
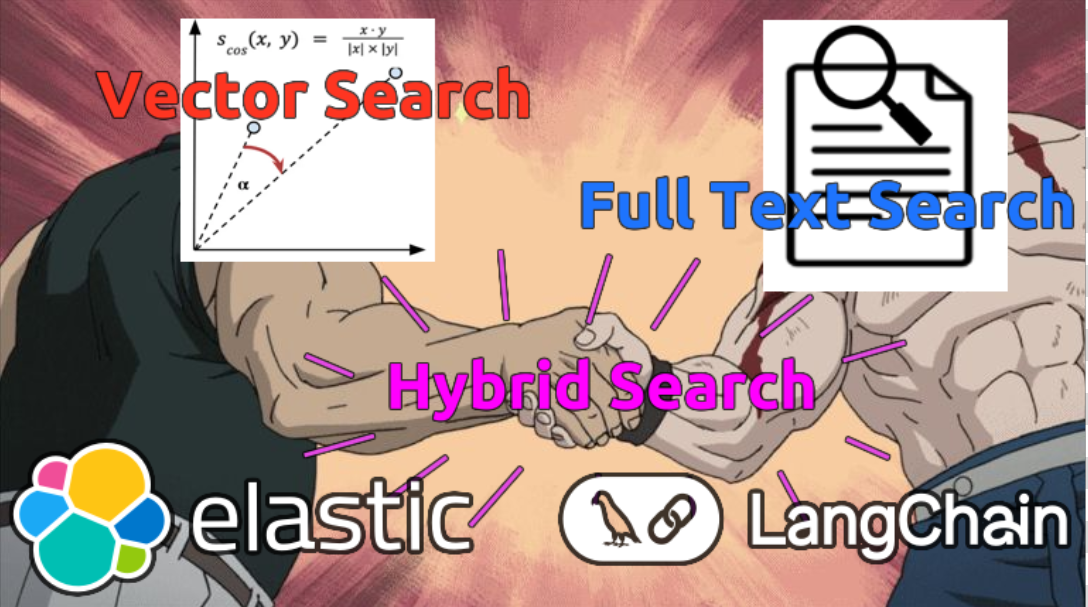
Hybrid search with Java: LangChain4j Elasticsearch integration
Learn how to use hybrid search in LangChain4j via its Elasticsearch integrations, with a complete Java example.