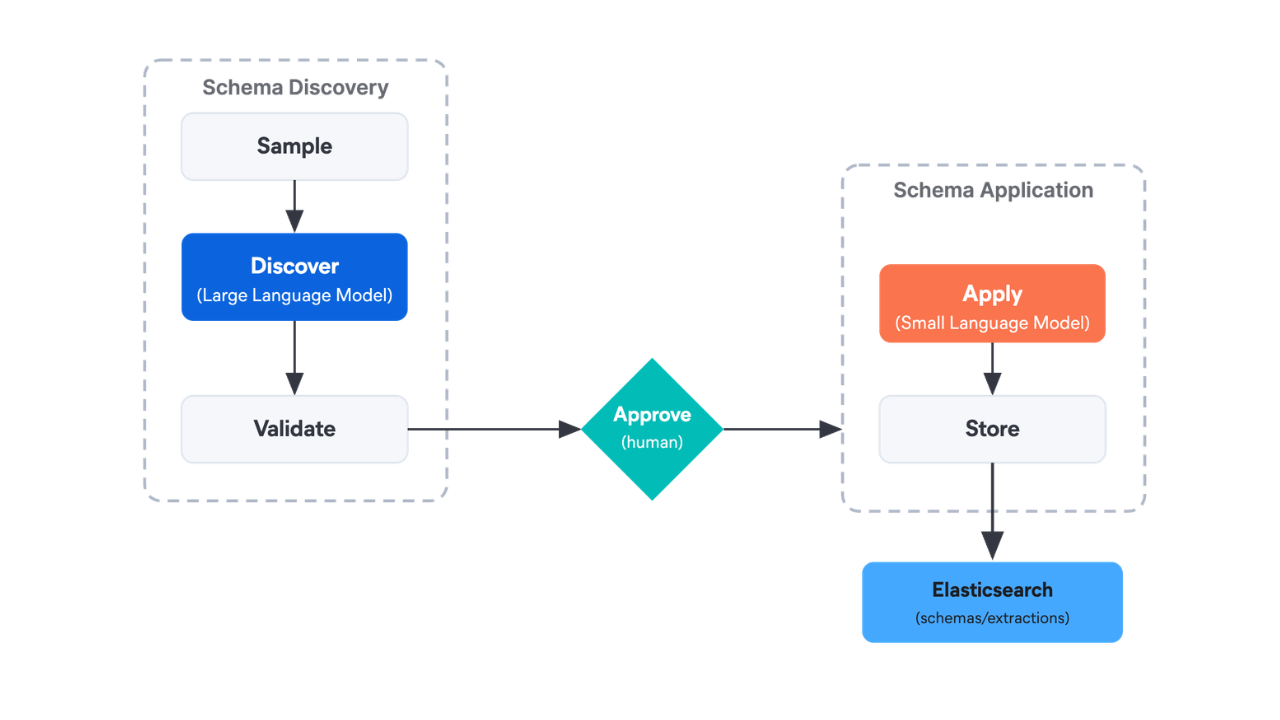
Agentic workflows in Elasticsearch: pause an AI agent for human approval, resume 72 hours later
Build AI agent orchestration where the workflow waits for a human approval and then executes the fix on its own, with nothing extra to provision and the whole decision trail queryable in Elasticsearch.
Agent Builder is available now GA. Get started with an Elastic Cloud Trial, and check out the documentation for Agent Builder here.
An AI agent receives a question and processes it within seconds. The agent responds before the session expires. That model works well for question and answer or code generation. And it works well for point-in-time analysis. But what happens when the agent needs to wait for a human to approve something and that human is in a meeting or dealing with another incident? The session expires and context is lost. The work starts over from scratch.
Elasticsearch Workflows solves this with a persistent execution state. A workflow can pause at a human approval gate for days and resume exactly where it left off. Every decision is persisted in Elasticsearch as searchable data.
In this article, we’ll build this in practice with a real scenario: Documents that failed during ingestion get stuck in a data stream’s failure store.
In this scenario, every step is reproducible. By the end, you’ll have an end-to-end workflow triggered by alerts, with pre-execution approval, automatic remediation, post-execution verification, and a rejection-and-revision path.
What you’ll learn
We’ll cover how to:
Use the failure store to capture and remediate documents that failed ingestion.
Build a long-running workflow with structured and binary approval gates using
waitForInputandwaitForApproval.Invoke Elastic Agent Builder AI agents automatically after human approval.
Trigger workflows automatically from alerting rules.
Handle approval and rejection paths (real human-in-the-loop, not just a checkbox).
What’s a long-running AI agent?
The difference between a session-bound agent and a long-running agent is the nature of the work rather than the speed of the large language model (LLM).
A session-bound agent lives within a session: It receives a question and processes it. Then it responds to the question. If the process dies, the context dies with it.
Operational processes, like data remediation or infrastructure provisioning, or like change review, are different. The processing itself is fast. What takes time are human decisions at unpredictable moments. The person who needs to approve a reindex might be handling an incident or in a different time zone. Or they may simply be at lunch. Long-running agents handle these breaks in workflow by assembling separate infrastructure: a database to store execution state, a server for the orchestrator, a UI for approvals, and integrations for notifications.
Elasticsearch Workflows runs where the data already lives. The workflow's long-term execution state is persisted in Elasticsearch, surviving restarts and waiting days between steps. AI agents come from Agent Builder and maintain a session only for the duration of each step, such as when the step ends or when the session ends. The workflow holds the context that spans across steps and days, and alerts come from the same rules already monitoring your data. The approval UI is in Kibana, and there’s no additional infrastructure to provision.
The workflow's internal execution state is managed by Kibana. The remediation-runs index is the audit trail that the workflow itself writes and that you can query like any other Elasticsearch index.
What’s the Elasticsearch failure store?
When Elasticsearch receives a document it cannot index, it has two options: Reject the document with an error, or store it somewhere safe for later analysis. The failure store is that second option.
Imagine a logs-demo-app data stream with the price field mapped as float. If the source application sends "price": "N/A" instead of a number, Elasticsearch cannot index the document. With the failure store enabled, it’s redirected to a dedicated index within the data stream itself rather than losing that document.
Documents in the failure store preserve the original content and include information about the error, including the exception type, the message, the pipeline and processor that failed, and even the stack trace. You can query the failure store using the data_stream::failures syntax.
A typical document looks like this:
{
  "@timestamp": "2026-07-16T14:45:02.111Z",
  "document": {
    "id": "AZ9rY09teEMlWkReFa9e",
    "index": "logs-demo-app",
    "source": {
      "user_id": "u-test-1",
      "price": "INVALID",
      "message": "Order failed"
    }
  },
  "error": {
    "type": "document_parsing_exception",
    "message": "failed to parse field [price] of type [float]"
  }
}
The document.source field contains the original document that failed, and the error field describes what went wrong. This is exactly the structure that the failure-analyst agent will read to diagnose the problem.
But the documents remain stuck there. Someone needs to diagnose the problem and fix the pipeline or mapping. They also need to reindex the documents back into the data stream. This is exactly the kind of work that combines AI automation with human approval, and it’s what we’re going to build.
How the AI agent orchestration works, from alert to resolution
The workflow connects four building blocks: an alerting rule, two AI agents, human approval gates, and an audit index. The diagram below shows how these components interact.
The alerting rule monitors logs-demo-app::failures every minute. When it finds documents written within the previous five minutes, it starts a workflow execution.
The workflow first runs read_failures to retrieve the failed documents. It then passes them to the failure-analyst agent through the diagnose step. The agent inspects the destination mapping and identifies the root cause. It then produces a structured remediation plan without making any changes.
The workflow records this plan in the remediation-runs index with the status awaiting_fix_approval and pauses at Gate 1.
Gate 1 uses waitForInput, a structured form that collects the reviewer's decision and optional notes. While the workflow waits, its state remains persisted in Elasticsearch. No agent session or polling loop needs to remain active, which means that the gate can wait for hours or days without continuously consuming compute resources.
If the reviewer approves the plan, the workflow invokes the remediation-executor agent through the execute_fix step. The agent calls the execute-failure-store-fix skill and creates the ingest pipeline. It also performs the bounded reindex and returns a detailed execution report.
Gate 2 appears only after the execution finishes. It uses waitForApproval to present the agent's report and asks the reviewer to choose between Yes, mark as resolved and No, escalate. The workflow then records the final outcome in remediation-runs and includes the complete report in agent_report.
If the reviewer rejects the initial plan at Gate 1, the workflow sends the diagnosis and the reviewer's feedback back to the failure-analyst agent, which then produces a revised plan that’s presented at Gate 1b. If approved, the revised plan follows the same automatic execution and verification path. If the plan is rejected again, the workflow records the case as fix_rejected and ends without applying any changes.
The remediation-runs index records the diagnosis, revision requests, revised plans, execution reports, and terminal outcomes as searchable audit documents. The shared workflow execution_id correlates records belonging to the same remediation run.
Production consideration: Exception-based verification
The diagram above shows the deliberately conservative implementation used in this tutorial: Every completed remediation pauses at Gate 2, including executions that appear fully successful. This makes the human-verification mechanism explicit and may be appropriate for low-volume or high-risk environments, but it can create review fatigue at scale. A production extension would add a deterministic verification step after execution. When the expected documents are present in the destination and the reindex reports no failures or policy-defined errors, the workflow can record resolved automatically. Only partial, failed, or ambiguous outcomes should pause at Gate 2 for site reliability engineering (SRE) review and possible escalation.
The following sections walk through each part: the data stream setup, the agents and skills, the alerting rule, and the workflow.
Prerequisites
To follow this tutorial, you’ll need:
An Elastic Cloud Serverless project or an Elastic Stack 9.4+ deployment.
Agent Builder (generally available [GA] on Elasticsearch projects, enabled by default).
The following environment variables configured:
export ES_URL="https://<your-project>.es.<region>.gcp.elastic.cloud:443"
export ES_API_KEY="<your-api-key>"
export KIBANA_ENDPOINT="https://<your-project>.kb.<region>.gcp.elastic.cloud"
Setting up a data stream with the failure store enabled
All code in this tutorial, including the workflow YAML, setup scripts, and agent instructions, is available in this repository.
Start by getting the code from the repository:
# Clone the repository without checking out all files
git clone --filter=blob:none --sparse https://github.com/elastic/elasticsearch-labs.git
cd elasticsearch-labs

# Check out only this companion folder
git sparse-checkout set supporting-blog-content/ai-agent-orchestration-human-approval-workflow
cd supporting-blog-content/ai-agent-orchestration-human-approval-workflow
Then run the setup script:
./scripts/01-setup-failure-store.shThe script prepares the test environment: It removes previous test resources, creates a failure-store-enabled index template, ingests three valid baseline documents, initializes the failure store, and creates the remediation-runs audit index. The price field is mapped as float with ignore_malformed: false ; nonnumeric values generate a parsing error and get redirected to the failure store instead of being silently dropped. The data stream itself is created automatically when the first document is indexed.
The failure store is enabled at the index template level, not on the data stream directly. The template includes a data_stream_options block that tells Elasticsearch to activate the failure store for any data stream created from that template:
"data_stream_options": {
  "failure_store": {
    "enabled": true
  }
}
The data stream is created automatically upon the first ingestion request, inheriting the failure store configuration from the index template. From that point on, any document that cannot be indexed is redirected to the failure store instead of being rejected with an indexing error.
The script also ingests three valid documents with numeric price values. These documents establish the healthy baseline: The data stream exists and contains valid data before any ingestion failures occur.
After the 01-setup-failure-store.sh script completes, the environment is ready:
logs-demo-app           → 3 valid documents
logs-demo-app::failures → 0 documents (empty, index initialized)
remediation-runs        → created with explicit keyword mappings
The invalid documents that trigger the alerting rule and start the workflow are ingested later, when you run 02-trigger-test.sh in the testing section. This sequence shows a realistic failure scenario: The data stream is operating normally with valid data, and then an upstream change causes malformed documents to arrive.
Importing the agents and skills into Agent Builder
Run the restore script to import the two agents and two skills, along with the workflow into your Kibana instance:
pip install requests python-dotenv
python3 scripts/restore.py
Expected output:
Restoring skills
  created  failure-store-remediation-planner
  created  execute-failure-store-fix
  Skills: created=2, updated=0

Restoring agents
  created  failure-analyst
  created  remediation-executor
  Agents: created=2, updated=0

Restoring workflow
  imported failure_store_remediation

Restore completed successfully
Running the script again updates existing components without creating duplicates.
The AI agents that diagnose and execute the fix
After running the restore script, two agents will be available in Agent Builder: one to diagnose failures and another to apply approved fixes. In Kibana, go to Agent Builder and verify that both agents and their associated skills were created correctly.
failure-analyst, the read-only diagnosis agent
This agent reads failed documents from the failure store and inspects the destination mapping. It produces a structured remediation plan that includes an ingest pipeline definition and bounded replay instructions. The plan also includes a risk assessment. The agent doesn’t execute the proposed remediation.
The agent instructions establish its objective and read-only boundary. Key instructions include:
## Description

Analyzes failed documents from the failure store, identifies root causes, and proposes remediation pipelines.

## Instructions

# Role

You are a cautious Elasticsearch data quality analyst specializing in data
stream failure stores.

# Goal

Analyze a batch of related failure-store documents and produce a safe,
evidence-based remediation plan for human review.

Do not execute any changes.

# Required approach

- Identify the common root cause and the affected document pattern.
- Propose the smallest bounded remediation that addresses the demonstrated failure.
- Do not propose an executable remediation when required context is missing.
- Do not create pipelines, change mappings, update templates, run reindex,
  or perform any write operation.

...
Its associated failure-store-remediation-planner skill provides the specialized rules used to construct a safe replay. For example:
...

- A remediation pipeline that replays indexing or mapping failures from a failure store must use `recover_failure_document` as its first processor.
- For a small human-reviewed batch, filter the reindex source using the exact failure-store document `_id` values supplied in the input.
- Mapping changes, template changes, failure-store deletion, and upstream application changes must be listed only as manual follow-up recommendations.

...
The response contract is also constrained so that the workflow can consume the plan reliably:
Return exactly one JSON object and no additional explanatory text.
Do not use Markdown code fences, preambles, summaries, or attachments.
Together, the agent instructions and skill allow failure-analyst to produce an actionable but bounded remediation plan while leaving execution under the control of the workflow and its human approval gate.
remediation-executor, the agent that applies the approved fix
The workflow invokes this agent after the remediation plan has been approved at Gate 1. Unlike the first agent, remediation-executor is allowed to perform the write operations required to apply the approved remediation.
Its agent instructions intentionally keep this role focused on immediate execution:
## Description
Executes Elasticsearch operations: creates pipelines and runs reindex.

## Instructions
You execute Elasticsearch remediation operations.

When asked to run a remediation, invoke the skill
"execute-failure-store-fix" directly and immediately.

Do not ask for confirmation. Do not ask clarifying questions.

After the skill completes, write a plain-text summary as your final message.
Include: whether the pipeline was created, how many documents were matched,
how many were successfully reindexed, and how many failed. This message is
captured by the workflow and shown to the human reviewer.
The associated execute-failure-store-fix skill defines how the approved plan is retrieved and executed. Key instructions include:
## Name

execute-failure-store-fix

## Description

1. The prompt will include a "Workflow execution ID". Use it to search the
   remediation-runs index for the approved plan for this specific execution.

2. Determine which field contains the remediation plan:
   - If status is "awaiting_fix_approval", read the "diagnosis" field.
   - If status is "awaiting_fix_approval_v2", read the
     "revised_diagnosis" field.

3. From that JSON object, extract:
   - remediation_pipeline.pipeline_id
   - remediation_pipeline.pipeline_definition
   - remediation_pipeline.reindex_request
   - affected_docs.data_stream

4. Create the ingest pipeline in Elasticsearch using the extracted
   pipeline_definition.

5. Execute the reindex_request exactly as specified in the approved plan.
   Do not substitute or hardcode the destination — use
   affected_docs.data_stream from the approved plan.

6. Report how many documents were matched, successfully reindexed,
   and failed..
The skill searches by both execution_id and approval status. This ensures that the executor retrieves the plan approved for the current workflow execution rather than an unrelated remediation run. The status determines whether it uses the original diagnosis or the revised_diagnosis produced during the revision path.
This separation gives the two agents distinct responsibilities: failure-analyst investigates the failure and proposes a bounded plan without making changes, while remediation-executor applies the selected plan only after the workflow has completed the required human approval step.
The setup scripts import the complete agent instructions and skill definitions. The excerpts above highlight the instructions most relevant to understanding the responsibilities and behavior of each agent. The complete definitions are available in backup/save_agents.json and backup/save_skills.json in the repository.
After verifying that the agents and their skills have been imported correctly, the next step is to configure the alerting rule that detects new documents in the failure store and starts the remediation workflow.
How do I trigger a workflow from an Elasticsearch alert
The remediation process starts with an Elasticsearch alerting rule that monitors the failure store and starts the workflow when new failures are detected. Because the restore.py script has already imported and enabled failure_store_remediation, you can connect the workflow while creating the rule.
Creating the alerting rule that watches the failure store
The rule checks the failure store every minute and creates an alert when it finds documents written within the configured five-minute time window.
Go to Management → Rules → Create rule.
Select Elasticsearch query.
Configure:
Query type:
ES|QL.Query:
FROM logs-demo-app::failures
| WHERE @timestamp > NOW() - 5 minutes
| STATS failure_count = COUNT(*)
| WHERE failure_count > 0
Select time field:
@timestamp.Select alert group: Create an alert if matches are found.
Time window:
5 minutes.Check every:
1 minute.In the Actions section, click Add action → Workflows.
Select the
failure_store_remediationworkflow.Under Run workflow for, select New alerts.
Set Action frequency to Run per alert.
Save and enable the rule.
Whenever the rule creates a new alert, it starts one failure_store_remediation workflow execution for that alert. The failure store is still empty at this stage; the invalid documents are ingested later by 02-trigger-test.sh.
With the alert trigger configured, let’s examine the workflow that performs the diagnosis, approval, remediation, and verification steps.
Building the agentic workflow, step by step
At this point, the workflow has already been created in Kibana by the restore.py script executed earlier. To understand how the workflow operates, we’ll examine it incrementally, using relevant YAML excerpts to explain the role of each step in the remediation process. The complete workflow definition is available in the tutorial repository.
Declaring the alert trigger and the 7-day timeout
The workflow declares an alert trigger that allows it to be initiated by the alerting rule created earlier.
version: "1"
name: failure_store_remediation
description: >
  Long-running workflow that remediates failed documents in a data stream's
  failure store. Triggered by an alerting rule when failures are detected.
  An AI agent diagnoses the root cause and proposes a fix. After human
  approval, the remediation-executor agent runs the fix automatically,
  then pauses for verification.
enabled: true
tags: [failure-store, remediation, agentic]
settings:
  timeout: 7d

triggers:
  - type: alert
Two details are important here. First, the timeout: 7d defines that the workflow can remain active for up to seven days. We set this explicitly because the workflow will pause at human approval gates that may take hours or days to respond.
Second, declaring type: alert makes the workflow available to alerting. The workflow action configured in the rule establishes the connection between the alert and failure_store_remediation.
Reading failed documents from the failure store
The workflow begins by retrieving failed documents using the ::failures syntax:
steps:
  - name: read_failures
    type: elasticsearch.search
    with:
      index: "logs-demo-app::failures"
query:
	    range:
		"@timestamp":
		gte: "now-5m"
		lte: "now"
size: 50
sort:
        - "@timestamp": "desc"
The range query limits the search to failure-store documents created during the same five-minute window monitored by the alerting rule. Within that window, size: 50 bounds the batch to the 50 most recent matching documents. For larger volumes, use search_after or pagination.
How the AI agent diagnoses the root cause
The next step sends the failed documents to the failure-analyst agent:
  - name: diagnose
    type: ai.agent
    agent-id: failure-analyst
    timeout: 300s
with:
      message: |
        Analyze these failed documents from the "logs-demo-app" failure store.

        Failed documents:
        {{ steps.read_failures.output.hits.hits | json }}

        Identify the root cause, classify the failure type, propose a concrete
        fix with ingest pipeline processors, generate a remediation pipeline to
        reindex the failed documents, and assess the risk.

        YOUR RESPONSE MUST BE A SINGLE JSON OBJECT ONLY.
  Do not write any explanation, preamble, markdown, or commentary.
  Start your response with { and end with }.
  Use exactly these top-level keys: root_cause, failure_type, affected_docs,
  proposed_fix, remediation_pipeline, risk_assessment.
The {{ steps.read_failures.output.hits.hits | json }} template injects the documents retrieved in the previous step into the agent's prompt. The agent analyzes the error patterns and identifies that the price field received string values where floating-point values were expected. It then proposes a remediation pipeline.
The agent's output arrives in steps.diagnose.output.message as a single JSON object. The exact diagnosis, proposed remediation, pipeline definition, and reindex request may vary between executions because they’re generated by the AI agent from the failures it receives. In our tests, the agent consistently identified the root cause and generated working remediation pipelines.
Despite this natural variability, the response contract remains fixed so that the workflow can persist the plan and the executor can reliably extract its executable components. The response always contains the six required top-level keys: root_cause, failure_type, affected_docs, proposed_fix, remediation_pipeline, and risk_assessment.
Recording the diagnosis for audit
Before requesting human approval, the workflow writes the diagnosis and proposed remediation plan to the remediation-runs index. This creates a durable audit record that can later be retrieved by the remediation-executor if the plan is approved:
- name: record_diagnosis
  type: elasticsearch.index
  with:
    index: remediation-runs
    document:
      "@timestamp": "{{ now | date_to_xmlschema }}"
      execution_id: "{{ execution.id }}"
      data_stream: "logs-demo-app"
      triggered_by_rule: "{{ event.rule.name }}"
      failure_count: "{{ steps.read_failures.output.hits.hits | size }}"
      failure_count_total: "{{ steps.read_failures.output.hits.total.value }}"
      diagnosis: "{{ steps.diagnose.output.message }}"
      status: awaiting_fix_approval
The execution_id correlates the diagnosis with the current workflow execution. The record stores both the number of failure documents loaded into the bounded batch and the total number of failures matching the query. After human approval, the executor uses the execution_id together with the approval status to retrieve the correct remediation plan.
How do human approval gates work in Elasticsearch Workflows?
The workflow uses two kinds of pause steps for different kinds of human decisions. Gate 1 uses waitForInput to collect a structured approval decision and reviewer feedback. Gate 2 uses waitForApproval because verification requires a binary choice: Mark the case as resolved, or escalate it.
| Gate 1 | Gate 1b | Gate 2 |
Step name |
|
| gate_verify (approved path) / gate_verify_v2 (revised path) |
Step type |
|
|
|
Timeout | 72h | 72h | 72h |
Decision shape | Approve or reject, plus notes | Approve or reject, plus notes | Yes, mark as resolved / No, escalate |
Presents | AI diagnosis and proposed plan | Revised plan | remediation-executor report |
Appears | Always | Only after Gate 1 rejection | Only after execution completes |
Gate 1 is defined like this:
- name: gate_fix
  type: waitForInput
  timeout: 72h
  with:
    message: |
      GATE 1/2 - Fix Approval

      Data stream: logs-demo-app
      Failed documents: {{ steps.read_failures.output.hits.total.value }}

      The AI agent has diagnosed the failures. Review the full diagnosis
      in the 'diagnose' step output above, then approve or reject.
    schema:
      type: object
      properties:
        approved:
          type: boolean
          title: "Approve fix"
          default: true
        notes:
          type: string
          title: "Feedback (required if rejecting)"
When the workflow reaches this step, execution pauses, and its state is persisted in Elasticsearch. No agent session or polling loop needs to remain active while the gate waits. Every gate accepts a response for up to 72 hours, subject to the workflow's overall seven-day timeout.
The schema collects an approval decision and an optional notes field. When the proposal is rejected, the workflow passes the notes to the failure-analyst agent as context for revising the remediation plan. The testing section shows the approval and rejection payloads at the point where each is submitted.
What happens when the reviewer approves or rejects the plan
When Gate 1 is submitted, route_fix resumes the workflow without rerunning the completed steps. The simplified excerpt below shows the first transition in each branch. (The complete executable YAML is available in the tutorial repository.)
- name: route_fix
  type: if
  condition: "steps.gate_fix.output.response.approved: true"
  steps:
    - name: execute_fix
      type: ai.agent
      agent-id: remediation-executor
      timeout: 300s
      with:
        message: |
          Run remediation for the "logs-demo-app" failure store.

          Workflow execution ID: {{ execution.id }}

          The fix has been approved by a human reviewer. Execute the skill
          'execute-failure-store-fix' immediately without asking for confirmation.
Approval sends the current workflow execution_id to the remediation-executor. The executor uses this identifier together with the approval status to retrieve the remediation plan associated with this specific execution before applying it and continuing to Gate 2.
If Gate 1 is rejected, the workflow stores the reviewer’s feedback and asks the failure-analyst agent to produce a revised proposal. Gate 1b (gate_fix_revised) then presents that proposal for another human decision. When the revised plan is approved, execute_fix_revised sends the same workflow execution ID to the executor:
- name: execute_fix_revised
  type: ai.agent
  agent-id: remediation-executor
  timeout: 300s
  with:
    message: |
      Run the revised remediation for the "logs-demo-app" failure store.

      Workflow execution ID: {{ execution.id }}

      The revised fix has been approved by a human reviewer. Execute the skill
      'execute-failure-store-fix' immediately without asking for confirmation.
The executor uses the approval status to determine which plan belongs to the current path: the original diagnosis associated with awaiting_fix_approval or the revised_diagnosis associated with awaiting_fix_approval_v2. Both paths then continue to Gate 2. If the revised proposal is rejected at Gate 1b, the workflow records fix_rejected and ends without applying any changes.
Verifying the result at Gate 2 before closing the case
Gate 2 showing the remediation-executor report and waiting for the resolve-or-escalate decision.
Gate 2 is a verification checkpoint. By the time it appears, the remediation-executor agent has already created the ingest pipeline and run the reindex. It has also returned a detailed report. The gate embeds the executor's report, steps.execute_fix.output.message on the approved path, or steps.execute_fix_revised.output.message when the revised plan was executed, and asks the reviewer to select either Yes (mark as resolved) or No (escalate).
Gate 2 uses waitForApproval because the workflow only needs a binary verification decision. The operation details, including the pipeline ID, documents matched and reindexed, version conflicts, failures, and execution errors, come from the remediation-executor agent’s report rather than from fields entered manually by the reviewer.
In our validated execution, the agent created the logs-demo-app-price-remediation pipeline and matched and reindexed all five approved documents. It reported zero version conflicts and zero failures. The logs-demo-app data stream increased from three to eight documents, while the five original records remained in logs-demo-app::failures. This is expected because reindex copies documents; it doesn’t remove them from the failure store.
If the reviewer selects Yes, mark as resolved, route_verify writes a new document to remediation-runs with status resolved and stores the complete agent report in agent_report. If the reviewer selects No, escalate; the workflow writes an escalated record with the same report. The revised path mirrors this through route_verify_v2, producing the same statuses and the same agent_report field.
Gate 2 exists because a technically completed reindex can still produce partial or unexpected results. Escalating instead of automatically marking the remediation as resolved keeps the audit trail honest. Whether to keep this second gate depends on your environment and risk tolerance.
The complete workflow
After reviewing the workflow, remember that the complete code is available in the repository in the failure-store-remediation.yaml file.
The workflow can finish in five ways, depending on the decisions made at Gate 1, Gate 1b, and Gate 2. The diagram below shows how the original and revised remediation paths lead to resolved, escalated, or fix_rejected.
Every terminal outcome is appended to the remediation-runs audit history. Across the workflow paths, the audit records preserve the diagnosis, reviewer feedback when a revision is requested, the executor report, and the terminal outcome.
With the rule and its workflow action already configured, the end-to-end flow is ready to test.
Testing the workflow end to end
With the alerting rule enabled, run the trigger script to ingest five documents with invalid price values and current timestamps:
./scripts/02-trigger-test.shThe rule searches the previous five minutes, so it detects the new failure-store documents during its next evaluation. Go to Workflows → Executions, and open the new execution. Confirm that read_failures, diagnose, and record_diagnosis have completed and that gate_fix is waiting for input.
Approving the fix at Gate 1
At Gate 1, approve the proposed remediation by submitting:
{ "approved": true }The workflow resumes at route_fix and invokes the remediation-executor agent through execute_fix. It pauses at Gate 2 with the execution report.
The following clip shows Gate 1 being approved and the workflow resuming automatically at route_fix and execute_fix.

Before completing Gate 2, verify that the five remediated documents were added to the data stream:
GET logs-demo-app/_countExpected result:
{
  "count": 8
}
The data stream started with three valid documents, so a successful replay increases the total to eight. The original records remain in the failure store because reindex copies documents to the destination rather than removing the source records.
Complete Gate 2 by selecting Yes, mark as resolved or No, escalate. The workflow stores the selected outcome and the execution report in remediation-runs.
Rejecting the plan and reviewing a revised one
To test the rejection path, reset the environment and start another execution:
./scripts/03-reset-full-test-environment.sh --apply
./scripts/01-setup-failure-store.sh
./scripts/02-trigger-test.sh
At Gate 1, reject the proposal with specific feedback:
{
  "approved": false,
  "notes": "The proposed remediation should distinguish numeric strings from non-numeric strings. Convert numeric strings to a float, preserve non-numeric values in price_raw, and remove price only when conversion fails."
}
Although notes is optional in the current schema, provide specific feedback whenever you reject a proposal. The workflow passes this value to the failure-analyst agent when requesting a revised plan.
The workflow records the feedback and asks the agent to revise the proposal. It pauses at Gate 1b. To approve the revised plan, submit:
{
  "approved": true
}
To reject it definitively, submit:
{
  "approved": false,
  "notes": "Explain why the revised proposal should not be executed."
}
Approving the revision sends it through the same execution and Gate 2 verification path described above. Rejecting it records fix_rejected and ends the workflow without applying the remediation.
Conclusion
The pattern built in this tutorial combines three elements: persistent workflow state, specialized AI agents, and human control at the points where judgment matters. The failure-analyst agent diagnoses the problem and proposes a bounded remediation. Gate 1 pauses before any change is made, giving the reviewer control over execution. After approval, the remediation-executor agent applies the fix automatically, and Gate 2 pauses again so the result can be verified before the case is marked as resolved or escalated.
Persistent execution state solves more than the problem of expiring agent sessions. The diagnosis, reviewer feedback, execution report, and final decision are stored as searchable data in Elasticsearch and correlated by the workflow execution_id. This correlation allows the executor to retrieve the plan approved for the current workflow run, even when multiple remediation cases exist in remediation-runs. It also makes it possible to analyze how many remediations were approved on the first attempt and which failure types are most frequently rejected, along with how long approval gates remain open and which cases require escalation.
This workflow pattern also applies to index promotions, mapping changes, enrichment pipeline validation, infrastructure operations, and other processes where automation and human judgment must coexist: Diagnose the problem, pause for approval, execute the approved action automatically, pause for verification, and record the final outcome.
Resources
How helpful was this content?
Related Content
You and your AI agent shouldn't be using curl: Introducing the Elastic CLI and Agent Skills

Trust, but benchmark: How we let an AI agent optimize Elasticsearch
AI root cause analysis in Elastic Agent Builder that cites its evidence
Know your facts: How Elasticsearch AI Indices let agents skip the reading and keep the answer