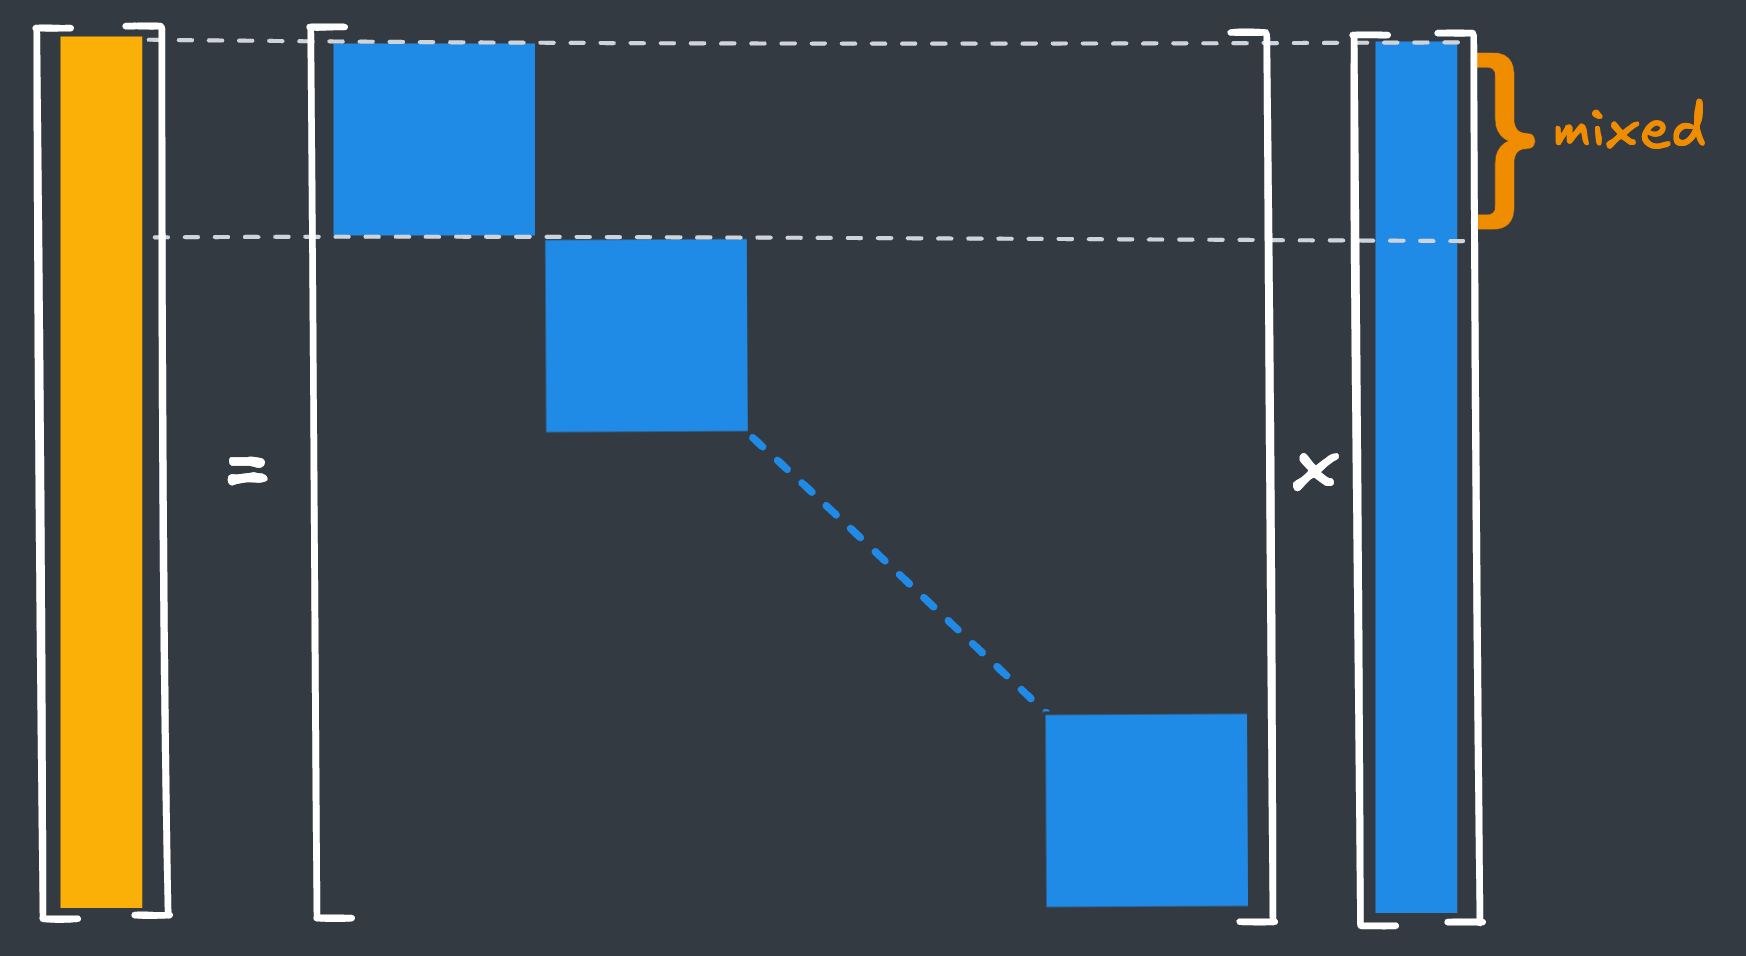
Optimizing scalar quantization with sparse preconditioners
We discuss a sparse preconditioner to apply to vectors which results in more stable quantization performance with respect to data distribution.

Get set, build: Red Hat OpenShift AI applications powered by Elasticsearch vector database
Learn how to use Elasticsearch with the ‘AI Generation’ Validated Pattern to rapidly deploy secure, GitOps-driven RAG applications on Red Hat OpenShift.

Mapping embeddings to Elasticsearch field types: semantic_text, dense_vector, sparse_vector
Discussing how and when to use semantic_text, dense_vector, or sparse_vector, and how they relate to embedding generation.

How to implement Better Binary Quantization (BBQ) into your use case
Explore why you would implement Better Binary Quantization (BBQ) in your use case and how to do it.

Elasticsearch BBQ vs. OpenSearch FAISS: Vector search performance comparison
A performance comparison between Elasticsearch BBQ and OpenSearch FAISS.

Elasticsearch vector database for native grounding in Google Cloud’s Vertex AI Platform
Explore how Elasticsearch, the first third-party native grounding engine for Google Cloud’s Vertex AI, lets you build custom GenAI experiences by grounding Gemini models in enterprise data.
Speeding up merging of HNSW graphs
Explore the work we’ve been doing to reduce the overhead of building multiple HNSW graphs, particularly reducing the cost of merging graphs.
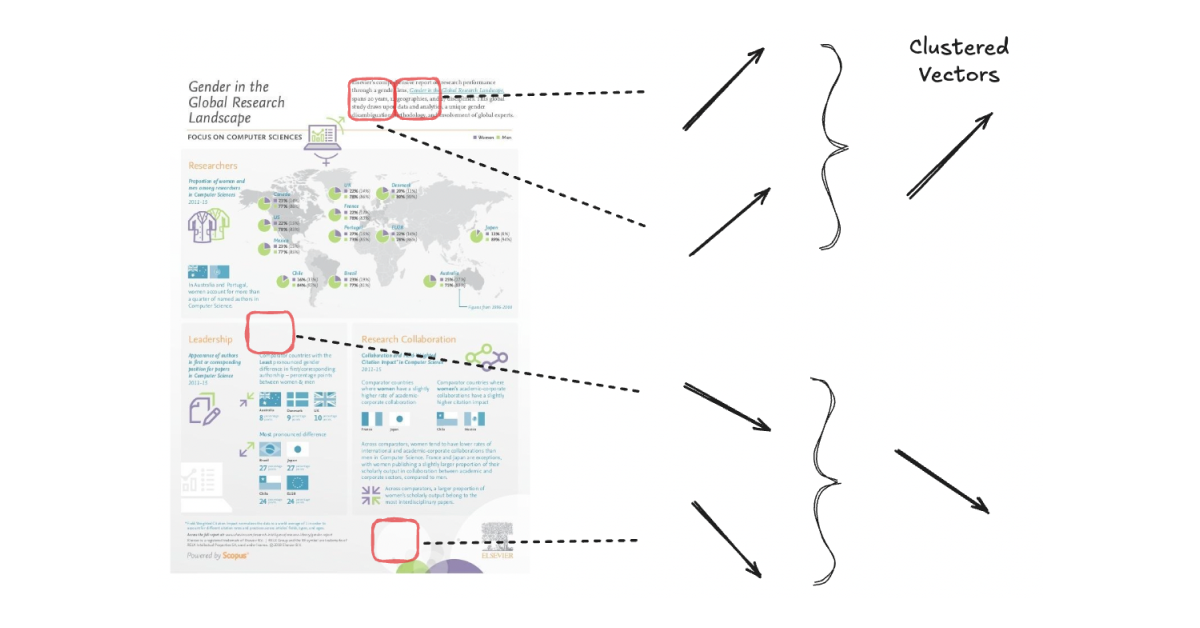
Scaling late interaction models in Elasticsearch - part 2
This article explores techniques for making late interaction vectors ready for large-scale production workloads, such as reducing disk space usage and improving computation efficiency.
Exploring GPU-accelerated vector search in Elasticsearch with NVIDIA: Chapter I
Powered by NVIDIA cuVS, the collaboration looks to provide developers with GPU-acceleration for vector search in Elasticsearch.
Searching complex documents with ColPali - part 1
The article introduces the ColPali model, a late-interaction model that simplifies the process of searching complex documents with images and tables, and discusses its implementation in Elasticsearch.

Semantic text in Elasticsearch: Simpler, better, leaner, stronger
Our latest semantic_text iteration brings a host of improvements. In addition to streamlining representation in _source, benefits include reduced verbosity, more efficient disk utilization, and better integration with other Elasticsearch features. You can now use highlighting to retrieve the chunks most relevant to your query. And perhaps best of all, it is now a generally available (GA) feature!

Unifying Elastic vector database and LLM functions for intelligent query
Leverage LLM functions for query parsing and Elasticsearch search templates to translate complex user requests into structured, schema-based searches for highly accurate results.