
Early termination in HNSW for faster approximate KNN search
Learn how HNSW can be made faster for KNN search, using smart early termination strategies.
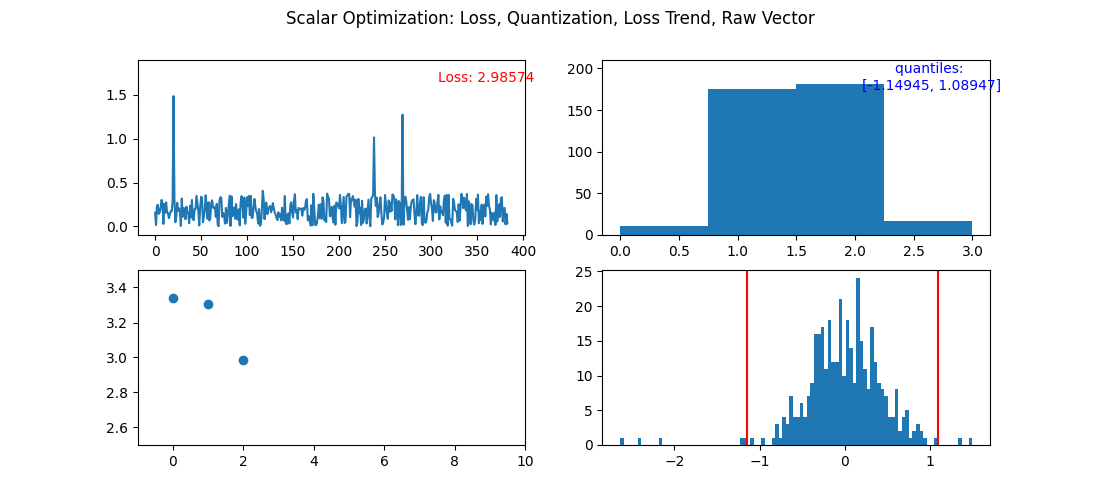
Optimized Scalar Quantization: Improving Better Binary Quantization (BBQ)
Here we explain optimized scalar quantization in Elasticsearch and how we used it to improve Better Binary Quantization (BBQ).

When hybrid search truly shines
Demonstrating when hybrid search is better than lexical or semantic search on their own.

“Hey Care!” - Speech-to-speech assistant powered by Elastic and OpenAI Realtime API
How we built an AI assistant for caregivers based on speech-to-speech interactions using OpenAI and Elasticsearch.

Using Ollama and Go to build a RAG application
Building a RAG application with Go using Ollama to leverage local models.

Agentic RAG with Elasticsearch & Langchain
Discussing Agentic RAG and implementing an agentic flow where the LLM chooses to call an Elastic KB.
How to use Elasticsearch Vector Store Connector for Microsoft Semantic Kernel for AI Agent development
Microsoft Semantic Kernel is a lightweight, open-source development kit that lets you easily build AI agents and integrate the latest AI models into your C#, Python, or Java codebase. With the release of Semantic Kernel Elasticsearch Vector Store Connector, developers using Semantic Kernel for building AI agents can now plugin Elasticsearch as a scalable enterprise-grade vector store while continuing to use Semantic Kernel abstractions.

Smokin' fast BBQ with hardware accelerated SIMD instructions
How we optimized vector comparisons in BBQ with hardware accelerated SIMD (Single Instruction Multiple Data) instructions.

Using Elastic and Apple's OpenELM models for RAG systems
How to deploy and test the Apple's OpenELM models and build a RAG system using Elastic.

RAG made easy with Spring AI + Elasticsearch
Customize your AI chatbot experience with private data. Learn how to build a Retrieval-Augmented Generation (RAG) app with Spring AI and Elasticsearch.

Late chunking in Elasticsearch with Jina Embeddings v2
Using the Jina Embeddings v2 model in Elasticsearch, implementing late chunking, and exploring the pros and cons of long context embeddings models.

Elasticsearch open inference API adds support for IBM watsonx.ai Slate embedding models
How to use IBM watsonx™ Slate text embeddings when building Search AI experiences with Elasticsearch vector database.