Your logs already wrote the alert: Generating ES|QL detection queries in Elasticsearch
On the OpenTelemetry demo, the top generated ES|QL detection query matches 0 documents while the shop is healthy and 676 during a payment outage.
Elasticsearch turns raw logs into structured, searchable data at ingest. Follow the collect and analyze logs tutorial to see it end-to-end. Start a free cloud trial or try Elastic on your local machine now.
Significant Events wrote this ES|QL detection query from the OpenTelemetry demo's own log text. It matches 0 documents while the shop is healthy and 676 once payments start failing.
FROM logs.otel
| WHERE MATCH_PHRASE(body.text, "rpc error: code = Unavailable")
    AND (MATCH_PHRASE(body.text, "connection refused") OR MATCH_PHRASE(body.text, "i/o timeout"))
Every phrase in it came from those logs. Nothing came from a model guessing what an error looks like. The query also links back to the checkout-to-payment dependency it was built from, so the system knows which piece of knowledge it depends on.
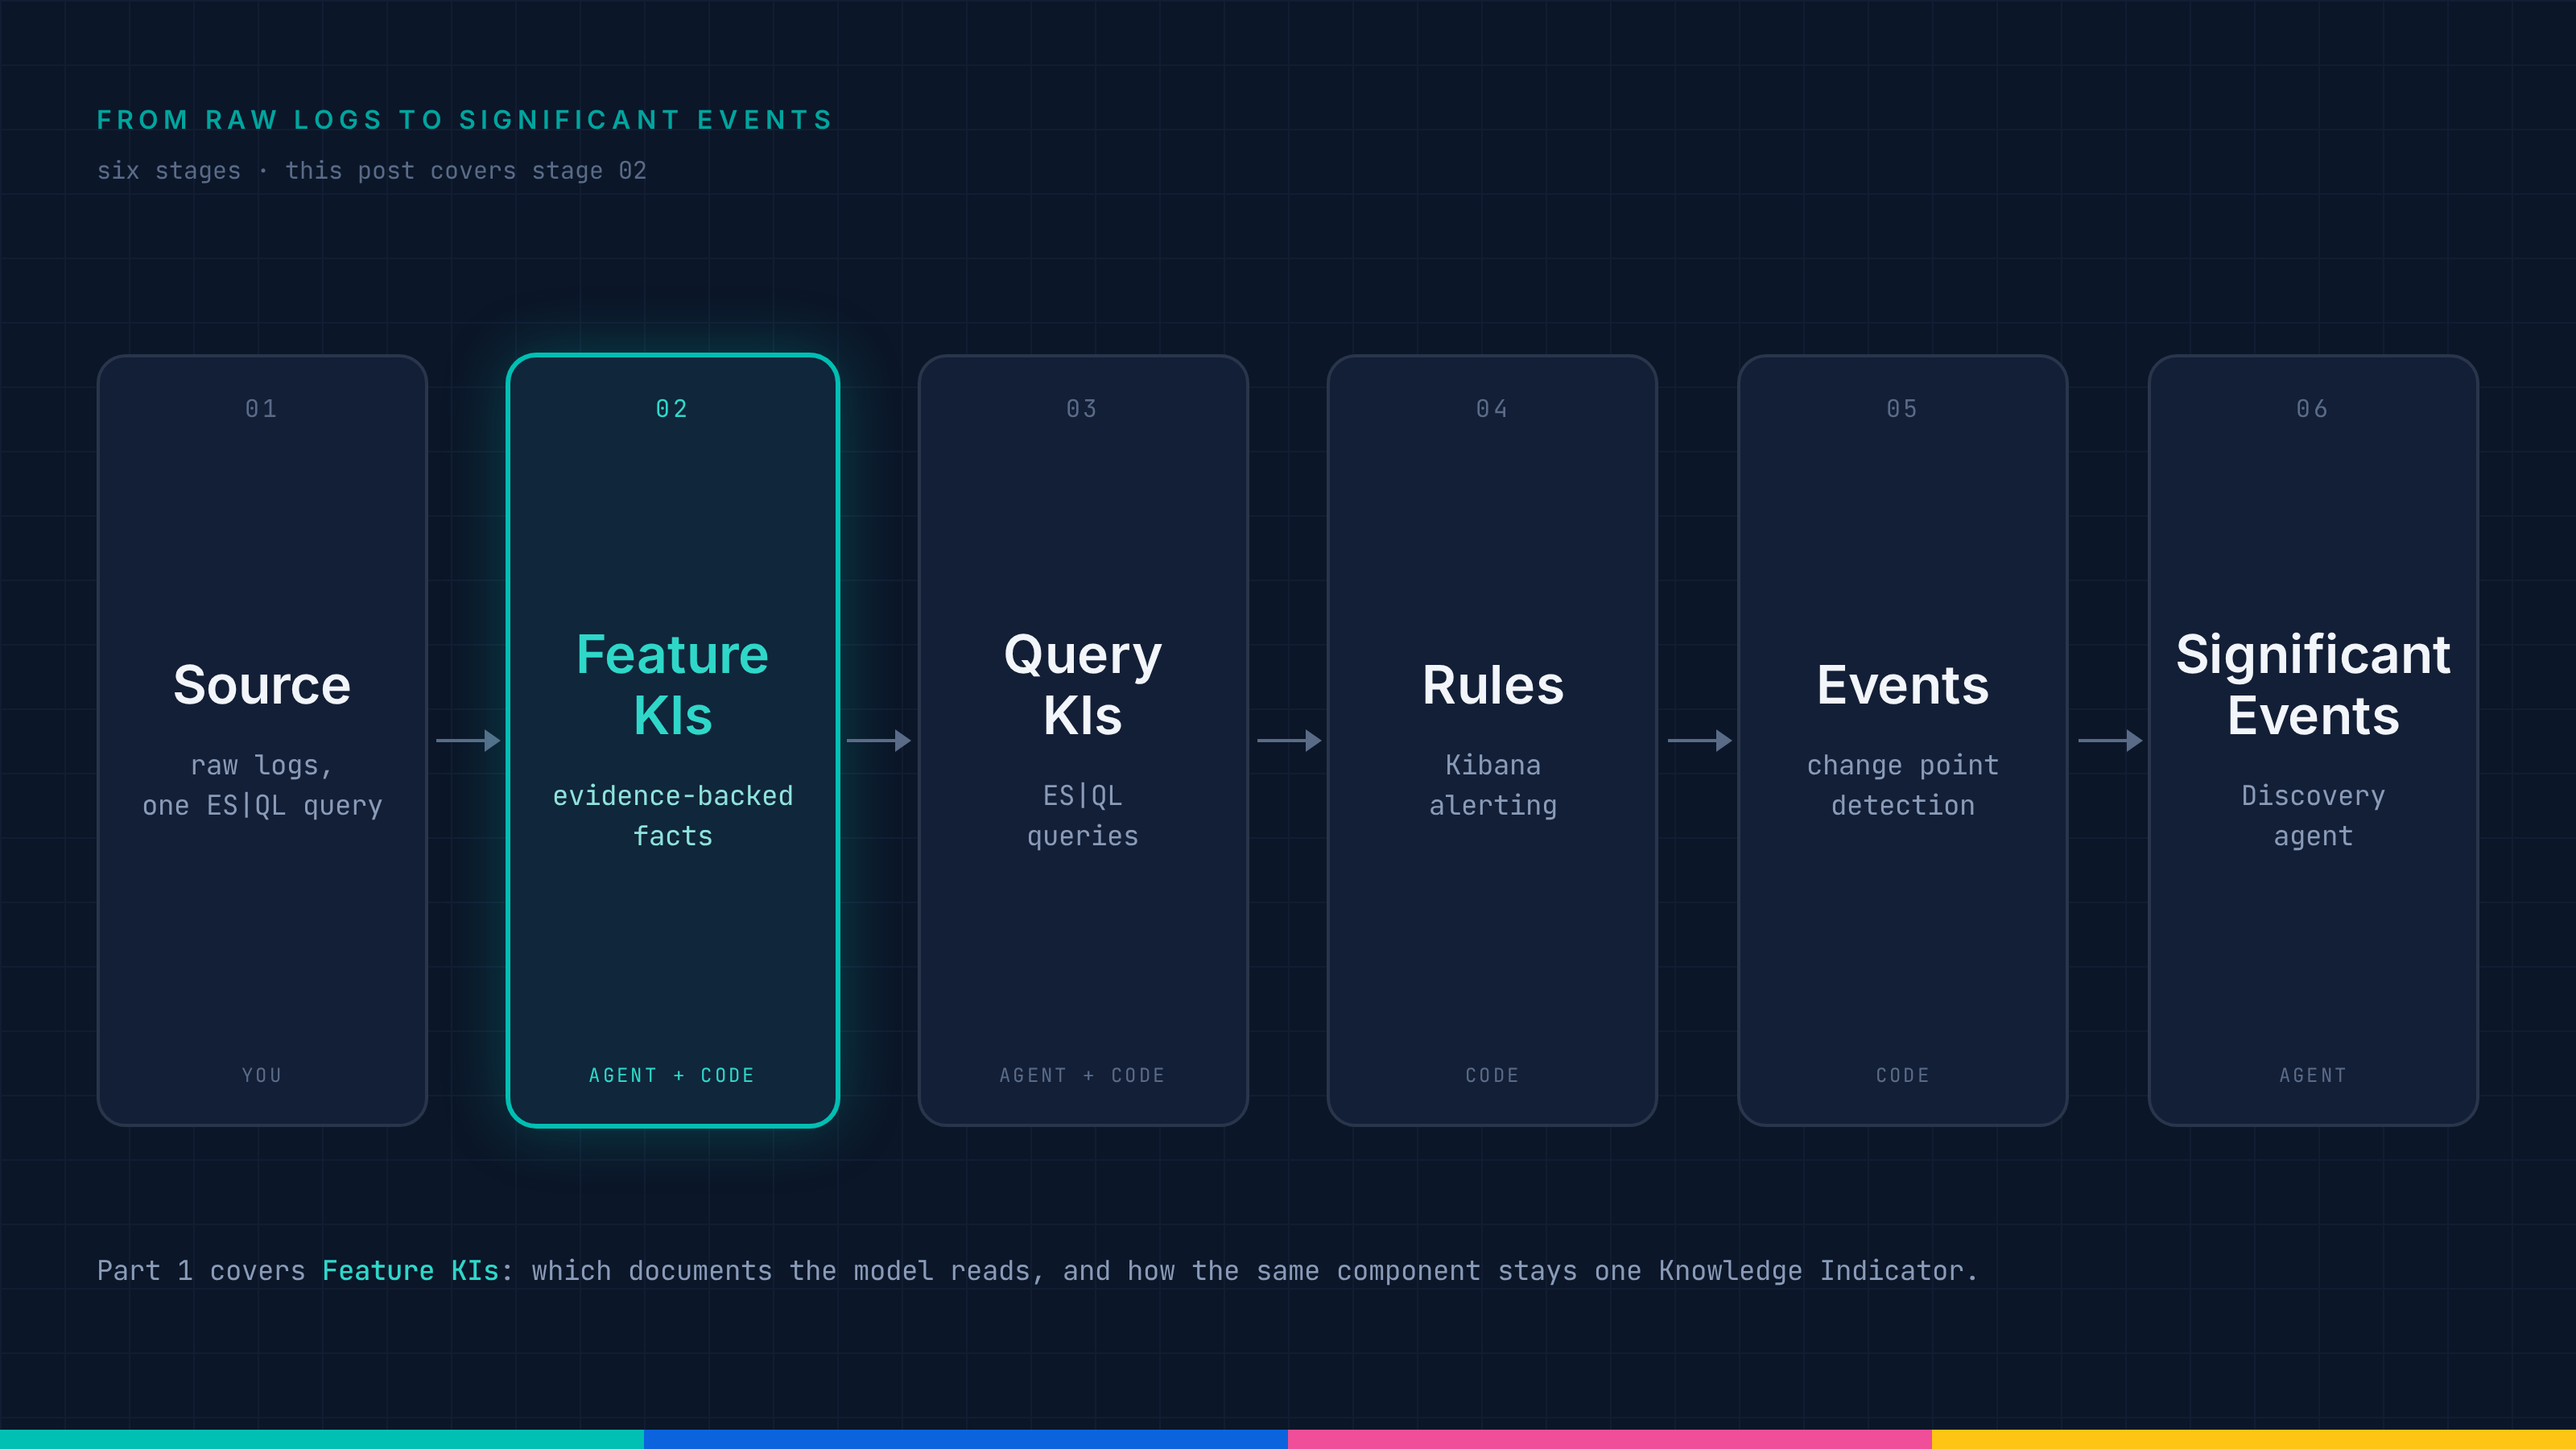
Part 1 built that knowledge. It extracted Knowledge Indicators (KIs), an evidence-backed description of the source drawn from about 100 sampled documents, after showing that the obvious shortcut fails. Point a language model at raw logs and ask for a rule, and you get a generic log.level: error that stays silent through the entire outage.
This post covers the second half. In this capture, 30 KIs became 10 Elasticsearch Query Language (ES|QL) detection queries, four of those were promoted to Kibana alerting rules automatically, and all of them retire when the knowledge behind them stops being observed.
The OpenTelemetry demo runs on Kubernetes and ships its container logs to the stream logs.otel, which the Significant Events source reads from. After a healthy stretch we point checkout at the wrong port for payment and triple the load generator's users, and from then on every order fails at the payment step. Every KI and query below comes from one capture of that scenario.
What a query Knowledge Indicator is: An ES|QL query plus its evidence
Part 1 described feature KIs: the services, dependencies, technologies, infrastructure and schema of a source, each with the evidence it rests on. A query KI is the next layer. It's an ES|QL query plus enough context to judge it, stored next to the features it came from.
Here is the query from the opening as Significant Events stores it, abridged:
{
  "id": "341cdc03-27dd-4742-b77d-27e6d6f5a1ac",
  "type": "match",
  "title": "Payment Service gRPC Unavailable (connection refused or i/o timeout)",
  "category": "error",
  "severity_score": 85,
  "esql": {
    "query": "FROM $.nightshift.sources.default.logs-otel | WHERE MATCH_PHRASE(body.text, \"rpc error: code = Unavailable\") AND (MATCH_PHRASE(body.text, \"connection refused\") OR MATCH_PHRASE(body.text, \"i/o timeout\"))"
  },
  "evidence": [
    "body.text: \"rpc error: code = Unavailable desc = connection error: desc = \\\"transport: Error while dialing: dial tcp 10.104.231.249:9999: connect: connection refused\\\"\"",
    "body.text: \"dial tcp 10.104.231.249:9999: i/o timeout\"",
    "Feature: @grpc/grpc-js library in frontend service"
  ],
  "features": [
    { "id": "frontend-payment-grpc" },
    { "id": "checkout-payment-grpc" },
    { "id": "grpc-js" }
  ]
}
FROM points at the source's ES|QL view rather than the stream. The generator writes FROM logs and the system rewrites it, so a query always runs over exactly what the source defines. The opening example shows the stream name to keep it readable. evidence quotes the log lines the query is built on. features lists the feature KIs it depends on, and that list later decides when the query retires.
Those feature IDs are the stable identities Part 1 built. Extraction runs again and again as new logs arrive, and each run recognizes checkout-payment-grpc as the same dependency it saw before. The link from a query to its features therefore holds across runs, and a query written today still points at the right piece of knowledge next week.
What the ES|QL query generator reads before writing a query
Query generation is an Elastic Agent Builder agent, started by a managed workflow right after feature extraction. Its starting message is short: the source's name, its description, and up to 50 queries that already exist for it. Everything else it fetches.
It has two tools that matter. The first returns the source's KIs. Those are the feature KIs from Part 1, each with its evidence lines, plus two of the three computed ones. dataset_analysis holds the field inventory with value distributions, and log_patterns holds the categorized message patterns with a real sample of each. The generator never receives a batch of raw documents. The only log text it reads is what the KIs carry.
The second tool validates a batch of candidate queries, and it's the only way to finish. The agent writes a batch, submits it, reads the errors, fixes the queries that failed and submits again. The run ends when every query in the batch passes.
Validation checks every query against the live source before anything is stored:
- It strips links to KIs this source doesn't have.
- It rejects any query with no links left, so every query links to at least one known feature.
- It rejects exact duplicates of stored queries.
- It executes each query against the source and reports syntax errors, unknown fields and type conflicts back to the agent, which fixes them in the next round.
Only queries that execute cleanly reach storage.
How each ES|QL predicate traces back to a Knowledge Indicator
This capture produced 30 KIs: 27 inferred and 3 computed. The generator turned them into 10 queries. Six are match queries, which find specific log lines. Four are STATS queries, which track a value per minute. We ran every one against the healthy baseline and the incident. The table shows the three that this section walks through.
Query | Linked KIs | Healthy | Incident |
|---|---|---|---|
Payment Service gRPC Unavailable (connection refused or i/o timeout) | frontend-payment-grpc, checkout-payment-grpc, grpc-js | 0 | 676 |
Payment gRPC Connection Failure (frontend → payment) | frontend-payment-grpc, frontend, payment | 0 | 676 |
Checkout Service Startup / Configuration Boot | checkout, otel-demo | 0 | 1 |
Methodology: Test setup on the OpenTelemetry demo
Methodology. One capture of the OpenTelemetry demo 1.12.0 with two scenarios applied, each as an environment variable change. payment-unreachable sets checkout's PAYMENT_SERVICE_ADDR to payment:9999 instead of the payment service's real port, 50051. load-generator-ramp raises the load generator's LOCUST_USERS from 10 to 30. That gives 3,436 documents while healthy and 6,305 during the incident. One extraction run and one generation run, both with default settings. We executed each stored query against both windows and counted the matching documents.
The first two catch the outage. To see why they work, take the predicates apart and trace each one back to a KI.
Where the phrase literals come from
The phrase literals come from the text the KIs carry. "rpc error: code = Unavailable" and "connection refused" appear verbatim in the frontend error line that dataset_analysis lists among the most common values of body.text. "i/o timeout" appears in the evidence of the frontend-payment-grpc and payment KIs. The prompt requires every literal to come from the data. A component's name is inferred, so it rarely appears verbatim in the logs.
How dependency KIs decide what to watch
The dependency KIs decide what to watch. The prompt asks for queries on the communication path between two named services. Two dependency KIs point at payment. checkout-payment-grpc is the call checkout makes. frontend-payment-grpc comes from the frontend's error text, which reports the payment failure on the user's behalf. Both point at the same failure, so the generator wrote a query about gRPC calls to payment becoming unavailable.
How the technology KI identifies gRPC client errors
The technology KI (grpc-js) identifies these lines as gRPC client errors in the frontend. The text inside them comes from checkout. Its Go gRPC client reports the unreachable payment port as rpc error: code = Unavailable with the transport error underneath, and the frontend logs that text inside its own error. The query matches that exact structure.
How the schema KI picks the field to query
The schema KI decides the field. The source follows OpenTelemetry semantic conventions, so the message lives in body.text, and entity fields like app and k8s.deployment.name sit under resource.attributes. That object is a passthrough, so queries can use k8s.deployment.name directly.
Neither query is scoped to a service. Leaving the scope off costs nothing here, because these phrases only ever appear in frontend logs. The third row shows the opposite case: the generator scoped that query to checkout through k8s.deployment.name and matched checkout's startup line. That line is also part of the evidence behind the checkout-payment-grpc KI:
service config: &{productCatalogSvcAddr:product-catalog:3550 cartSvcAddr:cart:7070 ... paymentSvcAddr:payment:9999 ...}The startup query matches once, when checkout restarts with the bad port. Its severity is 25 because a restart isn't an incident on its own. Still, it's the most precise signal in the batch, because it shows the misconfiguration itself in plain text.
Three prompt rules that keep generated ES|QL queries accurate
A detection query has a hard job. It has to stay quiet on a healthy day and catch a failure that hasn't happened yet. The payment queries above return zero for the whole healthy stretch, and that zero is correct. A check that rejected every query with no matches today would throw away the best ones. Significant Events puts its guardrails earlier instead, in what the generator is allowed to write.
Match exact phrases: MATCH_PHRASE vs the : operator in ES|QL
In ES|QL, body.text : "failed to charge card" matches documents that contain any one of those words. On this source, that query matches 432 documents while everything is healthy. Most of them are lines like order confirmation email sent to "steve@example.com", which match on the word "to". MATCH_PHRASE(body.text, "failed to charge card") matches 0 while healthy and 676 during the outage. It's the second query in the table above. Validation enforces this in code. It rejects any multi-word : or MATCH without the AND operator, so a query like that never reaches storage.
Filter only on fields that carry a signal, not on log.level
log.level is the field the naive rule in Part 1 leaned on. In this capture, only checkout and payment set a level, and every level they write is info. No document carries an error level, even in the middle of the outage. The prompt tells the generator never to filter on a field that dataset_analysis doesn't list, and not to filter on a severity whose value never changes. The generator never used log.level and matched on the error text the services write instead.
Combine ES|QL predicates only when they share a document
dataset_analysis tells the generator that a field or a phrase exists somewhere in the source. It doesn't say that they appear on the same documents as another predicate. A service scope and an error phrase can each be real and still never meet, for example when the error is logged by the caller and not by the service that failed. The prompt tells the generator to combine two predicates only where the evidence puts them on the same documents. Otherwise it keeps only the predicate that carries the signal.
How we measure which prompt rules work
These rules come from measurement. Our evaluation suite injects failures into test environments, runs the generated queries against them and counts what they catch. We keep a rule in the prompt when it raises that hit rate.
Match queries vs STATS queries, and which become Kibana alerting rules
What match queries and STATS queries each detect
The generator writes two kinds of query, and they answer different questions. A match query is cause-based. It finds the specific event that says what broke, like the gRPC Unavailable line. A STATS query is symptom-based. It turns the source into a per-minute series, such as an error rate or a request volume, that shows something is wrong even when no single line says so.
The prompt asks for strict shapes. A match query is FROM ... | WHERE ... and nothing else: no SORT, LIMIT or KEEP, because the system manages those. A STATS query computes one value per one-minute bucket into a column called metric_value, and it keeps every bucket the aggregation produces, with no threshold that drops points.
Which ES|QL detection queries become Kibana alerting rules
Severity decides what happens next. The generator scores each query from 0 to 100, by the kind of problem it detects and how serious that problem is. A security problem starts higher than an error, and an error starts higher than a configuration change. The payment query scored 85.
A match query with severity 60 or higher is promoted to a Kibana alerting rule automatically. Each promoted rule runs every 5 minutes with a 7-minute lookback, and writes how many documents it matched. Severity also picks how closely the next stage watches that count. By default, rules at 80 and above get the critical profile, a 40-minute window in 1-minute buckets. The rest are analyzed over about two hours in 5-minute buckets. Match queries below 60 stay stored as KIs, and you can promote any of them by hand. STATS queries are stored as KIs and aren't promoted to rules yet.
In this batch, four match queries scored 60 or higher. Both payment queries became critical rules and fire during the outage. The other two watch for email delivery failures and Kubernetes restart events, and neither matches anything in this capture.
How duplicate ES|QL queries are detected and skipped
Generation runs again whenever extraction finds something new, so on a busy source the generator keeps meeting its own earlier output. For each candidate it has to decide whether to skip it, replace an existing query, or add a new one.
This split between code and model is the same one Part 1 used for identity. Code rejects exact duplicates after normalizing the ES|QL. Everything subtler is the model's call. That includes a query that differs only by one added filter, and the same signal written with MATCH_PHRASE instead of an AND chain. The prompt tells it that functional equivalence counts as a duplicate, and to prefer skipping over replacing when it's unsure. A replacement keeps the existing query's ID, so a rule built on it keeps working.
When a detection query retires and its Kibana alerting rule is deleted
Part 1 promised that queries retire when the knowledge they rest on does.
Every query gets an expiry when it's written. A reconcile pass then checks each one against the live feature KIs of its source. If the query has expired, or if any one KI in its features list is no longer live, the reconcile pass retires the query and removes its rule.
The payment query above can live only as long as frontend-payment-grpc, checkout-payment-grpc and grpc-js keep being observed. If the demo moved payment to HTTP and extraction stopped seeing the gRPC edge, that KI would expire, and the query would go with it. Excluding a KI on the Knowledge Indicators page has the same effect, because an excluded KI isn't live. That's the review point Part 1 described: you correct the system's understanding once, and the queries built on the wrong idea disappear without you touching them.
What's next for Significant Events
Part 1 built what the system knows about this source, and this post turned that into queries that retire when it changes.
Next, we're bringing the evaluation checks to live sources, so a query that can never match gets flagged in production too. On a quiet day a broken query and a correct one can look the same, so we're getting that check right before it removes anything.
Part 3 takes the rules from this batch and follows them through the outage. It covers what happens to the 676 matches, and how change point detection spots the jump in a rule's count.
How helpful was this content?
Related Content
How Elastic Significant Events turns 100 log samples into detection rules
The Great Cat Escape: A hands-on guide to OpenTelemetry, Elastic APM, and Kibana alerting
One ES|QL query, 365 days of audit logs: Same search on hot data and searchable snapshots
The service with the most errors was healthy: root cause analysis from logs with ES|QL