
向量数据库应该为您做什么?


Elasticsearch 向量数据库:不仅仅是向量,深受开发人员喜爱
没有漏洞,也无需妥协。经过优化的默认设置。混合检索。一切协同运作,因为这一切本就是如此构建的。
只需一次调用:数分钟内从零实现向量搜索
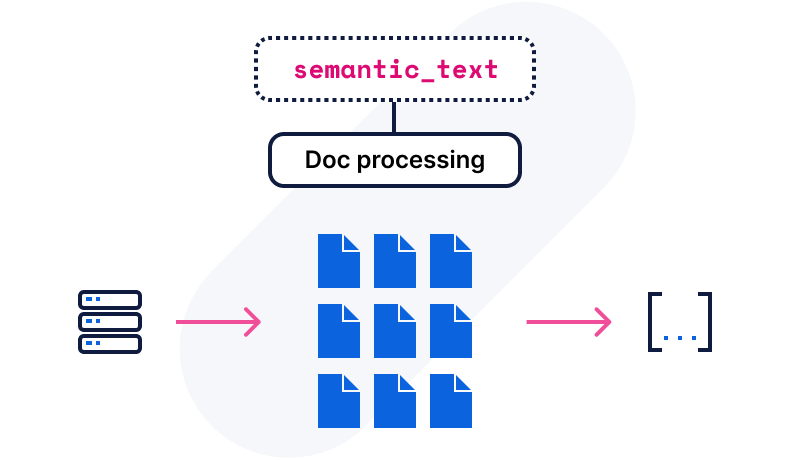
开始使用 Elasticsearch 向量数据库。为向量工作负载、混合搜索以及生成嵌入或接入自有模型提供优化的默认设置,助您以最快速度实现向量搜索。
您只需提供内容,剩下的交给我们。
from elasticsearch import Elasticsearch

client = Elasticsearch(
   "https://xyz.elastic.cloud:443",
   api_key="..",

)

client.indices.create(
   index="my_semantic_vectors",
   mappings={
       "properties": {
           "content": {"type": "text", "copy_to": "semantic_content"},
           "semantic_content": {"type": "semantic_text"},
       }
   },
)

client.bulk(
   operations=[
       {"index": {"_index": "my_semantic_vectors"}},

       {"content": "Yellowstone National Park spans Wyoming, Montana, and Idaho, covering over 2.2 million acres. It is famous for the geyser Old Faithful and sits atop the Yellowstone Caldera, a supervolcano."},

       {"index": {"_index": "my_semantic_vectors"}},

       {"content": "Yosemite National Park covers over 750,000 acres in California. A UNESCO World Heritage Site, it is best known for its granite cliffs, waterfalls, and giant sequoia trees."},

       {"index": {"_index": "my_semantic_vectors"}},

       {"content": "Rocky Mountain National Park is known for its mountainous terrain, including Longs Peak, the highest in the park. It is a popular destination for hiking, camping, and wildlife viewing."},
   ],
)
from elasticsearch import Elasticsearch

client = Elasticsearch(
   "https://xyz.elastic.cloud:443",
   api_key="..",

)

client.indices.create(
   index="my_semantic_vectors",
   mappings={
       "properties": {
           "content": {"type": "text", "copy_to": "semantic_content"},
           "semantic_content": {"type": "semantic_text"},
       }
   },
)

client.bulk(
   operations=[
       {"index": {"_index": "my_semantic_vectors"}},

       {"content": "Yellowstone National Park spans Wyoming, Montana, and Idaho, covering over 2.2 million acres. It is famous for the geyser Old Faithful and sits atop the Yellowstone Caldera, a supervolcano."},

       {"index": {"_index": "my_semantic_vectors"}},

       {"content": "Yosemite National Park covers over 750,000 acres in California. A UNESCO World Heritage Site, it is best known for its granite cliffs, waterfalls, and giant sequoia trees."},

       {"index": {"_index": "my_semantic_vectors"}},

       {"content": "Rocky Mountain National Park is known for its mountainous terrain, including Longs Peak, the highest in the park. It is a popular destination for hiking, camping, and wildlife viewing."},
   ],
)
借助 Elasticsearch 向量数据库进行构建


向量数据库,以及您实际需要的其他一切
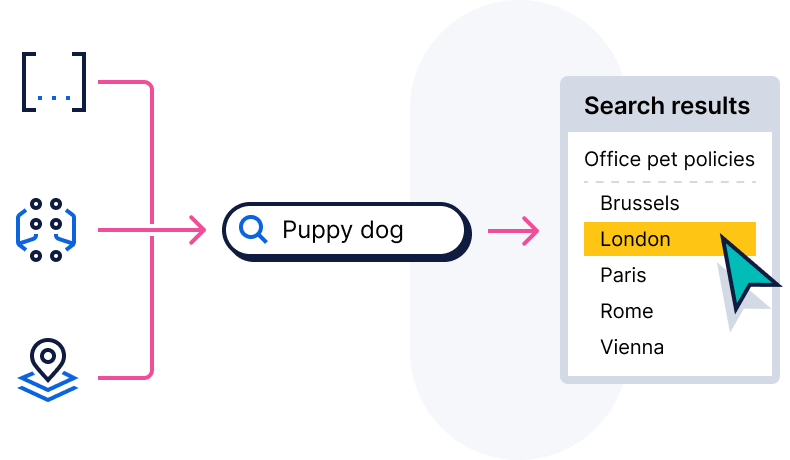
实际应用中的向量搜索所需的不只是向量。无需额外拼接,即可在单个查询中将语义搜索与筛选器、安全性、结构化字段和 BM25 排序相结合。

高品质社区
从提示词到产品,团队如何利用 Elasticsearch 向量数据库构建产品。
客户聚焦
FRAIM 使用 Elasticsearch 构建面向 AI 时代的知识搜索平台,通过原生整合文本搜索和向量搜索,将整体搜索平台成本降低 50% 以上,并显著加快 RAG 和 AI 智能体的开发。
客户聚焦
WP Engine 利用 Elasticsearch 为 WordPress 网站引入 AI 创新,并借助与 Google Cloud 的原生集成,将 AI 功能开发时间从数周缩短至数小时,同时实现 5ms 的搜索响应时间和零停机运行。
客户聚焦

Adobe 可以扩展、管理多种用例,并将机器学习功能与 Elastic 结合使用。
用数字看结果
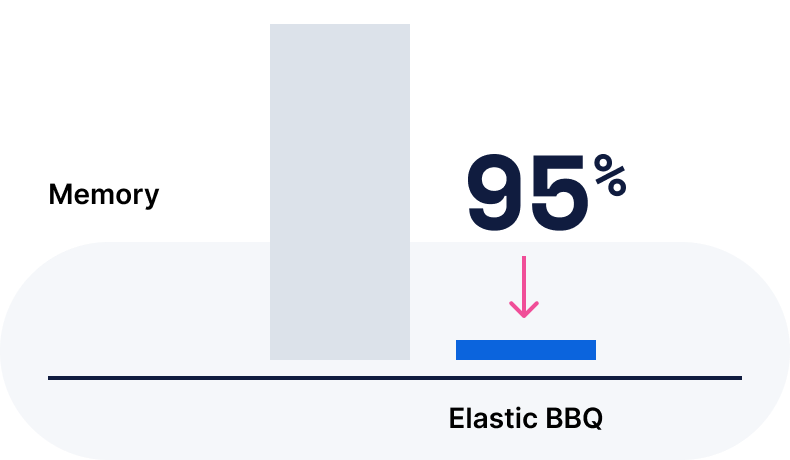
Elasticsearch 向量数据库性能基准测试和结果。


入门指南:构建各个阶段所需的资源
采集、解析和索引
嵌入
检索
开发工具
嵌入
检索
开发工具
常见问题
什么是向量数据库?它是如何运作的?
什么是向量数据库?它是如何运作的?
向量数据库将信息存储为向量,即数据对象的数值表示,也称为向量嵌入。它利用向量嵌入,在海量结构化、非结构化和半结构化数据(如图像、文本、视频和音频)中实现多模态搜索。向量数据库专为管理向量嵌入而构建,因此可提供完整的数据管理解决方案。
什么是向量嵌入?
什么是向量嵌入?
向量嵌入使用机器学习模型将文本转化为数字,让您可以执行向量搜索。通过将数据转换为向量,嵌入可以更容易地比较、搜索和分析空间中项目之间的相似性。
向量数据库有哪些优势?
向量数据库有哪些优势?
向量数据库可实现本地部署、隔离和主权云环境之间的无缝数据迁移,并为向量嵌入提供存储空间,从而提供大规模搜索的效率。
向量数据库擅长相似性搜索,可以让您轻松找到相关项目,这对于推荐系统、图像搜索和内容发现至关重要。借助语义搜索功能,它们不只停留在关键词的简单匹配上,而是能够根据词语的意义和上下文环境来提供搜索结果。通过存储向量嵌入,它们可以支持人工智能和机器学习应用程序,从而更容易部署自然语言处理 (NLP) 和推荐模型。
Elasticsearch 是向量数据库吗?
Elasticsearch 是向量数据库吗?
是的,Elasticsearch 是世界上部署最广泛的开源向量数据库,为您提供大规模、高效地创建、存储和搜索向量嵌入的有效方法。借助 Elastic 的企业级向量数据库,即使数据快速变化,您也可以实现快速查询时间和最佳性能。它可根据扩展进行构建,在简化开发流程的同时提供相关的个性化搜索结果。
为什么选择 Elastic 作为您的向量数据库?
为什么选择 Elastic 作为您的向量数据库?
Elasticsearch 是全球下载量最高的向量数据库,专为帮助开发者更快速、更低成本地提供高精度搜索和可扩展的 AI 体验而打造。Elasticsearch 向量数据库开箱即用地处理混合检索中的复杂环节,提供优化的默认设置、原生 Jina AI 和第三方模型,以及托管式 GPU 推理。您可以在单个索引中对文本、图像和多模态数据执行向量搜索和关键词搜索,无需构建或维护嵌入流水线。它针对向量工作负载进行了预先调优,可提供高性能,在流量激增时自动承载额外负载,并在需求下降时相应缩减资源。您还可以获得所需的安全性、RBAC 和恢复机制,让您专注于构建应用,而不是管理基础设施。
我能否将 Elasticsearch 作为本地部署或隔离向量数据库运行?
我能否将 Elasticsearch 作为本地部署或隔离向量数据库运行?
是的。Elasticsearch 完全可以本地部署在裸机、私有云或没有外部连接的完全隔离网络中。政府机构、国防承包商和受监管企业使用 ECE 来扩展本地部署的 Elasticsearch 集群,包括在保密和断开连接的环境中。Elastic Cloud 上的所有向量搜索、混合搜索和 RAG 功能在本地部署中同样可用。