
One field, one copy: How Elasticsearch columnar storage drops the inverted index
Storing each field once means no inverted index, so doc values now read in bulk and skippers let queries skip whole ranges of documents, while new mapping attributes control what each field is allowed to contain.
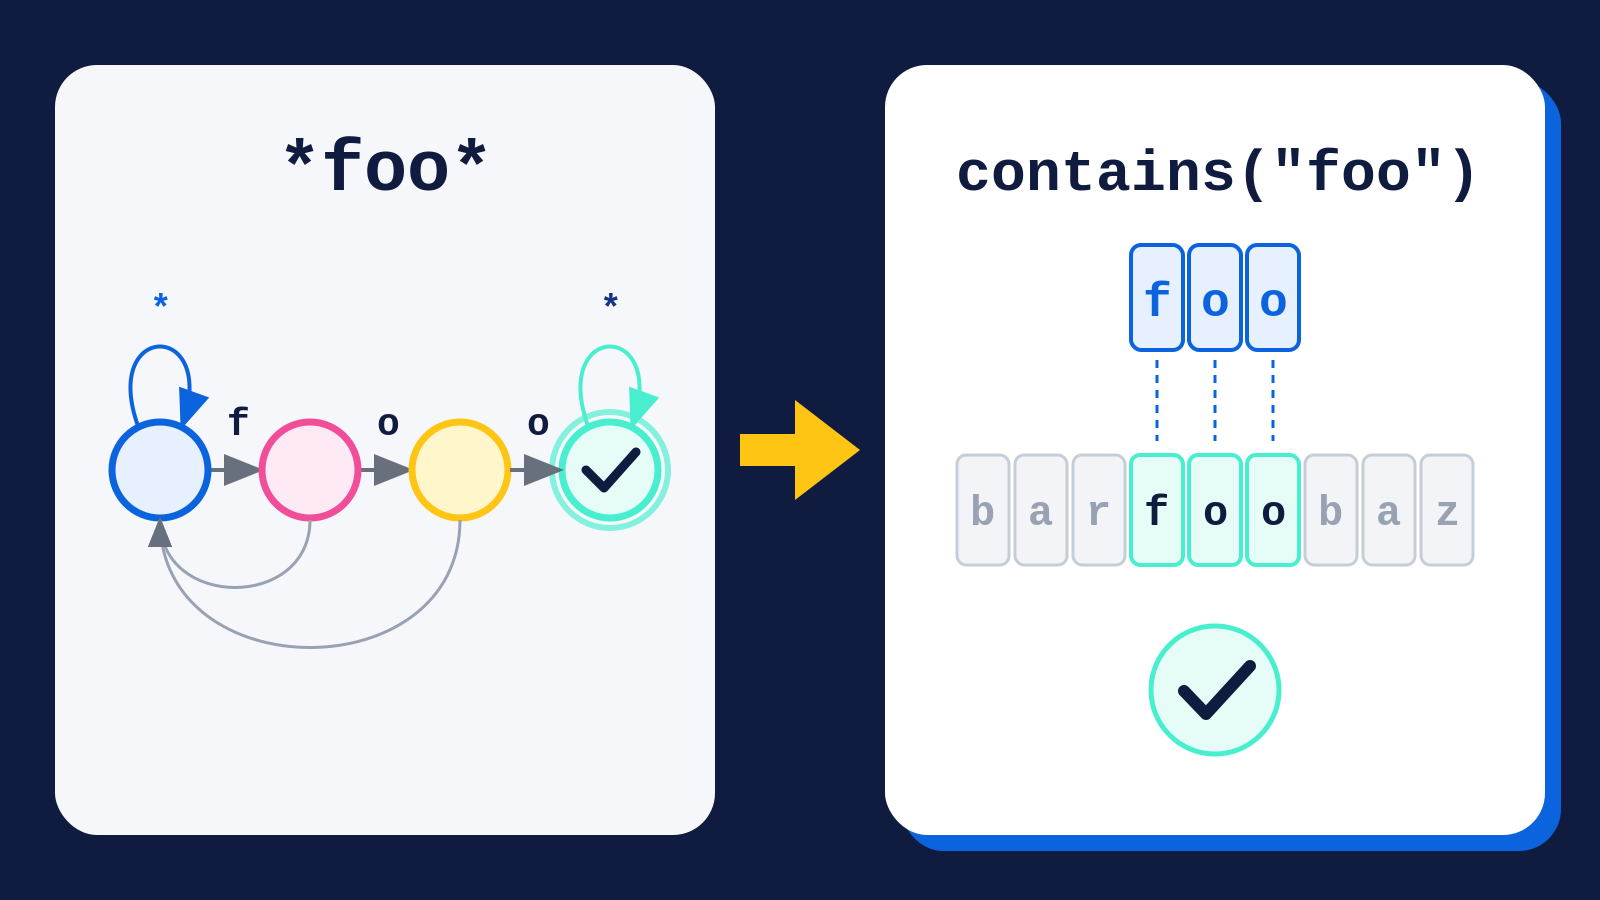
Query rewrite rules in Elasticsearch: 2.3x faster wildcard scans
A second rule makes empty-string filters 1.6x faster. It reads string lengths straight from the offset array and never touches the compressed bytes. Both rules came from the same habit of running real queries and hunting for the special case.

30x faster than Prometheus: How we rebuilt Elasticsearch as a leading columnar metrics datastore
Elasticsearch now stores OTel metrics at 3.75 bytes per data point and queries them up to 30x faster than Prometheus. Here's how we rebuilt TSDS and ES|QL.
LogsDB and TSDS performance and storage improvements in Elasticsearch 8.19.0 and 9.1.0
Exploring the latest enhancements to TSDS and LogsDB, including optimizing I/O, improving merge performance, and more.

Storage wins for time-series data in Elasticsearch
Explore Elasticsearch's storage improvements for time series data and best practices for configuring a TSDS with storage efficiency.