Blogs
Entwickler-Einblicke und praktische Anleitungen von unseren Experten, um Ihr Sucherlebnis zu inspirieren und zu verbessern
ChatGPT and Elasticsearch: Creating custom GPTs with Elastic data
Get started with custom GPTs using ChatGPT and Elasticsearch. Learn how to create custom GPTs that interact seamlessly with your Elasticsearch data.
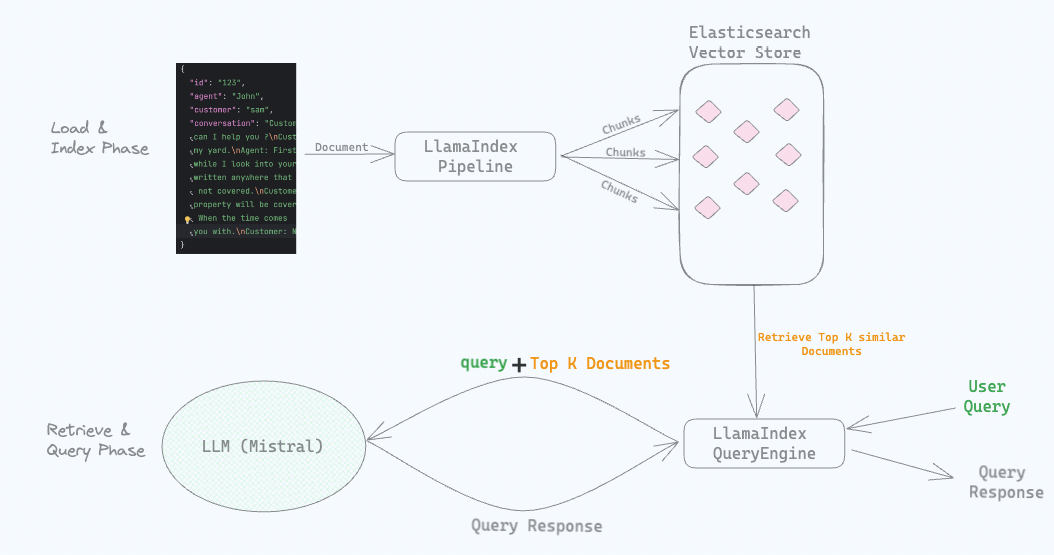
RAG (Retrieval Augmented Generation) with LlamaIndex, Elasticsearch and Mistral
Learn how to implement a RAG (Retrieval Augmented Generation) system using LlamaIndex, Elasticsearch and locally running Mistral.
How to ingest MongoDB data into Elastic Cloud
Gain MongoDB data insights with Elastic Cloud. Learn to ingest & sync data from MongoDB to Elasticsearch using the Elastic MongoDB connector.
Elasticsearch open Inference API adds support for Cohere’s Rerank 3 model
“Learn about Cohere reranking, how to use Cohere's Rerank 3 model with the Elasticsearch open inference API and Elastic's roadmap for semantic reranking.”
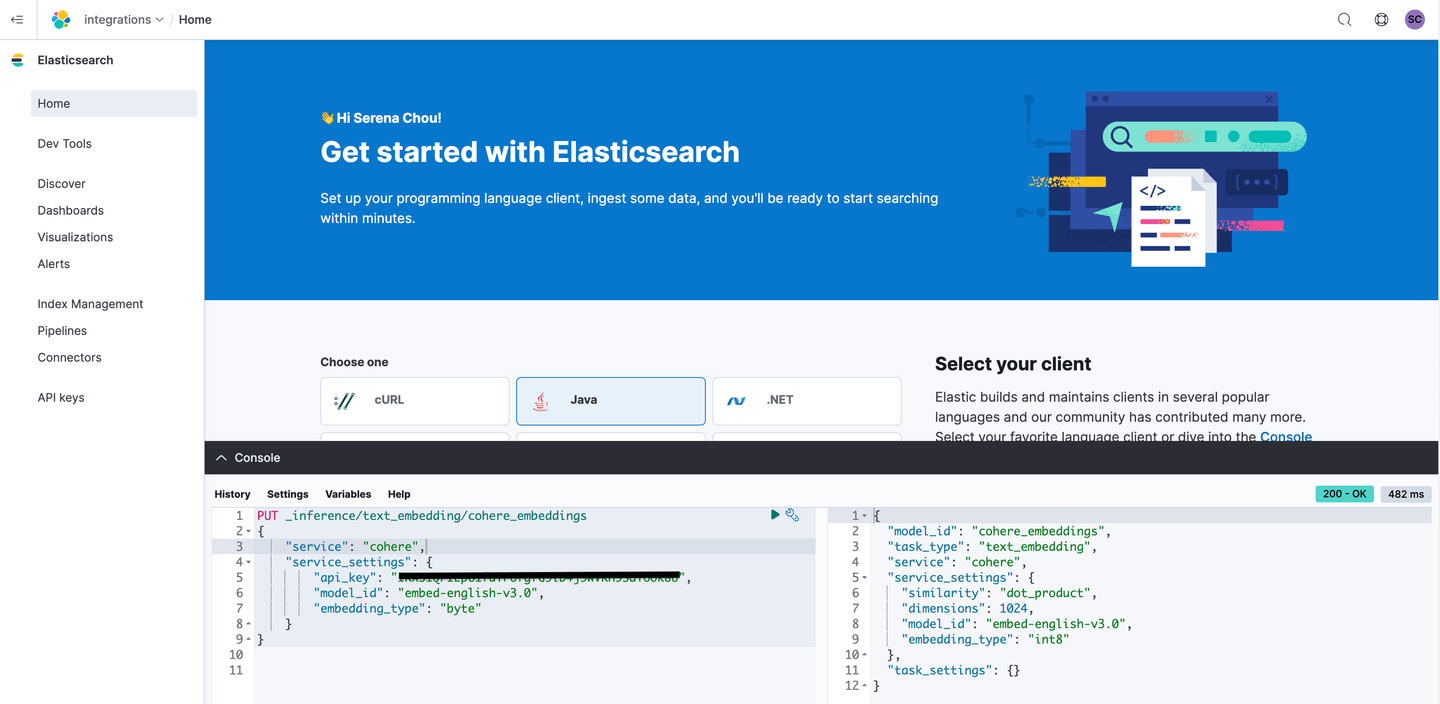
Using Cohere embeddings with Elastic-built search experiences
Elasticsearch now supports Cohere embeddings! This blog explains how to use Cohere embeddings with Elastic-built search experiences.
Scaling ML inference pipelines in Elasticsearch: How to avoid issues and troubleshoot bottlenecks
Learn strategies to run Machine Learning (ML) inference pipelines in Elasticsearch, troubleshoot bottlenecks and avoid issues when scaling.
From ES|QL to PHP objects
Learn how to execute and manage ES|QL queries in PHP. Follow this guide to map ES|QL results to a PHP object or custom class.
Ingesting data from Snowflake to Elasticsearch using Meltano
Ingest data from Snowflake to Elasticsearch with Meltano. Follow along to setup Meltano, connect to Snowflake & ingest data to Elasticsearch.
Elasticsearch binary document ingestion: Evolution & the Data Extraction Service
Discover the history of extracting text from binary documents at Elastic and learn about our open-code solution: the Data Extraction Service.
Building a RAG System With Gemma, Hugging Face & Elasticsearch
Follow this step-by-step guide to build a Retrieval Augmented Generation (RAG) system using Gemma, Hugging Face, and Elasticsearch.
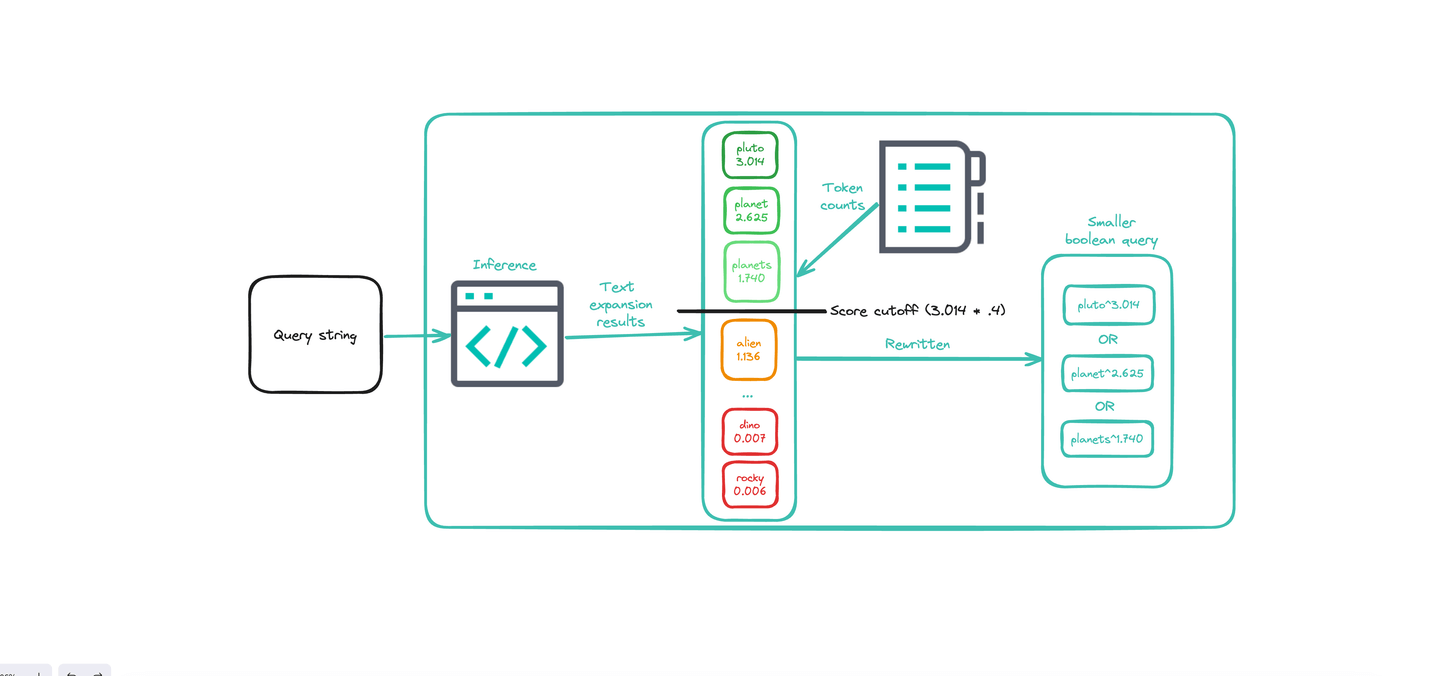
Improving text expansion performance using token pruning
Learn about token pruning and how it boosts the performance of text expansion queries by making them more efficient without sacrificing recall.
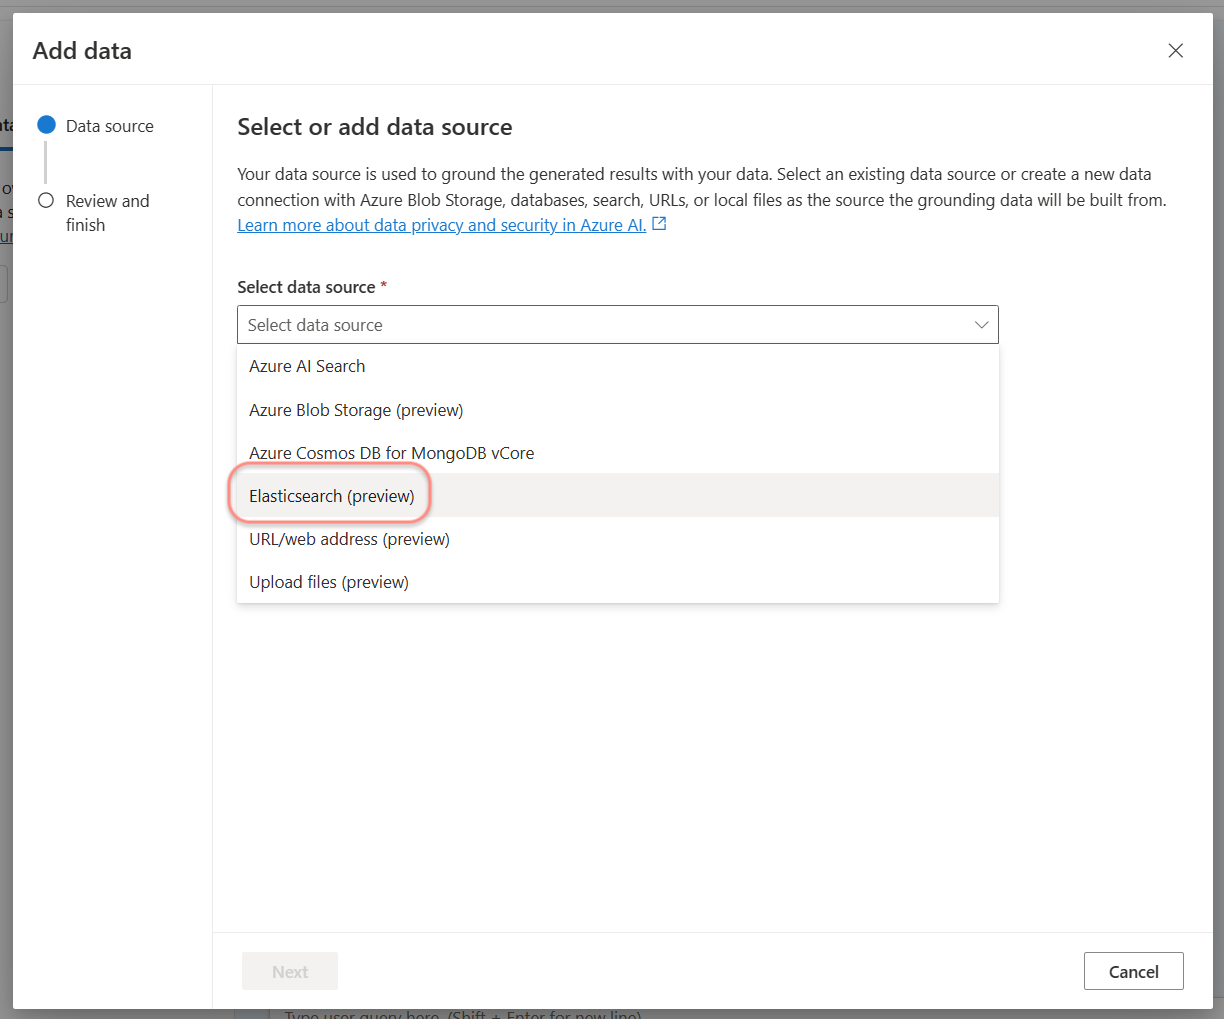
Introducing Elasticsearch vector database to Azure OpenAI Service On Your Data (preview)
Microsoft and Elastic partner to add Elasticsearch (preview) as an officially supported vector database and retrieval augmentation technology for Azure OpenAI On Your Data, enabling users to build chat experiences with advanced AI models grounded by enterprise data.