Blogs
Insights de desenvolvedores e artigos práticos dos nossos experts para inspirar e fortalecer suas buscas
Retrieval Augmented Generation (RAG)
Learn about Retrieval Augmented Generation (RAG) and how it can help improve the quality of an LLM's generated responses by providing relevant source knowledge as context.
Understanding scalar quantization in Lucene
Explore how Elastic introduced scalar quantization into Lucene, including automatic byte quantization, quantization per segment & performance insights.
Implementing image search: vector search via image processing in Elasticsearch
Learn how to implement image search with an example. This blog covers how to use vector search through image processing in Elasticsearch.
A conversational search experience for retail: Elasticsearch Relevance Engine with Google Cloud’s generative AI
This blog presents a new search experience for retailers using generative AI with Vertex AI and Elasticsearch.
Using hybrid search for gopher hunting with Elasticsearch and Go
Learn how to achieve hybrid search by combining keyword and vector search using Elasticsearch and the Elasticsearch Go client.
Perform vector search in Elasticsearch with the Elasticsearch Go client
Learn how to perform vector search in Elasticsearch using the Elasticsearch Go client through a practical example.
Perform text queries with the Elasticsearch Go client
Learn how to perform traditional text queries in Elasticsearch using the Elasticsearch Go client through a practical example.
Elasticsearch as a GenAI caching layer
Explore how integrating Elasticsearch as a caching layer optimizes Generative AI performance by reducing token costs and response times, demonstrated through real-world testing and practical examples.
Scalar quantization 101
Understand what scalar quantization is, how it works and its benefits. This guide also covers the math behind quantization and examples.
How to Use Amazon Bedrock with Elasticsearch and Langchain
Learn to split workplace documents into passages, transform these passages into embeddings in Elasticsearch and integrate Amazon Bedrock LLM.
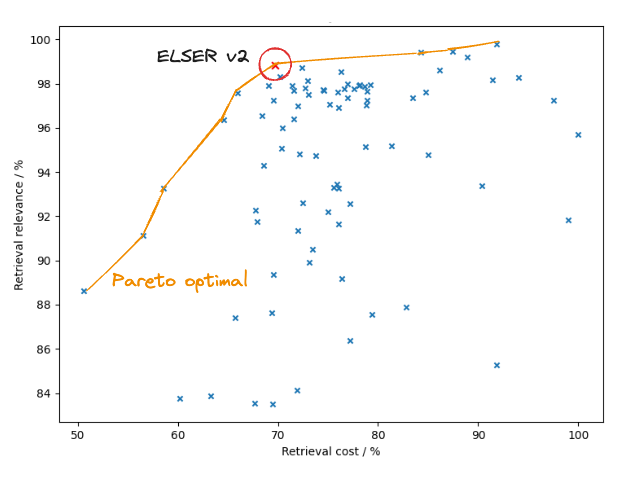
Improving information retrieval in the Elastic Stack: Optimizing retrieval with ELSER v2
Learn how we are reducing the retrieval costs of the Learned Sparse EncodeR (ELSER) v2.
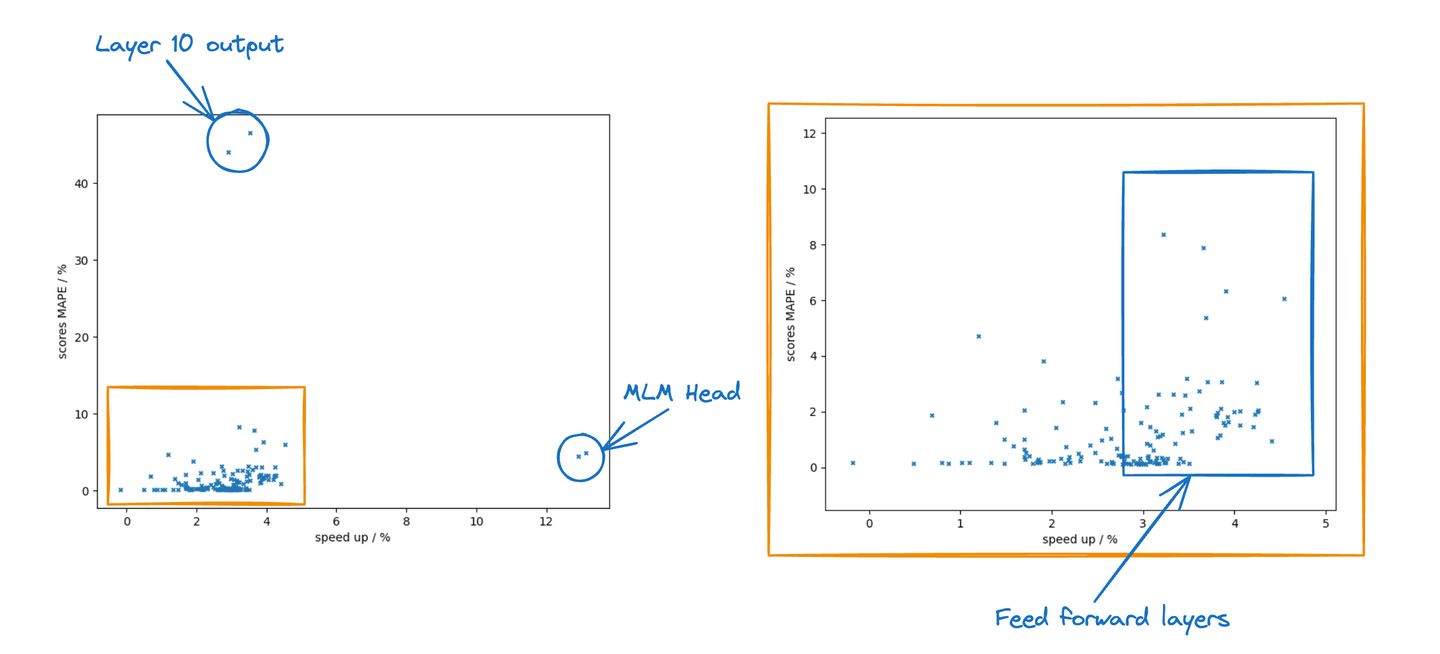
Improving information retrieval in the Elastic Stack: Improved inference performance with ELSER v2
Learn about the improvements we've made to the inference performance of ELSER v2, achieving a 60% to 120% speed increase over ELSER v1.