AI video search with Elasticsearch and Jina: Find the exact seconds of footage you need
Cut each clip at its shot boundaries and embed every scene as a vector, and a plain text query gives back the file plus the exact seconds to drop on a timeline.
jina-ocr-v1: One OCR model for layout, tables, math and 100+ languages
jina-ocr-v1 scores 83.4 on olmOCR-bench with 570 million active parameters, the highest of any OCR model under 600 million, and it outscores GPT-5.2 on OmniDocBench.
0.35% trained, 100% competitive: the frozen-tower architecture behind jina-embeddings-v5-omni
The latest jina embeddings model generates multimodal embeddings for text, images, video and audio, competing with models nearly 6x its size on vector search while training just 0.35% of the weights.
One field, every modality: how Elasticsearch's semantic field indexes and searches images, audio, video and PDFs automatically
The semantic field turns images, audio, video, PDFs and text into multimodal embeddings at ingest time. Describe a scene and find the matching image or use a video frame to surface related clips, all from one Elasticsearch field.
56% faster, up to 50% better retrieval performance: What's inside Jina's new 600 million parameter listwise reranker
Jina Reranker 3.5 beats v3 by 50%+ on case law, closes the gap with models 7x its size on legal, medical, and financial benchmarks, and beats them outright on structured data. It's a drop-in replacement for v3, with no API changes.
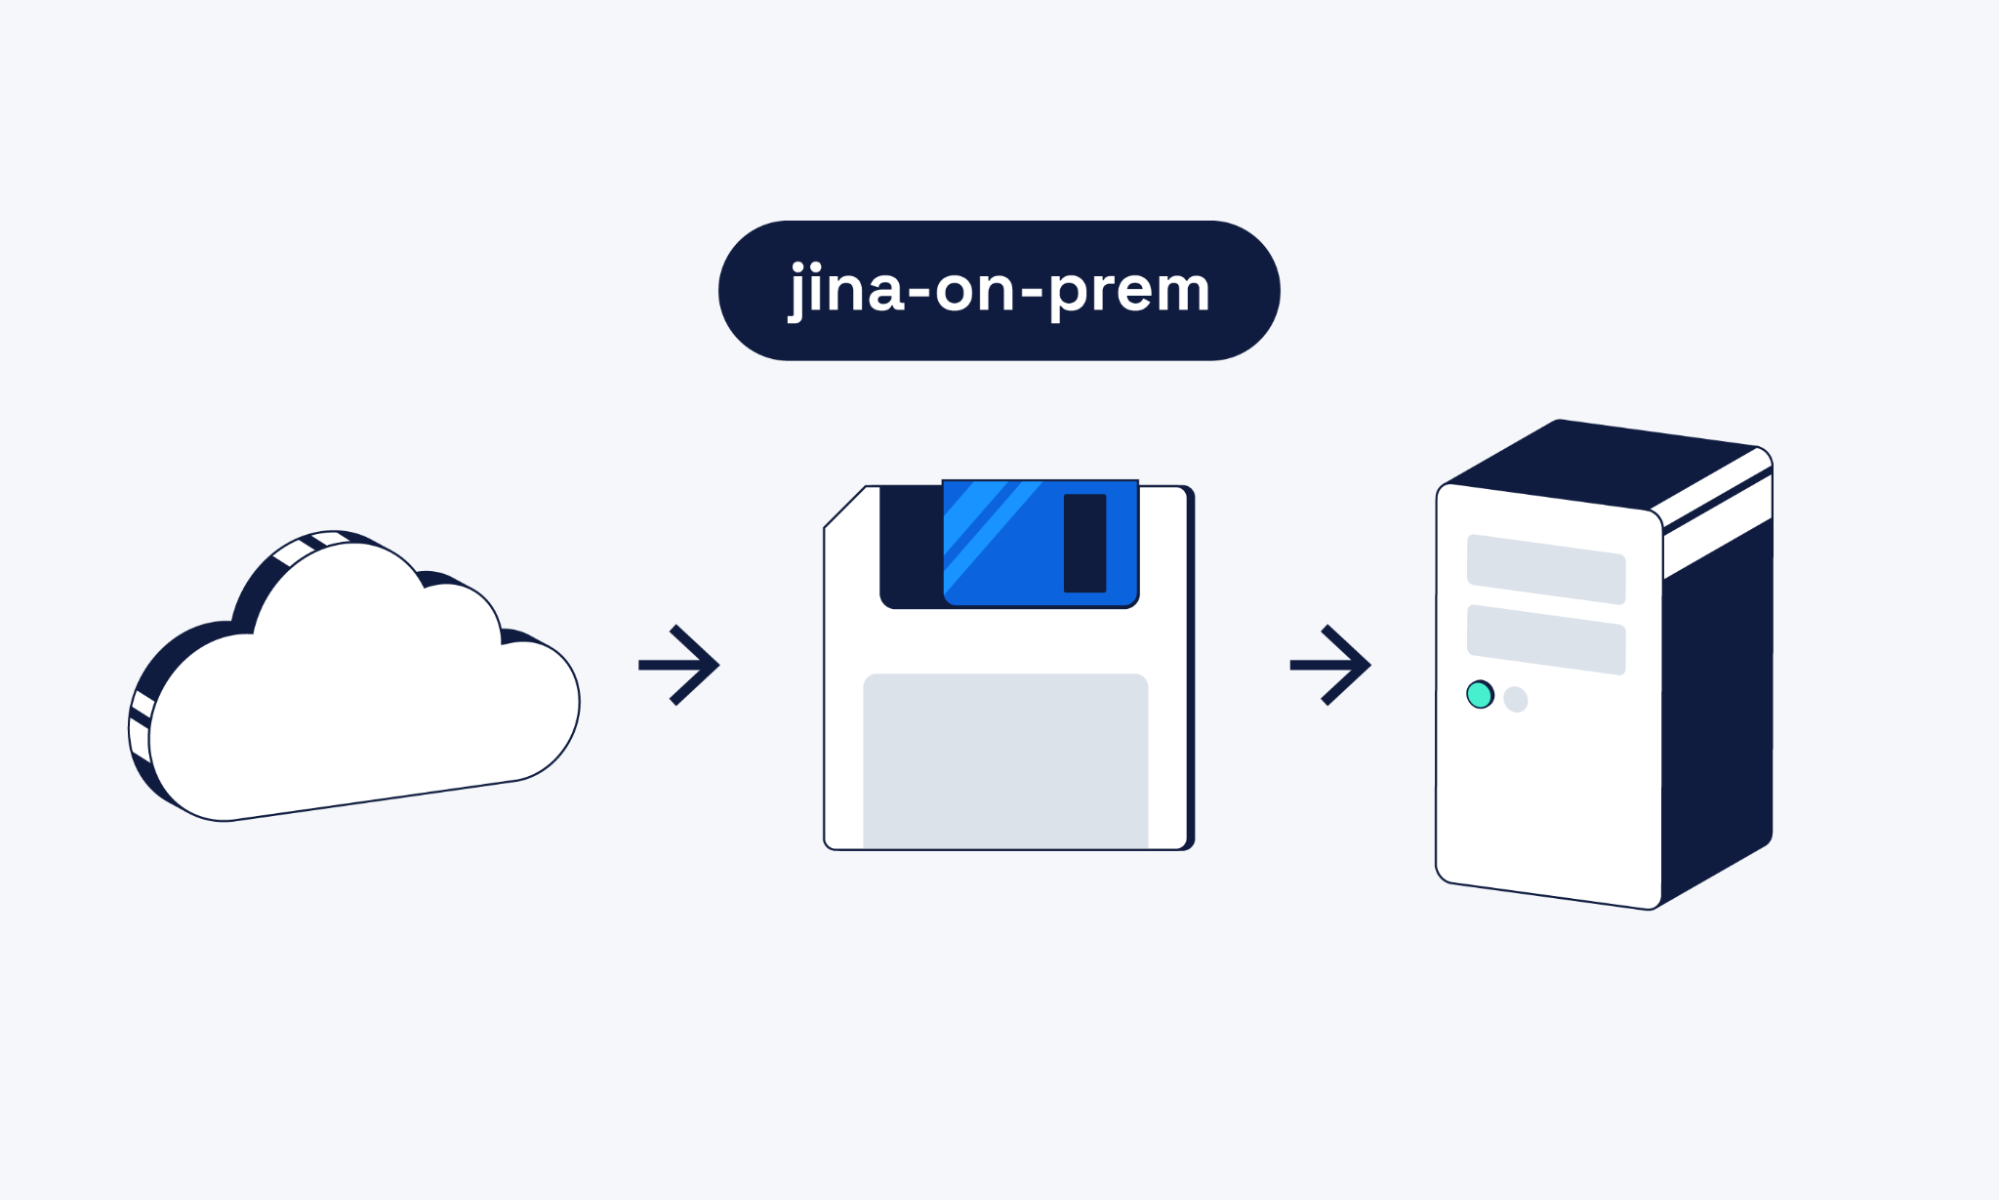
On-prem in under 5 minutes: Jina embedding models now available for on-prem deployment
All 28 Jina AI models, including rerankers, as ready-to-deploy Docker containers, with zero telemetry and no license server. Drop-in compatible with OpenAI, Cohere, Voyage AI and Elastic Inference Service APIs.
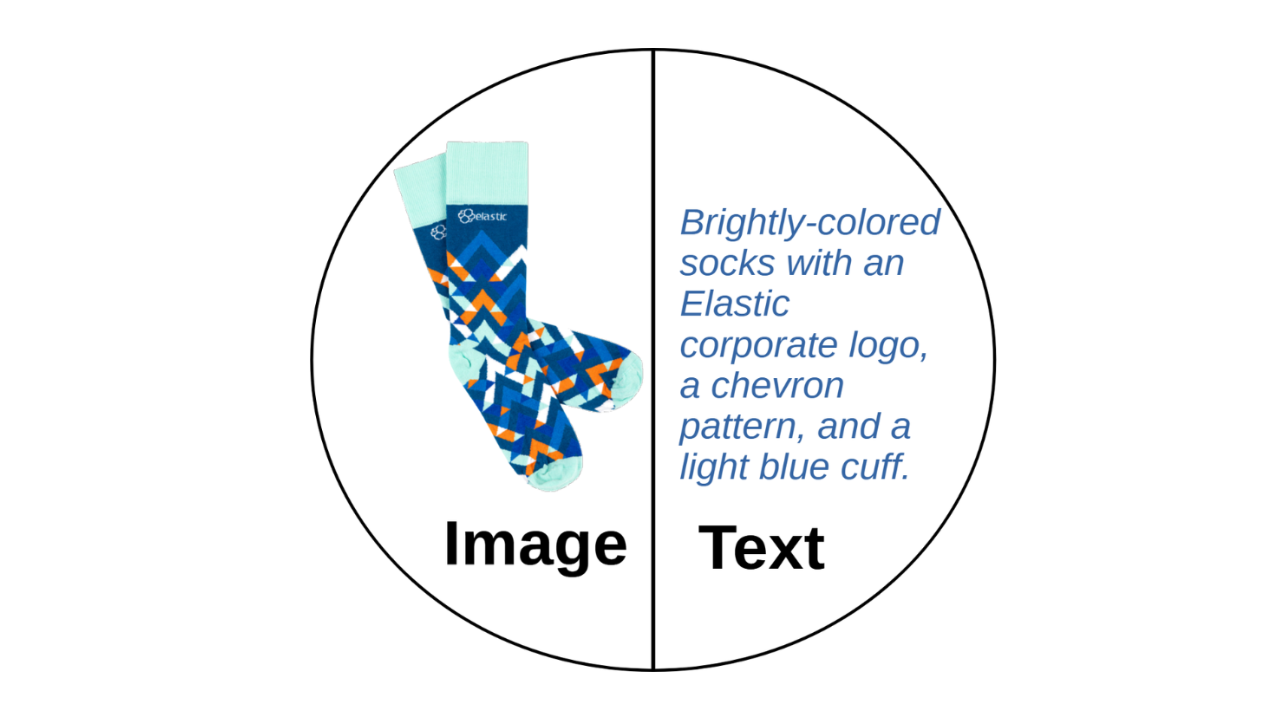
A picture is worth 1.5x the words: What we learned benchmarking product search embeddings
We benchmarked two embedding models on 5,000 real products and found that combining image and text beats either alone by up to 50%. Here's the data and the model that won.
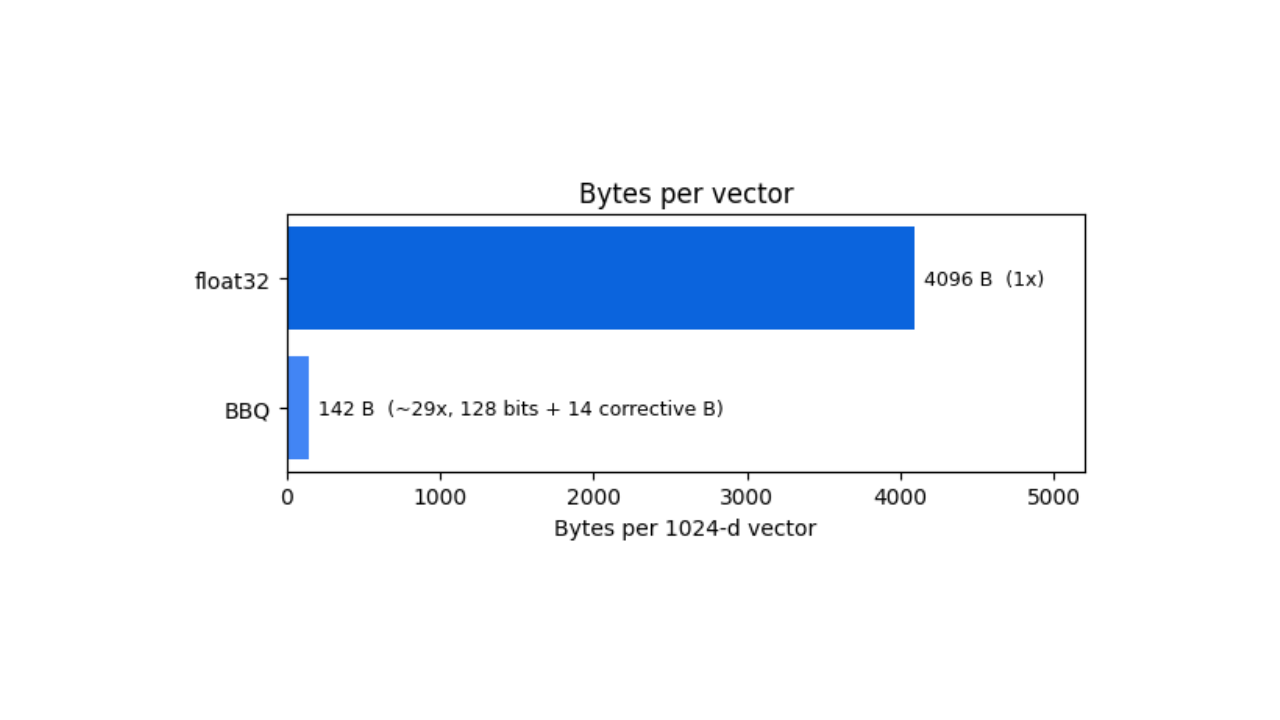
How BBQ shrinks Jina v5 embeddings by 29x without losing recall in Elasticsearch
A hands-on test comparing BBQ and float32 vector indices in Elasticsearch, measuring memory, disk and recall@10 across five languages.
jina-clip-v2 brings text-to-image search across 89 languages to Elasticsearch, no GPU needed
Run multimodal search across 89 languages inside Elasticsearch with jina-clip-v2: one embedding space for text and images, with no separate model infrastructure to manage.
Small model, big benchmarks: how Jina-VLM beat the competition at 2.4B and what ICLR told us is coming next
Jina-VLM is a 2.4B open multilingual VLM leading VQA benchmarks across 29 languages. Plus: five days of ICLR 2026 takeaways on RLVR, sparse embeddings and retrieval.
One index, all media: Introducing jina-embeddings-v5-omni
jina-embeddings-v5-omni lets you embed text, images, video, and audio into a single Elasticsearch index and query across all of them at once.
Jina embeddings v3 now available on Gemini Enterprise Agent Platform Model Garden
Jina search foundation model, jina-embeddings-v3, is now self-deployable on Gemini Enterprise Agent Platform Model Garden, with more to follow. Run jina-embeddings-v3 on a single L4 GPU inside your own VPC.