Blogs
Developer insights and practical how-to articles from our experts to inspire and empower your search experience.
Too much of a good thing: Why 20 candidates beat 200 when reranking search results
We expected more candidates to help, but across 25 benchmarks in Elasticsearch jina-reranker-v3.5 peaked at 100 candidates for BM25 and just 20 for semantic search, where 200 scored worse than no reranker at all.
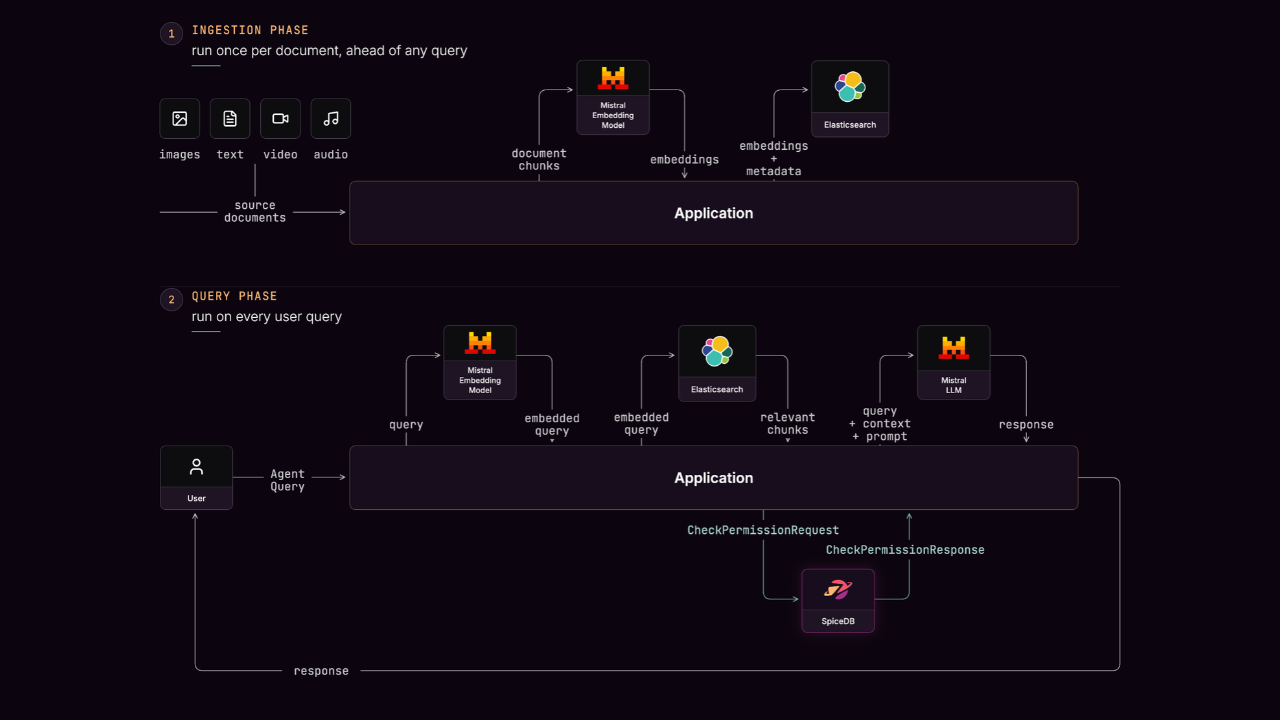
Fine-grained authorization for Elasticsearch RAG with SpiceDB
Department filters break the first time Engineering shares one document with Sales, so SpiceDB checks each retrieved chunk against a relationship graph before your Elasticsearch RAG pipeline passes it to the LLM.
AI connectors in Kibana: 90+ data sources your agent can call
Your index has the alert, but the Slack thread, GitHub PR, Confluence doc and PagerDuty timeline that explain it sit elsewhere. AI connectors are how your agent reads all four while it reasons.
Fewer bits, same recall: More conservative auto-calibration sweeps for DiskBBQ
Elasticsearch now weights document bits three times higher in its cost model, so DiskBBQ tries preconditioning and deeper reranking before spending another bit and quantized vectors stay small at the same recall.
How our agent skills research, build, and test a complete Elastic integration
We pointed our agent skills at the NIST NVD API and got two data streams and a validated CEL program, with pipeline and system tests passing. The research showed 78% of a day’s CVE records are republications of older ones, which changed the design.
We cut 40% of our MCP tools to get into Claude’s connector directory
Anthropic’s reviewers read every tool in our MCP connector and sent back fixes, wording changes and a case for publishing fewer of them, which is part of why mcp.elastic.co is now on the roadmap.
Elastic Cloud Serverless audit logs: Ship the trail to Observability or Security
Eight alerting rules and seven dashboards arrive with the logs, including Kibana Object Forensics, where a deleted detection rule shows up with the person who deleted it and the space it was in.
56 scanned pages to a cited answer in 5 minutes: RAG pipeline for the documents search cannot read
Ask a scanned, table-heavy PDF a question in plain language and get an answer stamped with the page it came from, because jina-ocr-v1 turns every page into structured Markdown that Elasticsearch embeds at ingest.
Bringing Elastic into Claude: The ‘why,’ the ‘how,’ and the ‘gotchas’
Point your Claude plugin at main and every merge ships as a release, and that’s the least surprising thing that happened between submitting and going live.
Your AI chat is not a screenshot: Live shared conversations in Elastic Agent Builder
Whoever picks up the problem next reads the whole thread and carries on with the same agent, with no access to anything beyond that one conversation.
How we’re building a context engine to cut agent token use by 71%
With a context engine, the same agent and model answered in 64 seconds using 9 tool calls. The baseline took 213 seconds, 33 calls, and missed a key relationship entirely.
The fastest work is the work you never do: 100x faster sorted queries in Elasticsearch
How Elasticsearch 9.6 lets ES|QL push its current TopN threshold into Lucene, and how that 100x shows up on some sorted queries and barely registers on others.