Check 100 candidates, not 10 million documents: Faster kNN filters in Elasticsearch
Elasticsearch now decides for each query whether to run a kNN filter before or after the vector search. On a 10M-vector corpus post-filtering was faster in 104 of 120 benchmark pairs while still returning k results.
GPU-accelerated vector indexing in Elasticsearch with NVIDIA cuVS: 138M vectors in under 10 minutes
Moving index builds to the GPU leaves the CPU free for queries, which is how vector indexing throughput went up 7x and p90 search latency fell 6x while indexing ran, with no change to recall.
AI video search with Elasticsearch and Jina: Find the exact seconds of footage you need
Cut each clip at its shot boundaries and embed every scene as a vector, and a plain text query gives back the file plus the exact seconds to drop on a timeline.
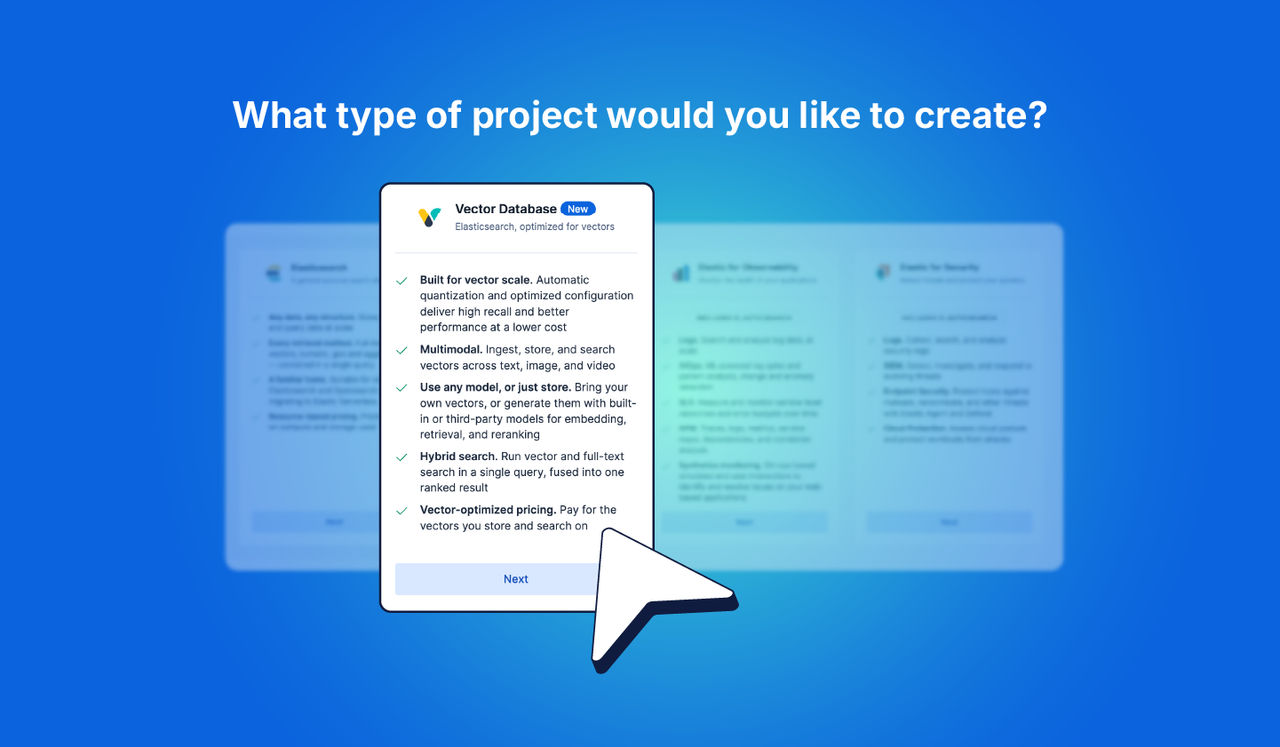
Elasticsearch Vector Database: Ship in minutes, scale affordably to hundreds of billions
The hard parts of hybrid retrieval, already done, with optimized defaults, third party and native Jina AI models, and managed GPU inference all out of the box. Build fast, scalable AI apps, not infrastructure.
One setting for production vector search: How vectordb_document mode tunes Elasticsearch automatically
Benchmarks across four datasets show how one index setting applies bfloat16 vector quantization, cache preloading and parallel merges to improve vector search throughput and decrease storage.
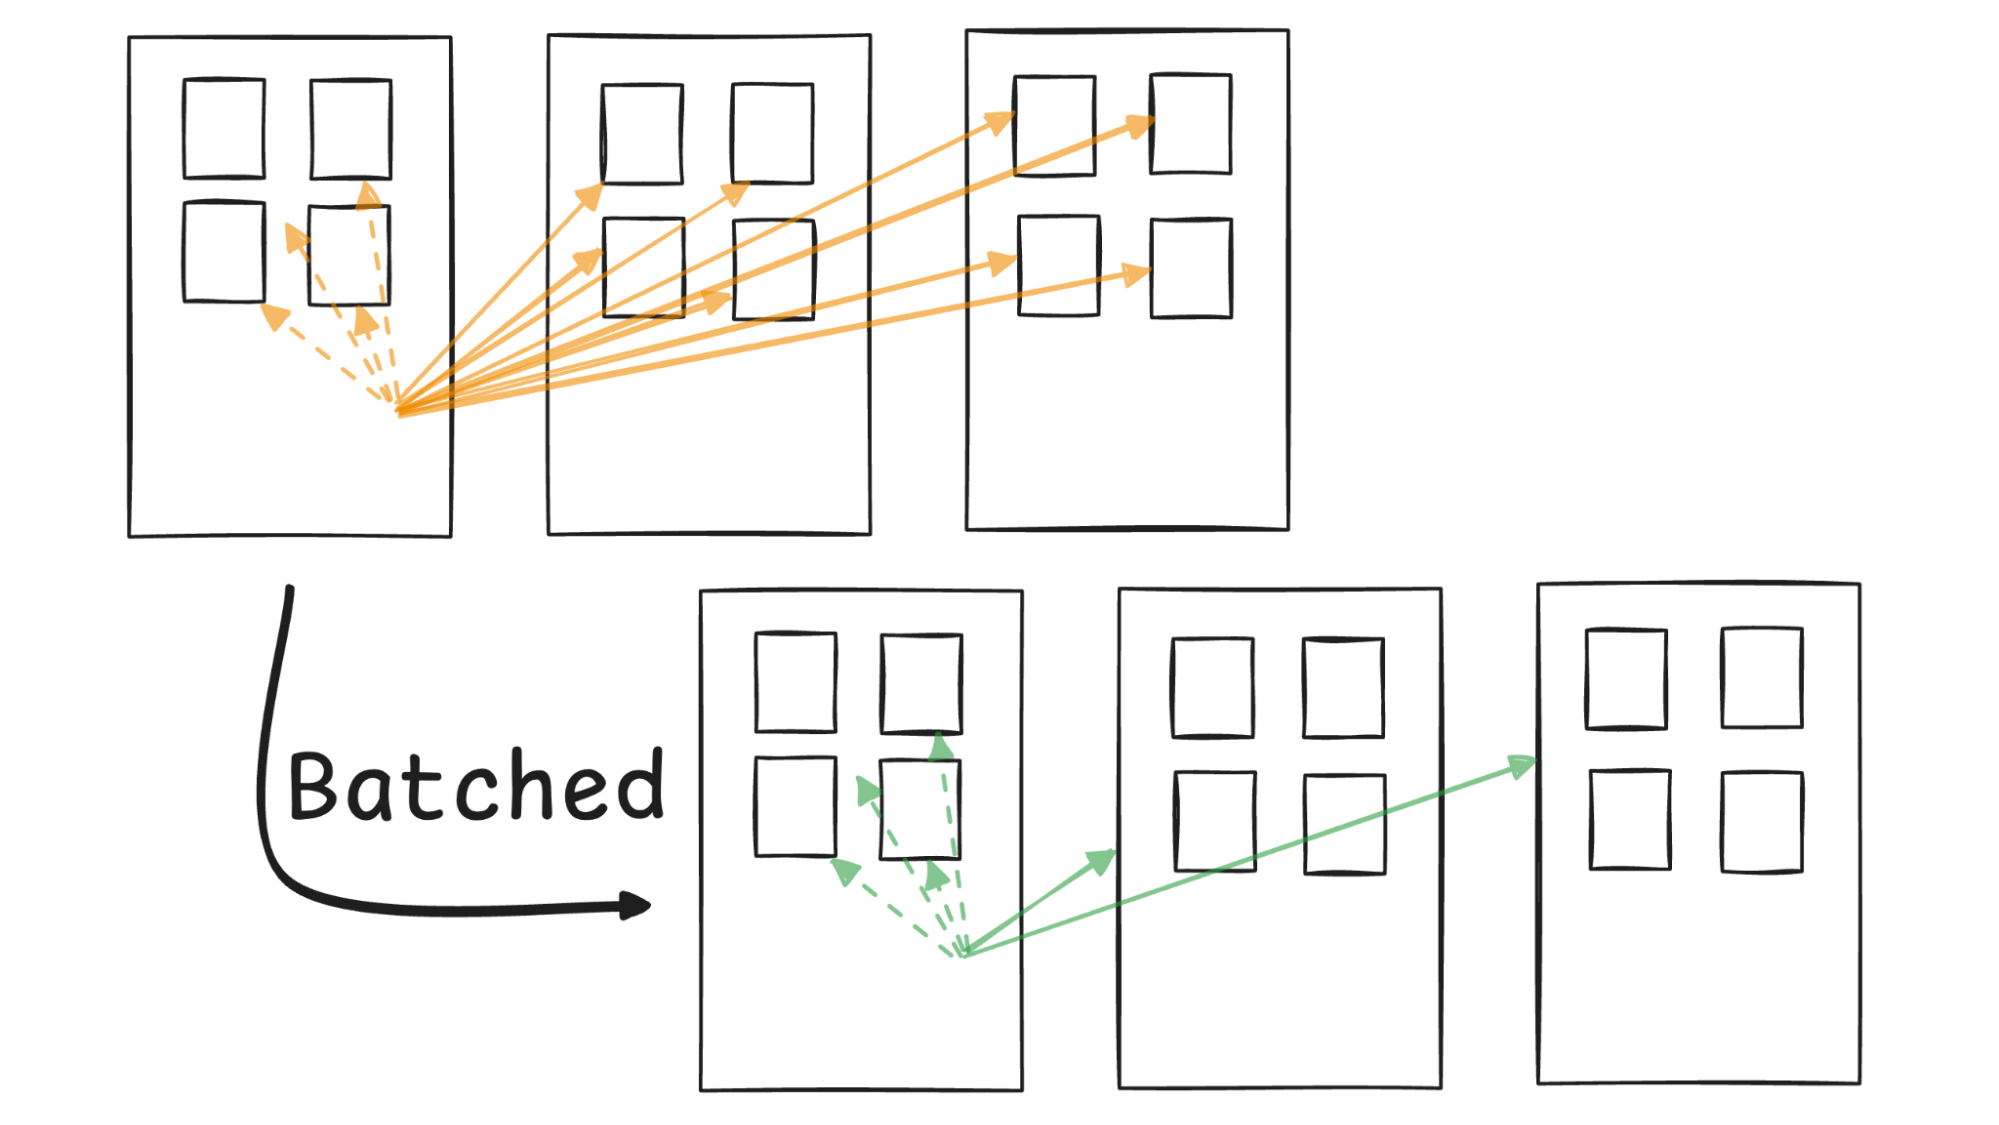
How Elasticsearch's batched query phase improves search performance at scale
The batched query phase can cut search execution time in half by reducing transport overhead and better distributing reduction work across the cluster.
The mystery stress your heap chart can't see: AutoOps now watches vector off-heap memory
Dense vectors use off-heap memory your heap chart never shows. AutoOps detects memory pressure before vector RAM stress causes OOM.
One field, every modality: how Elasticsearch's semantic field indexes and searches images, audio, video and PDFs automatically
The semantic field turns images, audio, video, PDFs and text into multimodal embeddings at ingest time. Describe a scene and find the matching image or use a video frame to surface related clips, all from one Elasticsearch field.
17% faster search, zero config: auto-calibrating vector quantization in Elasticsearch
Automatic calibration at merge time picks vector quantization parameters for each segment by predicting recall from a small sample. Here's how we built it into Elasticsearch's merge path.
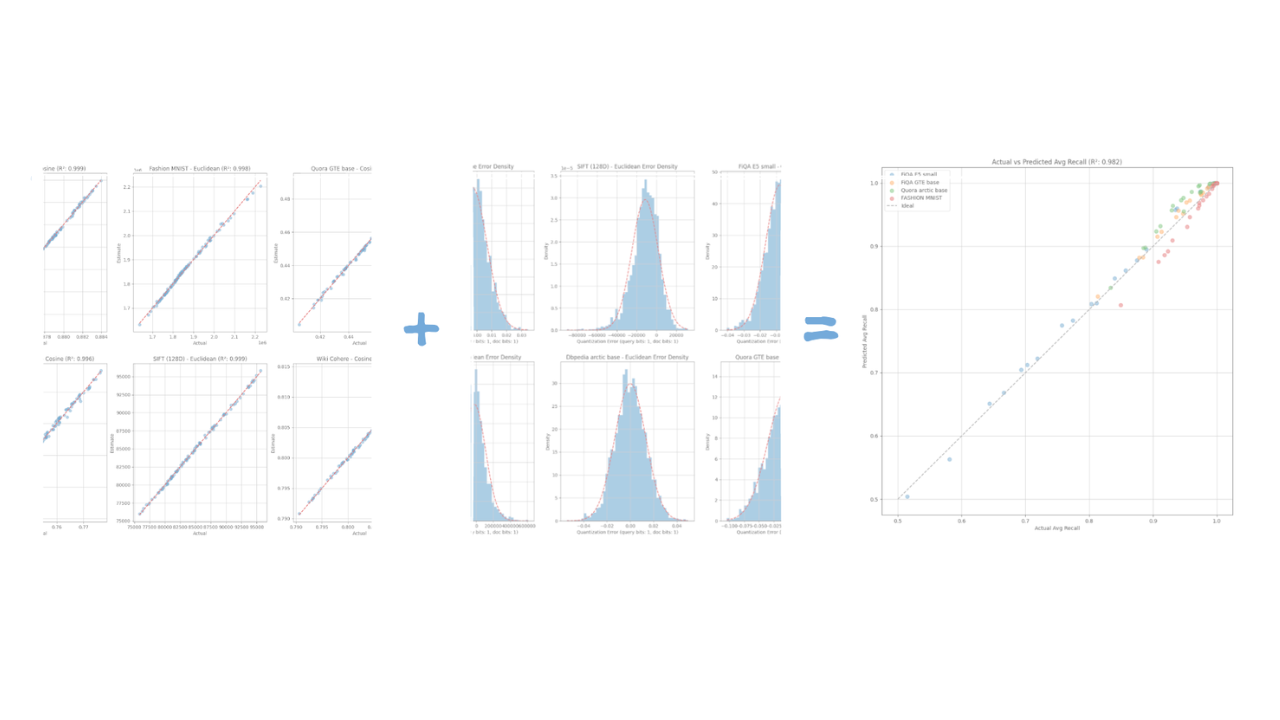
How Elasticsearch auto-tunes vector quantization to hit your recall target
Learn the geometric model that lets Elasticsearch predict recall with R² > 0.98 accuracy and auto-select vector quantization parameters from a small data sample.
4 NVIDIA AI tasks, 1 Elasticsearch API: Embeddings, chat, completion, and rerank
Set up NVIDIA hosted models in Elasticsearch with one API key and a model ID. No custom integration code needed.
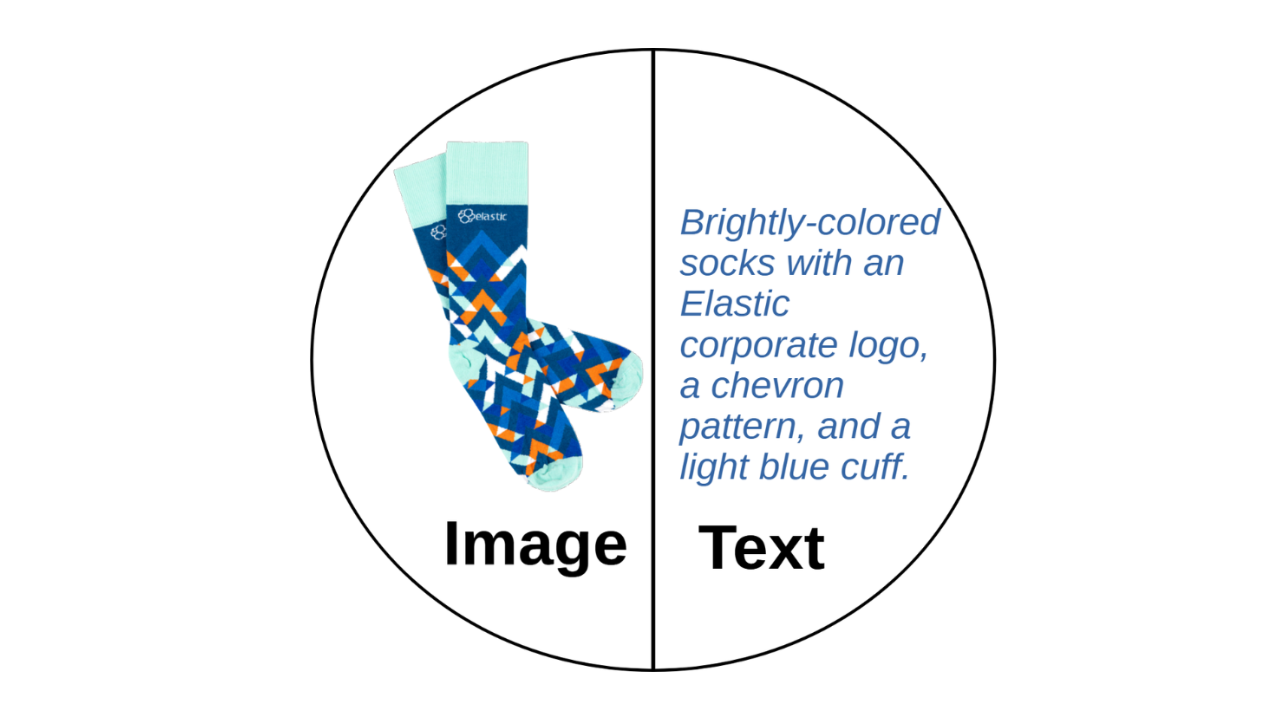
A picture is worth 1.5x the words: What we learned benchmarking product search embeddings
We benchmarked two embedding models on 5,000 real products and found that combining image and text beats either alone by up to 50%. Here's the data and the model that won.