Blogs
Hands-on, insight-driven content about observing your production and development environments using Elastic Observability.
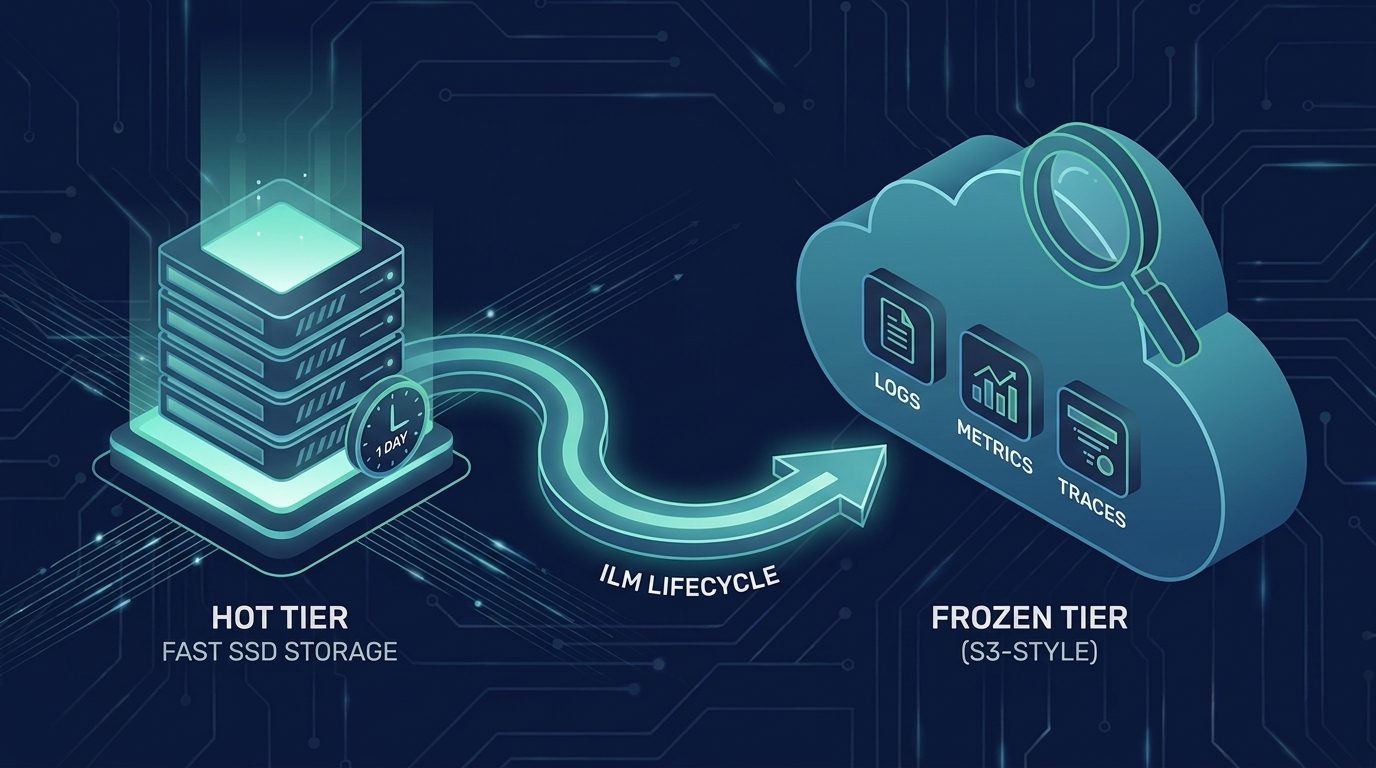
Cut log storage costs with two Elasticsearch data tiers instead of four
Elastic benchmarked one day of logs on SSD with everything older moved to frozen searchable snapshots, and it came out 16x cheaper than keeping all of it hot. The ILM policy and the cost model are both in the post.
Temporal Cloud observability in Elastic: 50+ metrics, zero collectors
Elastic scrapes metrics.temporal.io, so the workflow that has been stuck in Running for an hour turns out to be a task queue nobody is polling, and you find that out before you open a single worker log.
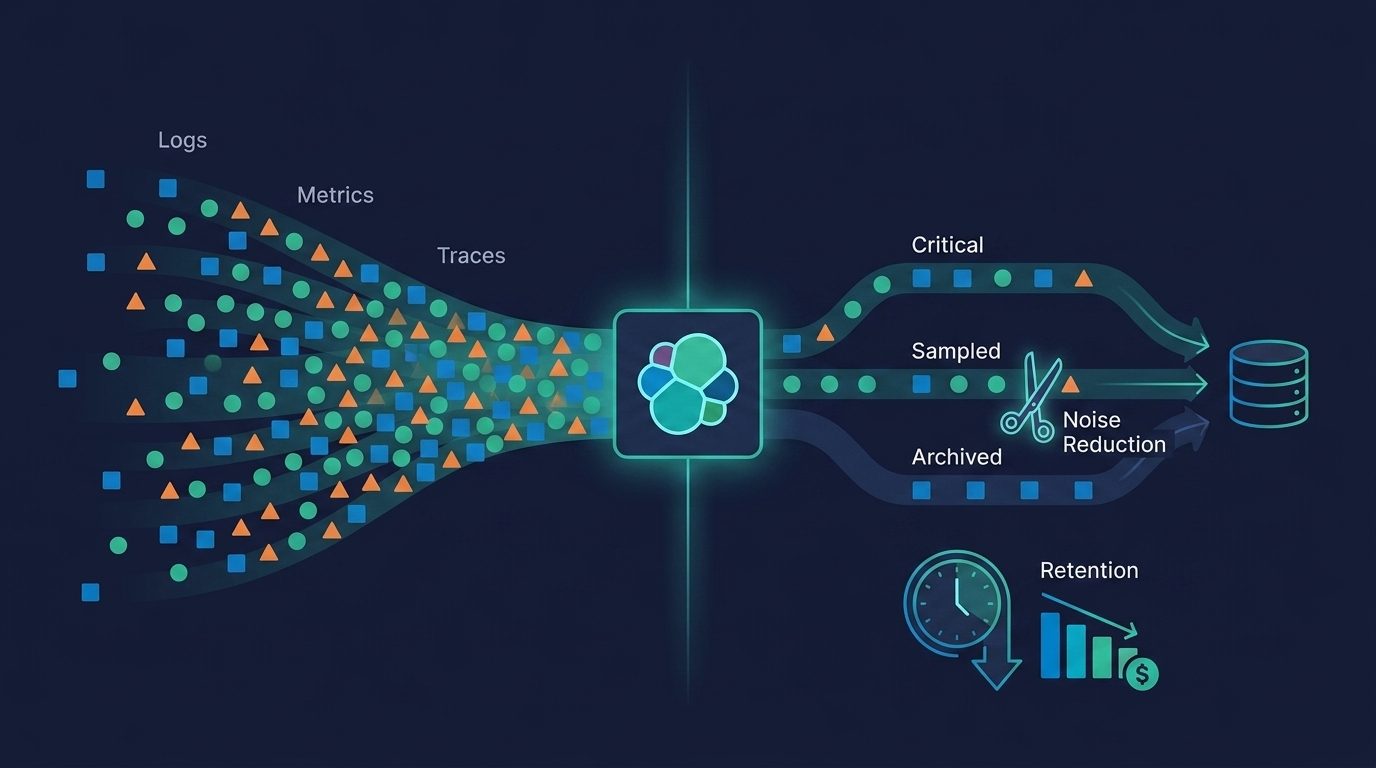
Not every log deserves 90 days: per-stream retention in Elastic Streams
AI Partitioning reads your data and proposes child streams. Retention, drops and downsampling then become per-stream settings, so the noisy ones expire on their own schedule.
Cross-project search for Elastic Observability: one query across every linked project
Keep your observability data where it lives, and still search, alert, and monitor across every linked Serverless project, easily!
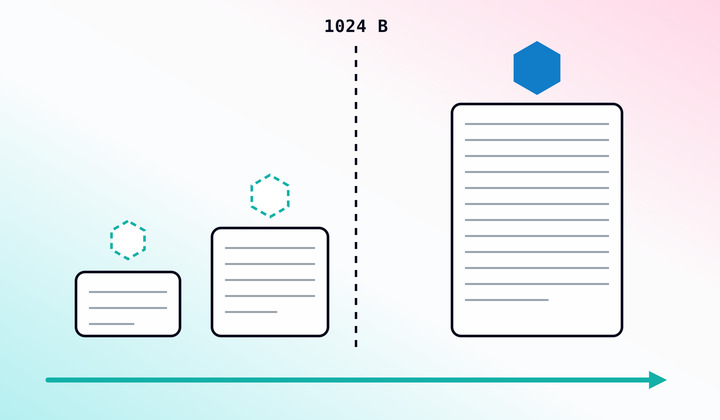
No log file too small: How Elastic Agent tracks files below the 1 KiB threshold
Elastic Agent 9.5 builds a small log file's identity out of the bytes it already has, then re-links it as it grows and crosses 1024 bytes, so it is never re-ingested.
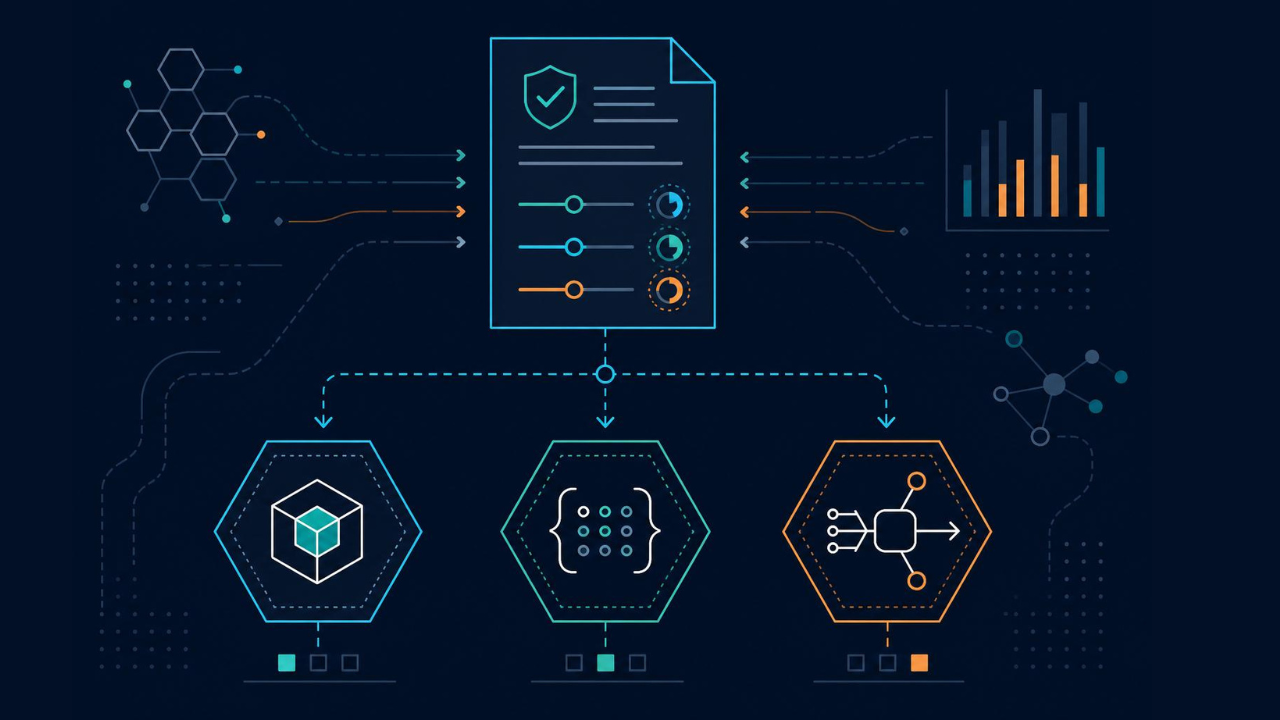
Telemetry Policy: change OpenTelemetry sampling and log levels at runtime, no restart
Telemetry Policy says what you want to happen and leaves each component to work out how. Change an OpenTelemetry Java agent's trace sampling to 1% and the JVM keeps serving traffic.
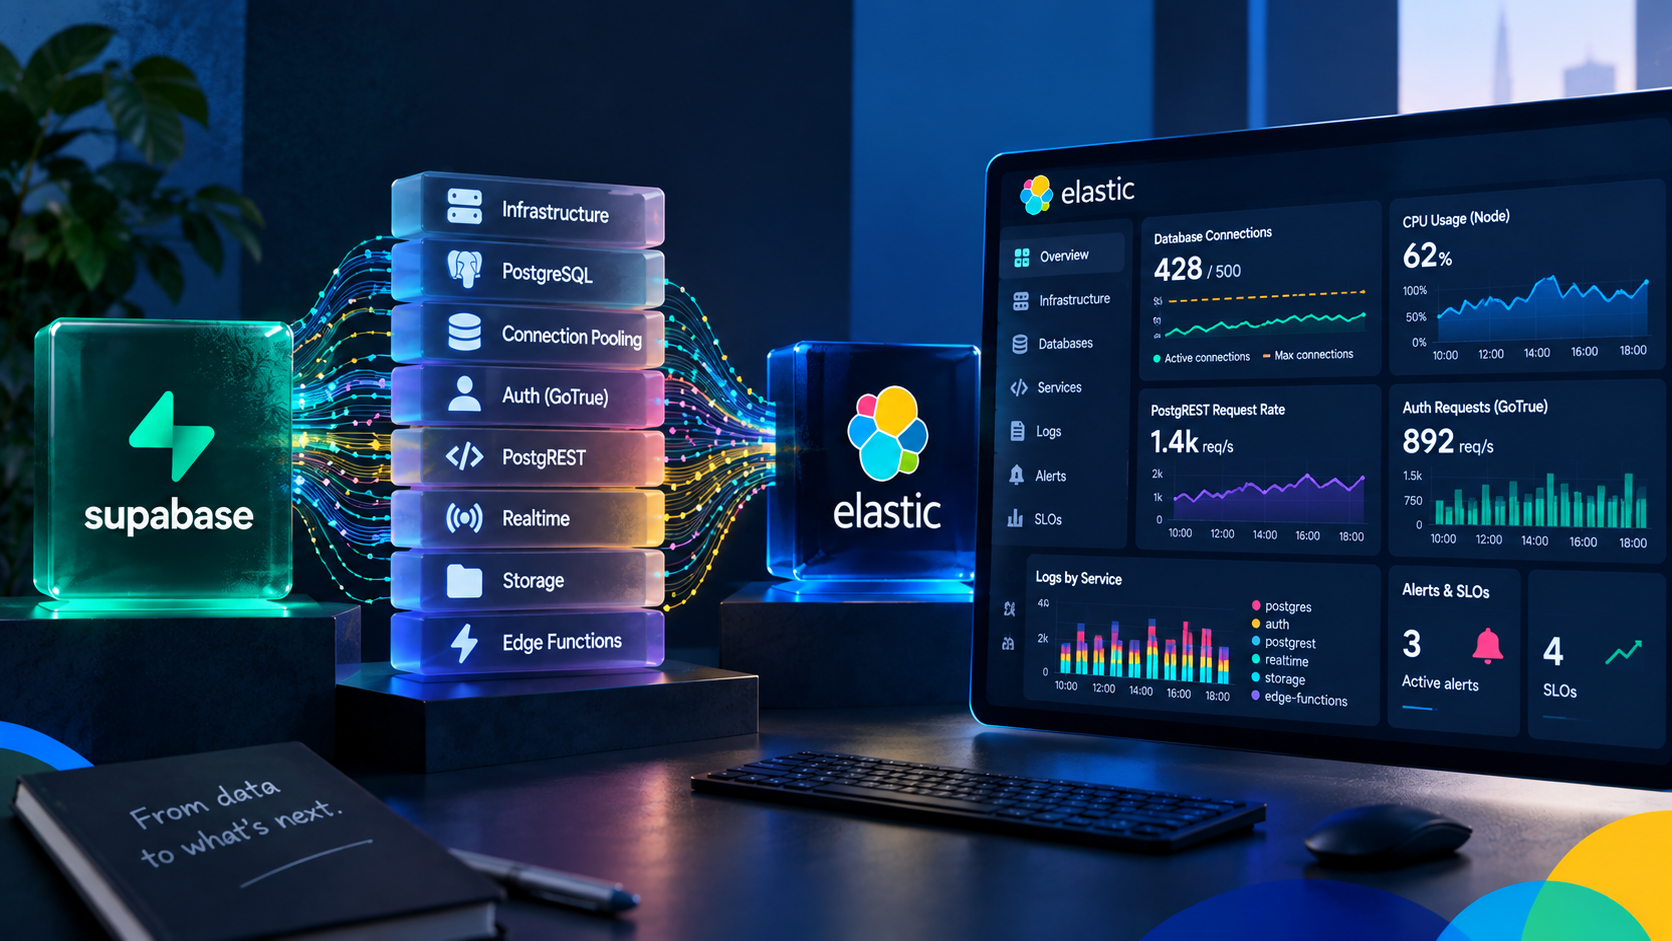
Monitor Supabase in Elastic: dashboards, alert templates, SLO templates, and zero agents
When your Supabase API goes slow, it could be the node, Postgres, the pooler or PostgREST. Elastic tells you which one and shows you the logs from whichever it was.
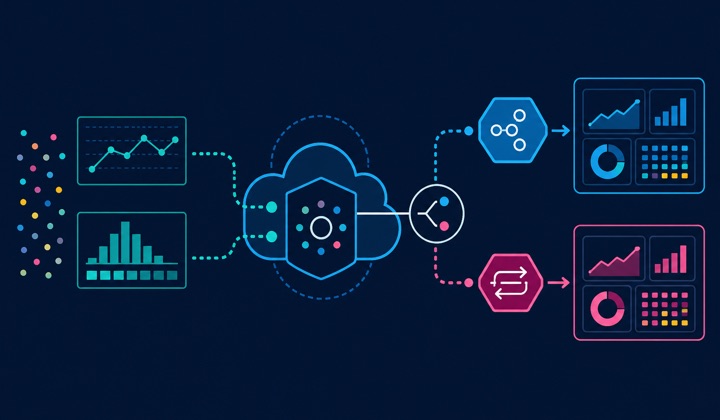
Native OTLP metrics ingestion on Elastic Cloud Hosted
Send an exponential OpenTelemetry histogram and Elasticsearch keeps the scale and buckets you sent. All four type and temporality combinations work now, and your SDK and Collector config stay exactly as they are.
Collecting rootless Podman logs with Elastic Agent: the CRI parser, user-scoped paths, and the Podman socket
Rootless Podman containers write their logs in CRI format. This Fleet policy reads them and attaches container.* fields, with the match_source_index value that rootless paths need.
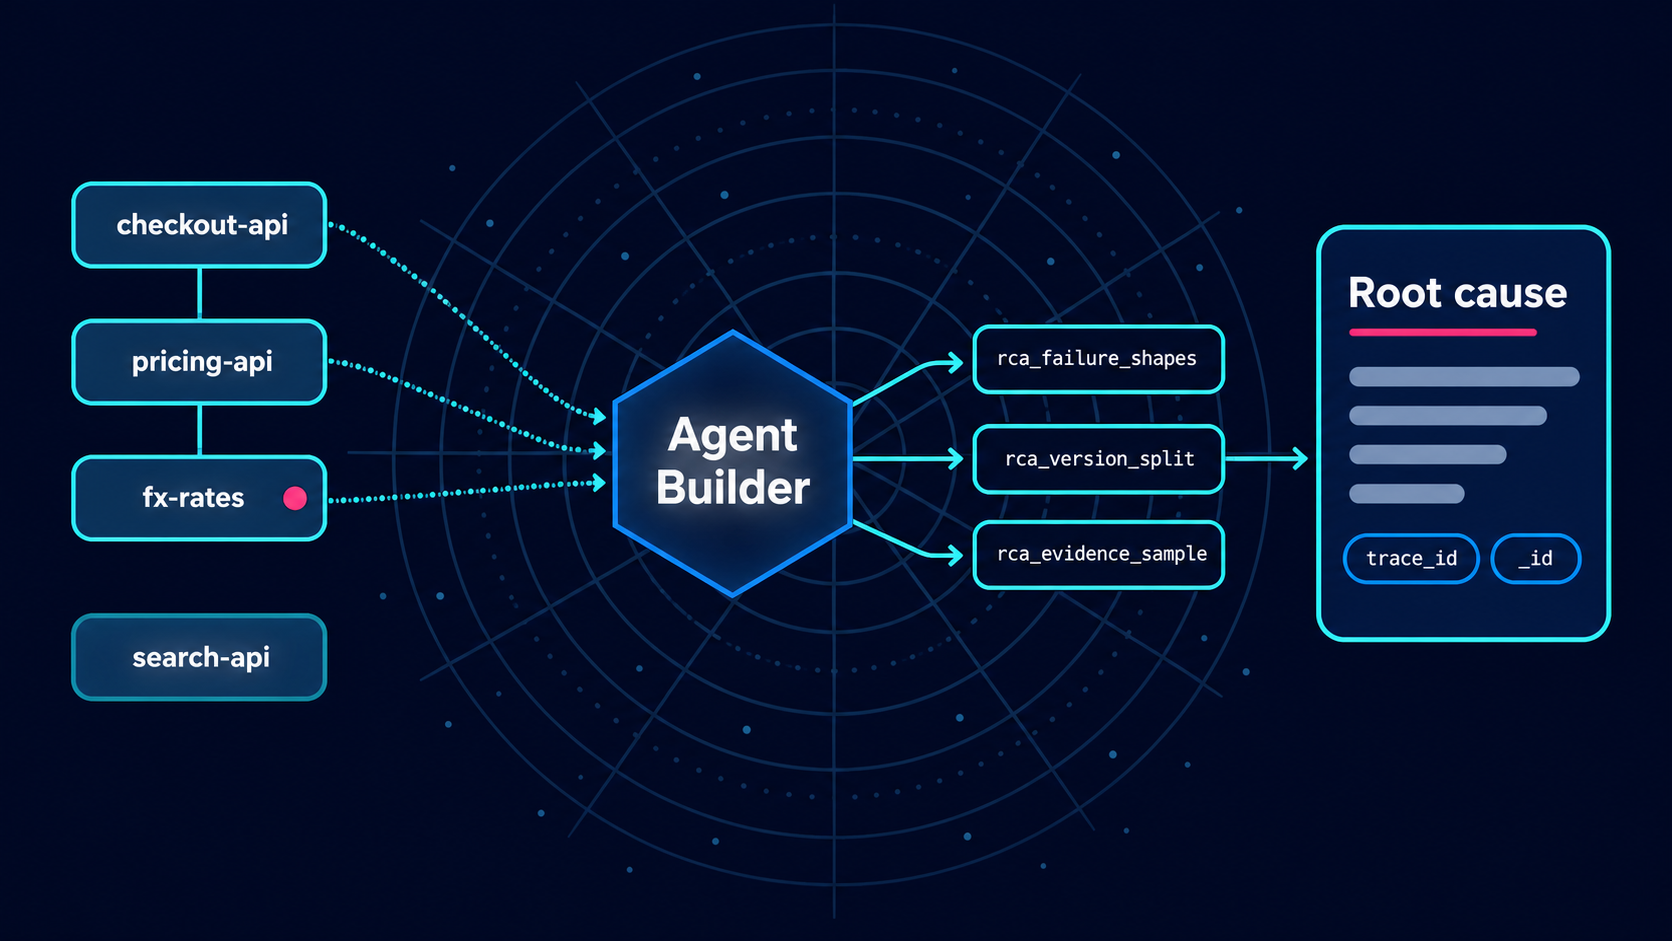
AI root cause analysis in Elastic Agent Builder that cites its evidence
The new release failed at 27.2%, the old one at 28.2%, so the deploy was never the cause; the agent worked that out in 72 seconds and handed back a trace ID for the failure that was.
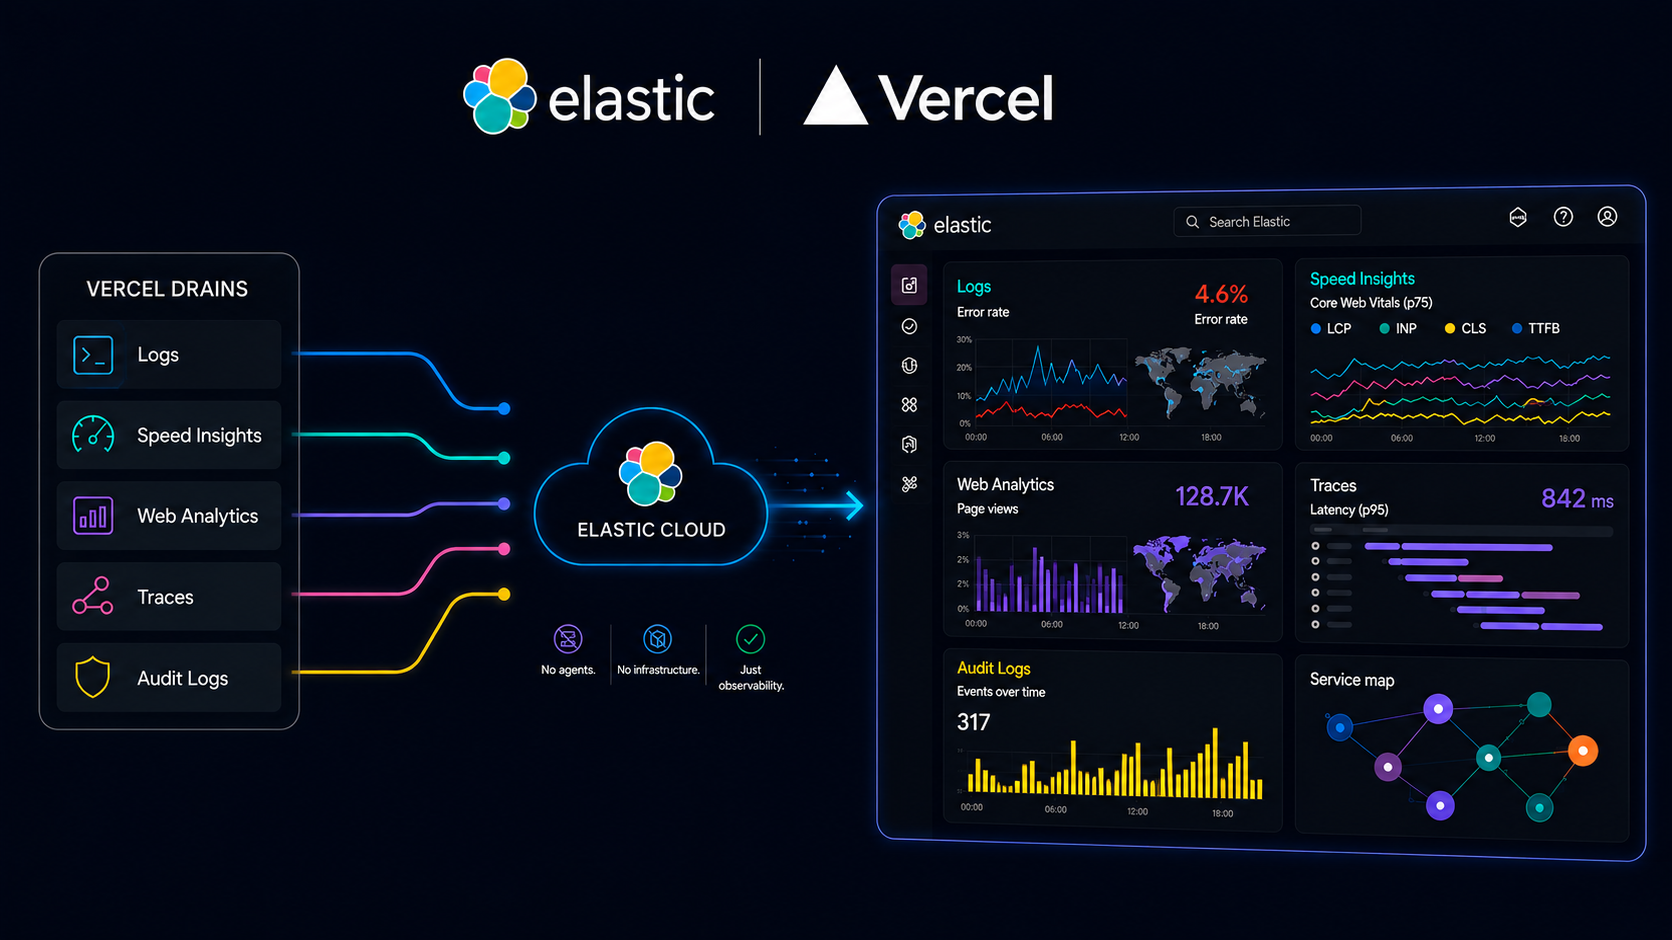
Drain Vercel into Elastic: serverless observability with nothing to install
A drain and an API key put Vercel logs, traces, and Speed Insights into Elastic Cloud, where you can follow a slow request from the edge to the Lambda function behind it.
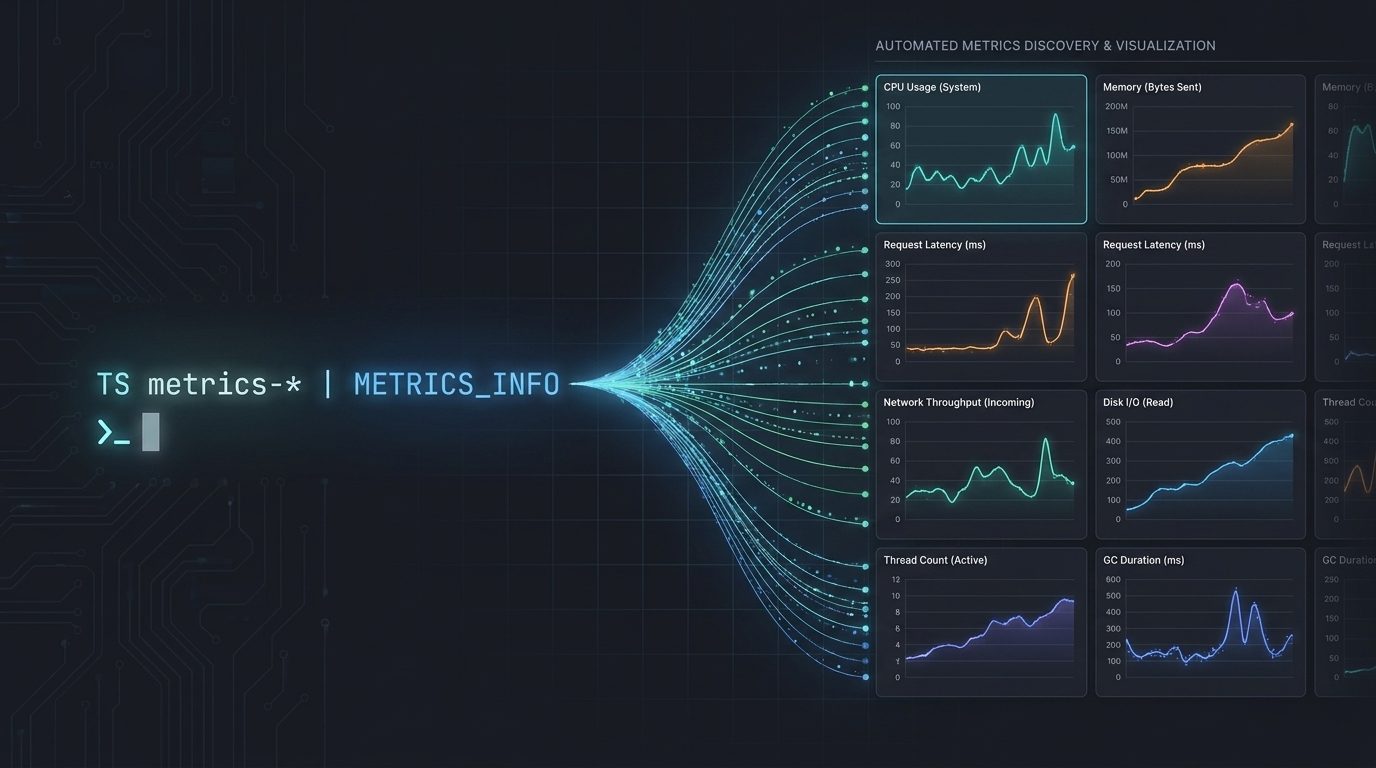
How one ES|QL query builds a metric chart for every metric in Elasticsearch
METRICS_INFO reports what metrics are in your data and how to aggregate each one, so Kibana Discover can chart counters, gauges and histograms correctly with no configuration and no field names to look up.